Categories
Self-Hosted Open Source Data Management Data Catalog Metadata Management Data Publishing Open Data Portal Open GovernmentStars
Forks
Watchers
Developer links
CKAN
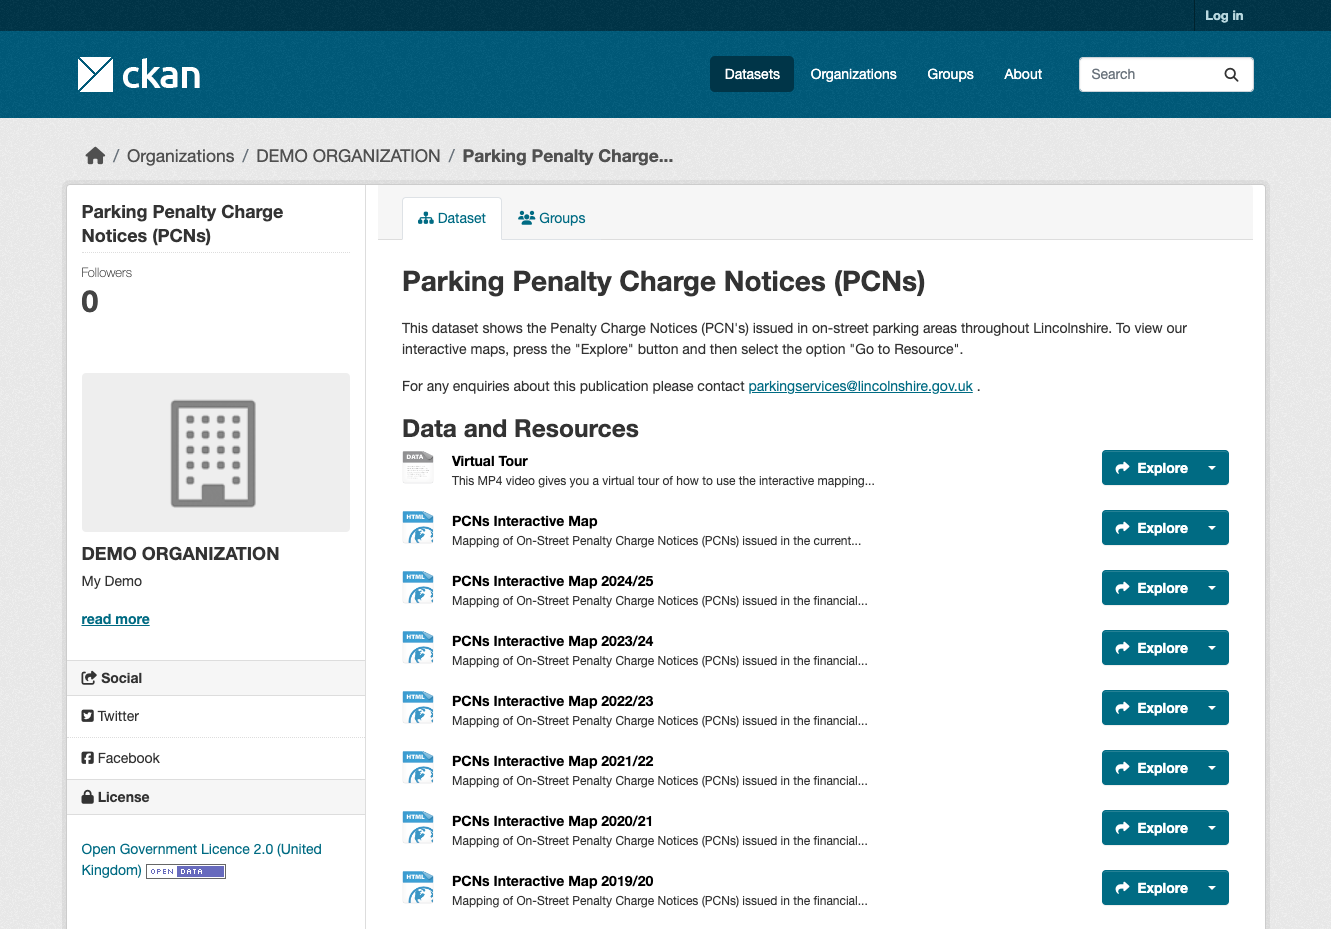
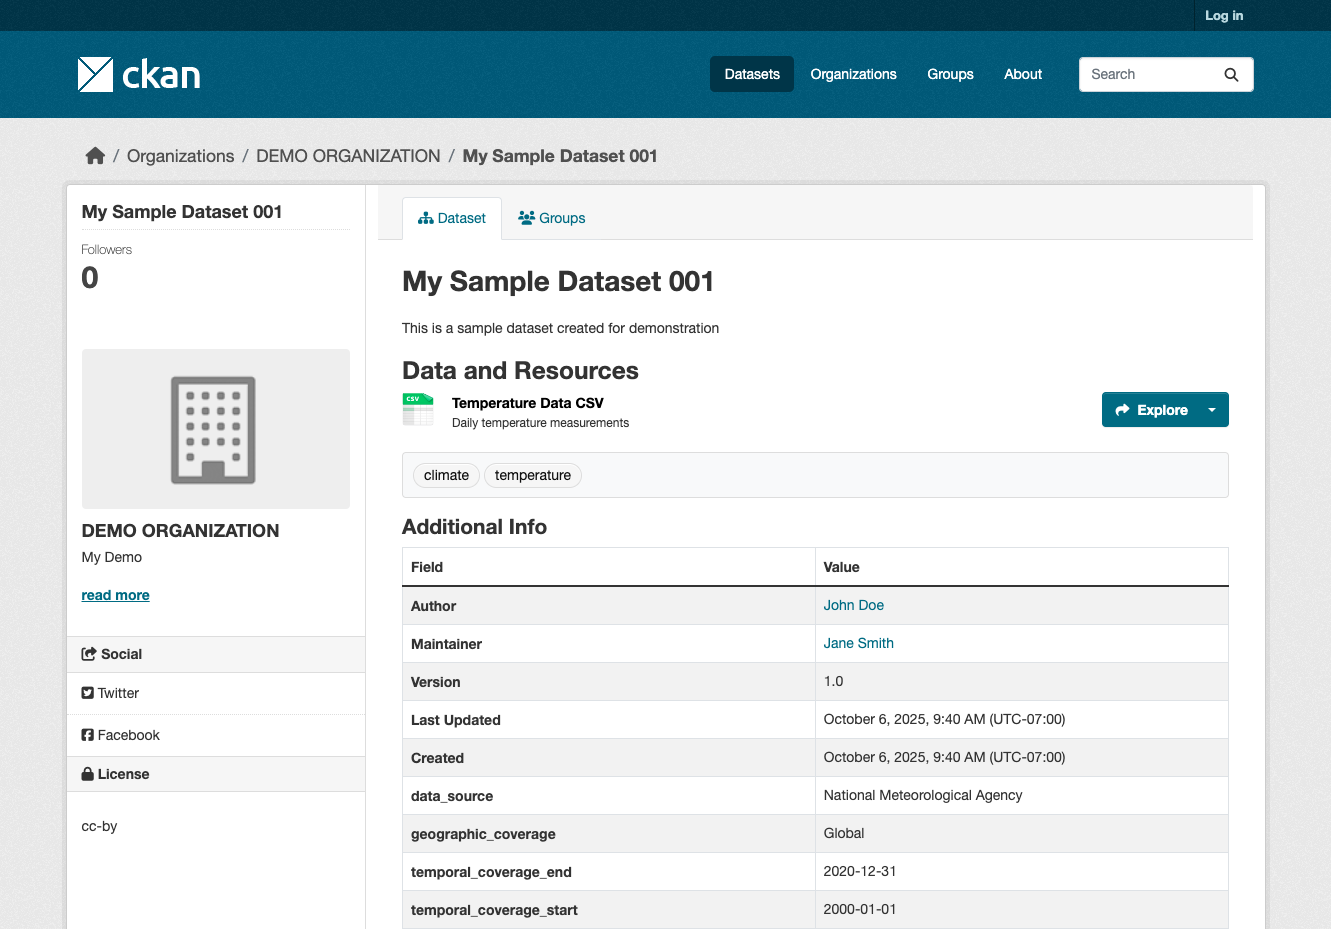
CKAN lets governments, research institutions, and companies publish data as a searchable catalog, where every dataset carries its description, license, tags, and downloadable files. Organizations own their datasets, and members, editors, and admins get different rights, so a dataset can stay private until someone with publishing rights releases it. Visitors narrow results with faceted filters on tags, formats, and organizations, or write fielded queries with wildcards and fuzzy matching. Resource pages preview spreadsheets in a grid and, when the data fits, as maps and charts, and they also display images, PDFs, and HTML. The DataStore keeps tabular resources as queryable tables, serving filtered rows with range conditions and nested AND/OR logic. Everything the web interface does is also available through the Action API. Groups gather related datasets, and custom metadata fields extend each record. Per-dataset activity streams document how data changes, and follow buttons feed a personal news feed. Files can be stored on local disk or, with extensions, in S3, Google Cloud Storage, or Azure Blob Storage. Extensions add geospatial search, harvesting for federated portals, multilingual metadata, and more chart types, and themes restyle the portal to match your brand. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Benefits
- Publish data with proper governance
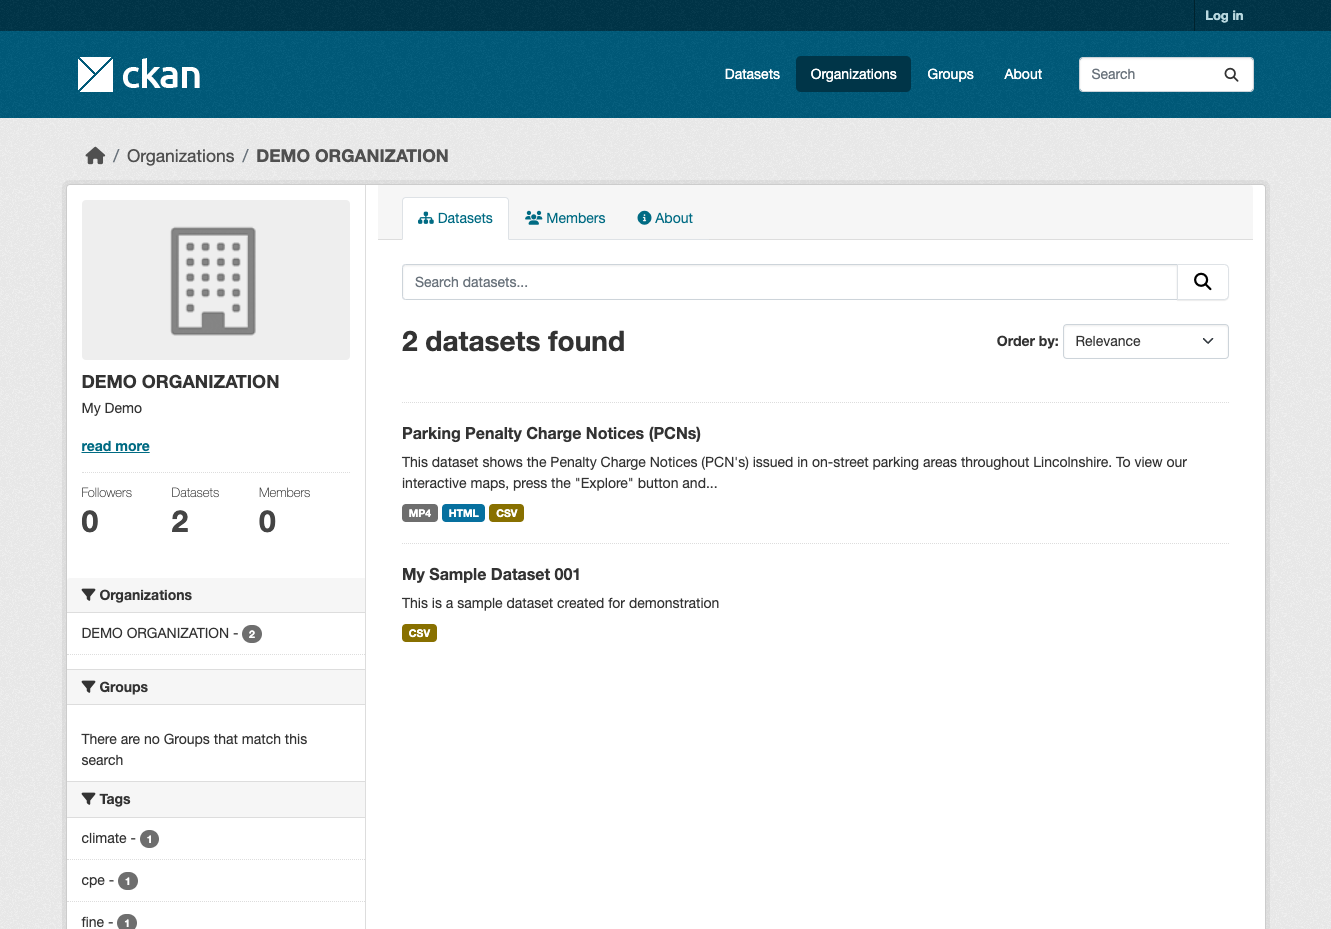
- Organizations own their datasets, and Member, Editor, and Admin roles decide who can view, edit, or publish them, so each department controls its own release process.
- Help people find the right data
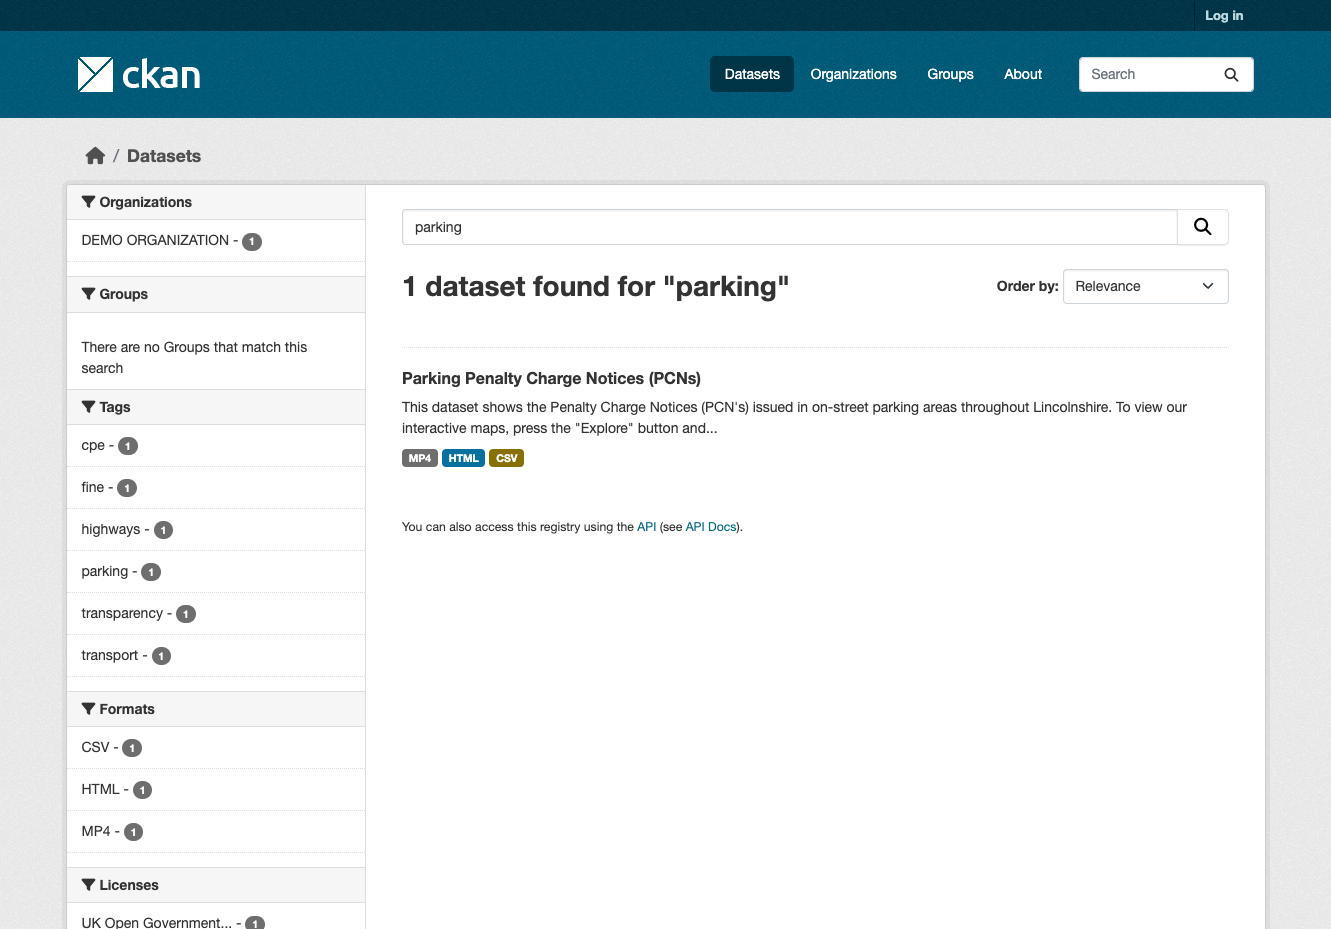
- Faceted filters on tags, formats, and organizations, plus fielded queries with wildcards and fuzzy matching, let visitors narrow large catalogs quickly without knowing exact dataset titles.
- Let visitors preview before downloading
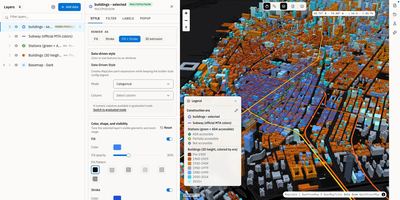
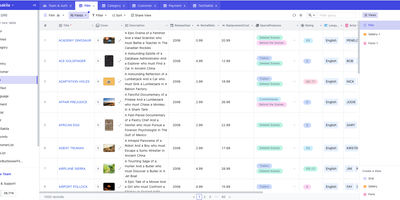
- Spreadsheets open in a grid, suitable tables become maps or charts, and images, PDFs, and HTML render inline, so people judge a resource before downloading it.
- Integrate through a complete API
- Everything the web interface does is available through the Action API, and the DataStore adds filtered queries over tabular resources, so apps and dashboards can use the data directly.
Features
- Organizations and roles
- Each organization has its own home page, members, and private-to-public publishing workflow, with Member, Editor, and Admin roles controlling who can view, edit, and publish datasets.
- Faceted Solr search
- Apache Solr powers keyword search with filters for tags, formats, and organizations, plus advanced fielded queries using wildcards, proximity matching, and fuzzy matching.
- DataStore and Action API
- The DataStore keeps tabular resources in PostgreSQL and exposes them through the Action API, with range filters, nested AND/OR conditions, and keyset pagination for fast large exports.
- Resource previews and views
- Resource pages preview CSV and Excel files as grids, offer map and chart views for suitable data, and display images, PDF documents, and HTML directly.
- Activity streams and follows
- Dataset pages show an activity stream of recent changes, and users can follow datasets, organizations, or other users to receive updates in a personal news feed.
- Extensions and themes
- Plugins add geospatial search, harvesting, multilingual metadata, and cloud storage, while the opt-in Midnight Blue theme and a theming guide restyle the portal.