
Stars
Forks
Watchers
Developer links
Docspell
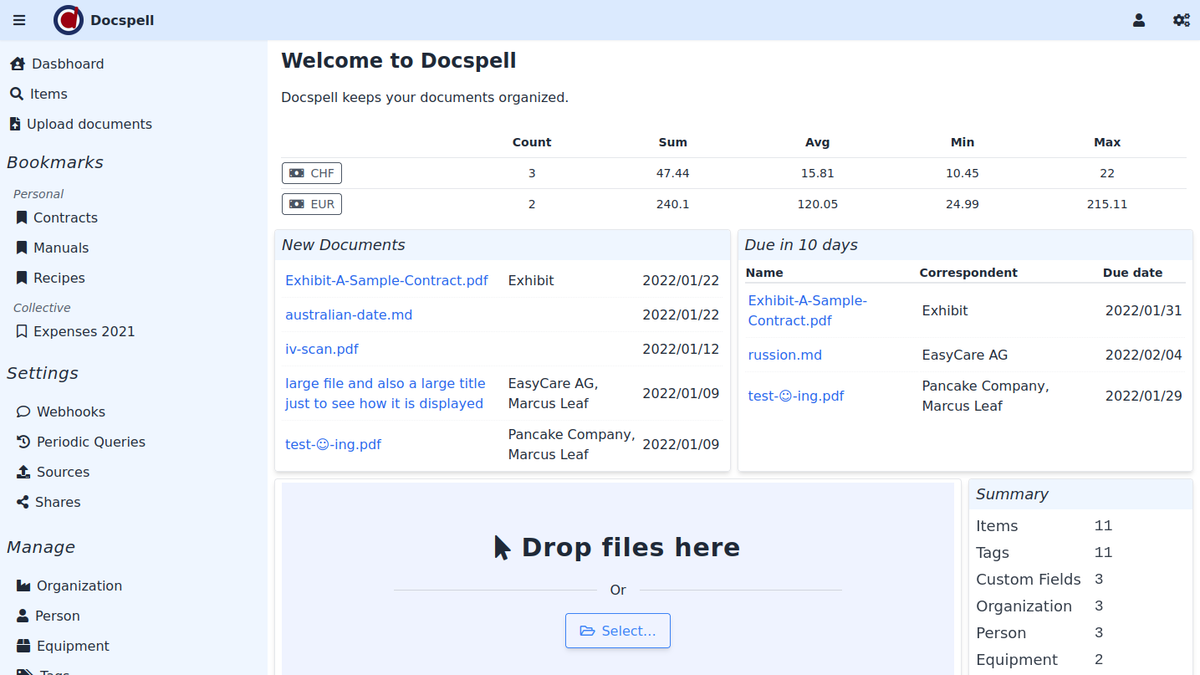
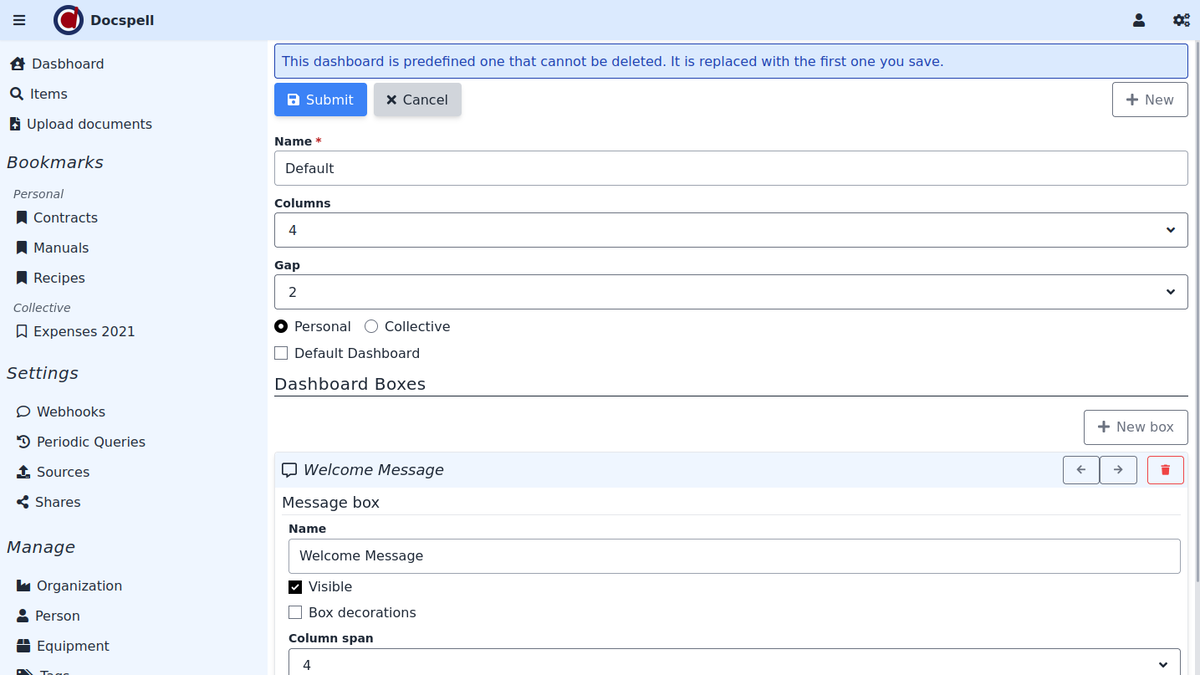
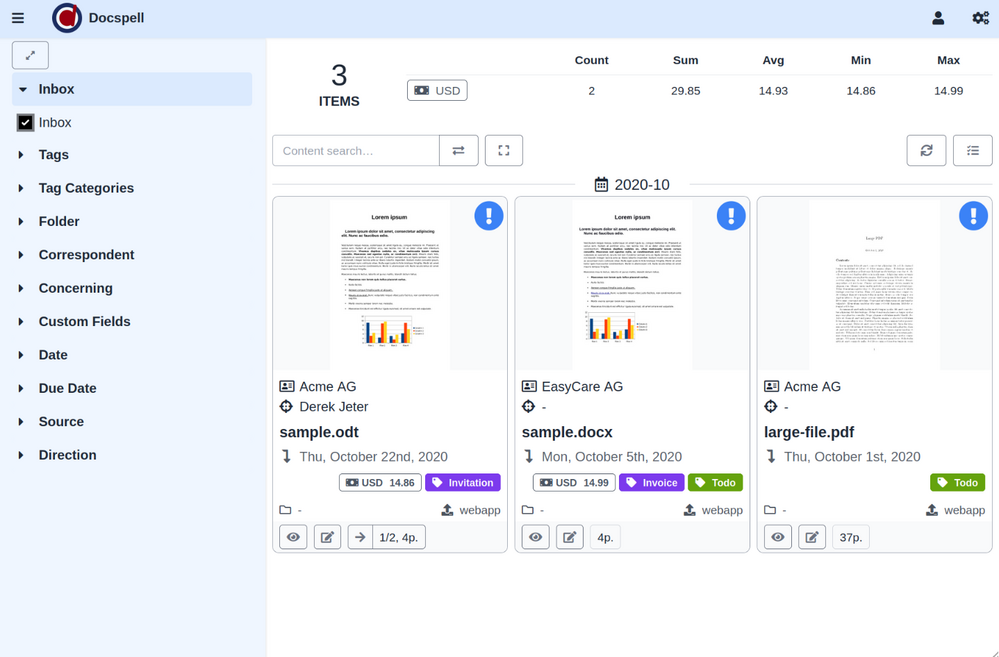
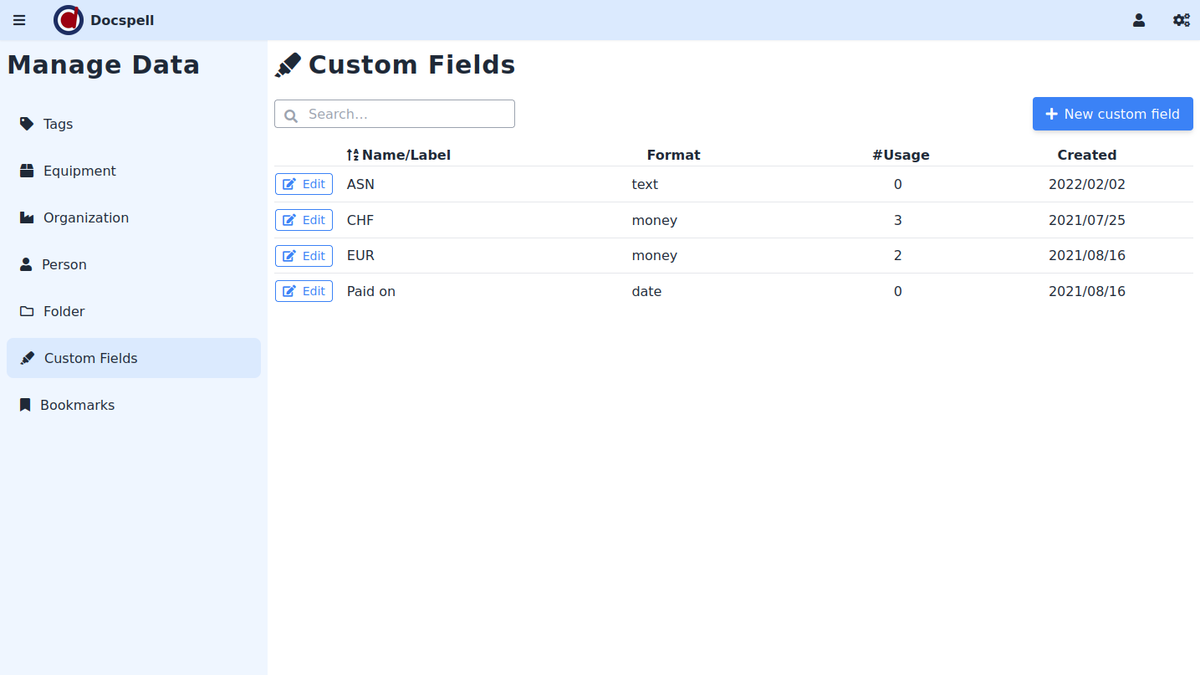
Convert paper archives, email attachments, and PDF records into an organized digital repository with Docspell, an open-source document management system that automates optical character recognition, metadata extraction, and full-text search. Users can ingest receipts and invoices through network scanners, monitored IMAP email mailboxes, mobile uploads, or drag-and-drop browser tools. The background processing pipeline executes optical character recognition via Tesseract, enhances image contrast with unpaper, and extracts text from Word documents and PDFs. Machine learning algorithms analyze document syntax to predict correspondents, suggest relevant organization tags, and identify due dates automatically. Team members can search their entire filing cabinet using complex Boolean queries and full-text indexing powered by Apache Solr or PostgreSQL. Administrators can configure multi-user collectives with isolated permissions, define custom metadata attributes, set up webhooks, and share time-limited document download links. Users can also merge multi-page scans, track processing job queues, and export curated document collections for tax filings or legal audits. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPL v3.0 licensed.
Benefits
- Automated OCR and Image Enhancement
- Extract machine-readable text from scanned physical pages, photos, and PDFs using Tesseract OCR and unpaper image pre-processing, generating searchable PDF archives without manual transcription.
- Intelligent NLP Metadata Classification
- Apply Stanford CoreNLP machine learning to infer document correspondents, detect invoice dates, and recommend categorization tags from document contents without requiring manual data entry.
- Automated Multi-Channel Document Ingestion
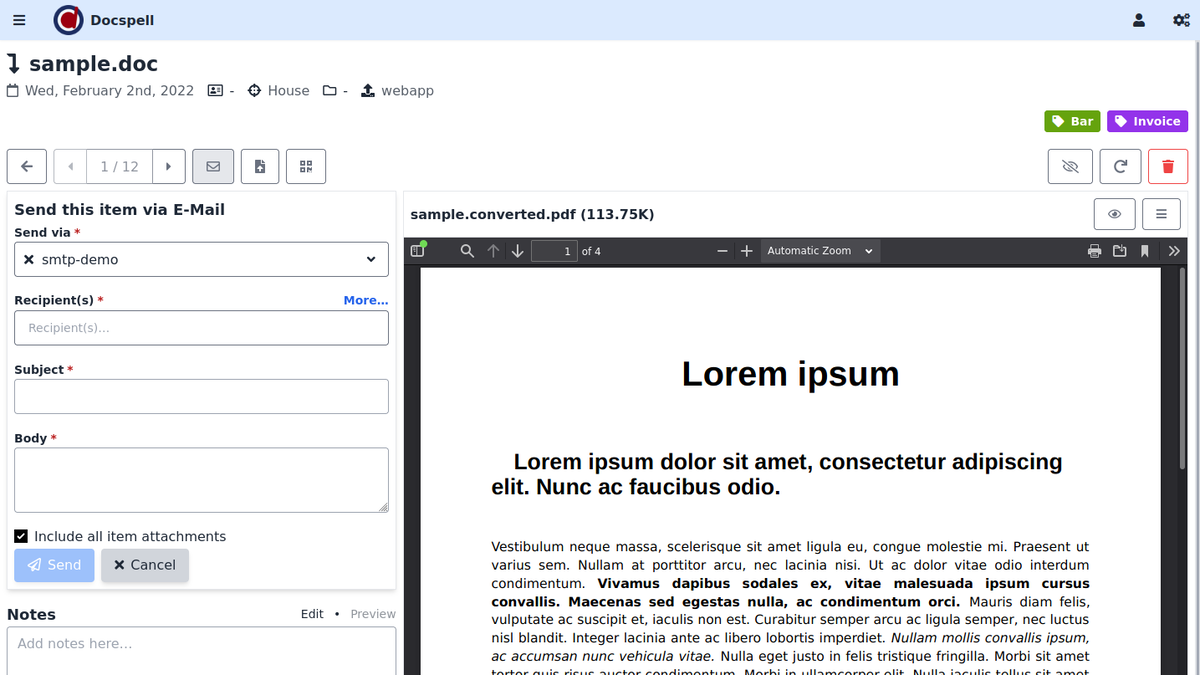
- Poll IMAP email inboxes, process incoming scanner folders, accept REST API payloads, and upload receipts from mobile devices to centralize document intake across all personal and office workflows.
- Scalable Full-Text Search Engine
- Locate critical paperwork instantly with powerful query syntax, fuzzy matching, and filtered faceted drill-downs powered by Apache Solr or native PostgreSQL full-text search indexes.
Features
- Automated Optical Character Recognition
- Convert scanned images and non-searchable PDF documents into searchable text layers using Tesseract OCR, Ghostscript, and unpaper pre-processing filters.
- Stanford CoreNLP Learning
- Train local machine learning models to suggest document senders, categorize document types, and extract dates from natural language text.
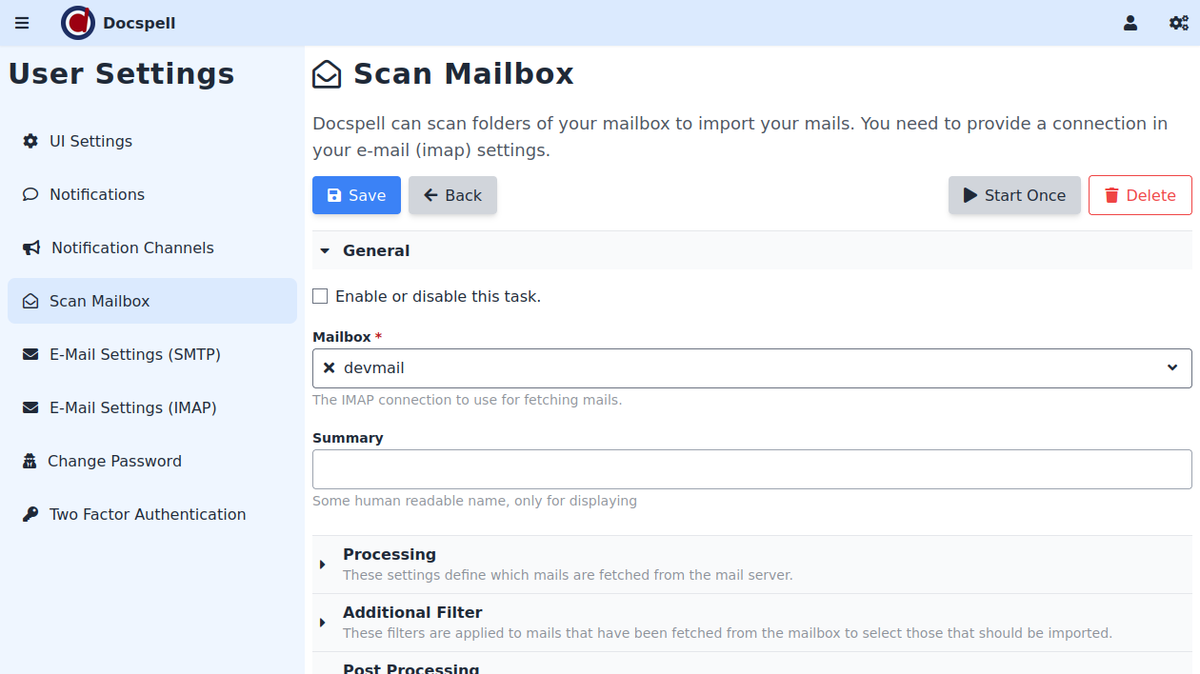
- Automated IMAP Mailbox Ingestion
- Monitor configured email accounts over IMAP to extract PDF attachments, process email bodies, and catalog incoming invoices automatically.
- Apache Solr Full-Text Search
- Execute complex search queries with phrase matching, token combiners, and faceted result filters using Apache Solr or PostgreSQL search backends.
- Multi-User Collective Isolation
- Organize documents within distinct collective workspaces featuring granular role-based access controls, custom metadata fields, and secure file sharing.
- Batch Editing and Merging
- Combine multi-page scans, split mixed PDFs, reassign correspondents across bulk selections, and download zip archives of tagged records.