Stars
Forks
Watchers
Developer links
OpenGateLLM
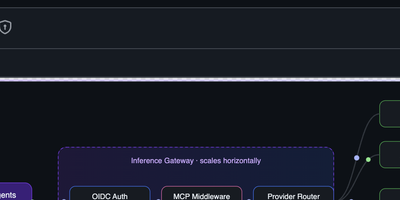
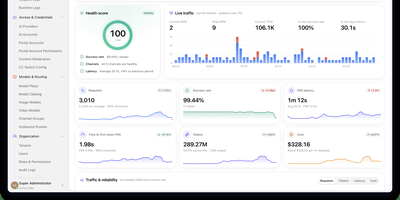
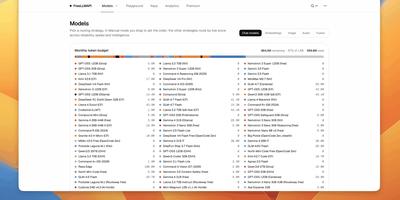
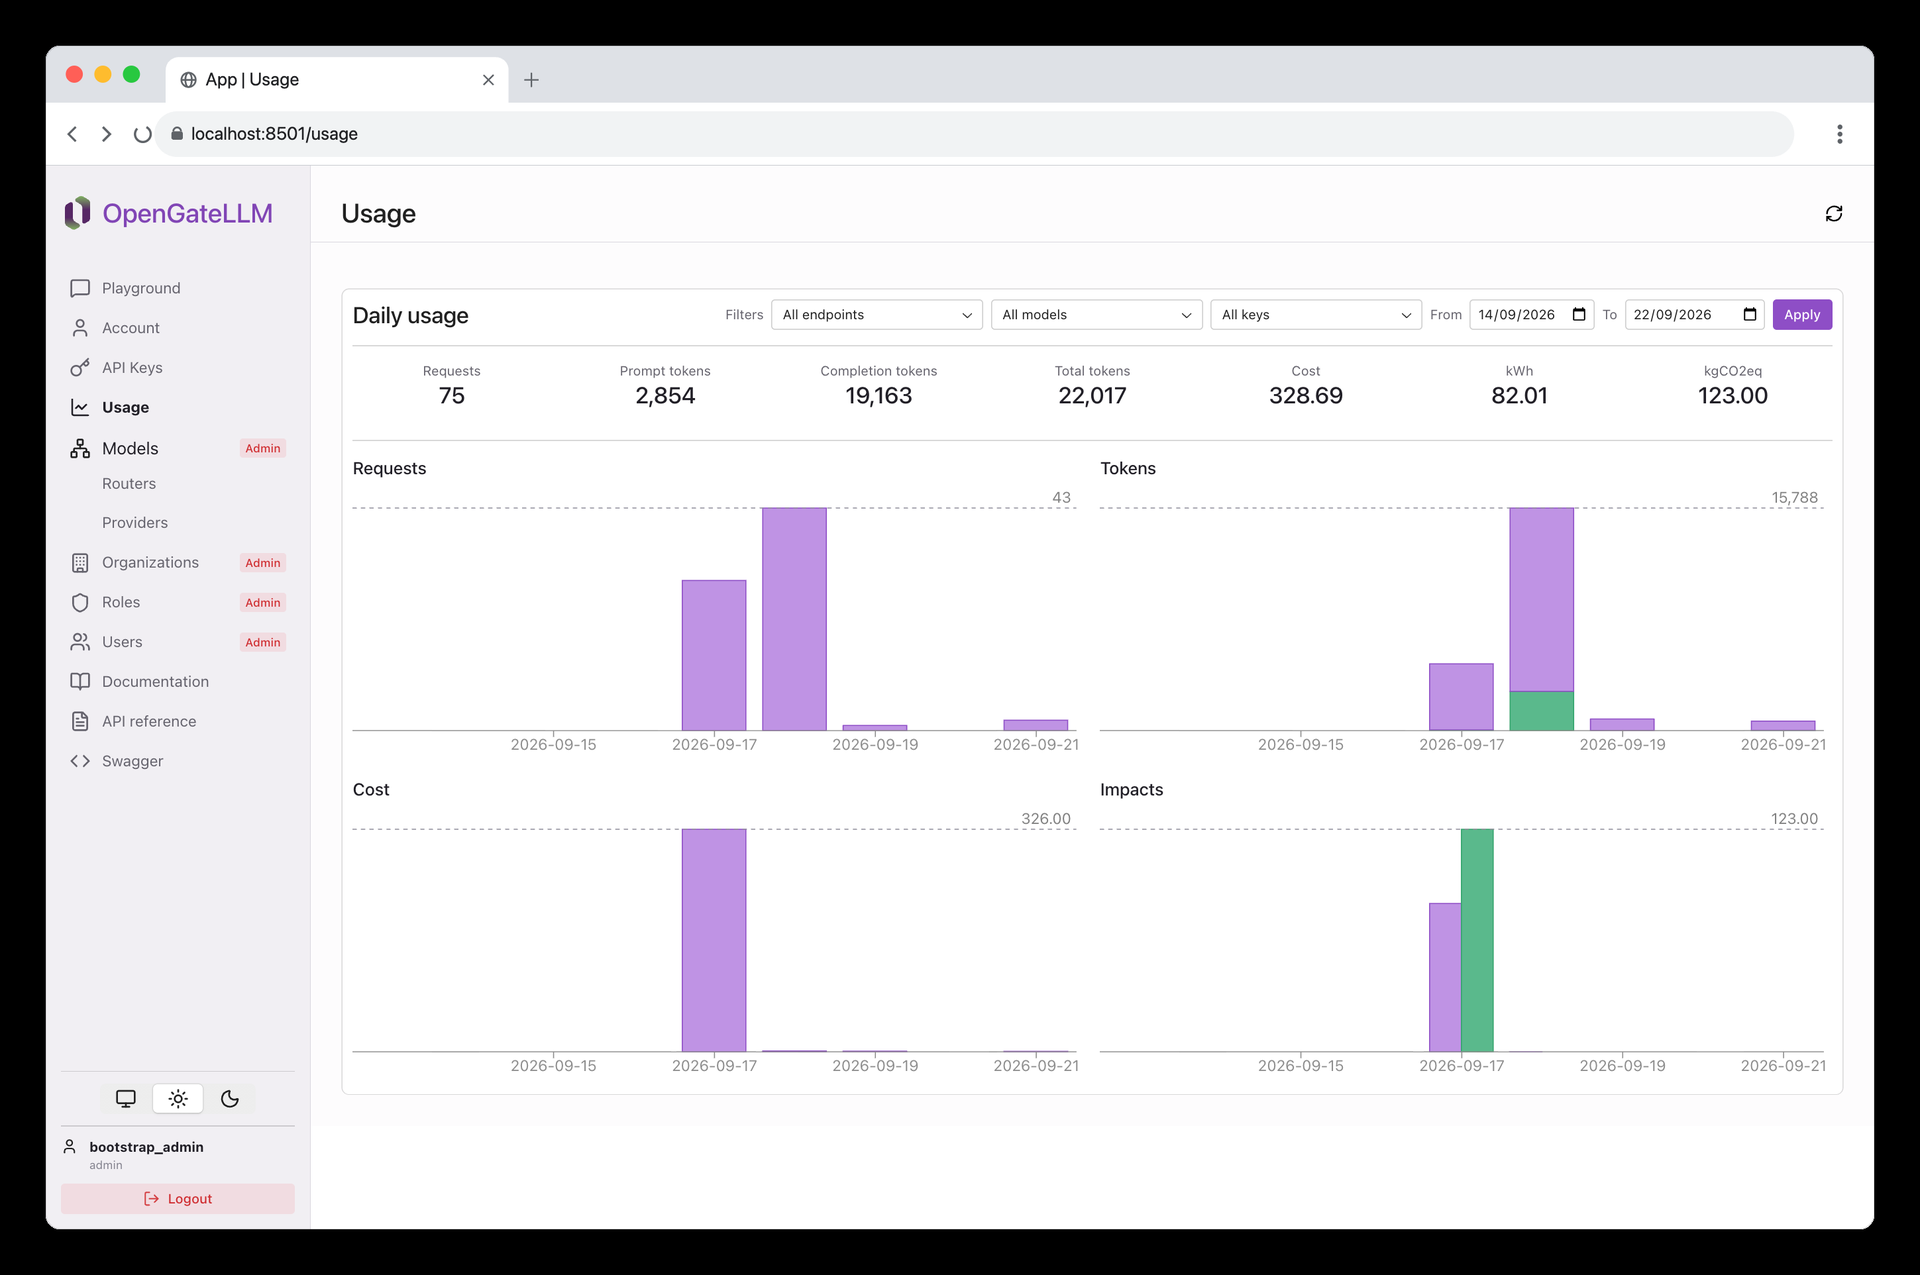
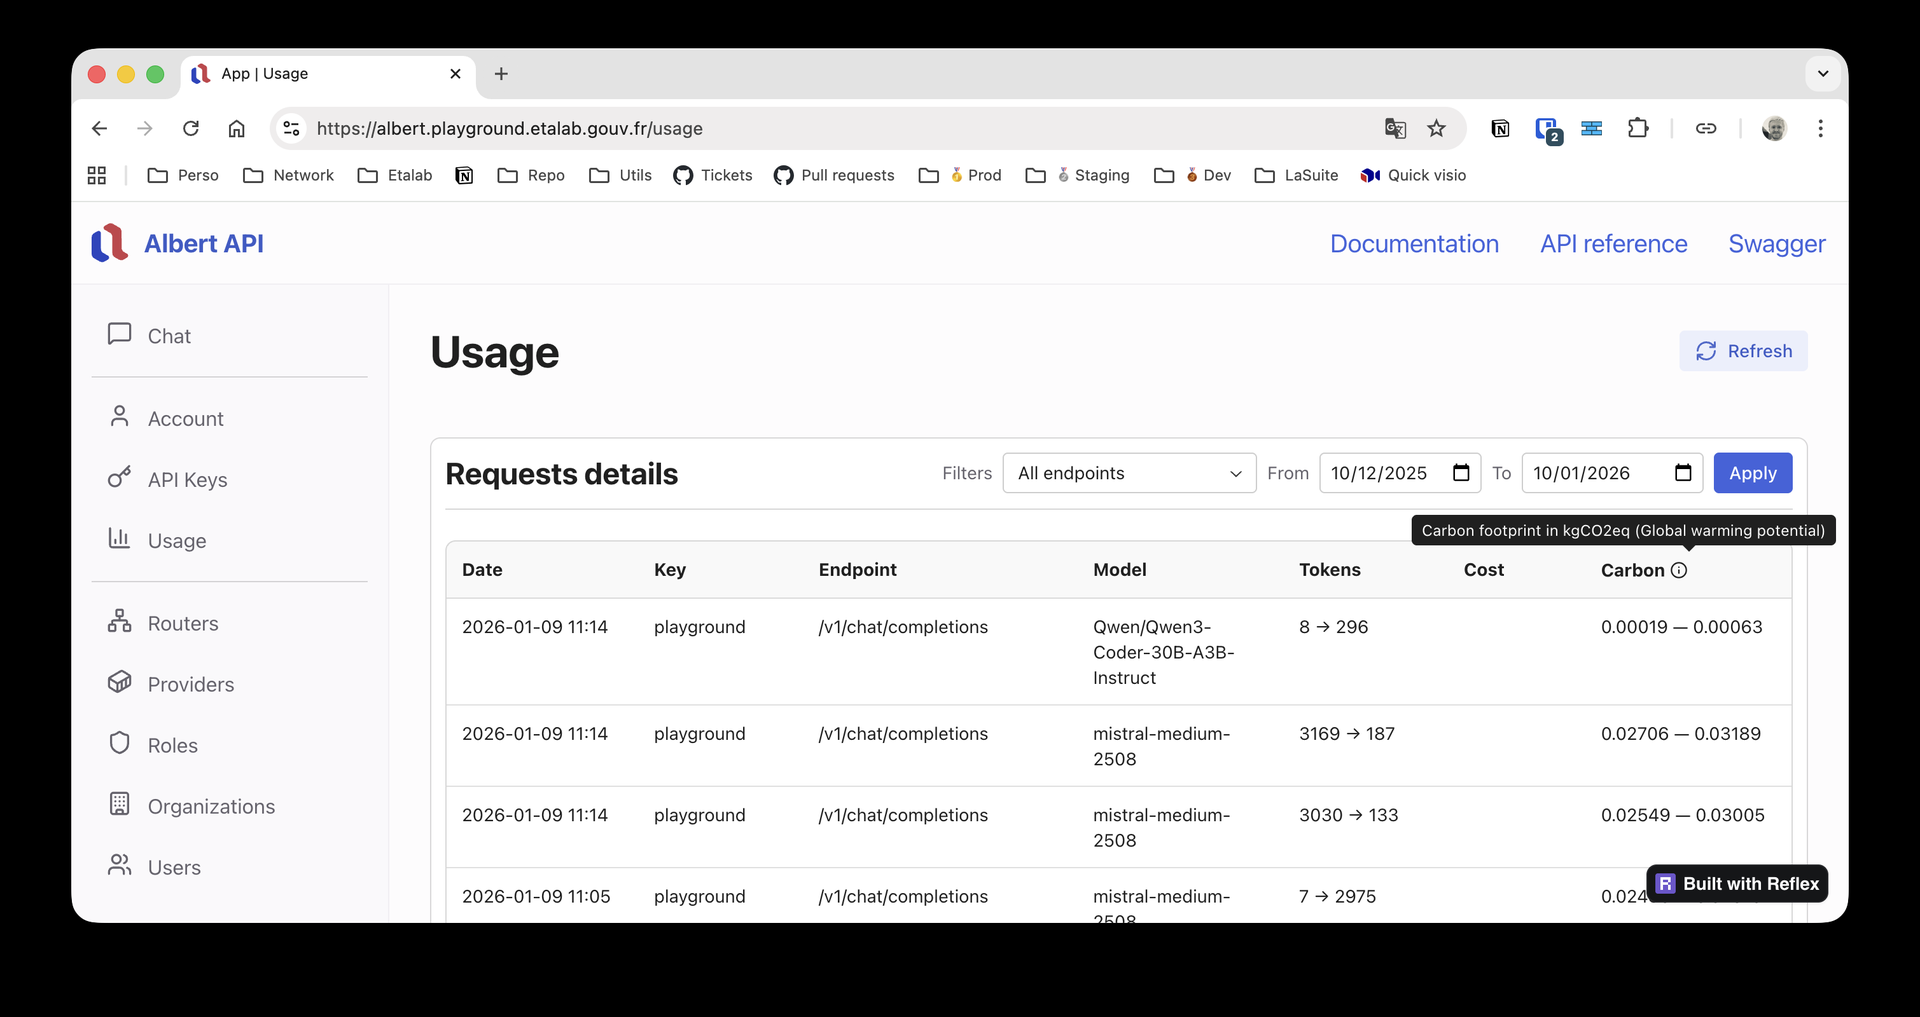
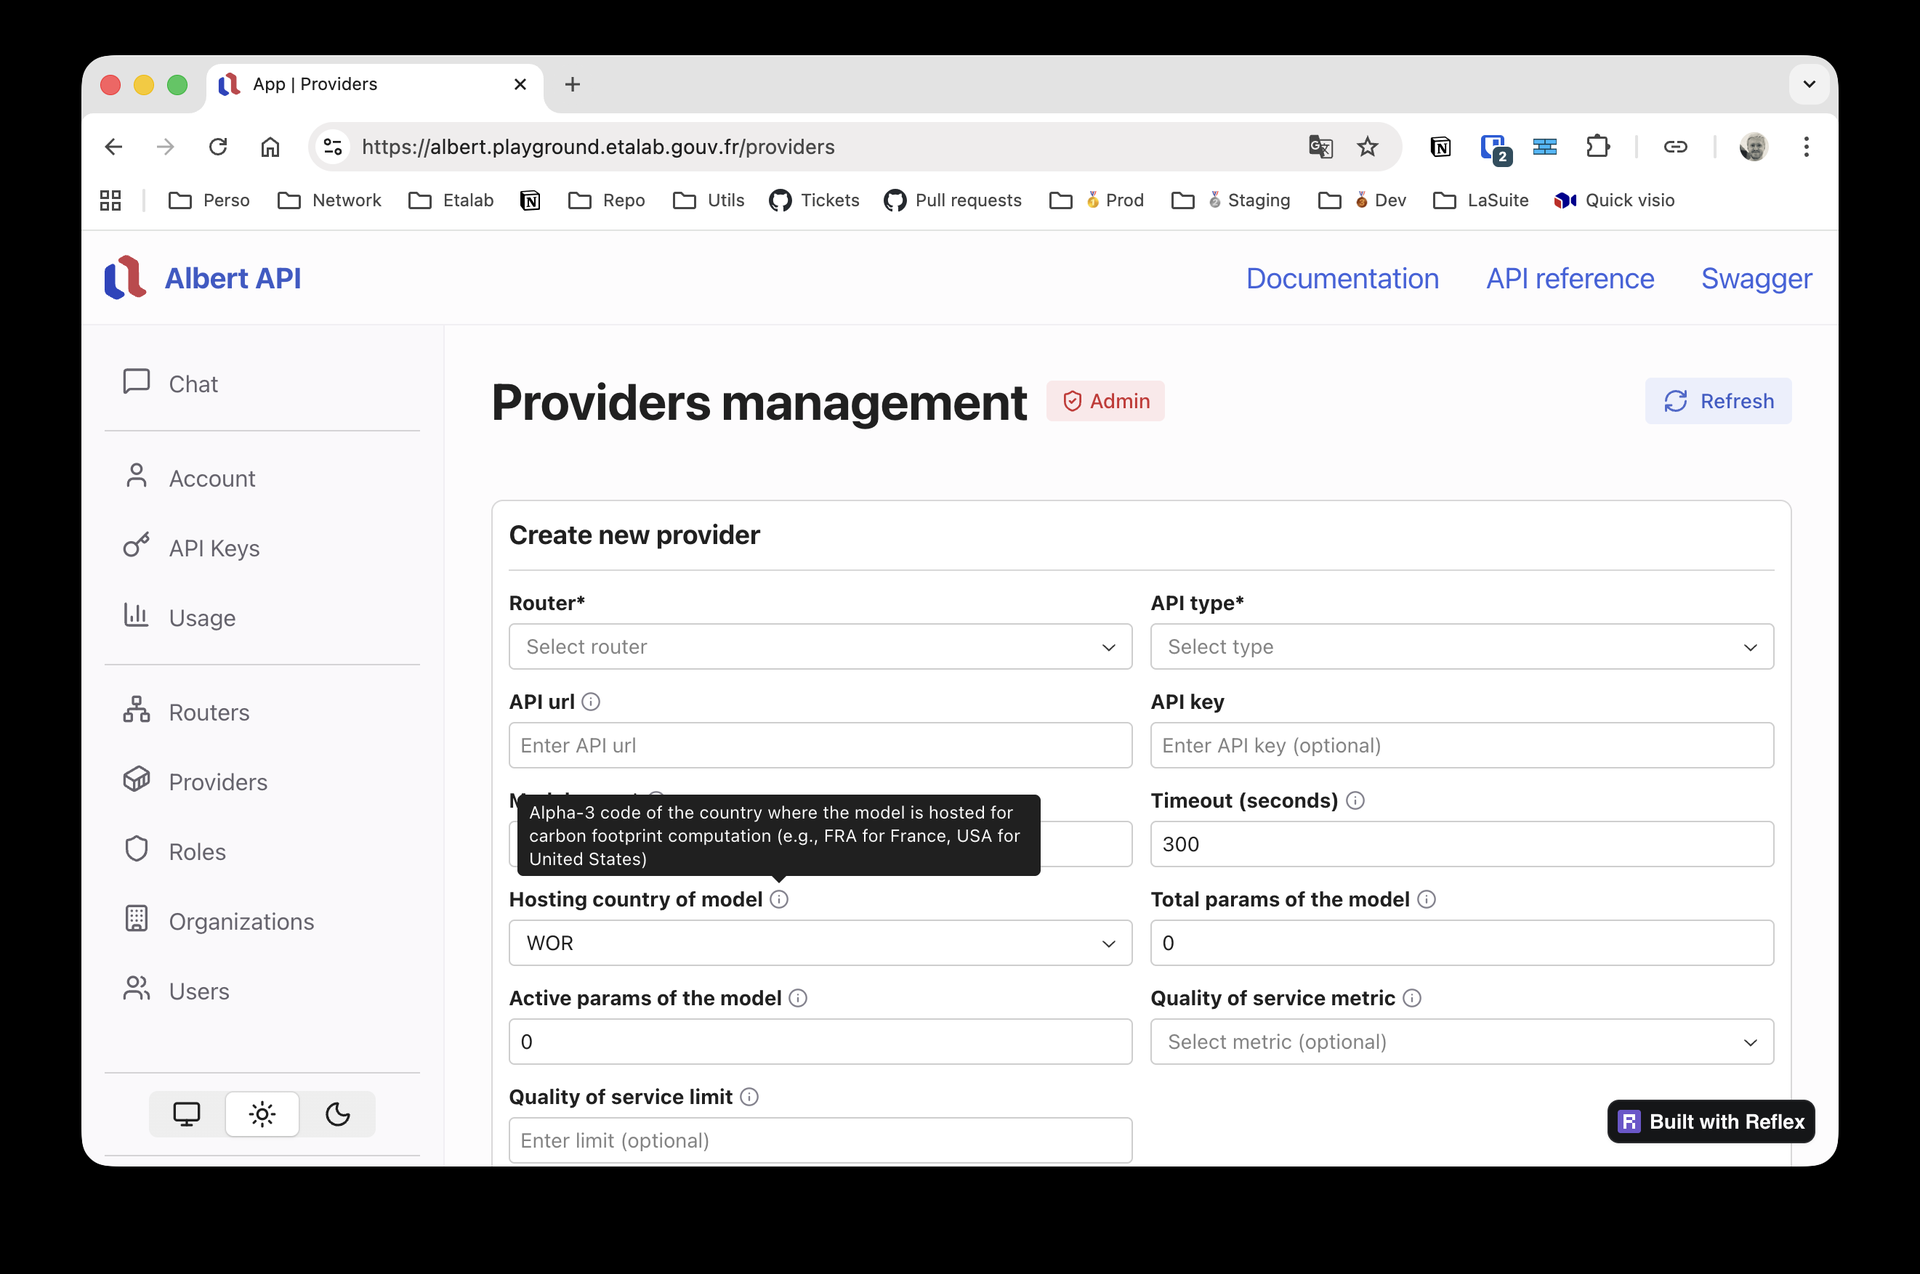
One endpoint, every model you run, and a government-grade paper trail for each request. OpenGateLLM sits in front of your AI infrastructure as the single door: applications call one OpenAI-compatible API, and the gateway decides which backend answers, a self-hosted vLLM cluster, an Ollama box in the corner, a Hugging Face TEI embeddings service, or a hosted provider when you allow one. You publish friendly model names as routers and attach real provider APIs behind them, then load-balance across those backends by shuffle or least-busy so a second GPU node starts earning its keep the moment you register it. Chat completions, embeddings, reranking, OCR, and audio transcription each get their standard endpoint, so existing OpenAI SDK code, LangChain, and LlamaIndex projects point at a new base URL and keep working. Governance is built in rather than bolted on: organizations, users, and roles control who may call which model, API keys authenticate every request, and rate limiting keeps one enthusiastic team from eating the whole cluster. Usage monitoring follows every inference, and carbon footprint estimates attach to models through their hosting zone and parameter counts. Retrieval-augmented generation against Elasticsearch or Qdrant plugs into the same surface. No chat history is stored, which is rather the point when the data is yours. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- One API For Every Backend
- Applications speak a single OpenAI-compatible dialect while the gateway translates for vLLM, Ollama, Mistral, TEI, Albert, and OpenAI behind it. Swapping a backend stops being an application change.
- Governance Built In
- Organizations, users, and roles decide who can call which model, API keys authenticate requests, and rate limits protect shared GPU capacity from one team's runaway batch job.
- Load Balanced By Design
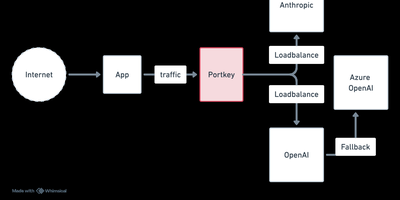
- A named router fronts several provider APIs for the same model and balances traffic by shuffle or least-busy strategy, so adding inference capacity is a registration, not a migration.
- Sovereign And Observable
- No chat history is stored, inference traffic is monitored, and carbon estimates follow each model from its hosting zone and parameter count. Your prompts stay on infrastructure you govern.
Features
- Five Endpoint Families
- Chat completions, embeddings, rerank, OCR, and audio transcription endpoints activate per model type, covering language, retrieval, document, and speech workloads through one gateway.
- Provider Load Balancing
- Routers bind a public model name to multiple provider APIs (vLLM, Ollama, TEI, Mistral, Albert, OpenAI) and distribute requests with shuffle or least-busy strategies.
- Built-In RAG Support
- Retrieval-augmented generation queries Elasticsearch or Qdrant vector stores, so document-grounded answers ride the same authenticated API as plain chat.
- Carbon Footprint Tracking
- Each model declares its hosting zone and total and active parameter counts; the gateway estimates inference emissions using the EcoLogits methodology.
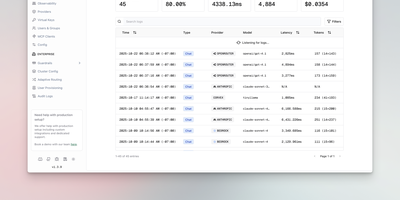
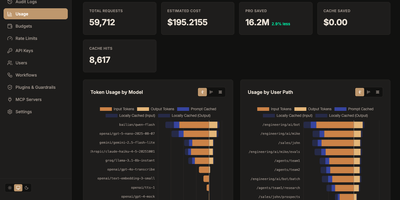
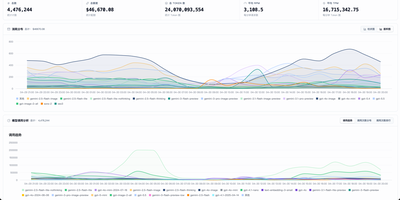
- Grafana Monitoring Templates
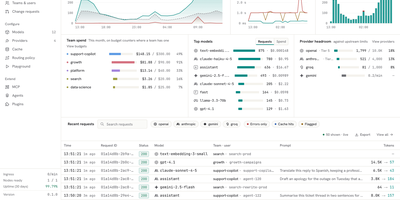
- Shipped Grafana dashboards chart inference and gateway traffic, complementing per-request usage monitoring for capacity and cost reviews.