Stars
Forks
Watchers
Developer links
PullMD
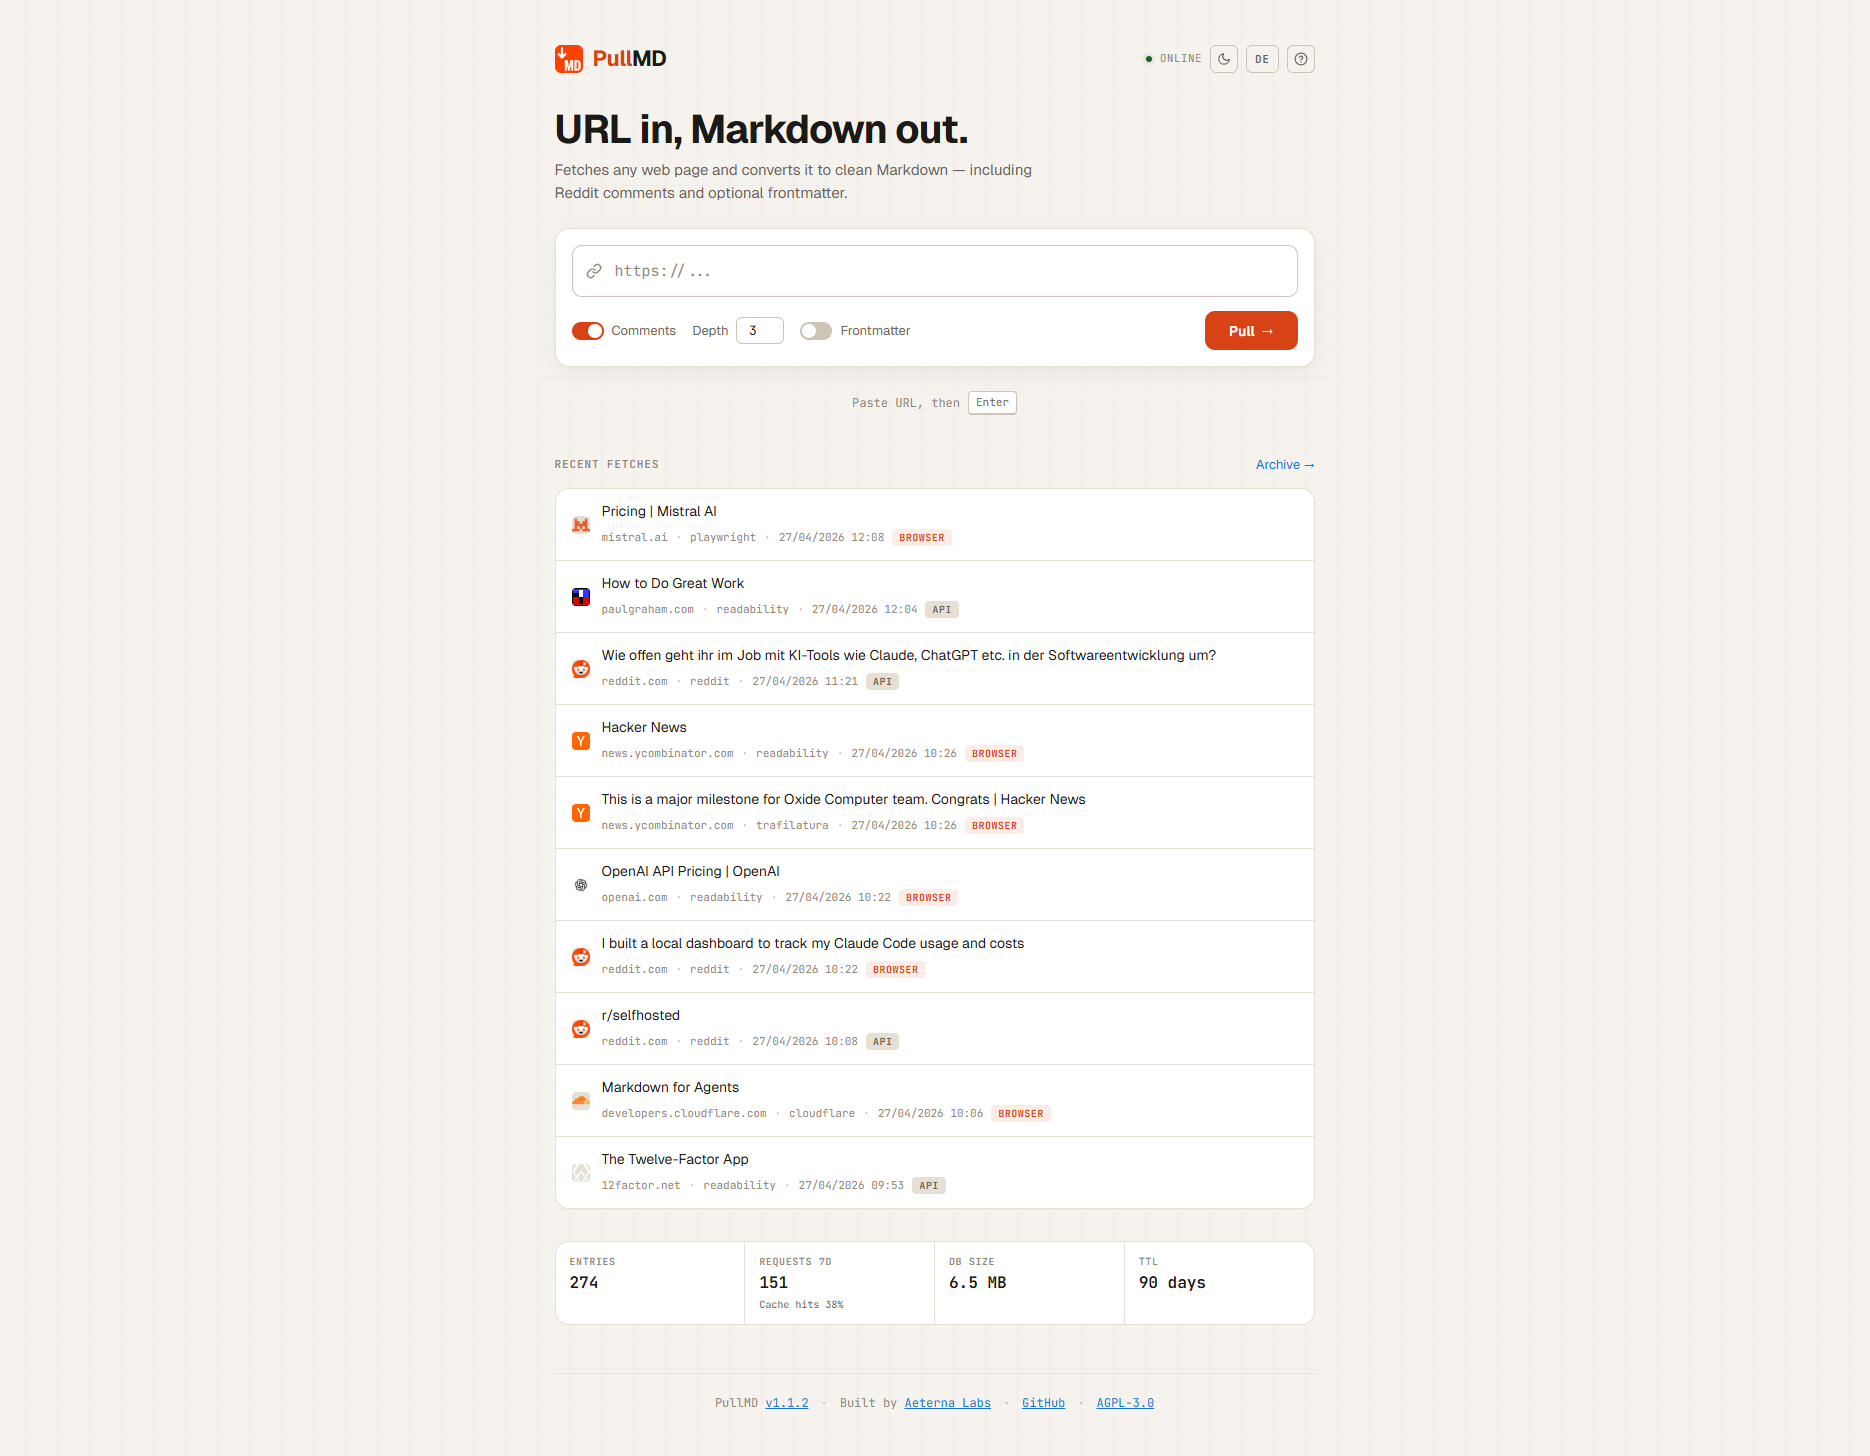
PullMD turns any URL or file you point it at into clean Markdown your AI agent can actually afford to read. Paste a web page and get back tidy body text with metadata tucked into frontmatter instead of navigation soup and cookie banners. Send it a Reddit or Hacker News thread and it returns the full comment tree with depth and count under your control. Hand it a PDF, Word file, PowerPoint, spreadsheet, or EPUB and it hands back Markdown, with an optional OCR tier for stubborn table-heavy documents. YouTube links come back as title, description, and a transcript with clickable timecodes, no API key required. The query-scoped mode answers a question about a long page by returning only the relevant sections, typically cutting 70 to 95 percent of the tokens. Every conversion gets a short share link that re-fetches the source when it goes stale and serves the last good snapshot if the original dies. Agents connect through the built-in MCP server with OAuth 2.1, a plain REST API, or a downloadable Claude Code skill, while you keep history, an archive, and cache statistics in the web app. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Benefits
- Token-Lean Markdown Output
- Pages return as clean body text with metadata in frontmatter, unpadded tables, and query-scoped extraction that typically removes 70 to 95 percent of tokens from long pages before your model pays for them.
- Reads Nearly Everything
- Web pages pass through a fallback chain of native Markdown, Readability with Trafilatura, and headless Chromium, while documents, images, audio, and YouTube transcripts each get their own conversion pipeline.
- Share Links Stay Fresh
- Every conversion receives a short stable address that re-fetches the source when the cached copy is older than an hour and falls back to the last good snapshot if the source disappears entirely.
- Agent-Native Interfaces Included
- A stateless MCP server with OAuth 2.1, a one-line REST API, and a downloadable Claude Code skill let Claude Code, Cursor, and other agents fetch clean Markdown without local installs or prompt hacks.
Features
- Web Page Extraction
- A fallback chain tries native site Markdown, then Readability plus Trafilatura with best-result scoring, then headless Chromium rendering for JavaScript-heavy pages that defeat simpler extractors.
- Document Conversion
- PDF, Word, PowerPoint, Excel, and EPUB files convert by URL or upload through an optional sidecar, with an OCR tier available for scanned or table-grade PDFs that need text recovery.
- Thread And Transcript Capture
- Reddit and Hacker News threads return with their comment trees at configurable depth, and YouTube videos return title, description, and transcripts with clickable timecodes and no API key.
- Image And Audio Understanding
- Images become captions and audio becomes transcripts through any OpenAI-compatible or local vision and speech model you configure, so media files join the same Markdown workflow.
- History, Archive, Statistics
- The web app keeps your recent conversions, a paginated archive, cache size and hit-rate statistics, extraction telemetry, and a sidecar health endpoint that monitoring tools can poll.