Categories
Self-Hosted Developer Tools Observability AI Gateway API Management LLM Proxy Model Routing Cost ControlStars
Forks
Watchers
Developer links
Nyro
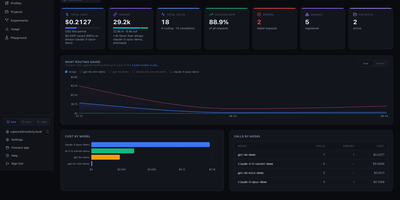
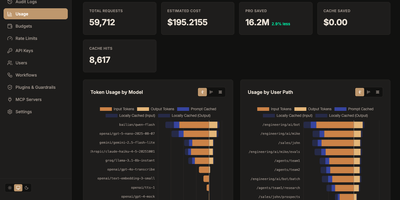
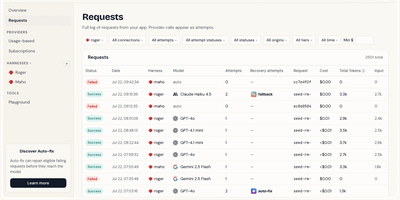
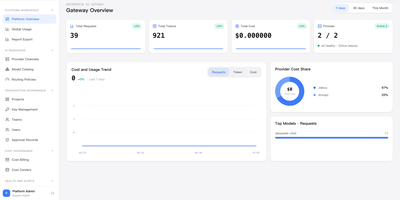
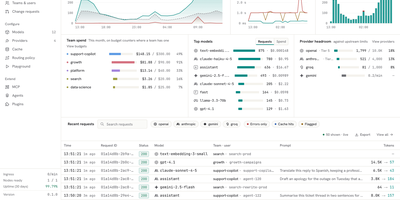
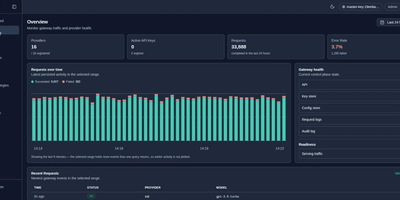
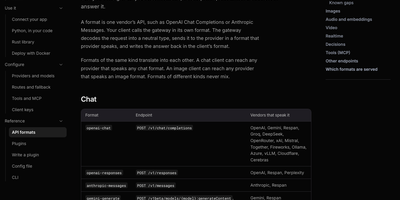
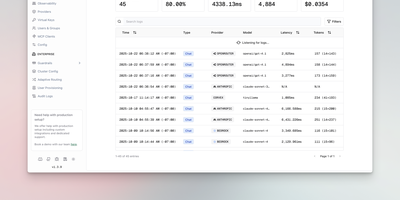
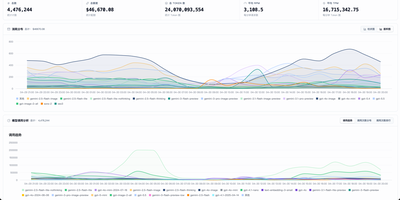
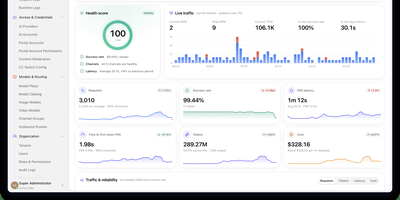
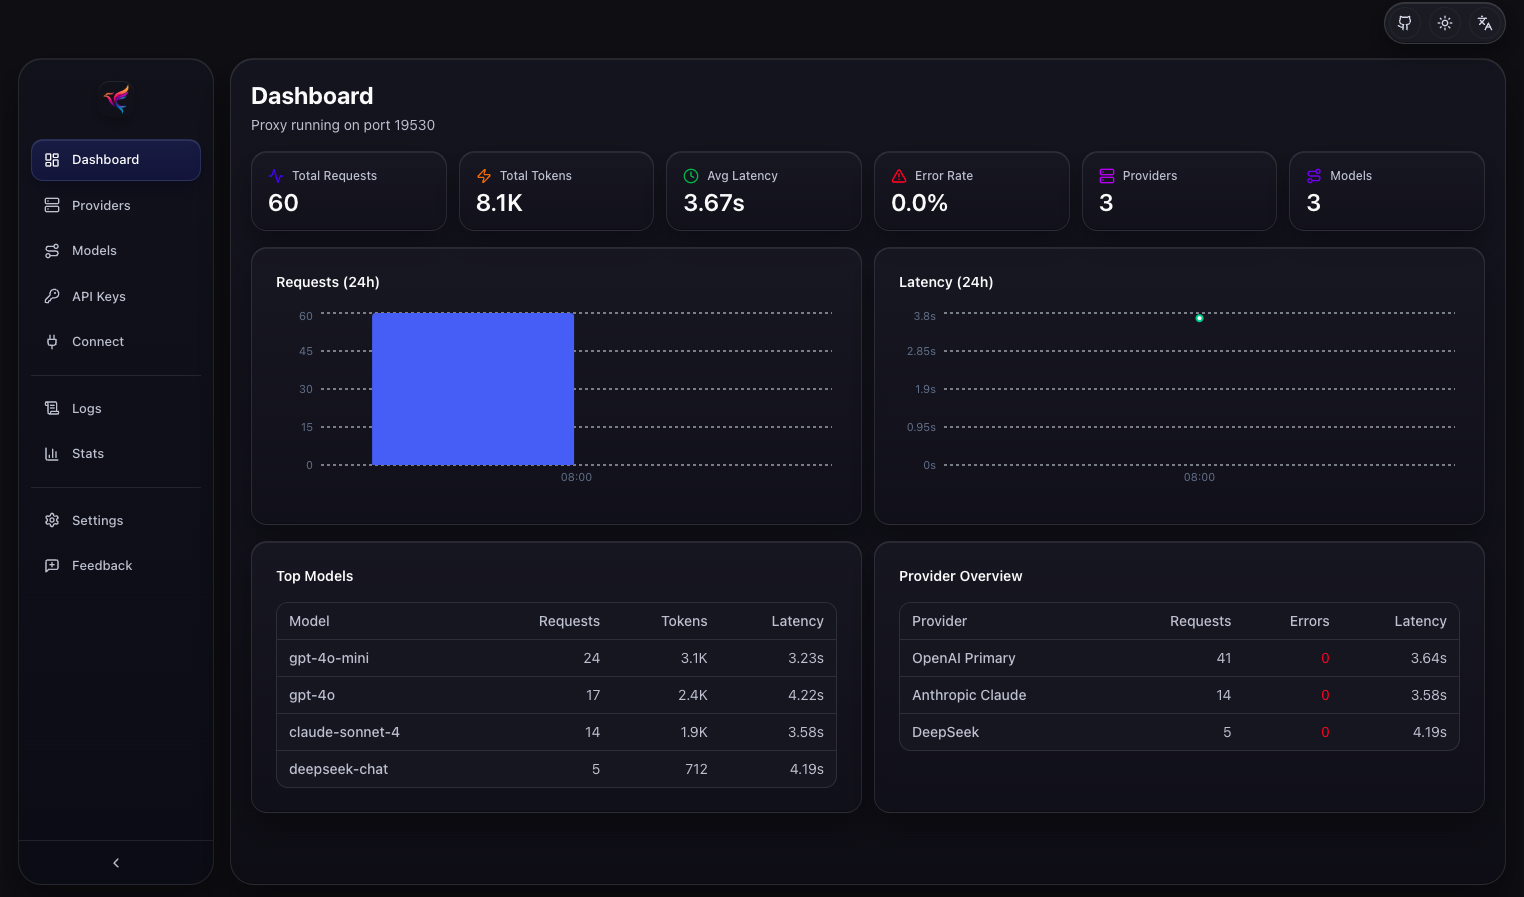
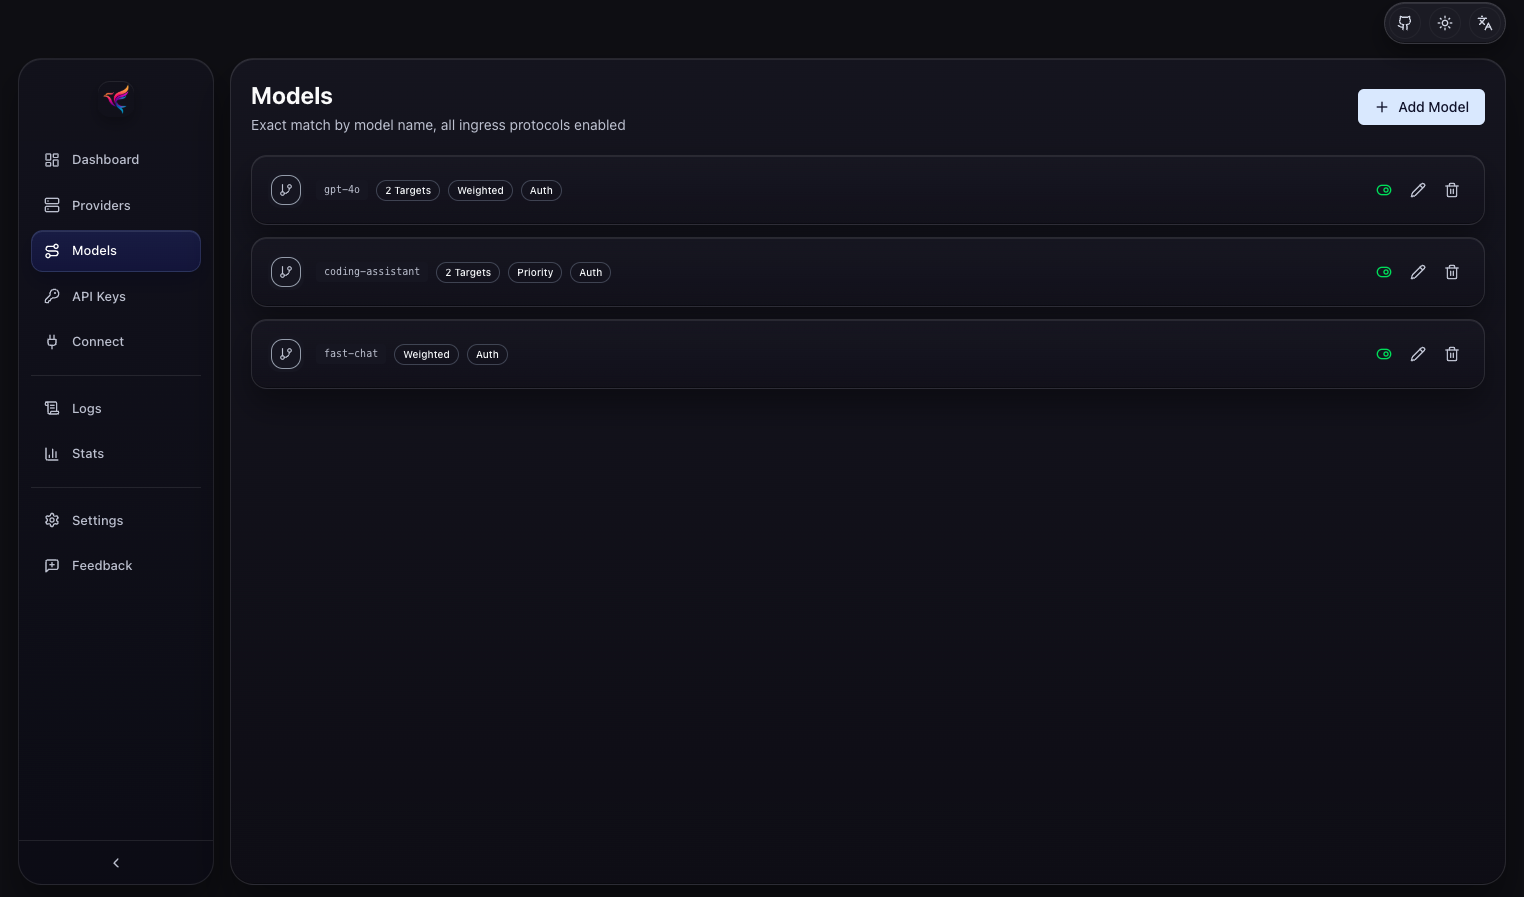
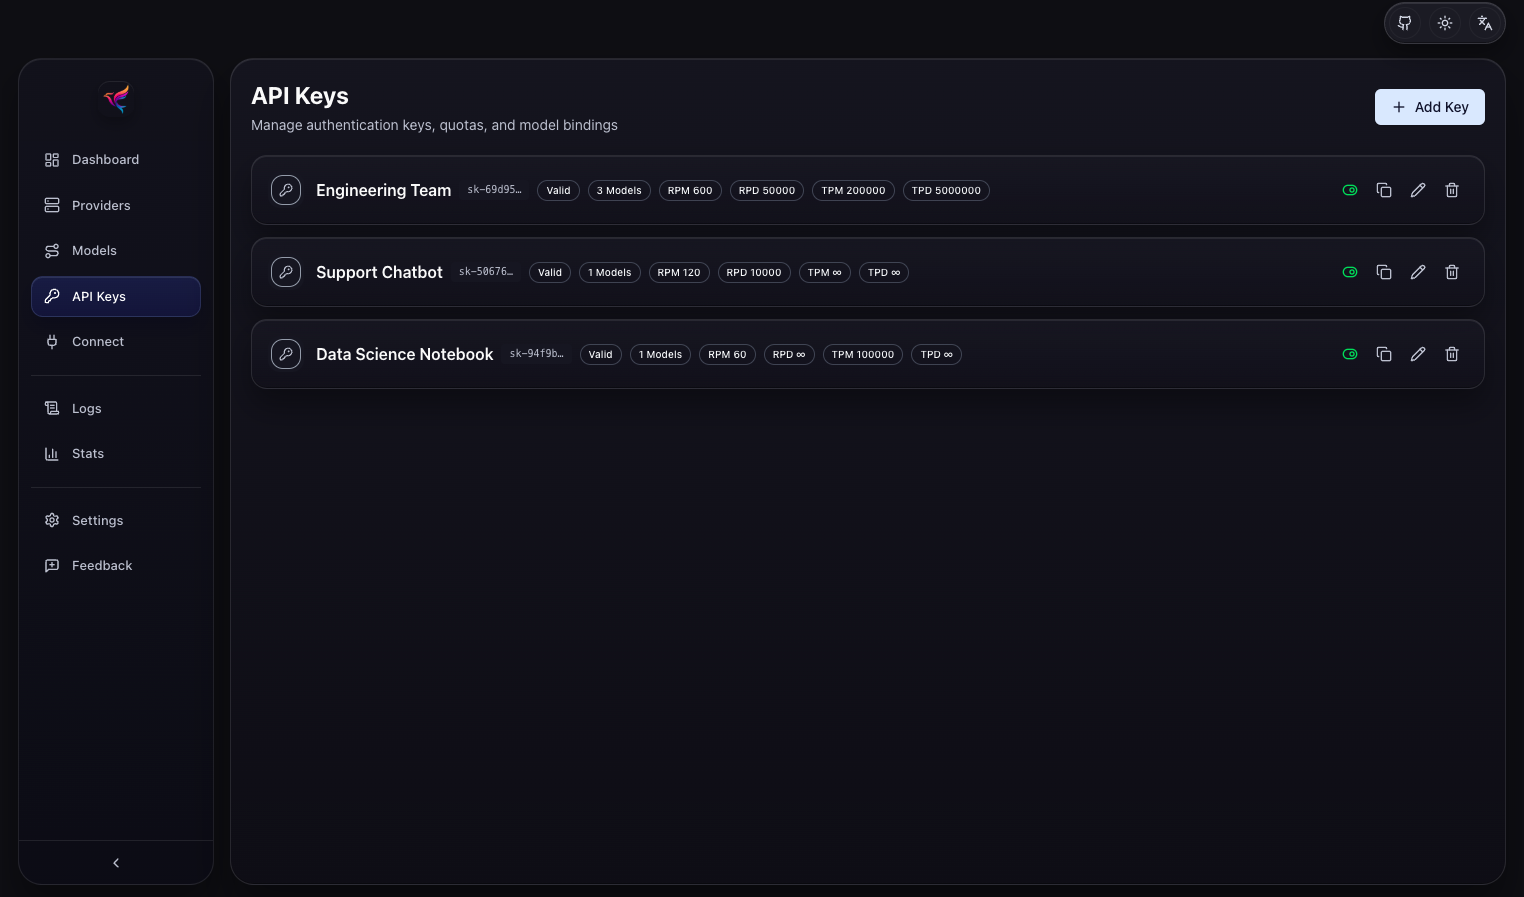
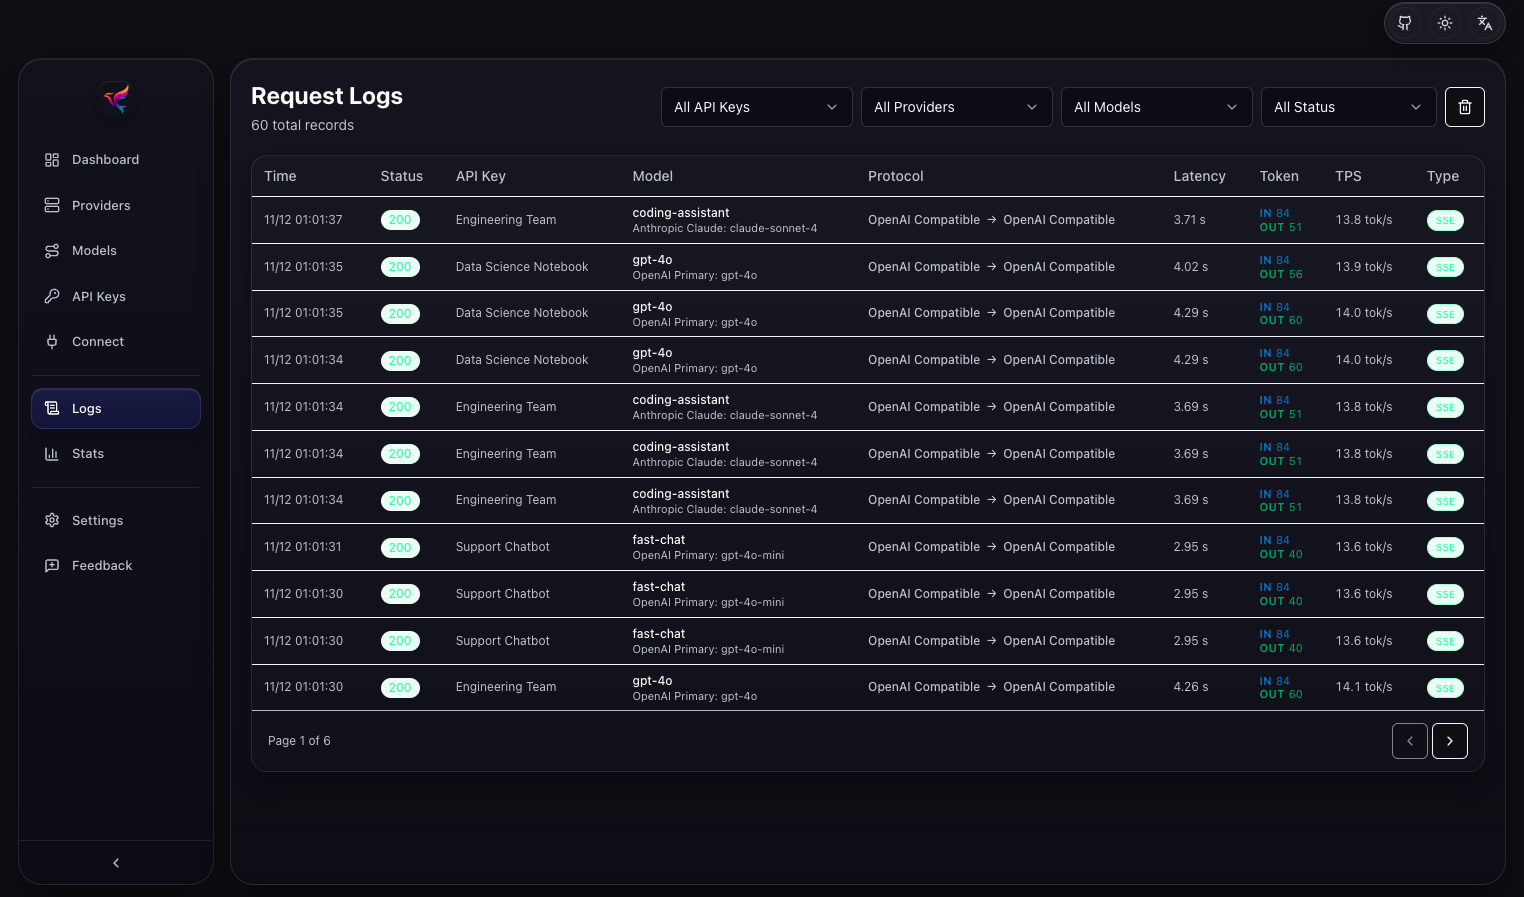
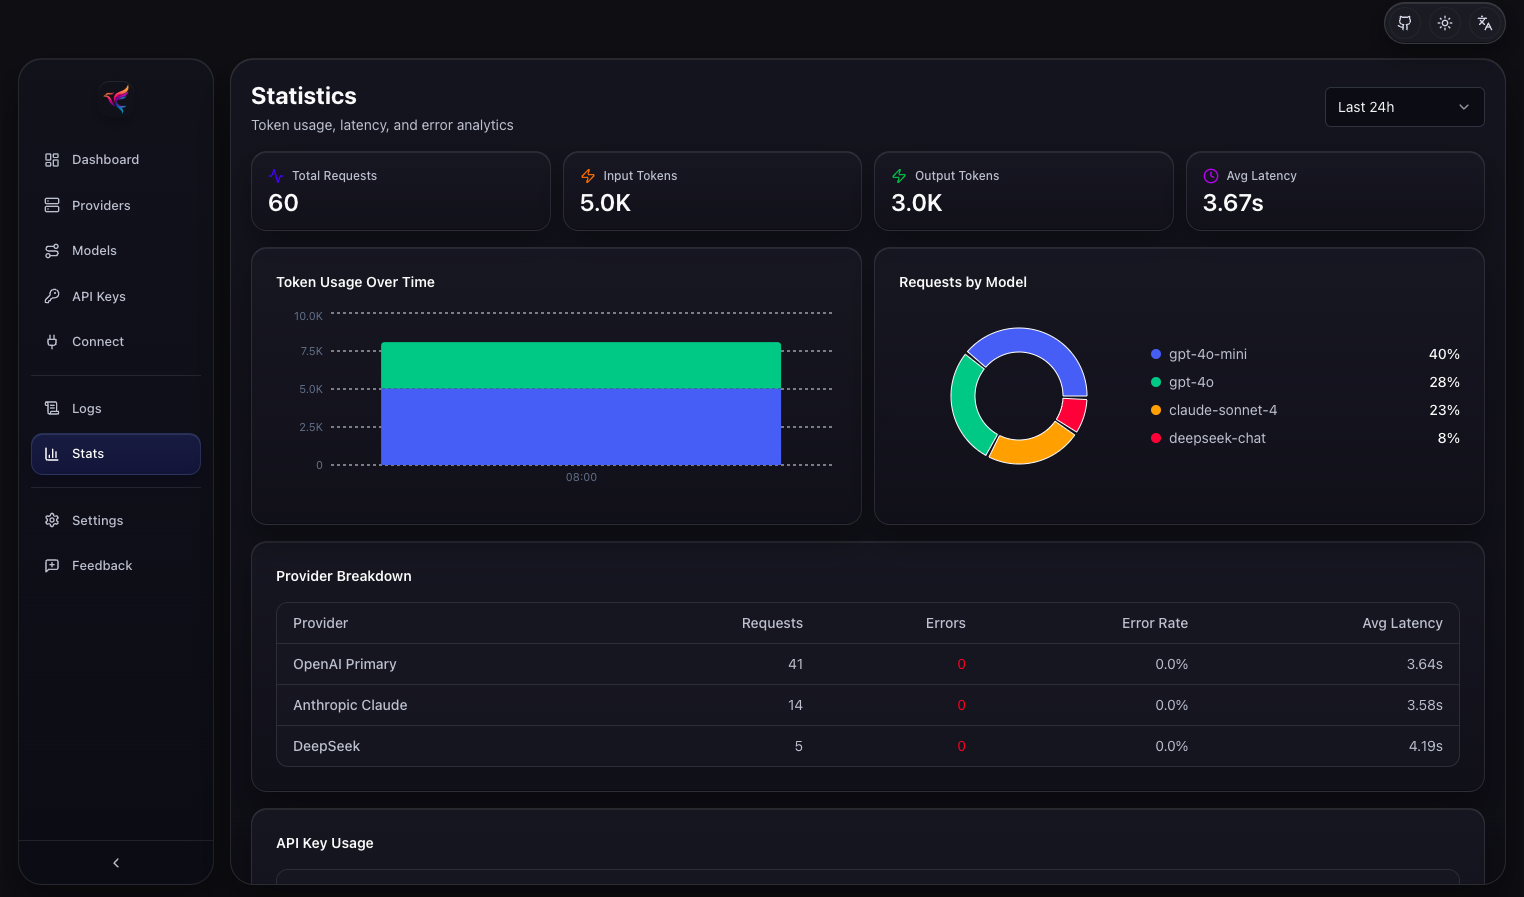
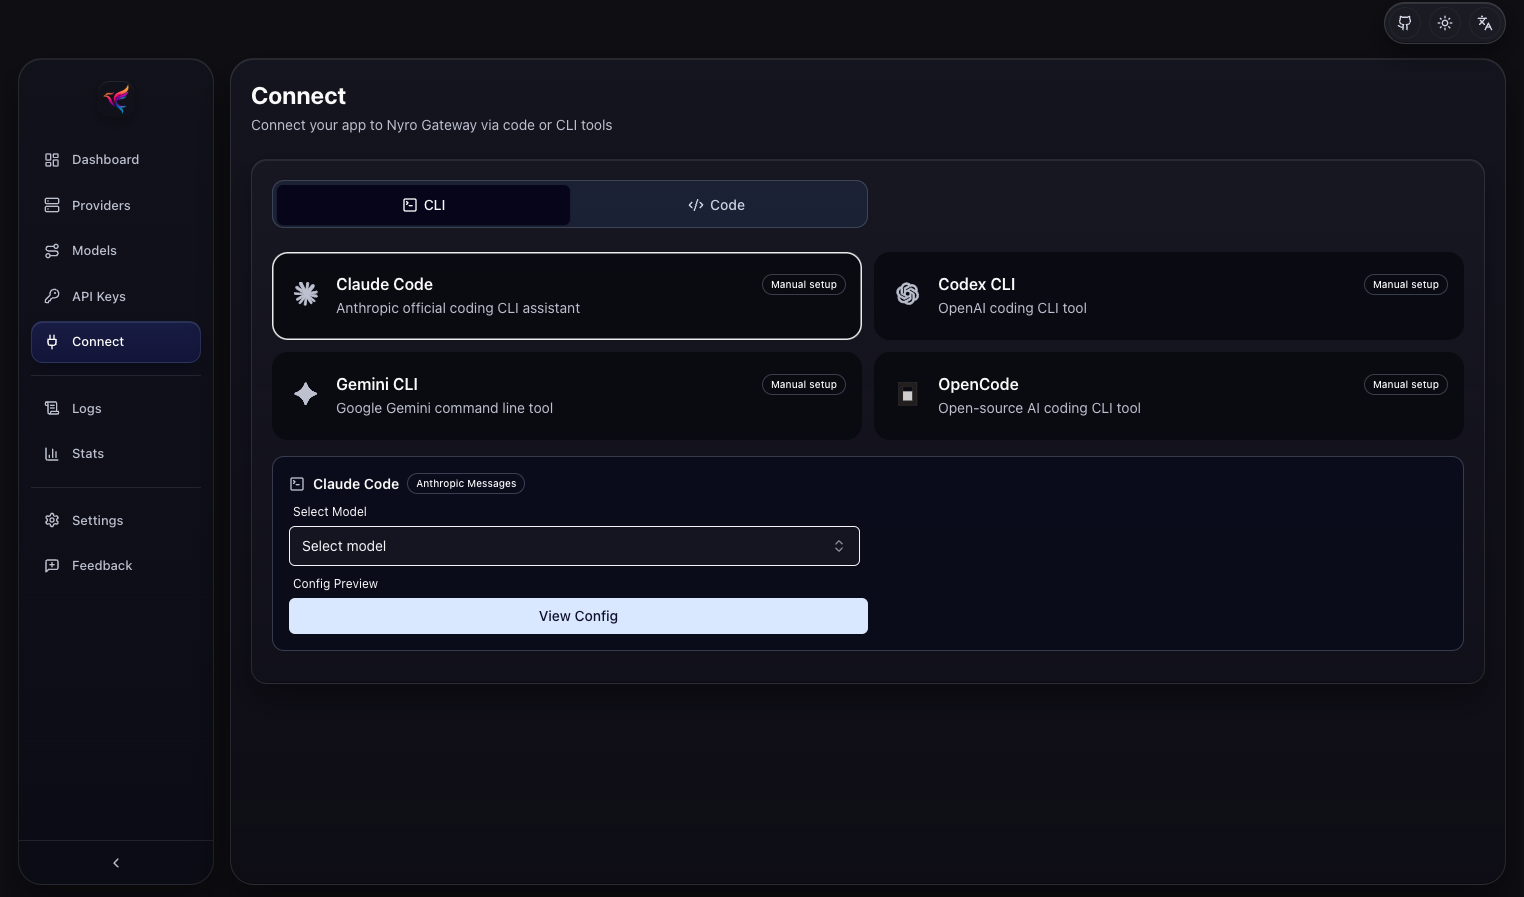
Point Claude Code, Codex CLI, Gemini CLI, or any OpenAI, Anthropic, or Gemini SDK at one address and Nyro routes every request to whichever model provider you choose. The gateway translates protocols on the fly, including streaming, reasoning blocks, and tool calls, so a tool built for one API can run on a model from another. Define virtual model names, bind each to one or more providers, and pick weighted load balancing or priority failover; unhealthy targets are skipped and recover automatically. Issue API keys with limits on requests and tokens per minute and per day, and bind each key only to the models it may call. Exact and semantic caching return repeated answers instantly. A request log records provider, model, token counts, latency, and streaming speed, and usage charts break traffic down by model and provider. The Connect page generates ready-to-paste samples in Python, TypeScript, and cURL, plus one-click configuration for popular coding CLIs. Choose an embedded database for a single host or an external PostgreSQL or MySQL server for production, and run the gateway, the admin UI, or both as separate processes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- Use Any Model With Any Tool
- Protocol translation lets Claude Code, Codex CLI, and SDK clients talk to one backend model, so you pick the provider without changing a line of client code.
- Switch Providers Without Reconfiguring
- Virtual model names decouple clients from backends, so you can move traffic to a cheaper or faster provider from the dashboard and every tool keeps working.
- Control Spend And Access Per Key
- Per-key request and token quotas plus explicit model bindings keep teams, bots, and notebooks inside their limits, and expired or unbound keys are denied by default.
- See Every Request And Token
- Searchable logs and usage charts show latency, tokens, and errors by model and provider, so you can spot slow backends and tune routing with real numbers.
Features
- Protocol Translation Gateway
- Accepts OpenAI Chat and Responses, Anthropic Messages, and Gemini requests, with streaming, reasoning, and tool calls converted between formats.
- Weighted And Priority Routing
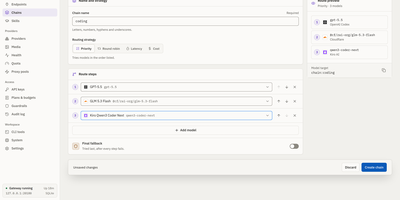
- Spread traffic across providers by weight or fail over by priority, with unhealthy targets skipped and automatically retried after a short recovery window.
- Exact And Semantic Caching
- Identical requests return stored responses instantly, and embedding-based matching reuses answers for similar questions, with per-model time to live and threshold overrides.
- API Keys And Quotas
- Create keys with per-minute and per-day request and token limits, expiry dates, and model bindings, then enable or disable them with one switch.
- Logs And Usage Stats
- Browse request logs with status, provider, tokens, latency, and tokens per second, and review usage charts grouped by model and provider.
- Connect Code And CLI
- Copy working Python, TypeScript, and cURL examples for any model, or generate configuration for Claude Code, Codex CLI, Gemini CLI, and OpenCode.