Categories
Self-Hosted Developer Tools AI Infrastructure LLM Gateway Local LLM OpenAI Compatible API Model Router Inference ManagementStars
Forks
Watchers
Developer links
llama-swap
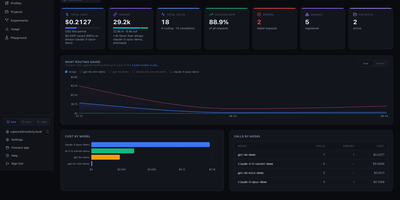
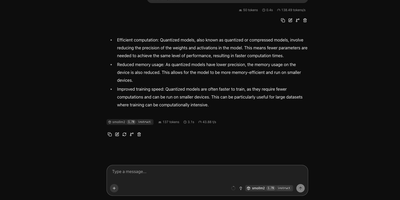
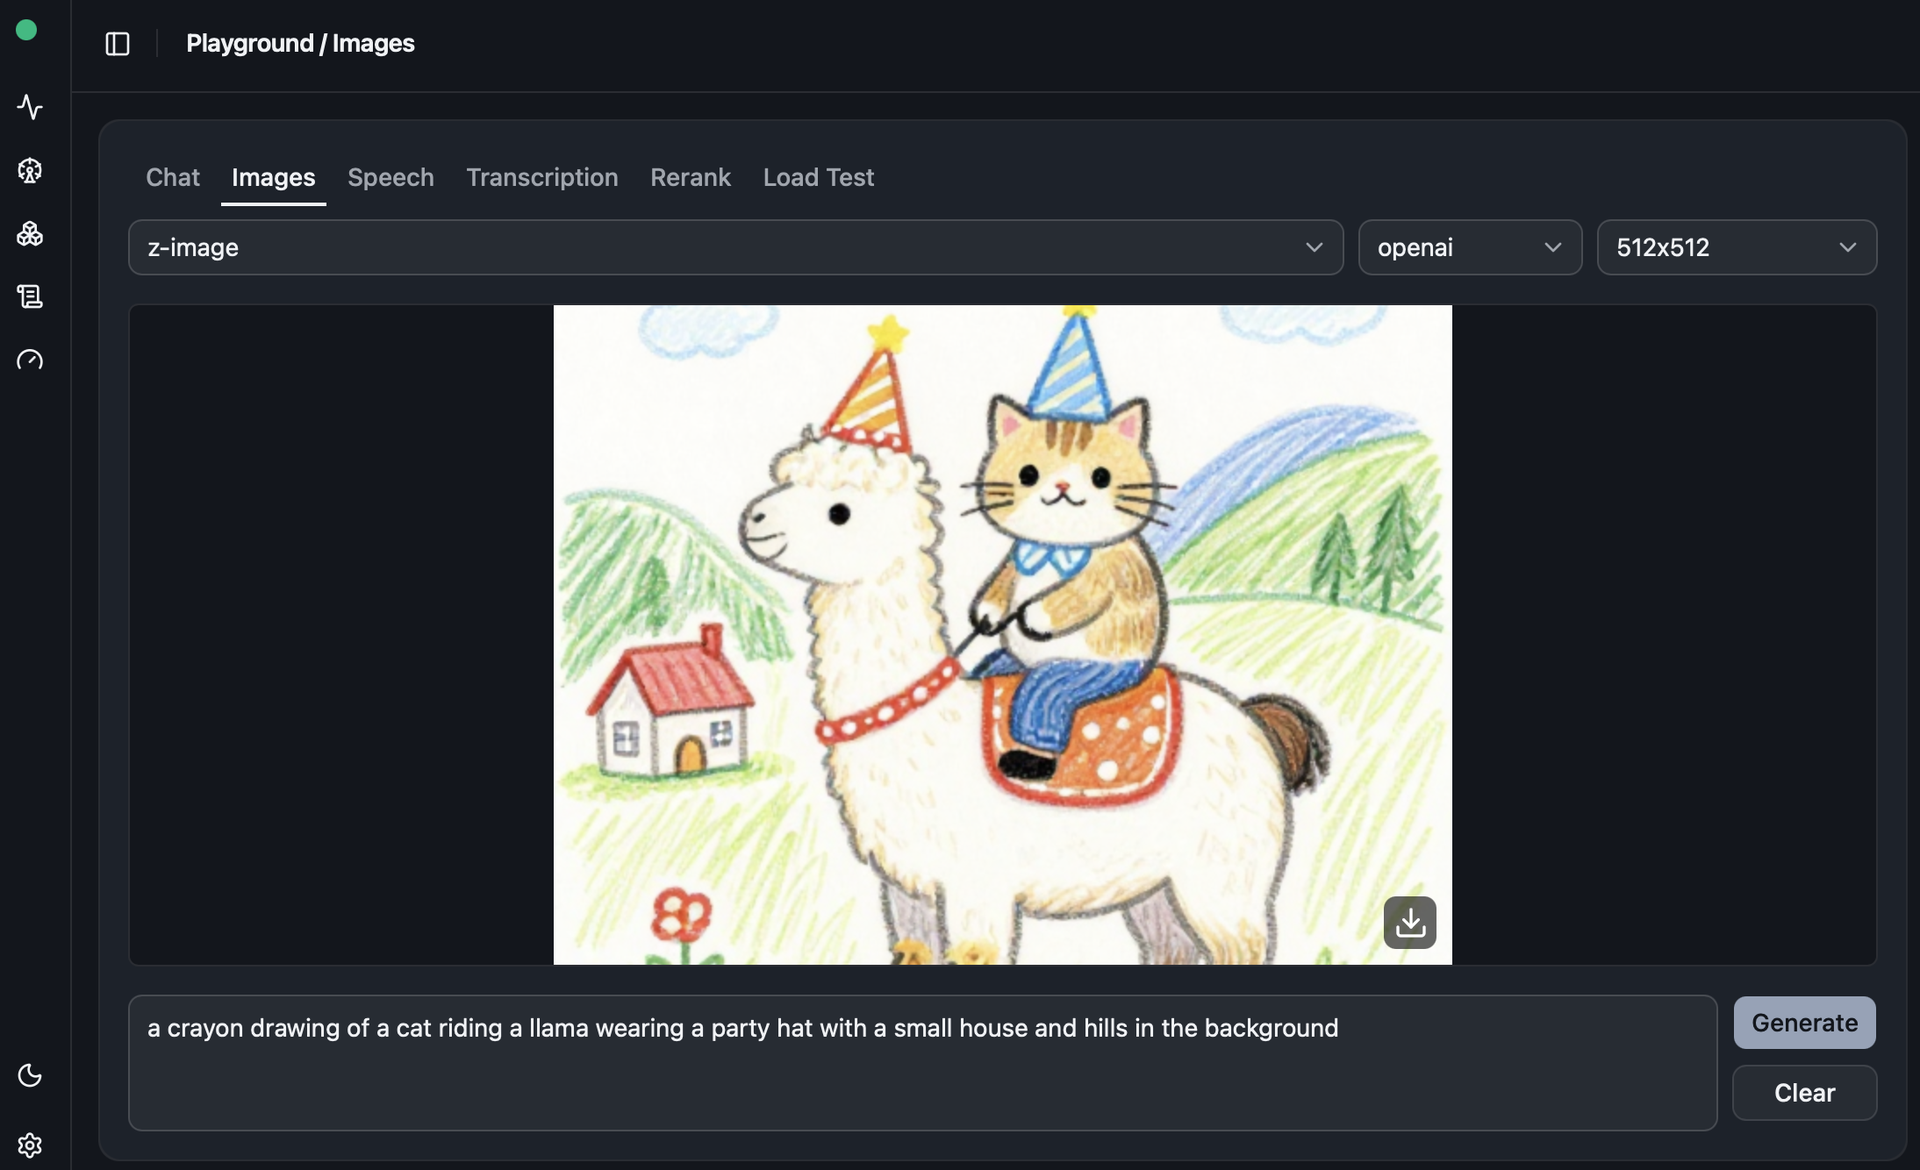
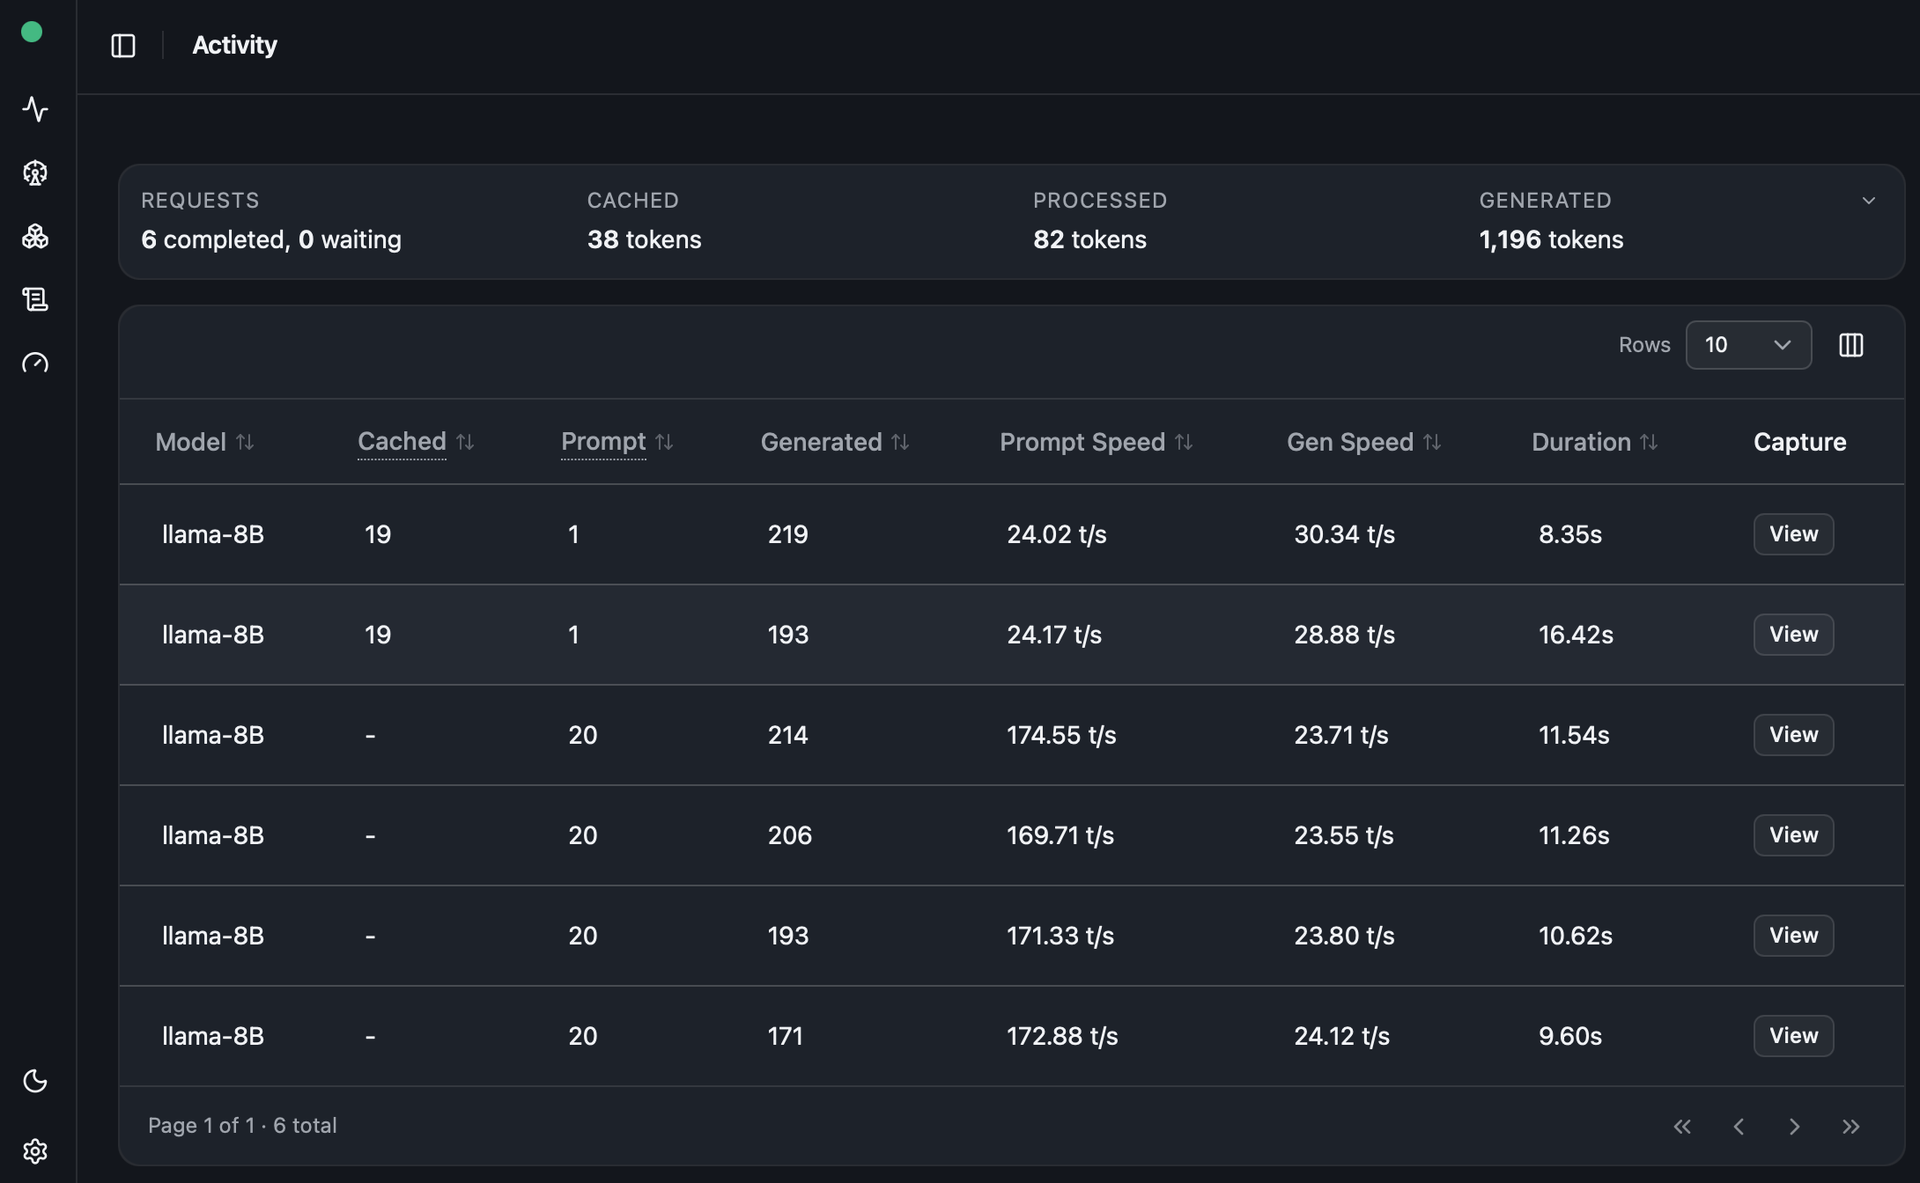
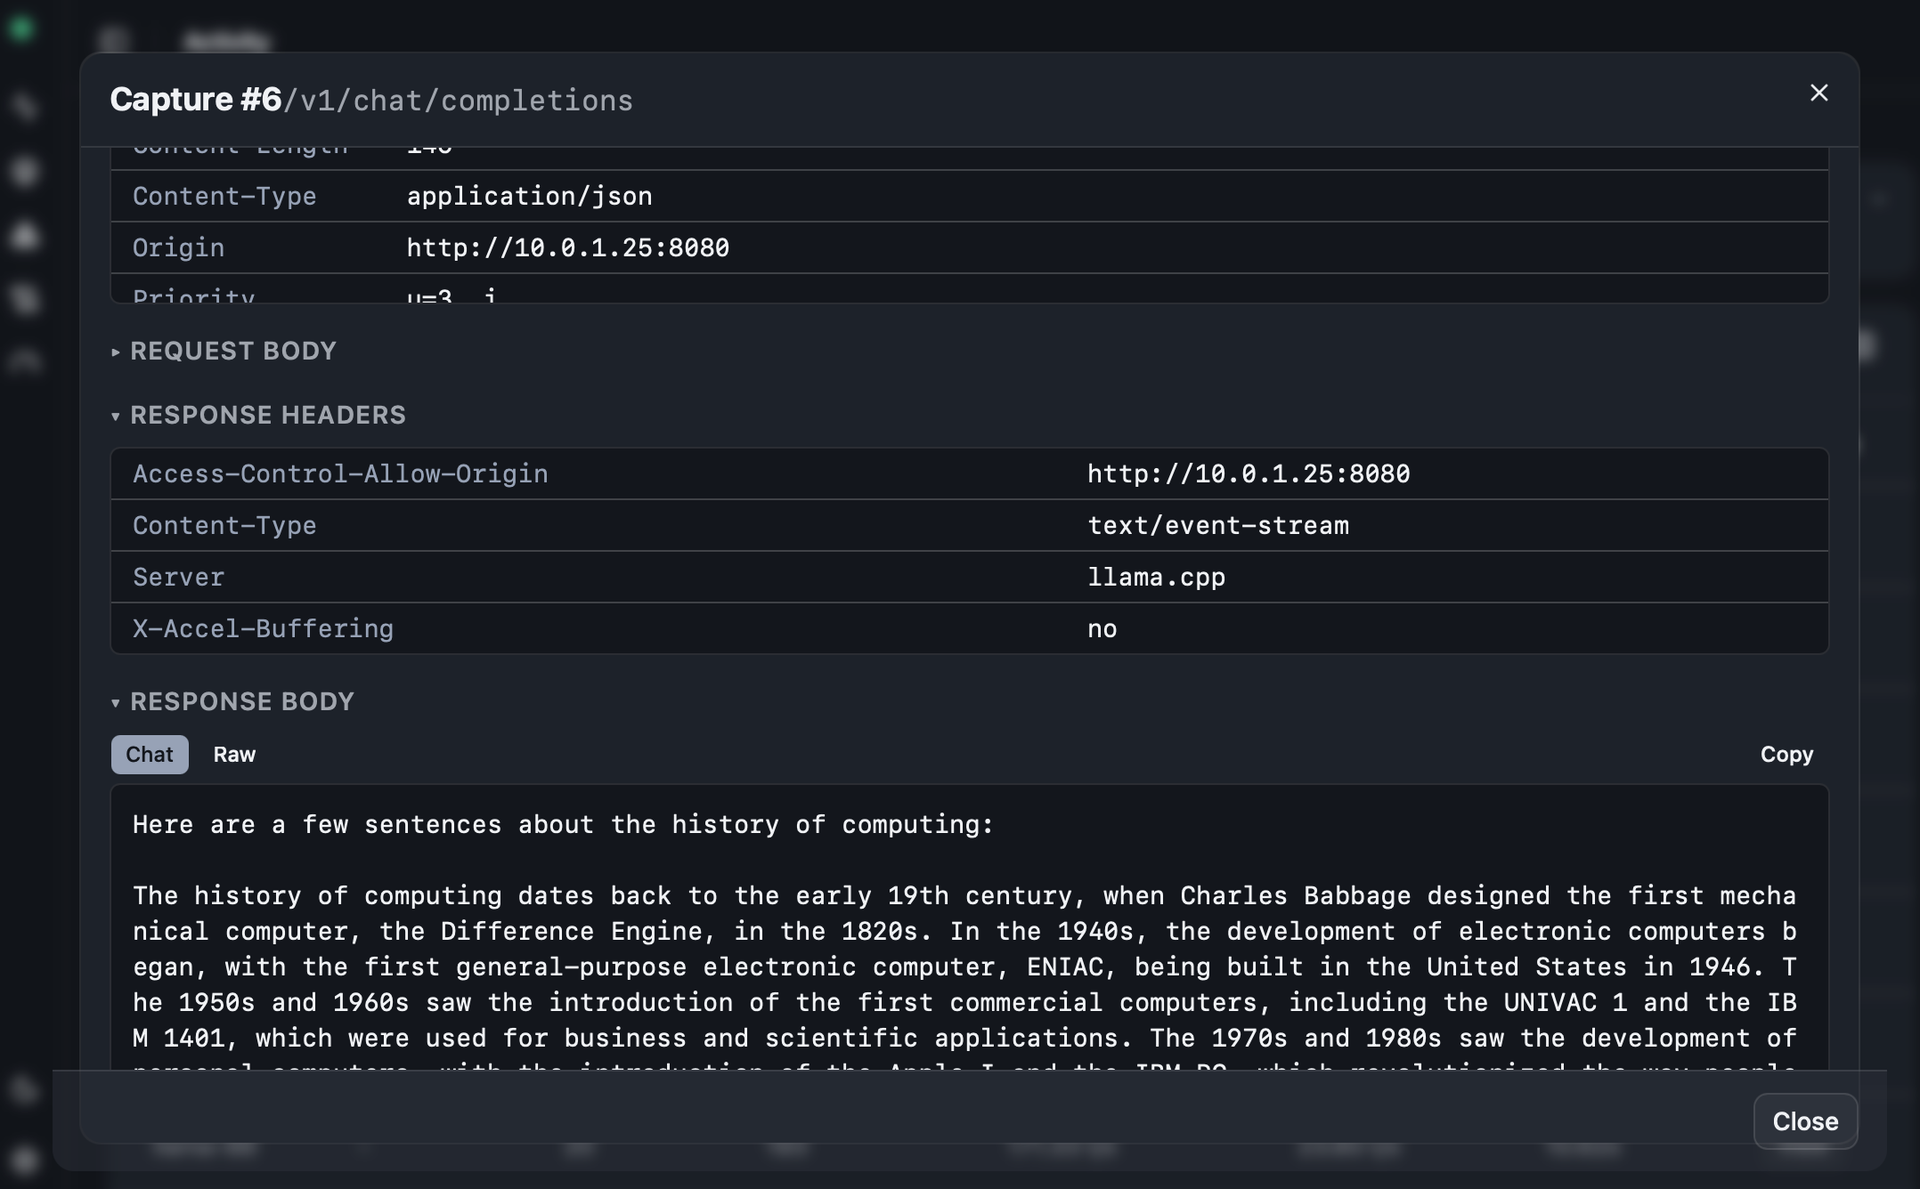
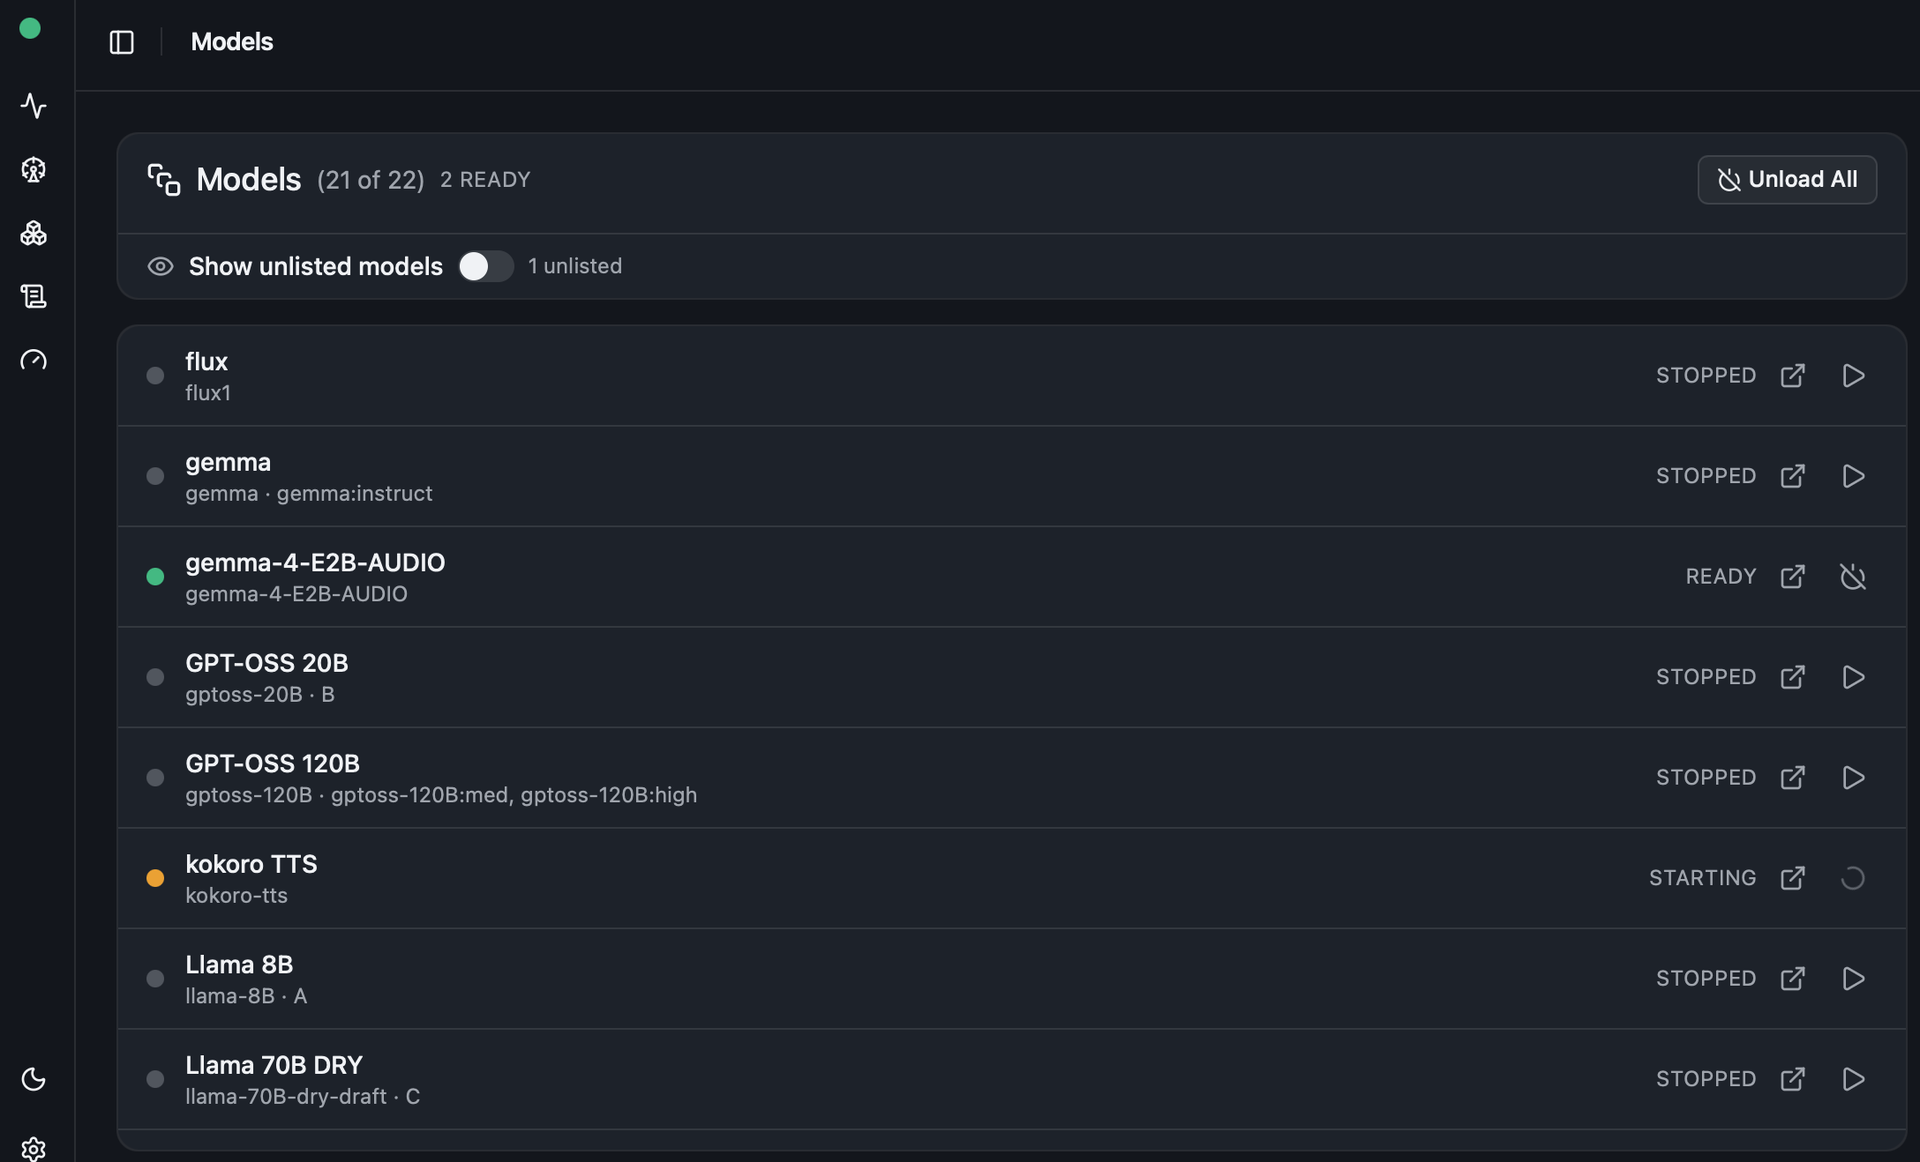
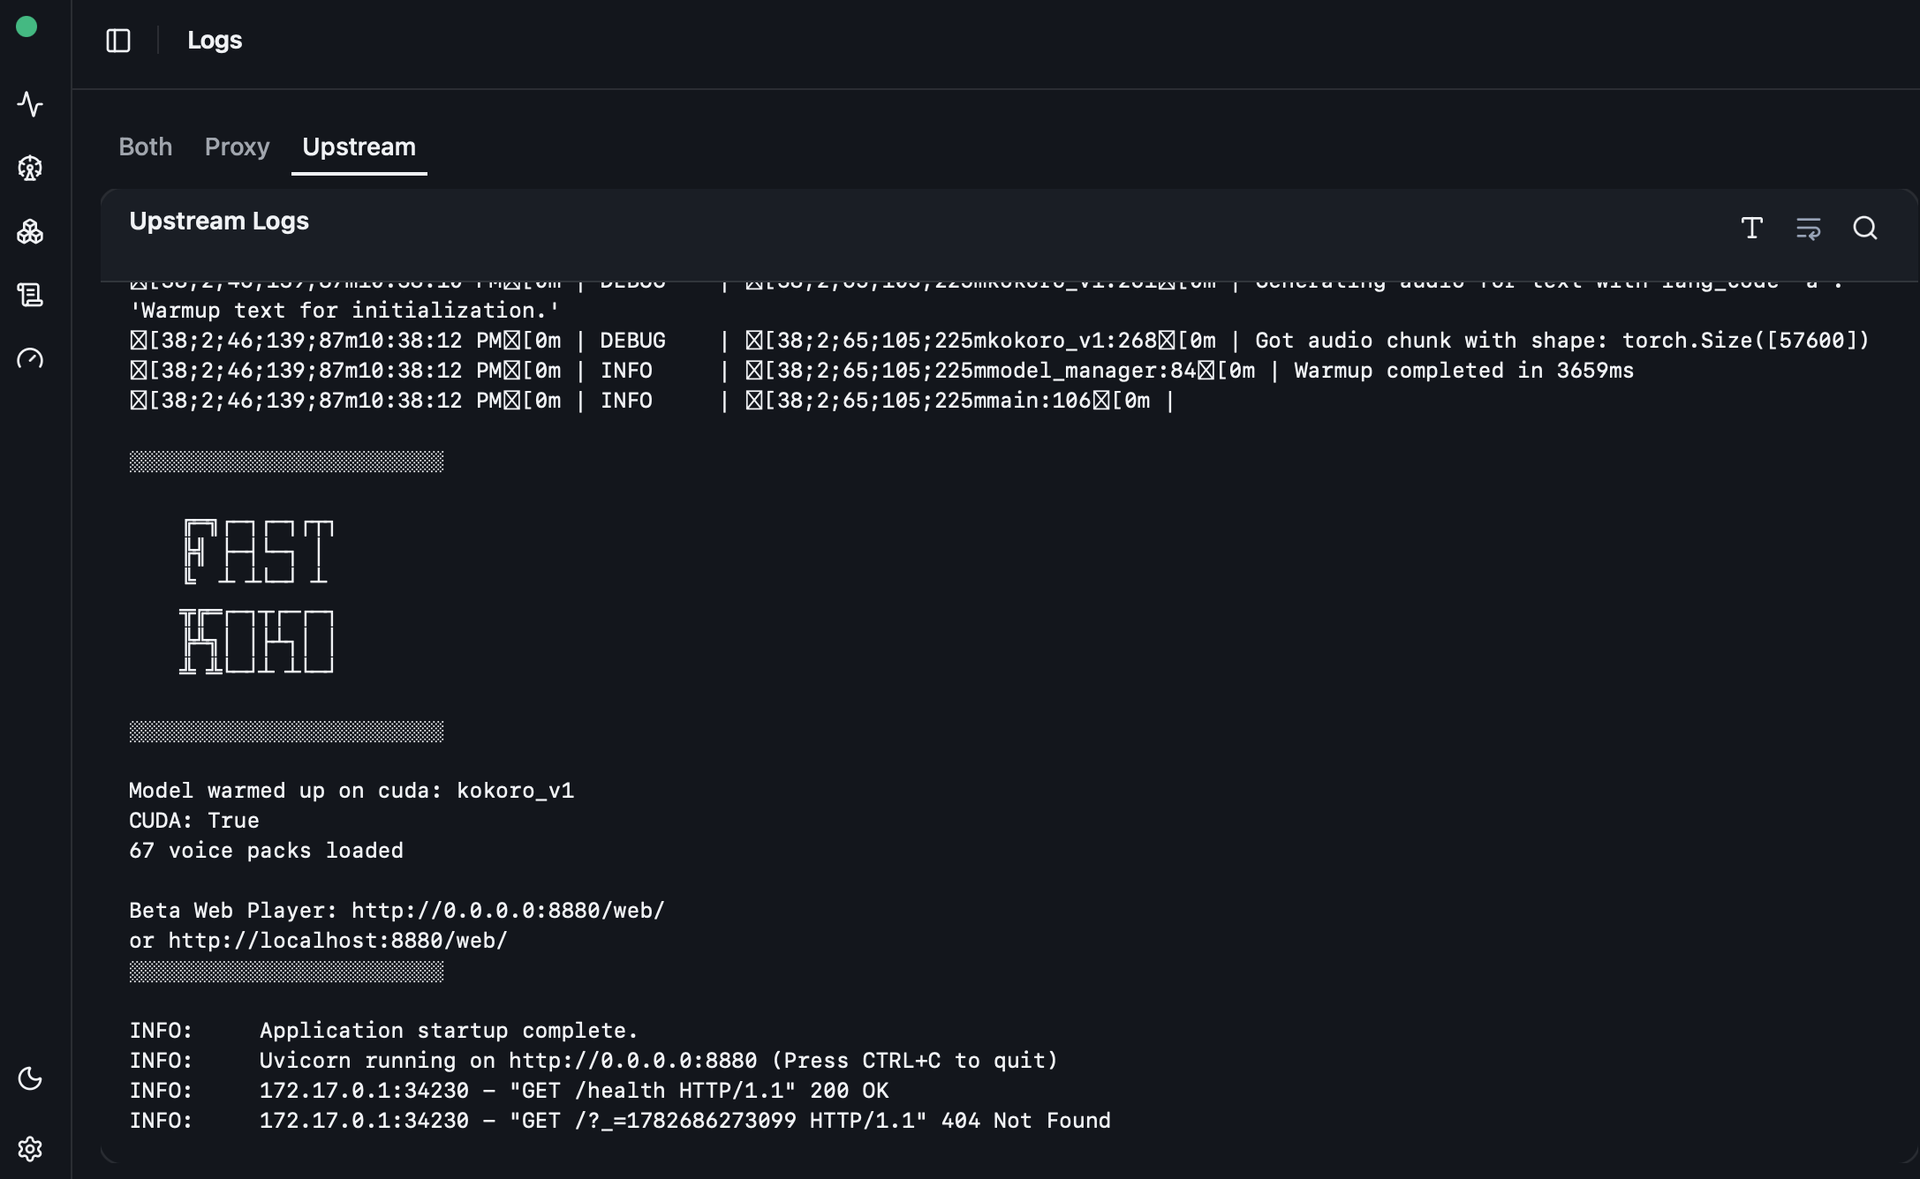
llama-swap puts one OpenAI-compatible and Anthropic-compatible endpoint in front of all your local models and loads whichever one each request names, unloading the one it replaces. Define models in a single YAML file, and chat, embedding, speech, transcription, and image requests reach the right backend automatically. The web UI includes a playground for chatting with any model, token metrics for every request, a request inspector that shows raw payloads and responses, buttons to load and unload models by hand, and a live log stream for the proxy and each upstream process. Profiles switch model routing at runtime, a swap matrix keeps selected models loaded together, and a time-to-live setting frees memory after idle periods. API keys restrict who can call the endpoints, and filters strip or force request parameters. Docker and Podman commands start and stop containers per model, and a Prometheus endpoint exposes system and GPU metrics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Run More Models Than Memory
- Models load on demand and unload when idle, so a modest server can offer dozens of models behind one address instead of keeping each one resident all day.
- Swap Inference Engines Freely
- Because llama-swap only proxies requests, you can upgrade llama.cpp, vLLM, or an image server independently, and your applications keep calling the same stable endpoint.
- Debug Requests Without Guessing
- Token metrics, a request inspector, and streaming logs sit in one interface, making it easy to see exactly what a client sent and how fast the model answered.
- Control Who Uses Your GPUs
- API keys, per-model parameter filters, and profiles let you share a single machine across teammates and tools, with access that stays limited and predictable.
Features
- Automatic Model Hot-Swapping
- Each request names a model; llama-swap starts its command, waits until it is healthy, stops the previous one, and forwards the call without client changes.
- Built-In Web Playground
- Chat with any configured model, compare outputs, and test prompts from the browser with streaming responses, without writing a single line of client code.
- Token Metrics Dashboard
- Review prompt and generation token counts, speeds, and timing for every request, so slow models and heavy prompts are easy to spot.
- Request And Response Inspector
- Open any captured request to read its headers, body, and the upstream reply, which speeds up troubleshooting of client integrations and prompt templates.
- Live Log Streaming
- Follow proxy, upstream, and per-model logs in real time from the browser or over HTTP, with buffered history delivered first for context.
- Profiles And Swap Matrix
- Switch routing sets at runtime and define which models may run together, so memory is planned deliberately instead of guessed at.