Archestra
Archestra delivers the enterprise AI infrastructure layer that organizations need when managing multiple LLM providers, MCP servers, and AI agents across teams becomes unmanageable. The LLM gateway routes requests across Anthropic, OpenAI, Azure, Bedrock, and DeepSeek with virtual API keys, per-team cost limits, and dynamic model routing — giving every developer one token for Claude Code, Cursor, or Codex while finance tracks spend per department. The MCP gateway authenticates tool calls with OAuth 2.1 and On-Behalf-Of tokens so each tool executes as the calling user, not a shared service account, eliminating credential sprawl. The private MCP registry lets teams publish custom tool servers with approval flows promoting servers from dev through staging to production, each environment maintaining its own credentials and network egress policies. The Kubernetes operator manages MCP server lifecycle — deploying containers, scaling, health-checking, and routing gateway traffic to local servers automatically. The agent runtime supports scheduled triggers, email and webhook invocations, sub-agent delegation, reusable skills, and sandboxed code execution with a K8s-native filesystem. Deterministic guardrails including Dual-LLM verification and Lethal Trifecta protections prevent dangerous tool calls before execution. Built-in OpenTelemetry traces and Prometheus metrics provide full observability without additional tooling. Docker deployment exposes the Admin UI on port 3000 and API on port 9000 with a single command. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Agent Gateway
Backed by the Linux Foundation with contributions from AWS, Cisco, IBM, Microsoft, Red Hat, and Shell, Agentgateway is the first data plane built from the ground up for AI agent workloads — providing a unified Rust-based proxy that handles conventional HTTP and gRPC traffic alongside MCP tool servers, A2A agent communication, and LLM inference endpoints through a single deployment. The LLM gateway routes requests to OpenAI, Anthropic, Gemini, AWS Bedrock, and other providers through an OpenAI-compatible unified API with per-tenant budget controls, spend tracking, prompt enrichment, load balancing across multiple model endpoints, and automatic failover when providers experience outages. The MCP gateway federates multiple tool servers behind one endpoint, supporting stdio, HTTP/SSE, and Streamable HTTP transports with built-in OAuth authentication compliant with the MCP auth specification, integrating Auth0 and Keycloak out of the box. OpenAPI integration exposes existing REST APIs as MCP-native tools without code changes, enabling legacy services to participate in agent workflows. Policy-based RBAC controls which agents access which tools, while OpenTelemetry integration provides distributed tracing across agent communication chains. Deploy as a standalone binary with flat YAML configuration or on Kubernetes using the built-in controller with Gateway API support for declarative infrastructure-as-code management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
New API
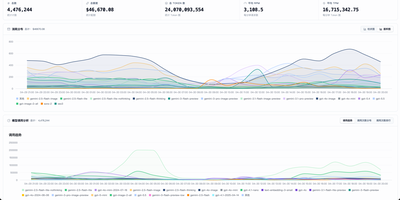
New API is a Go-powered LLM gateway that funnels over 40 AI providers, from OpenAI and Anthropic to Google Gemini, Azure, AWS Bedrock, DeepSeek, and Mistral, through a single OpenAI-compatible endpoint with intelligent routing and enterprise cost controls. Bidirectional format conversion translates between OpenAI Chat Completions, Claude Messages, and Gemini GenerateContent APIs transparently, so clients call any provider using their preferred format while the gateway handles the rest. Routing logic supports weighted random channel selection, priority-based failover, and automatic retry on provider errors to maximize uptime. The React admin dashboard shows usage charts, token consumption tracking, per-model cost breakdowns, and real-time request monitoring. Multi-tenant architecture includes three role levels, token-based authentication, per-user quota management, and a three-phase billing system with tiered pricing via a custom expression language. Multimodal support covers text completion, vision, embeddings, text-to-speech, speech-to-text, image generation, and creative task providers like Midjourney-Proxy and Suno-API. The interface ships in five languages including English, Chinese, Japanese, and French. Docker deployment runs with SQLite or MySQL for persistence. 45,000+ GitHub stars. AGPL-3.0 licensed.
Open Connector
With over 5,000 GitHub stars since its June 2026 launch, OOMOL OpenConnector bridges the gap between AI agents and the real world by handling the authentication nightmare that stops LLMs from calling external APIs safely. The runtime connects to more than 1,000 SaaS providers — GitHub, Gmail, Notion, Slack, Microsoft, HubSpot, Google Workspace, and hundreds more — through 10,000+ prebuilt typed Actions that agents can discover and execute without ever touching raw credentials. OAuth2 flows, API key rotation, custom credentials, and no-auth providers are all managed centrally with AES-encrypted storage, scoped runtime tokens, and configurable action allowlists and blocklists that enforce least-privilege access. Agents interact through five access surfaces: the Model Context Protocol endpoint at /mcp for Claude and other MCP-capable hosts, a full REST API at /v1 for programmatic control, an auto-generated OpenAPI specification for code generation, a TypeScript SDK for application integration, and the oo CLI for local agent relay. The built-in Web Console provides browser-based administration for configuring OAuth apps, managing connections, inspecting action schemas, and reviewing execution logs with redacted inputs. Deploy via Docker Compose with SQLite for single-server setups, run from source on Node.js 22+, or push to Cloudflare Workers with D1 and R2 for edge deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
AnythingMCP
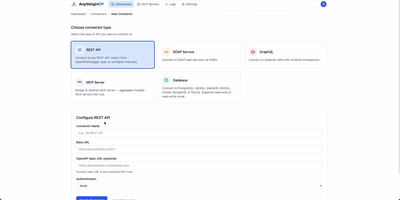
Connecting autonomous AI assistants to internal enterprise databases and legacy systems is streamlined by AnythingMCP, a visual Model Context Protocol gateway with automated knowledge graph generation and granular access controls. Engineers can import OpenAPI specifications, Postman collections, SOAP WSDL files, or raw database credentials to generate standardized Model Context Protocol tools in minutes without writing custom code. The built-in knowledge graph automatically maps entity relationships across disparate databases and software platforms, teaching agents how to correlate customer records in CRM tools with live order histories in enterprise resource planning software. System administrators can enforce fine-grained access policies by restricting tool execution permissions to specific roles and scoping database operations to read-only queries with strict row limits. An interactive web console provides real-time tool inspection, payload testing, request tracing, and comprehensive audit logs that capture every upstream invocation with full parameter visibility. Enterprise teams can integrate identity providers through OAuth2, SAML single sign-on, and SCIM automated user provisioning while protecting sensitive credentials using AES-256-GCM encryption at rest. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPLv3 licensed.
MetaMCP
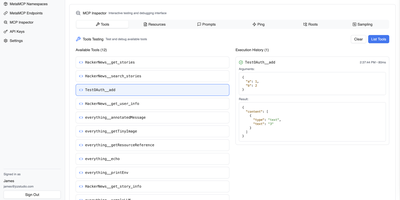
With 2,600+ GitHub stars, MetaMCP solves the MCP server sprawl problem by aggregating any number of upstream servers into a single authenticated endpoint that any MCP client connects to once. Group servers into namespaces — development tools in one, data sources in another — then publish each namespace as its own SSE, Streamable HTTP, or OpenAPI endpoint with API-key authentication in headers or query parameters, or full OAuth per the MCP Spec 2025-06-18 standard. The aggregation engine discovers tools, resources, and prompts from all active servers in parallel, prefixes tool names with server identifiers to prevent collisions, and applies configurable middleware including tool filtering to reduce context-window bloat and description overrides to improve LLM comprehension. The web management UI lets you configure MCP servers with stdio, SSE, or Streamable HTTP transports, toggle servers active or inactive per namespace, create and revoke API keys per endpoint, and inspect discovered tools with their schemas. Nested MetaMCP support enables hierarchical architectures where one MetaMCP instance consumes another, creating multi-level tool organization with automatic name resolution. Compatible with Claude Desktop, Claude Code, Cursor, Open WebUI, and any MCP-compatible client through a single connection URL. The Docker container packages the TypeScript backend with PostgreSQL for configuration persistence, exposing the management UI on port 12005 and MCP endpoints on configurable ports. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
GPT Load
GPT Load has become the go-to self-hosted AI gateway for teams managing multiple LLM provider credentials behind a single URL. The Go-built proxy transparently preserves native API formats for OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, and Google Gemini — applications swap one base URL and keep their existing SDK integration untouched. Twenty built-in channels cover official APIs (OpenAI, Anthropic, Gemini, xAI), cloud platforms (Azure OpenAI, AWS Bedrock, Google Vertex AI), model services (DeepSeek, Moonshot AI, SiliconFlow, Zhipu AI, Alibaba Cloud, Volcengine, OpenRouter, Groq), and subscription accounts (Codex, Claude, Antigravity, Grok) using the same credential management, scheduling, and health system. The intelligent key pool rotates among valid credentials using atomic counters for fair high-concurrency distribution, automatically blacklists failing keys after configurable thresholds, and recovers them via scheduled health checks — all transparent to clients. Weighted load balancing distributes traffic across multiple upstream endpoints while per-credential proxies route individual keys through different egress paths. The Vue 3 management dashboard provides real-time statistics, group configuration, key testing, request logs with full debugging context, per-model cost estimates, and route inspection. Docker deployment exposes the management interface and proxy on port 3001 with SQLite by default, MySQL or PostgreSQL optional, and Redis for distributed leader-follower cluster scaling. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OmniRoute
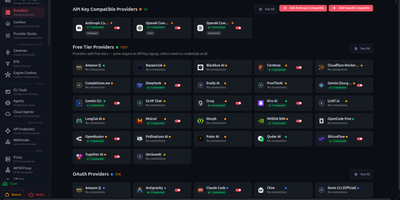
OmniRoute is an AI gateway, aggregating 338 LLM providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Kimi, MiniMax, and GLM into a single OpenAI-compatible endpoint at localhost:20128. The gateway catalogs over 1,200 models across 90 free-tier providers and 40 free-forever providers, automatically rotating through tier-1, tier-2, and tier-3 fallback chains when any provider exhausts its quota or returns errors. RTK plus Caveman stacked token compression reduces eligible context by 15 to 95 percent before forwarding requests, cutting API costs dramatically without degrading output quality. OmniRoute exposes its full routing engine through a built-in MCP server with 104 tools across 31 scopes over stdio, HTTP, and SSE transports, plus an A2A protocol server with six autonomous agent skills and JSON-RPC 2.0 streaming. The gateway integrates directly with Claude Code, Cursor, GitHub Copilot, Codex CLI, OpenCode, and Cline through standard base-URL configuration. Seventeen routing strategies include latency-optimized, cost-minimized, and auto-scoring modes that evaluate candidates on success rate, context fit, model fitness, quota state, and circuit-breaker health. The Next.js dashboard provides real-time provider status, usage analytics, combo chain configuration, and model catalog browsing via a responsive PWA. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Bifrost
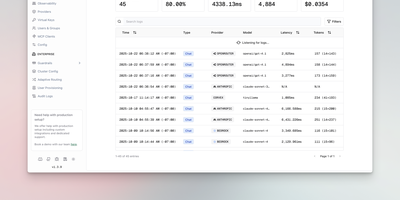
Bifrost is an open-source AI gateway that unifies 23+ LLM providers into a single OpenAI-compatible endpoint with automatic failover, semantic caching, and built-in cost governance, so one provider going down never takes your production AI application with it. Point your existing OpenAI or Anthropic SDK at Bifrost's local endpoint and gain access to OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure, Groq, Mistral, and Ollama without changing application code. Define fallback chains that automatically switch providers when one returns errors or exceeds latency thresholds, keeping response times stable during outages. The built-in web dashboard at port 8080 lets you configure providers, create virtual API keys, monitor live request traffic, and review analytics without editing configuration files. Semantic caching combines exact hash matching with vector similarity search via Weaviate, serving cached responses for identical or paraphrased prompts in sub-millisecond time to cut costs on repetitive workloads. The MCP gateway connects AI agents to external tools like filesystems, databases, and web APIs, exposing them to clients such as Claude Desktop and Cursor with per-key allow-lists. Four-tier budget hierarchy at customer, team, virtual key, and provider levels enforces spend caps, rate limits, and model restrictions across your organization. Extend functionality through custom Go plugins for analytics, monitoring, or security middleware. Native Prometheus metrics and OpenTelemetry distributed tracing give operations teams full production observability. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
FreeLLMAPI
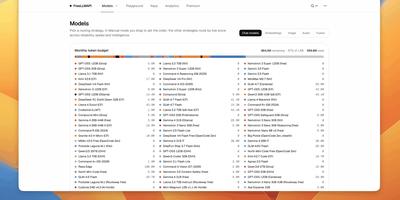
FreeLLMAPI collapses the chaos of 29 free LLM providers — Google AI, Cerebras, Groq, Mistral, OpenRouter, GitHub Models, Cohere, Cloudflare Workers AI, NVIDIA NIM, HuggingFace, SiliconFlow, Reka, Z.ai, and more — into a single /v1 endpoint that speaks both OpenAI and Anthropic protocols. The smart router selects the best available model for each request, automatically fails over to the next provider when rate limits hit, and tracks per-key token consumption so you never exceed a free-tier cap. Keys are stored with AES-256-GCM encryption and clients authenticate using a single unified bearer token, never exposing upstream provider credentials to downstream applications. The catalog tracks 251 model families across 358 provider/model endpoints with approximately 4 billion tokens per month of aggregate free-tier capacity, auto-refreshing from a signed manifest at freellmapi.co twice daily without requiring git pulls. Beyond chat completions, the proxy handles embedding, image generation, and audio/TTS endpoints, plus structured outputs with JSON schema forwarding, JSON healing, and format-ignore failover. An integrated MCP server at /mcp provides gateway introspection for coding agents, while the self-hosted OpenAPI reference at /v1/docs documents every route. Compatible with OpenAI SDKs, LangChain, LlamaIndex, Continue, Claude Code, and Hermes — just change base_url. Deploy via Docker, npm, or build from source. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Apache APISIX
With 17,000 GitHub stars, 460+ contributors, and deployments across telecommunications, automotive, and financial services running on over 10,000 CPU cores at the largest known installations, Apache APISIX delivers a fully dynamic API gateway achieving 140,000 QPS on eight cores with sub-millisecond latency through NGINX's event-driven architecture and LuaJIT-compiled plugin execution. The 100+ open-source plugins cover authentication (JWT, OAuth 2.0, OIDC, Keycloak, LDAP), observability (Prometheus, Datadog, SkyWalking, OpenTelemetry), traffic management (rate limiting, circuit breaking, canary releases, traffic splitting), and security (CORS, IP restriction, CSRF protection) — all hot-reloadable without process restarts via etcd-based real-time configuration synchronization. Multi-protocol support handles HTTP, gRPC, MQTT, TCP, UDP, and WebSocket traffic for both north-south API access and east-west service mesh communication. AI gateway capabilities proxy requests to 20+ LLM providers with semantic caching, token-aware rate limiting, provider failover routing, and content moderation. Custom plugins extend the gateway in Lua, Go, Java, Python, or WebAssembly. Radixtree route matching handles 100,000+ routes without performance degradation. Functions as a Kubernetes ingress controller with native service discovery for Consul, Nacos, and Eureka. Deploy via Docker or Helm charts with horizontal scaling through etcd cluster coordination. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Inference Gateway
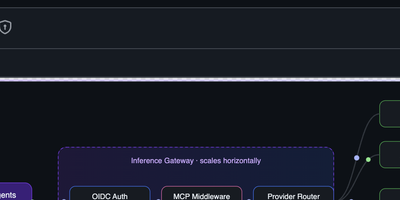
Inference Gateway puts a single OpenAI-compatible API endpoint in front of OpenAI, Anthropic, Groq, Cohere, Ollama, DeepSeek, Google, Mistral, MiniMax, Moonshot, Nvidia, and llama.cpp, so your application code never changes when you switch models or providers. The Go binary starts on port 8080 and normalizes authentication, streaming protocols, and response formats across all backends transparently. Native Model Context Protocol support auto-discovers tools from connected MCP servers and injects them into LLM requests without client-side management, enabling server-side tool execution across any provider that supports function calling. Agent-to-Agent protocol integration allows distributed agent communication through a declarative Agent Definition Language that generates production-ready Go or Rust servers from a single YAML manifest. The dedicated Kubernetes Operator manages Gateway, Agent, MCP, and Orchestrator custom resources with automatic HPA scaling, OIDC authentication, and service discovery that rebuilds MCP configurations when the discovered server set changes. Prometheus metrics and OpenTelemetry tracing provide full request-level observability across the entire inference pipeline. Middleware controls enable per-request provider selection, model routing, and fallback strategies. Official SDKs in Go, Python, TypeScript, and Rust provide typed client interfaces with streaming support. Docker Compose deployment requires only environment variables for API keys. A CNCF Sandbox applicant. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Kong
With over 43,000 GitHub stars and adoption by companies including Nasdaq, Samsung, and Expedia, Kong Gateway is the world's most deployed open-source API gateway, processing billions of API requests daily across hybrid-cloud and multi-cloud architectures. Built on the battle-tested NGINX engine with OpenResty's LuaJIT runtime, Kong delivers sub-millisecond proxy latency while supporting REST, gRPC, GraphQL, WebSocket, SOAP, and Kafka protocols. The plugin architecture includes authentication via JWT, Basic Auth, HMAC, key authentication, OAuth 2.0, and LDAP, alongside rate limiting with configurable windows per consumer, IP address, or API key. The AI Proxy plugin provides a universal LLM API that routes across OpenAI, Anthropic, Google Gemini, AWS Bedrock, Azure AI, Databricks, Mistral, and Hugging Face through a single standardized interface, while MCP proxy capabilities convert REST APIs into MCP tools and provide traffic governance for AI agents. Kong supports declarative configuration via YAML for GitOps workflows, a RESTful Admin API for dynamic configuration, and decK CLI for version-controlled infrastructure-as-code management. Upstream health checking with active and passive probes enables automatic failover, and the ring balancer distributes traffic across upstream targets with consistent hashing, round-robin, or least-connections algorithms. The Kong Plugin Hub hosts over 100 community and official plugins covering logging, monitoring, transformation, security, and traffic control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Convoy
Convoy is an enterprise-grade webhooks gateway that manages both incoming and outgoing webhook traffic to guarantee reliable event delivery without exposing internal microservices to the public internet. Organizations deploy the platform at the edge to ingest events from message brokers such as Apache Kafka, RabbitMQ, and Google Cloud PubSub, or receive HTTP webhooks from third-party services directly. The gateway enforces delivery policies through configurable rate limiting per endpoint, circuit breaking during downstream outages, and automated retries using constant or exponential backoff with jitter. Developers can generate customer-facing webhook portals embedded via iframes, allowing end users to inspect delivery attempts, verify HMAC-SHA256 signatures, and manually replay failed events. Comprehensive security controls include static egress IP proxying to prevent server-side request forgery, automated rolling secret keys, and instant alerting via Slack or email when endpoints fail consecutively. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Elastic License 2.0 licensed.
KrakenD
KrakenD processes over 18,000 requests per second on a single instance while consuming under 50MB of RAM at 1,000 concurrent connections, operating as a stateless API gateway that requires no database whatsoever. The Community Edition has earned over 2,600 GitHub stars by outperforming database-dependent alternatives like Kong and Tyk in independent benchmarks. Written entirely in Go, it uses declarative JSON or YAML configuration files that integrate directly into GitOps workflows for version-controlled infrastructure management. The gateway aggregates responses from multiple backend services into a single API call, transforms request and response payloads with field filtering, grouping, and mapping, and applies zero-trust security policies including JWT validation, OAuth 2.0, CORS, HSTS, clickjacking protection, and XSS prevention. Traffic management features include multi-layer rate limiting at both the router and proxy levels, circuit breakers for backend fault isolation, spike arrest policies, and concurrent call support that requests the same data from multiple backends in parallel for improved response times. Telemetry integrates with OpenTelemetry, Prometheus, Grafana dashboards, Datadog, Zipkin, and Jaeger for distributed tracing and metrics collection. The gateway extends through Go plugins, Lua scripting, Martian modifiers, and Google CEL expressions for custom request processing logic. AI workload routing supports OpenAI, Anthropic, Gemini, and other model endpoints with built-in fallback, retries, and load balancing. Deploy via Docker with the devopsfaith/krakend image as a single binary. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.