Odysseus
Agents with tool use, deep research, a document editor, an IMAP/SMTP email client with AI triage, notes, tasks, and a CalDAV-synced calendar - Odysseus bundles all of it into one open-source, self-hosted AI workspace. It runs local models through Ollama, vLLM, or llama.cpp and cloud APIs like OpenAI and OpenRouter, with a hardware-aware Cookbook that scans your machine and recommends quantized models that fit. Persistent memory uses ChromaDB with hybrid vector-plus-keyword retrieval, web search runs through a bundled SearXNG instance, and agents can use MCP servers, files, and shell access with safety controls, plus custom skills and scheduled agent tasks. A blind Compare mode runs side-by-side model duels with identities hidden and accumulates Elo-style ratings from your votes, so model selection is based on your actual workloads rather than leaderboard claims. Deep research mode - adapted from the Tongyi DeepResearch approach - reads sources through SearXNG and produces cited reports, while the email client tags, summarizes, sets reminders, and drafts replies locally rather than through a third-party mail AI. The writing-first document editor adds AI edits, Markdown and HTML support, and version history. The stack is Python 3.11 with FastAPI, SQLite for state, and a vanilla JS frontend, licensed AGPL-3.0 with zero telemetry. Because agents can read email and execute commands, keep authentication enabled and never expose it as a public unauthenticated service.
LibreChat
Every major model provider behind one ChatGPT-style interface: LibreChat spans OpenAI, Anthropic, Google, Azure, AWS Bedrock, Vertex AI, Groq, Mistral, OpenRouter, DeepSeek, and any OpenAI-compatible endpoint including local Ollama. You can switch models mid-conversation and compare providers without changing tools. Its Agents framework builds no-code custom assistants with tool access via Model Context Protocol servers, file search over uploaded documents through an optional pgvector-backed RAG service, and a sandboxed Code Interpreter that executes Python, JavaScript, Go, C++, Java, PHP, and Rust. Artifacts render React components, HTML, and Mermaid diagrams directly in chat, and image generation works through DALL-E and other configured providers. Multi-user support is enterprise-grade, with OAuth, SAML, LDAP, and two-factor authentication, per-user conversation history in MongoDB, and Meilisearch-powered search across all messages and files, plus reusable presets, forkable threads, and persistent memory across conversations. The economics favor teams: instead of a ChatGPT Plus seat per person, everyone shares one instance billed per API token, with access to every provider rather than one - and providers see individual API calls, not your accumulated organizational knowledge. Deployment is Docker Compose; API keys and endpoints are configured through .env and librechat.yaml.
AnythingLLM
Chat with your own documents: AnythingLLM, from Mintplex Labs, wraps retrieval-augmented generation (RAG) in an open-source application anyone can run. You organize content into workspaces, each an isolated namespace with its own documents, vector embeddings, chat history, and settings, so one instance can hold several separate knowledge bases. Upload PDFs, DOCX, TXT, and other formats, or scrape web pages; the built-in collector parses and chunks them into a vector database (LanceDB by default, with Pinecone, Chroma, Qdrant, and others supported). Answers cite their source documents. It works with both cloud LLMs (OpenAI, Anthropic, Gemini) and local ones via Ollama or LM Studio, and the embedding model is separately configurable. Beyond RAG chat, it includes AI agents that can browse the web and run tools, an embeddable chat widget for your website, a developer API, and multi-user mode with admin, manager, and default roles plus per-workspace access control. Context assembly is smarter than naive RAG: pinned documents, attached files, vector search hits, and recent chat history are combined under a token budget so the model's context window is filled efficiently, and each workspace supports multiple independent conversation threads against the same knowledge base. Because the embedding model, vector store, and chat LLM are all independently swappable, you can move between providers without re-ingesting a single document. The stack is Node.js with a React frontend, MIT-licensed.
Hermes Agent
OpenRouter's most-used application by token volume — over 17 trillion tokens processed — Hermes Agent is an open-source autonomous agent built by Nous Research that lives on your server and gets more capable every day. Define a goal in natural language and Hermes plans sub-tasks, executes them through tool integrations, observes results, handles errors, and refines until the job is done or it genuinely needs your input. Persistent memory with full-text search and LLM summarization lets it recall context across sessions, and an agent-created skills system self-improves after complex tasks. A messaging gateway connects Telegram, Discord, Slack, WhatsApp, Signal, and 16 more platforms with cross-channel conversation continuity. A built-in cron scheduler runs daily reports, nightly backups, and weekly audits unattended. Subagent spawning parallelizes workstreams, and six terminal backends — local, Docker, SSH, Singularity, Modal, and Daytona — fit any infrastructure. Works with any LLM provider: Nous Portal, OpenRouter for 400+ models from 70+ providers, OpenAI, Anthropic, or your own endpoint. The API key you supply powers all LLM calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Teable
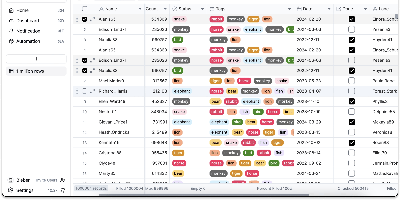
An Airtable-style spreadsheet interface directly on PostgreSQL: Teable is an open-source no-code database where every table is a real Postgres table. Unlike tools that store records in a metadata abstraction layer, every Teable table is a real Postgres table with standard column types, so filtering, sorting, and grouping run at database speed, million-row tables answer complex filters in roughly 200 milliseconds without index tuning, and any PostgreSQL-compatible tool - psql, BI dashboards, ETL pipelines - can query the same data directly. The interface offers Grid, Kanban, Gallery, Calendar, and Form views as non-destructive overlays with their own filters and hidden fields, plus 20+ field types, formulas, comments, attachments, batch editing, undo/redo, and edit history. Collaboration is real-time with live cursors and instant sync across views, backed by Redis, and a REST API is auto-generated per table, largely compatible with Airtable API clients - alongside native SQL access for BI tools, analytics pipelines, and your own applications to JOIN and query directly, with no exports, API rate limits, or sync jobs. Global search spans all records, chart plugins handle quick visualization, and CSV and Excel import/export cover migrations. Where Airtable caps paid plans at 100K-500K rows and charges roughly $20 per user per month, a self-hosted Teable instance has neither limit: the Postgres database itself is the export if you ever leave. Built in TypeScript with NestJS, deployed via Docker with PostgreSQL and Redis, and licensed AGPL-3.0.
OpenClaw VPS
A personal AI assistant that remembers what it learns and reaches you wherever you are — OpenClaw is an open-source agent gateway built by the OpenClaw Foundation with 247,000+ GitHub stars. It connects to 200+ LLM models through providers like Anthropic, OpenRouter, and OpenAI, and meets you on 21+ messaging channels: Telegram, Slack, Discord, WhatsApp, Signal, iMessage, Matrix, and more. Persistent memory with full-text search lets the agent recall context across sessions, and a self-improving skills system means it gets more capable the longer it runs. Voice wake words and talk mode enable hands-free interaction on macOS, iOS, and Android. A live canvas provides an agent-driven visual workspace. Built-in browser automation, cron scheduling for unattended tasks, and subagent spawning for parallel workstreams round out the toolset. The gateway architecture keeps all sessions, credentials, and conversation history on your own server — nothing transits a third-party cloud unless you choose to connect one. The API key you provide for your chosen LLM provider powers the underlying calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Twenty
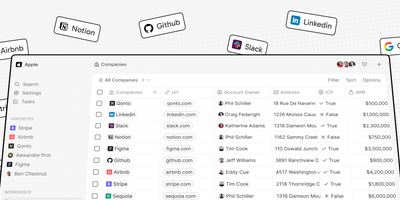
Salesforce's core workflow, open-source and on your own server: Twenty is a modern CRM built as exactly that alternative. It ships the standard CRM objects out of the box: people, companies, opportunities, notes, and tasks, displayed in table and kanban views with drag-and-drop and real-time updates. Its defining technical feature is a metadata-driven data model: you define custom objects and fields in the UI, and the backend regenerates its GraphQL schema at runtime, so a new object gets working queries, mutations, filters, and sorting within seconds, with no migrations to run - adapting the CRM to your sales process never requires code changes. A REST API is auto-generated from the same schema, GraphQL subscriptions push real-time updates, and webhooks fire on record changes for external integration. A visual workflow builder automates actions like notifications and field updates, TypeScript-based apps extend the platform with custom logic and frontend components, and email and calendar sync pulls Gmail messages and meetings onto contact timelines so communication history sits next to the record. The stack is NestJS with TypeORM, PostgreSQL, Redis, and BullMQ on the backend, React with Jotai on the frontend. Self-hosting on RepoCloud means unlimited users with no per-seat licensing - the pricing model that penalizes growing teams on commercial CRMs - and your pipeline, contacts, and deal history live in your own PostgreSQL database rather than a vendor's.
Mattermost
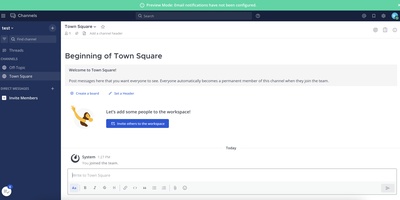
Teams that cannot send messages through someone else's cloud run Mattermost - the open-core, self-hosted alternative to Slack. It provides public and private channels, threaded discussions, unlimited search history, file sharing with previews, one-to-one audio calls, and screen sharing, with desktop clients for Windows, macOS, and Linux plus iOS and Android apps. Messages support full Markdown, which suits engineering conversations with code blocks and logs. Playbooks turn repeatable processes such as incident response and release management into checklist-driven workflows with automated triggers and retrospectives. Integration is a core strength: prebuilt connectors for GitHub, GitLab, Jira, ServiceNow, and PagerDuty, plus webhooks, slash commands, bots, a REST API, and a plugin marketplace with 700+ entries - together making it a working surface for ChatOps rather than just a chat room. Playbooks add keyword and event triggers, task assignment, status broadcasting, and post-incident retrospectives, so operational knowledge is not trapped in individuals' heads. The server is a single Go binary backed by PostgreSQL, with React clients, released monthly under MIT license and deployable fully air-gapped - which is why governments and defense organizations run it inside closed networks, and why the same control applies to any team with confidentiality requirements. The compiled Team Edition is free for unlimited users with no message history cutoff, so costs stay flat as the team grows.
EasyAppointments
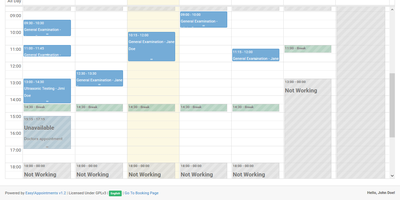
Service businesses get a booking page without per-booking commissions or monthly SaaS fees from Easy!Appointments, the self-hosted appointment scheduler. Customers pick a service, provider, and open time slot from a clean web form; the system enforces working plans, breaks, and booking rules you define per provider, then confirms by email to both sides. The structure fits real service organizations: multiple providers with individual schedules, multiple service types with their own durations and prices, and admin/secretary roles for front-desk management. Two-way Google Calendar synchronization keeps each provider's external calendar authoritative - book in Easy!Appointments and it appears in Google Calendar, block time in Google and the slot disappears from the booking form. Version 1.6 adds SMS notifications and payment support, and a REST API opens the scheduling data to custom integrations. Built on PHP (CodeIgniter) with MySQL, it installs in a single folder and can share a database with your existing site; a WordPress plugin embeds the booking form directly in pages or posts. The interface ships in dozens of languages with time-zone handling throughout. GPL-3.0 licensed and free for commercial use - a helpdesk, clinic, salon, or consultancy runs its whole booking workflow on its own server.
Tymeslot
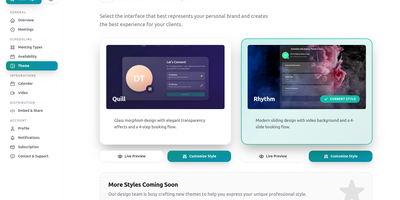
Built on Elixir's fault-tolerant OTP runtime, Tymeslot delivers the complete scheduling toolkit that Calendly charges for and Cal.com relicensed away from open source in 2026. Share one booking link and let clients pick available slots — your calendar stays synchronized and double-bookings disappear automatically through real-time availability checking against Google Calendar, Microsoft Outlook, and any CalDAV server including Nextcloud. Meeting types support configurable durations, buffer times, and availability windows that clients can book without email back-and-forth. Phoenix LiveView powers the real-time UI with WebSocket connections that update instantly as bookings arrive, without client-side JavaScript framework overhead. The platform attaches Zoom video rooms to confirmed bookings through your own Marketplace app credentials, sends confirmation and reminder emails via SMTP, Postmark, SendGrid, Mailgun, or AhaSend, and supports custom booking page themes with embed options for integration into existing websites. Circuit breakers, connection pooling, and graceful degradation maintain availability during provider outages. Authentication supports local accounts, GitHub OAuth, and reCAPTCHA protection on public booking forms. Self-hosting deploys as a single container with PostgreSQL embedded — no separate database container required. Two named volumes persist uploads and database state, while the same image powers the managed cloud at tymeslot.app so self-hosted users get identical features without a crippled community edition. Deploy via Docker, Cloudron with automatic updates, or Railway from a community template. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Chatwoot
Unleash the power of Chatwoot, the open-source superhero in the world of customer experience! This platform is perfect for businesses craving to connect with their customers across a multitude of channels without breaking the bank. Wave goodbye to the high-and-mighty likes of Intercom, Zendesk, and Salesforce Service Cloud, and say hello to a wallet-friendly powerhouse. Chatwoot turns your agents into customer service ninjas, armed with the latest in workload management, performance tracking reports that refresh themselves (because who has time for that?), and automations that work smarter, not harder. Zap through conversations with lightning-fast responses and manage your social media and email interactions in a single bound. Plus, with Chatwoot, you get to be the Sherlock of customer satisfaction, deducing your CSAT scores on autopilot. All this hosted on RepoCloud, where the cost is as tiny as the effort you'll need to switch over. Get ready to engage, enlighten, and entertain your customers with Chatwoot!
Vexa
Vexa is the only Apache 2.0 meeting bot API that self-hosts the complete transcription pipeline, from bot dispatch to Whisper speech-to-text to knowledge agents, with zero audio leaving your infrastructure. A single POST /bots request sends a transcription bot into any Google Meet, Microsoft Teams, or Zoom call, where it captures audio, runs speaker-attributed transcription through faster-whisper or any OpenAI-compatible endpoint, and streams results to your application via real-time WebSocket with sub-second latency. The built-in agent framework watches live transcripts and your accumulated workspace context, answering mid-call questions grounded in your own meeting history and wiki. An MCP server connects Vexa to Claude, Cursor, and other compatible AI tools, turning every captured meeting into queryable context for external agents. The Terminal, a bundled Next.js web workbench, lets you send bots, watch live transcripts, manage users and API tokens, and chat with your meeting archive from a browser. Docker Compose brings the full stack up on one Linux host in five minutes; the Helm chart scales to thousands of users on Kubernetes with a Pod-per-bot architecture and built-in RBAC. Recordings persist in MinIO or any S3-compatible store, transcripts in Postgres, with Redis handling queues and scheduling. Deploy on RepoCloud for a dedicated VPS with full root SSH access and browser console. Apache 2.0 licensed.
Memos
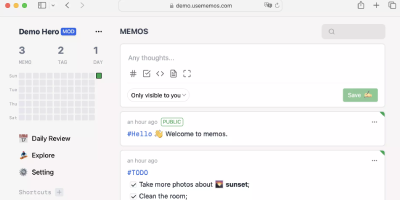
Open the page, write a Markdown note, move on - Memos is a lightweight, self-hosted service built for quick capture. Instead of folders, notebooks, and titles, it presents a timeline: open the page, write a Markdown note, and move on. Notes support headings, code blocks with syntax highlighting, task lists, tables, and file attachments, with tags auto-extracted from #hashtags in the text. Each memo carries a visibility level, private, protected (logged-in users), or public, so one instance works as a personal log, a small team wiki, or a lightweight microblog. The backend is a single Go binary with a React frontend, around 50 MB of memory at runtime and a ~20 MB Docker image, so it fits comfortably on the smallest instance size with near-zero maintenance. SQLite is the default store, with MySQL and PostgreSQL supported for multi-user deployments needing more concurrency, and full REST and gRPC APIs - Connect RPC for browsers, gRPC-Gateway for external tools - make capture scriptable from CLIs, bots, and automation platforms. Fast full-text search spans all memos, pinned notes keep references handy, and a masonry view suits visual browsing. MIT-licensed with zero telemetry; content is stored as plain Markdown in a database you control, so notes remain readable, exportable, and free of proprietary formats.
Morphic
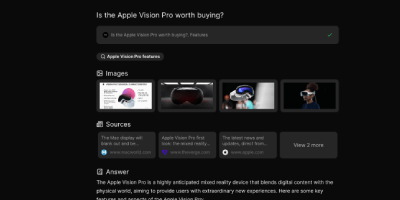
Perplexity's answer-engine experience, self-hostable and open-source: Morphic searches the web and writes cited answers. Instead of returning a list of links, it searches the web, reads the sources, and generates a complete answer with inline numbered citations. The generative UI streams rich components, source cards with thumbnails, image grids, syntax-highlighted code, and LaTeX math, rather than plain markdown. Quick mode answers fast; Adaptive mode runs deeper multi-step research. Search backends are pluggable: the Docker Compose bundle ships with a private SearXNG instance so no search API key is required, and Tavily, Brave, and Exa are supported alternatives. LLM providers include OpenAI, Anthropic, Google, Ollama, and any OpenAI-compatible endpoint, with per-mode model mapping - fast, cheap models for quick searches, stronger models for adaptive research, tuning the cost-quality trade-off per query type. An inspector panel exposes tool execution during multi-step research, and AI-suggested follow-up questions keep an investigation moving. Chat history persists in PostgreSQL, results are shareable by URL, file uploads feed context into queries, and optional Supabase authentication adds multi-user or guest access. Because the default search path is your private SearXNG instance, research topics never hit a commercial search API - and with local Ollama models the marginal cost of a query approaches zero. Built with Next.js, TypeScript, and the Vercel AI SDK under Apache 2.0.
Macro
Macro merges email, team chat, collaborative documents, task management, CRM, and video calls into one keyboard-driven application where AI agents operate across the entire workspace with shared team memory, replacing the Slack plus Notion plus Linear plus Superhuman plus HubSpot stack with a single deployment. The email module provides a multi-account unified inbox with keyboard shortcuts, shared team inboxes, and Gmail integration. Team messaging offers channels and direct messages designed for technical discussions with threaded conversations. The task system draws from Linear with board and list views tightly integrated with channels, email threads, and AI agents. Real-time collaborative documents use CRDT synchronization via Loro for conflict-free editing with Markdown-native formatting and @mention linking. A 2D canvas board embeds @links to tasks, files, and emails for visual project planning. AI agents access unified team-level memory spanning all workspace modules, taking autonomous actions across email, chat, tasks, and documents through MCP-compatible tool interfaces. Video calls include recording, transcription, and automatic logging to team memory. The CRM module tracks customers and contacts with custom properties, email synchronization, and data enrichment. Eighty-plus Rust microservices on the Axum framework handle backend operations while a SolidJS static SPA delivers the frontend with instant search and real-time collaboration. Docker Compose deployment provisions the complete service stack with PostgreSQL, Redis, OpenSearch, and FusionAuth authentication. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
QwenPaw
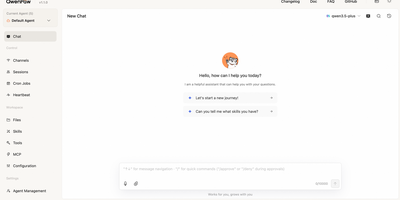
Designed as a unified personal AI workstation, QwenPaw operates as an autonomous digital copilot that coordinates scheduled automations, interactive coding sessions, and multi-channel team communication across everyday messaging apps. Users can dispatch long-running research tasks, process office documents including PDF, Excel, and Word files, and execute browser-based data collection without manual intervention. The built-in web console and terminal interface provide full visibility into agent reasoning, allowing operators to inspect intermediate thinking steps, review proposed file edits, and approve sensitive tool calls. Through direct connectors for Discord, Telegram, DingTalk, Lark, and WeChat, teams can trigger specialized skills or query shared workspaces directly from their existing group channels. A self-evolving personal memory system continuously indexes chat interactions and local resources into editable Markdown files, ensuring knowledge persists across restarts and task delegations. Built-in guardrails including a sandboxed execution runtime, tool access policies, and automated skill scanners protect underlying host files from unauthorized modifications during autonomous scripting runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Rocket.Chat
Blast off into productivity space with Rocket.Chat SIX, the ultimate team collaboration cosmos! Imagine a place where your messages, tasks, and projects all live in harmony, orbiting around your team's efficiency like a well-organized galaxy. This isn't just any old chat platform; it's a customizable universe where you're the master of your data domain, with the power to tweak, integrate, and innovate to your heart's content. Ready to provide stellar customer service? Engage with your clients in a way that's so contextually on-point, they'll feel like you're mind-reading across the cosmos. Plus, with a chat engine that's like a gravitational pull for user engagement, your app or website will become the center of your users' universe. And for the security-conscious space cadets, fear not! Rocket.Chat SIX is locked down tighter than a spaceship hatch, with end-to-end encryption and a buffet of deployment options to satisfy your security appetite. All this, hosted on RepoCloud, where the cost is as lightweight as zero-gravity. So why settle for a terrestrial tool when you can have a celestial experience? Rocket.Chat SIX: because your team deserves to collaborate in a universe that's light-years ahead!
PilotDeck
PilotDeck introduces a WorkSpace-first architecture where each project receives its own isolated file system, memory store, and skill set, preventing context bleed between parallel tasks. White-box memory makes generation, extraction, storage, and retrieval fully visible, letting users audit, edit, pin, and rollback individual entries when the agent misremembers, while Dream Mode consolidates memory fragments during idle windows. Smart Routing auto-detects task difficulty and sends complex calls to flagship models like Claude Sonnet or GPT-4o while routing simple requests to lighter models, achieving claimed 70% cost savings through on-device and cloud co-orchestration with TokenSaver tiering and sticky session binding. Always-on background execution keeps agents running after the user closes the browser, with Discovery and Cron-based scheduling for recurring workflows. The platform natively supports the Model Context Protocol for first-class MCP server integration, community skills via ClawHub on npm, lifecycle hooks intercepting PreToolUse and UserPromptSubmit events, and custom memory store providers. Multi-provider fallback automatically switches to backup providers on timeout or rate-limit errors. The WebSocket and HTTP gateway serves web, CLI, desktop, and Feishu IM channels from a single configuration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.