ChainForge
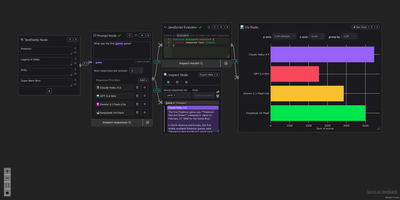
Comparing prompts and models by eye stops working fast, so ChainForge lays every experiment out on one visual canvas. Drop a table of inputs into a Prompt Node, add a handful of models, and the app sends every combination of template variable and model, then collects the answers in an Inspect Node that groups responses by any variable. Evaluator nodes score outputs with a few lines of code, and visualization nodes plot pass rates and numeric scores as histograms or box plots. Chat Turn nodes test follow-up questions, to see if a model caves when a user pushes back. Sparkle buttons draft synthetic table rows, test questions, and starter evaluator code with a model of your choice, and an LLM scorer can judge answers against a rubric you write. Example Flows open ready-made experiments, from a no-key starter with tiny in-browser models to prompt template comparisons, sycophancy checks, gender bias audits, red-teaming runs, and 188 flows converted from OpenAI Evals. Documents, Chunking, Retrieval, and Rerank nodes cover retrieval experiments. Finished flows export as cforge files, and results export to spreadsheets or JSON for the rest of the team. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Apache NiFi
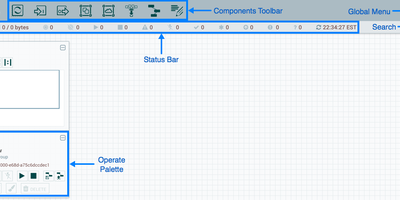
Deployed at thousands of enterprises across financial services, healthcare, government, and telecommunications, Apache NiFi is the industry-standard platform for building automated data pipelines through a visual drag-and-drop browser interface that requires zero coding for common integration patterns. The flow-based programming model connects over 300 built-in processors covering relational databases via ExecuteSQL and PutDatabaseRecord, Apache Kafka with PublishKafka and ConsumeKafka, HTTP endpoints through InvokeHTTP and ListenHTTP, cloud storage for AWS S3, Azure Blob, and Google Cloud Storage, SFTP/FTP file transfers, and JSON, XML, CSV, and Avro transformations. Data provenance tracking logs every routing decision, transformation, and delivery for every FlowFile, creating a searchable lineage graph from source to destination with full content replay capability for auditing and debugging. Guaranteed delivery uses configurable backpressure thresholds, prioritized queuing with latency or throughput optimization, and automatic retry with exponential backoff, ensuring no data loss even during downstream outages. The zero-leader clustering architecture distributes processing across nodes with automatic load balancing, while site-to-site protocol enables secure data transfer between NiFi instances across network boundaries. Security includes OpenID Connect and SAML 2.0 single sign-on, role-based access control with fine-grained policies per component, and TLS encryption for all communication. Custom processors can be written in Java and packaged as NAR bundles, or implemented directly in Python through the native scripting framework. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.