GPUWorks
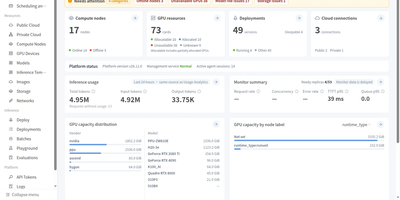
When your GPUs are spread across a rack in the office, rented cloud instances, and a Mac on a desk, GPUWorks pools them into one cluster that serves open models behind a single OpenAI-compatible endpoint. Pick a model from the built-in catalog of launch specs for vLLM and SGLang across NVIDIA, AMD, Huawei Ascend, T-Head PPU, Hygon, and Apple Silicon hardware, and the deploy page estimates the memory needed for weights, KV cache, and engine overhead, shows which GPUs the scheduler chose, and explains why it rejected the others. Several models can share one card through memory quotas or take turns with sleep and wake, while replicas, multi-node parallelism, and prefill and decode disaggregation scale a deployment out. The gateway handles chat, embeddings, rerank, audio, image, and realtime requests with API keys, per-key token usage, and failover routing. A monitor center charts time to first token, throughput, concurrency, and KV cache hit rates, usage analytics break tokens down by key and model, and a built-in benchmark sweeps concurrency to find your latency limit. GPU health checks and an AI assistant help diagnose failing cards, and a Playground lets you try any deployment in the browser. Nodes connect outbound, so they need no open ports, and models can be imported offline for air-gapped sites. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Deploy