ArchiveBox
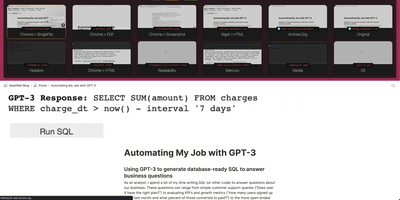
Backed by 27,700+ GitHub stars and actively developed with the v0.9.x architectural overhaul introducing an event-driven plugin ecosystem, ArchiveBox delivers the open-source self-hosted web archiving platform that preserves websites, bookmarks, social posts, media, source code, and research material in durable formats before link rot, platform shutdowns, and censorship erase them permanently. Feed it URLs one at a time or schedule automated imports from browser history, RSS feeds, Pocket, Pinboard, Instapaper, Wallabag, Shaarli, JSON, CSV, HTML bookmark exports, and browser extension captures. Each snapshot stores redundant copies as original HTML, rendered single-file HTML via SingleFile, full-page PDF, screenshot PNG, WARC archive, article text via Readability, favicons, HTTP headers, media files via yt-dlp, git repository clones, and structured metadata in SQLite. The Docker Compose deployment bundles Chrome, wget, curl, yt-dlp, SingleFile, and Readability parsers with automatic dependency management and isolation. Interact through the self-hosted web UI with search, tagging, and admin controls, the comprehensive CLI for batch operations, the REST API for programmatic access, or the Python API for custom integrations. The new abx-plugins system enables community extractors with per-plugin configuration, while the append-only-log architecture provides resumable crawls and audit trails. S3, B2, and Google Cloud storage backends sync archives to remote storage via rclone. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Grimoire
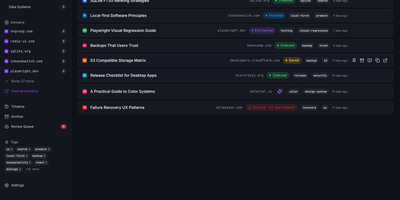
Grimoire captures, extracts, and indexes the content behind your bookmarks so you can search what pages actually say, not just their titles and URLs. The ingestion pipeline accepts links from the web UI, REST API, MCP server, browser bookmarklet, or bulk import, then fetches each page and extracts readable content using specialized parsers for GitHub repos, GitHub issues, StackOverflow threads, YouTube transcripts, PDFs, and standard web articles. Everything stores locally in SQLite with file-based content archives. Search operates in three modes: FTS5 keyword matching for exact terms, semantic embedding search for meaning-based retrieval using vector similarity, or a hybrid ranking mode combining both. Optional AI providers including OpenAI, Ollama, Anthropic, DeepSeek, and any OpenAI-compatible endpoint generate automatic tags, summaries, and embeddings without being required for core functionality. The interface built with React 18, Vite, TypeScript, Tailwind CSS, and Radix UI supports categories, nested tags, notes, archive and trash states, read-later flags, and multi-user isolated spaces. A single Bun-powered Hono process serves both the compiled frontend and the REST API on port 3210, requiring only one Docker container and a SQLite volume. Backup and restore export bookmarks, content, settings, and metadata as portable ZIP archives. Nearly 3,000 GitHub stars reflect growing adoption among developers and researchers. Running on a VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.