llama-swap
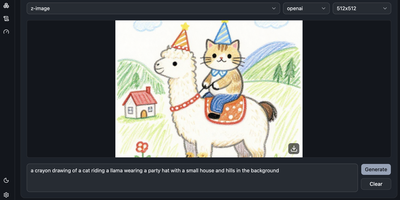
llama-swap puts one OpenAI-compatible and Anthropic-compatible endpoint in front of all your local models and loads whichever one each request names, unloading the one it replaces. Define models in a single YAML file, and chat, embedding, speech, transcription, and image requests reach the right backend automatically. The web UI includes a playground for chatting with any model, token metrics for every request, a request inspector that shows raw payloads and responses, buttons to load and unload models by hand, and a live log stream for the proxy and each upstream process. Profiles switch model routing at runtime, a swap matrix keeps selected models loaded together, and a time-to-live setting frees memory after idle periods. API keys restrict who can call the endpoints, and filters strip or force request parameters. Docker and Podman commands start and stop containers per model, and a Prometheus endpoint exposes system and GPU metrics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy