InfluxDB
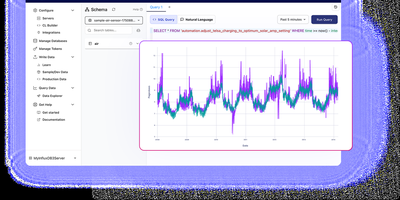
With over 31,600 GitHub stars and thousands of production deployments, InfluxDB 3 Core is the open-source time series database rebuilt in Rust on the FDAP stack — Apache Flight for high-throughput data transfer, DataFusion for vectorized SQL query execution, Arrow for columnar in-memory representation, and Parquet for compressed columnar storage. The engine delivers sub-10ms query response times on recent data and handles millions of writes per second through line protocol ingestion over HTTP, with unlimited tag cardinality eliminating the high-cardinality limitations that plagued earlier InfluxDB versions. The diskless architecture persists data as compressed Parquet files to S3-compatible object storage, Azure Blob, Google Cloud Storage, or local disk with configurable partitioning strategies, while the write-ahead log and in-memory buffer serve real-time queries against recent data before compaction. Native SQL support through DataFusion includes window functions, CTEs, subqueries, and joins, while InfluxQL maintains backward compatibility with existing InfluxDB 1.x and 2.x applications through the same query API. The embedded Python VM enables processing engine plugins and triggers that execute custom logic on write events, perform cross-database queries, and transform data in real time without external tooling. Flight SQL clients provide high-performance query access from Python, Go, Java, and Rust, and the HTTP API supports writes in line protocol format compatible with Telegraf's 300+ input plugins. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT/Apache 2.0 dual-licensed.
Apache Druid
When dashboards must answer in under a second over billions of streaming events, Apache Druid is the real-time analytics database built for the job. Point a supervisor at an Apache Kafka topic or Amazon Kinesis stream and events are queryable on arrival, late data included, with exactly-once guarantees. Batch loads run as SQL: INSERT and REPLACE statements ingest files, and EXTERN reads external sources. Schema auto-discovery adds new columns and types as data lands. Joins run at ingestion or at query time. A web console gathers the daily work in one place: a tabbed Query view with EXPLAIN PLAN and query history, a Connect external data wizard, and pages for datasources, segments, retention rules, supervisors, tasks, services, and lookups. Configurable tiers place hot and cold data on different hardware. Quality-of-service settings shield priority workloads from heavy ones. Clickstream analytics, ad campaign reporting, network telemetry, application performance tracking, and IoT metrics all fit. Applications connect over the HTTP SQL API or the Avatica JDBC driver, and native JSON queries remain available for advanced needs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Emoncms
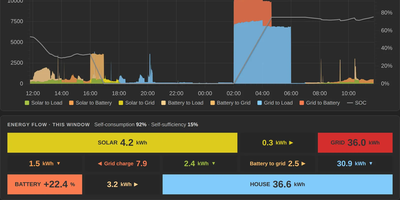
Energy meters, solar systems, heat pumps, and temperature sensors report to Emoncms, which logs every reading as a time series and turns it into graphs, dashboards, and ready-made apps. Readings arrive over an HTTP input API, MQTT topics beneath emon/, or AES-encrypted posts for devices without HTTPS, from scripts, Node-RED, Home Assistant, or emonHub. Input processing calibrates values, combines inputs, converts watts to cumulative kilowatt-hours, and logs the result to a feed. Device templates configure known hardware in one step, and schedules limit processes to set time windows. The graph viewer plots feeds on two axes, groups them into daily, weekly, monthly, or annual bars, and offers feed statistics and CSV export. Virtual feeds calculate values like heat pump COP on request and store nothing; post processing rebuilds feeds from recorded data. My Electric Flow charts live solar, battery, and grid power with an energy-flow breakdown and a Tariff explorer for Octopus Agile and other time-of-use tariffs. My Heatpump reports COP and SCOP. Other apps cover boilers, solar diversion, CO2 air change rates, and the UK grid fuel mix. The dashboard editor places dials, gauges, thermometers, charts, text, and images, and a dashboard can be made public. Sync uploads feeds to another server on a schedule and downloads them for recovery; the Backup module backs up and restores data. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
QuestDB
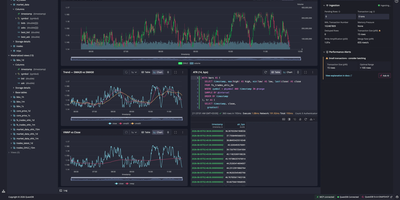
Powering trading floors at firms processing millions of market data events per second and trusted by organizations including Airbus, Yahoo, and Copenhagen Atomics, QuestDB has earned over 17,000 GitHub stars as the time-series database that refuses to make you choose between ingestion speed and query latency. The column-oriented, time-partitioned storage engine processes millions of rows per second on ingest through write-ahead logging with instant durability, while SIMD-accelerated parallel execution returns analytical queries over billions of rows in milliseconds. Time-series SQL extensions add ASOF JOIN for point-in-time lookups across tables with misaligned timestamps, SAMPLE BY for downsampling at arbitrary time intervals, LATEST ON for last-value queries, and WINDOW JOIN for sliding window aggregations — all through standard SQL syntax accessible via the PostgreSQL wire protocol, REST API, or the QuestDB Wire Protocol (QWP) that streams Apache Arrow at 220 million rows per second. Multi-tier storage automatically moves data from the WAL through native columnar format to Parquet files on S3-compatible object storage, keeping hot data fast and cold data portable without manual tiering. The built-in web console provides an interactive SQL editor with syntax highlighting, autocomplete, and charting for quick data exploration. Views, materialized views, and n-dimensional arrays support real-time analytics, while native Parquet export enables direct integration with Python, DuckDB, and AI/ML frameworks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
VictoriaMetrics
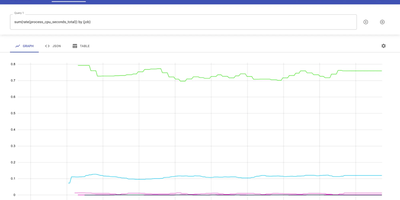
Trusted by thousands of organizations processing billions of time series data points and backed by 17,000+ GitHub stars, VictoriaMetrics delivers a monitoring and time series database that outperforms Prometheus by 16x on query speed while consuming 2.5x less disk space through its optimized compression and storage engine. The architecture supports both single-node deployments handling 10M+ active time series and a horizontally scalable cluster version with vminsert, vmstorage, and vmselect components providing multi-tenancy, replication, and independent namespace isolation. Data ingestion accepts both push protocols including InfluxDB line protocol, Graphite plaintext, OpenTSDB HTTP, CSV, and OpenTelemetry OTLP alongside pull-based Prometheus scraping and remote write, enabling drop-in replacement of existing monitoring stacks without reconfiguring exporters. MetricsQL extends standard PromQL with additional functions, subqueries, and implicit time range alignment while maintaining full backward compatibility with existing Prometheus alerts and Grafana dashboards. The vmalert component processes recording and alerting rules with Alertmanager integration, while vmbackup and vmrestore enable point-in-time snapshots to S3, GCS, and Azure Blob Storage. Stream aggregation operates as a StatsD alternative for pre-aggregating high-cardinality metrics before storage. NFS-compatible storage backends including Amazon EFS and Google Filestore allow shared persistent volumes across cluster nodes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Apache IoTDB
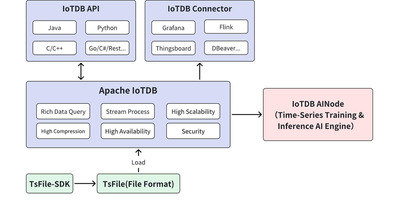
Sensors on factory floors, wind turbines, and connected vehicles produce readings every second, and Apache IoTDB is the time-series database built to store those readings and answer questions over them. Devices write through client sessions that tolerate out-of-order, delayed, and multi-frequency arrivals, so a gateway that reconnects after an outage can backfill history without corrupting the timeline. Series live in a device hierarchy you can browse like a directory tree, or in tables queried with standard SQL, common table expressions, set operations, and more than one hundred built-in aggregation and time-series functions. The TsFile columnar format shares one time column across aligned series and applies encodings designed for sensor data, which keeps high-frequency archives compact while Spark and Hadoop jobs read the same files directly for larger analysis. Pipe synchronization streams records or transfers whole TsFiles between edge sites and central clusters with path and device filtering, so plants keep collecting locally while headquarters queries a continuous copy. AINode brings forecasting, anomaly detection, and missing-value imputation into the database itself: register a model with SQL, then ask for predictions in the same query language instead of shipping measurements to a separate machine learning service. A low-memory Edge edition runs collection on constrained gateways, and clusters scale by adding DataNodes under ConfigNode coordination with automatic load balancing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Apache StreamPipes
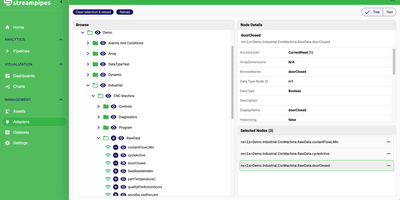
On the factory floor, the data already exists; it is just locked inside machines, PLCs, and protocols nobody on the analytics team speaks. StreamPipes unlocks it with guided adapters for OPC UA (including a web-based node browser), MQTT, Kafka, Pulsar, REST services, and industrial controllers, turning each source into a live stream in minutes. Domain experts then drag those streams into the pipeline editor, chain processors and sinks on a canvas, and watch connection validation check schema compatibility as they build, with live preview showing real values before anything is saved. Pipelines filter, enrich, aggregate, and route machine data, raise alerts, and write results to the built-in time-series data lake, where the data explorer charts history and spots trends. Finished pipelines run under an overview that starts, stops, and bulk-manages them, while detail views expose logs, metrics, status, and the pipeline as code. Live dashboards carry the same data to shop-floor screens and operations centers, organized around assets so a line, a cell, or a single machine becomes the navigation unit. Developers extend everything with custom adapters, processors, and sinks built on the Java SDK and deployed as microservices, or drive the platform from Python, Go, and Java clients. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Daily Stars Explorer
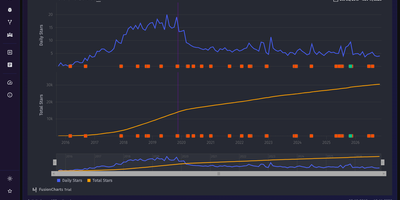
From a one-day Hacker News spike to a decade of steady growth, Daily Stars Explorer charts any GitHub repository's star history day by day, next to the releases and mentions that explain it. Type an owner and repository name, and daily and cumulative stars appear. Range shortcuts: 10Y, 5Y, YTD, QTD, MTD, and All. Zoom with a draggable lower navigator, switch to a Log Y axis, and read the stars gained inside the selected window. Transforms reshape the series. A trend line projects 30 days ahead. Yearly, monthly, or weekly grouping. Peak normalization. LOESS smoothing. Running average and median. First and second derivatives. Weekly growth rate. Feed overlays, enabled by optional provider credentials, mark releases and mentions from Hacker News, Reddit, GitHub, and YouTube right on the curve. Compare two already-fetched repositories on shared axes, with an aggregate selector, Log Y, and optional star milestones, then copy the link. With a GitHub token, separate pages chart commits, with the longest gap highlighted on demand, plus pull requests, issues, forks, and contributors. Global activity counts the public repositories or pull requests created on GitHub each day. Featured repos lists Hacker News and Reddit posts that link to GitHub projects, sortable by points, comments, or date. Star history, commit, and activity charts export to CSV or JSON. Favorite repositories can be pinned. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LynxDB
LynxDB is a single-binary log analytics database that ingests logs once into indexed columnar storage, so you can query the same events repeatedly without re-reading raw files or standing up a JVM stack. Pipe kubectl output or local files straight into the LynxFlow query engine for ad hoc investigation, or run the persistent server and let shippers deliver logs through Elasticsearch bulk, OpenTelemetry OTLP, Splunk HEC, syslog, and raw HTTP ingest paths. LynxFlow pipelines parse JSON, regex, key-value, CSV, and other formats at read time, then extend fields, filter with typed predicates, aggregate with stats, join CTEs, and rank results, all in one explicit grammar with time-series helpers for buckets, percentiles, gap filling, and trend lines. Full-text search runs on an FST dictionary, roaring bitmap postings, and bloom filters that skip cold segments, and materialized views keep partial aggregates ready so dashboards rewrite onto rollups automatically. Convert Sigma detections into LynxFlow queries for security hunting, tail live results as new logs arrive, and tier older data out to S3. Individual analysts use it to dissect local application logs, and platform teams run it as a cluster for shared observability with the Web UI and REST API open to everyone. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.