Evidently
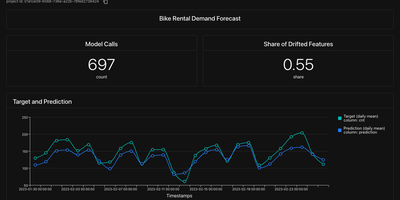
Evidently gives your models and LLM apps a proper check-up and keeps every result on one shared dashboard. Project dashboards chart predictions against targets, data drift, and quality scores over time, with counters for model calls and the share of drifted features. A reports page lists every evaluation snapshot with tags, metadata, timestamps, and view or download buttons, and a search box filters them by metadata. Over 100 built-in metrics cover data quality, classification, regression, ranking, recommendations, text descriptors, and LLM judges. Test suites add pass or fail conditions, so a nightly job can flag a drifting feature before customers notice a bad prediction. Datasets, traces, and prompts have their own tabs, which keeps retrieval and generation experiments beside the scores they produced. Reports export as HTML or JSON for sharing outside the dashboard. Results live in a local folder, a SQL database, or S3-compatible storage, and a remote workspace accepts snapshots sent from jobs running anywhere. Built-in demo projects with bike demand forecasting and e-commerce review classification show how a finished dashboard looks before you wire in your own data. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Laminar
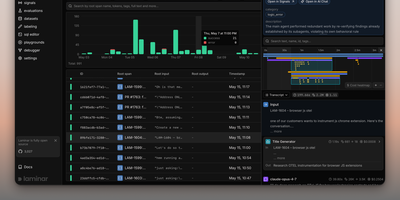
Backed by Y Combinator (S24) and processing traces from thousands of AI agents in production, Laminar is the open-source observability platform that treats agent debugging as a first-class engineering discipline rather than an afterthought. Its OpenTelemetry-native SDK auto-instruments Vercel AI SDK, LangChain, OpenAI, Anthropic, Gemini, Browser Use, Stagehand, Mastra, Pydantic AI, and the OpenAI Agents SDK with a single line of code, capturing every LLM turn, tool call, and sub-agent delegation as nested spans with full input/output data and token costs. The Signals engine lets you describe failures in plain language — "agent is stuck in a loop" or "tool returned empty results" — then reads every trace and alerts via Slack when it detects a match. A built-in debugger records runs and replays them from cache so each iteration takes seconds, designed for Claude Code, Cursor, or Codex to drive the repair loop via the MCP server or CLI. Run code-first evaluations in Python or TypeScript locally or in CI/CD pipelines, build datasets from production traces, and query everything with raw SQL through custom dashboards, the in-app editor, or your coding agent. The Rust backend delivers 20x trace compression, a custom real-time streaming engine, ultra-fast full-text search, and gRPC ingestion, while ClickHouse powers columnar analytics and PostgreSQL stores application state. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Langfuse
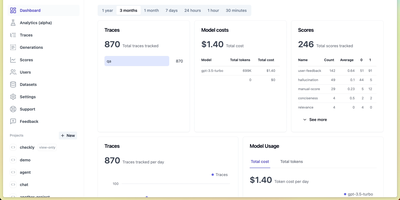
Backed by Y Combinator and trusted by over 2,300 companies processing billions of observations monthly, Langfuse is the most widely adopted open-source platform for building, monitoring, evaluating, and debugging LLM applications. The hierarchical tracing engine captures every LLM call, tool invocation, retrieval step, and agent action as nested spans based on OpenTelemetry, with automatic cost calculation, latency tracking, and token usage attribution across sessions and users. Prompt Management separates prompts from code with versioned artifacts, label-based deployments, one-click rollbacks, and runtime SDK fetching with server-side caching, while linking every generation back to its exact prompt version for attribution analytics. The evaluation system supports LLM-as-a-judge scoring, heuristic code evaluators, user feedback collection, and manual annotation workflows that run automatically on production traces or against curated datasets. The Playground enables interactive prompt testing on real production inputs with side-by-side model comparison across providers. Datasets and Experiments define test cases for systematic benchmarking with comparative result visualization. Native SDKs for Python and TypeScript provide decorator-based instrumentation, while 100+ integrations cover LangChain, LlamaIndex, OpenAI SDK, LiteLLM, Vercel AI SDK, and any OpenTelemetry-instrumented framework. The analytics dashboard surfaces cost breakdowns, quality scores, latency percentiles, and usage trends across models and prompt versions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
ClawMetry
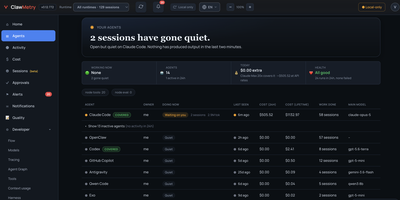
Without an SDK, a proxy, or a single line of agent code changed, ClawMetry reads the session files your AI agents already write and puts every session, tool call, token, and dollar on one live dashboard. The sessions view replays a run turn by turn, with a timeline that gives each tool call its own duration and cost, so a four-minute shell command stands apart from a call that took milliseconds. Usage charts split tokens and spend by runtime, model, session, and day. A live flow diagram follows messages from chat channels through the gateway to models and tools, and a context view tracks window use per turn along with compaction events. The Brain tab streams reasoning, tool calls, and errors as they happen, while memory, skills, health, logs, and cron jobs each get a tab of their own. OTLP receivers accept traces, metrics, and logs from runtimes that keep no local files. The MIT-licensed app reads OpenClaw, NVIDIA NemoClaw, Goose, and Qwen Code for free. Paid plans add the other 28 runtimes, including Claude Code, Codex, and Cursor, plus approval queues for risky tool calls, budget limits, anomaly detection, and a cost optimizer. Session data stays on your server unless you choose to run cloud sync. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.