VictoriaMetrics
Trusted by thousands of organizations processing billions of time series data points and backed by 17,000+ GitHub stars, VictoriaMetrics delivers a monitoring and time series database that outperforms Prometheus by 16x on query speed while consuming 2.5x less disk space through its optimized compression and storage engine. The architecture supports both single-node deployments handling 10M+ active time series and a horizontally scalable cluster version with vminsert, vmstorage, and vmselect components providing multi-tenancy, replication, and independent namespace isolation. Data ingestion accepts both push protocols including InfluxDB line protocol, Graphite plaintext, OpenTSDB HTTP, CSV, and OpenTelemetry OTLP alongside pull-based Prometheus scraping and remote write, enabling drop-in replacement of existing monitoring stacks without reconfiguring exporters. MetricsQL extends standard PromQL with additional functions, subqueries, and implicit time range alignment while maintaining full backward compatibility with existing Prometheus alerts and Grafana dashboards. The vmalert component processes recording and alerting rules with Alertmanager integration, while vmbackup and vmrestore enable point-in-time snapshots to S3, GCS, and Azure Blob Storage. Stream aggregation operates as a StatsD alternative for pre-aggregating high-cardinality metrics before storage. NFS-compatible storage backends including Amazon EFS and Google Filestore allow shared persistent volumes across cluster nodes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OpenSquilla
Claiming 60-80% token cost reduction compared to flat single-model deployments and backed by 6,500+ GitHub stars, OpenSquilla delivers an intelligent AI agent runtime where a local ML classifier evaluates every turn on message length, code blocks, keyword patterns, and semantic embeddings before routing it to the optimal model tier from C0 through C3. The pluggable provider layer connects natively to TokenRhythm, OpenRouter, OpenAI, Anthropic, Ollama, DeepSeek, Gemini, DashScope, Moonshot, Mistral, Groq, Zhipu, SiliconFlow, vLLM, LM Studio, and additional compatible backends with primary-plus-fallback selection. The four-tier cognitive memory architecture spans working, episodic, semantic, and raw layers with vector-semantic and BM25 retrieval powered by on-device ONNX embeddings that never leave your infrastructure. Security isolation operates at the syscall level via Bubblewrap on Linux and Seatbelt on macOS, complemented by policy-based execution controls and prompt injection protections. The unified TurnRunner executes identically across the Vue-based control console Web UI, terminal CLI, and chat channel integrations including Slack and Discord, ensuring consistent tool dispatch, retry logic, and decision logging regardless of entry point. Built-in skills cover deep research, multi-search-engine queries, document generation for DOCX, PPTX, XLSX, and PDF formats, GitHub integration, cron scheduling, and bounded subagent delegation. Per-agent workspaces with durable session storage provide transcript replay, context state management, and per-call cost tracking with automatic quota enforcement. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Erxes
Replacing HubSpot, Zendesk, Intercom, and Linear with a single self-hosted platform, erxes delivers an Experience Operating System trusted by over 4,000 GitHub stars and built on a modern Nx-powered monorepo architecture. The core ships with six foundational modules — My Inbox for omnichannel conversations across email, web chat, voice, and Discord; Contacts for unified customer profiles; Products for catalog management; Segments for behavioral targeting; Automation for visual workflow builders; and Documents for template generation. Beyond the core, a plugin marketplace activates Frontline for ticket management and omnichannel support queues, Sales for deal pipelines and lead scoring, Operations for project boards with cycle management, Content for headless CMS and knowledge bases, and Team for employee directories, time clocks, and internal chat. The technical stack combines GraphQL Federation with Apollo Server v4 and tRPC v11 microservices on Node.js, React 18 micro-frontends via Rspack Module Federation with TailwindCSS 4, MongoDB with Mongoose for persistence, Redis for caching, BullMQ for job queues, and Elasticsearch for full-text search. Deployment supports Docker Compose orchestration with automatic service discovery across all plugin containers. The Global Profile architecture enables agencies to manage multiple client brands under a single login with separated data stores. iOS and Android SDKs embed the messenger widget directly into mobile applications. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Maxun
With over 16,800 GitHub stars and growing rapidly, Maxun has become the go-to open-source platform for teams who need structured web data without writing scrapers. The TypeScript-based platform provides a no-code visual recorder that captures point-and-click interactions in real-time browser sync, automatically generating reusable extraction robots that handle pagination, infinite scrolling, and dynamic content. LLM-powered extraction accepts natural language prompts like "Extract 10 companies from the Y Combinator website" without requiring a URL — Maxun identifies the source and performs the extraction autonomously. The platform handles authentication-protected pages, adapts automatically to website layout changes through self-healing selectors, and exports directly to Google Sheets, Airtable, or any destination via webhooks. Robots run on configurable schedules with cron-based timing, turning any website into a perpetually fresh RESTful API endpoint. The crawl engine discovers and processes linked pages across entire domains with configurable depth and URL filtering, while the search capability runs automated queries across multiple engines. Official Node.js and Python SDKs provide programmatic control over robot creation, execution, and data retrieval, with MCP integration enabling direct connection to AI tools like Claude. The n8n community node enables workflow automation without custom code. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Novu
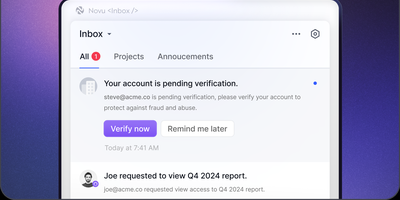
Powering notification delivery for thousands of organizations with over 39,000 GitHub stars, Novu is the open-source communication infrastructure that eliminates the need to build separate integrations for every messaging channel. The TypeScript-based platform provides a single API endpoint that routes notifications across In-App Inbox, Email via SendGrid, Mailgun, AWS SES, and Postmark, SMS through Twilio, Vonage, and Plivo, Push via Firebase Cloud Messaging, Expo, and APNS, and Chat through Slack, Discord, Microsoft Teams, and WhatsApp. The embeddable React Inbox component delivers real-time WebSocket-powered notifications with read/unread states, action buttons, and user-controlled preferences directly inside your application. The workflow engine orchestrates complex multi-channel delivery with conditional branching, time delays, digest batching to reduce notification fatigue, throttle controls, and per-step channel fallbacks. Novu Connect introduces Agent Communication Infrastructure enabling AI agents built with LangChain, Claude, or custom frameworks to hold threaded two-way conversations with humans across any supported channel through a single conversation model with identity resolution and credential management. The backend runs on Node.js with NestJS, MongoDB for notification storage, Redis with BullMQ for job queuing, and Socket.io for real-time delivery. Self-hosting deploys via Docker Compose with the dashboard accessible at port 4200. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Crawl4AI
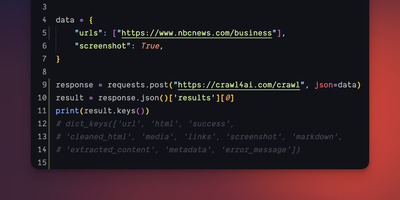
With over 77,000 GitHub stars, Crawl4AI is the most-starred open-source web crawler on GitHub and the go-to tool for converting the web into AI-ready data. Built on Python and Playwright, it transforms any website into clean Markdown with headings, tables, code blocks, and citation hints optimized for LLM ingestion, or extracts structured JSON via CSS selectors, XPath expressions, or direct LLM-based schema extraction through OpenAI, Anthropic, and Ollama providers. The self-hosted Docker server exposes a REST API on port 11235 with endpoints for crawling, streaming results, screenshots, PDF generation, JavaScript execution, and LLM-powered extraction. Version 0.9.x introduced secure-by-default operation with mandatory JWT authentication, strict request validation, declarative hooks replacing inline code, and bounded job queues. Adaptive crawling uses information foraging algorithms to determine when sufficient data has been gathered, while deep crawl mode traverses link graphs intelligently. The async browser pool manages concurrent sessions with stealth plugins, proxy rotation, custom headers, and session persistence for authenticated scraping. A built-in MCP server enables direct integration with Claude, ChatGPT, and Cursor for AI-driven web research workflows. Content filtering applies BM25 and TF-IDF relevance scoring to extract only pertinent sections from noisy pages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Forem
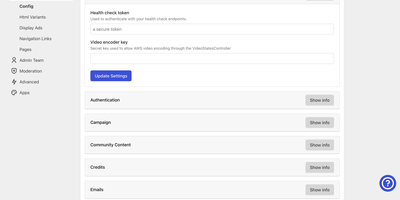
With 22,700 GitHub stars, 4,100+ forks, and proven scale powering dev.to — one of the largest developer communities serving millions of monthly users — Forem provides a complete community platform for building engaged audiences around shared interests, whether for developer documentation, customer communities, fan bases, or professional networks. The Rails backend with Preact frontend delivers article publishing with a rich Markdown editor, threaded discussions, user profiles with portfolio links, tag-based content organization, podcast hosting, classified listings for jobs and events, and social interactions including reactions, bookmarks, and following. AI-powered semantic search using PostgreSQL pgvector embeddings surfaces relevant content across articles and concepts, while scheduled automations enable community bots to create automated roundups, republish curated content, and trigger time-based moderation actions. Score-based content ranking replaces simple reaction counts with nuanced algorithms that resist gaming. The admin dashboard provides user management, content moderation, community settings, analytics, and organization controls. OAuth integration supports GitHub, Twitter, Apple, and configurable OIDC providers for frictionless sign-up. Dynamic open-graph image generation creates branded social cards automatically. Deploy with Kamal 2 to any cloud provider or bare metal server with PostgreSQL and Redis. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Ory Kratos
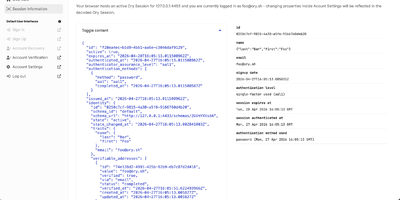
With 13,800 GitHub stars, adoption by OpenAI for ChatGPT's authentication infrastructure serving 800 million weekly active users, and governance under the Ory open-source ecosystem, Ory Kratos provides enterprise-grade identity management as a headless API server that separates authentication logic from user interface — enabling any frontend framework to consume standardized self-service flows for registration, login, recovery, verification, and profile management. Multi-factor authentication supports passkeys, WebAuthn security keys, TOTP authenticator apps, SMS one-time codes, email magic links, and backup recovery codes with configurable Authenticator Assurance Levels enforcing step-up authentication for sensitive operations. Social sign-in connects to any OpenID Connect provider including Google, GitHub, Apple, and Microsoft, plus enterprise SAML 2.0 federation for B2B single sign-on. Customizable identity schemas using JSON Schema define user profiles with flexible trait structures, while pre- and post-flow webhooks enable integration with CRMs, analytics, and compliance systems. The courier system handles email and SMS delivery for verification codes and password recovery links. Session management provides device tracking, forced logout, and configurable lifespans with privileged session elevation. Deploy alongside Ory Hydra for OAuth2/OIDC token issuance and Ory Keto for fine-grained permissions to build a complete identity platform. Docker Compose deployment with PostgreSQL. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Apache APISIX
With 17,000 GitHub stars, 460+ contributors, and deployments across telecommunications, automotive, and financial services running on over 10,000 CPU cores at the largest known installations, Apache APISIX delivers a fully dynamic API gateway achieving 140,000 QPS on eight cores with sub-millisecond latency through NGINX's event-driven architecture and LuaJIT-compiled plugin execution. The 100+ open-source plugins cover authentication (JWT, OAuth 2.0, OIDC, Keycloak, LDAP), observability (Prometheus, Datadog, SkyWalking, OpenTelemetry), traffic management (rate limiting, circuit breaking, canary releases, traffic splitting), and security (CORS, IP restriction, CSRF protection) — all hot-reloadable without process restarts via etcd-based real-time configuration synchronization. Multi-protocol support handles HTTP, gRPC, MQTT, TCP, UDP, and WebSocket traffic for both north-south API access and east-west service mesh communication. AI gateway capabilities proxy requests to 20+ LLM providers with semantic caching, token-aware rate limiting, provider failover routing, and content moderation. Custom plugins extend the gateway in Lua, Go, Java, Python, or WebAssembly. Radixtree route matching handles 100,000+ routes without performance degradation. Functions as a Kubernetes ingress controller with native service discovery for Consul, Nacos, and Eureka. Deploy via Docker or Helm charts with horizontal scaling through etcd cluster coordination. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Redpanda
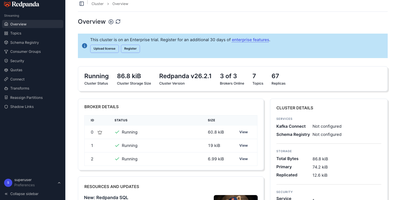
With 12,400 GitHub stars and adoption across enterprises processing billions of events daily, Redpanda delivers a complete Kafka wire protocol implementation in C++ that existing Kafka producers, consumers, Kafka Connect connectors, and Kafka Streams applications connect to without code changes — eliminating JVM garbage collection pauses and ZooKeeper coordination overhead through a single binary architecture built on the Seastar framework's thread-per-core model. The integrated schema registry supports Avro, Protobuf, and JSON Schema validation directly within the broker without separate infrastructure. Tiered storage automatically offloads cold data to object storage while maintaining seamless consumer access across the full retention window. Redpanda Console provides a web-based management interface for topic inspection, consumer group monitoring, schema management, and ACL configuration. Redpanda Connect extends the platform with 200+ pre-built connectors for data pipelines between databases, cloud services, and streaming systems. Exactly-once semantics with idempotent producers and transactional guarantees ensure data integrity for financial, healthcare, and compliance workloads. The Adaptable Data Plane in version 26.1 enables per-topic performance profiles balancing throughput, latency, and durability within a single cluster. Deploy via Docker or Kubernetes with official Helm charts — a three-node cluster starts with a single rpk command. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed (converts to Apache 2.0 after four years).
Valkey
With 26,600 GitHub stars, 50 contributing companies including AWS, Google Cloud, Oracle, and Ericsson, and governance under the Linux Foundation ensuring the BSD 3-Clause license can never be revoked by a single entity, Valkey delivers a truly open-source Redis-compatible key-value datastore that reached 1.19 million requests per second in version 8.0 through redesigned asynchronous I/O threading across CPU cores while maintaining single-threaded data structure operations for predictability. Native data structures include strings, hashes, lists, sets, sorted sets, bitmaps, HyperLogLogs, streams, and geo-spatial indices with JSON support through modules. Valkey 9.0 shipped full-text search and aggregation via Valkey Search, enabling tag queries, numeric filtering, and text matching directly within the datastore without external search engines. Cluster mode provides horizontal scaling with automatic sharding, replication for high availability, and per-slot metrics for granular monitoring. Lua scripting enables complex atomic operations, while the module plugin system extends the server with custom commands and data types including probabilistic Bloom filters. Client libraries for Python, Java, Go, Node.js, and PHP maintain full Redis OSS protocol compatibility — existing Redis applications work without code changes. Deploy as a standalone daemon or in clustered mode with Docker, supporting persistent and ephemeral workloads on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 3-Clause licensed.
SurrealDB
With 32,800 GitHub stars, 180 contributors, and version 3.2 shipping in July 2026, SurrealDB eliminates the database zoo by unifying document, graph, relational, time-series, geospatial, and key-value data models into a single Rust binary queried through SurrealQL — an intuitive SQL-like language that handles graph traversals, record links, subqueries, and computed fields without switching between multiple database engines. Purpose-built for AI applications, it integrates vector indexing, full-text search, and hybrid retrieval that blends semantic similarity with graph and relational intelligence for context-aware RAG pipelines and recommendation engines. Real-time subscriptions and event-driven triggers push live data changes to connected clients without requiring external message brokers like Kafka. Multi-row, multi-table ACID transactions guarantee consistency while incrementally computed views deliver pre-calculated analytics without batch processing. Role-based access control with record-level permissions, JWT authentication, and multi-tenant isolation enables backend-as-a-service usage where client applications connect directly with fine-grained security. SDKs for JavaScript, Python, Go, Rust, .NET, and Java connect via WebSocket or HTTP APIs. Storage and compute separation allows deployment as an embedded library, a single-node server, or a highly-scalable distributed cluster with TiKV or FoundationDB backends. Deploy via Docker with persistent volumes on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Source-available licensed.
Forgejo
Governed by the non-profit Codeberg e.V. with over 150 contributors and quarterly major releases reaching v16.0 in July 2026, Forgejo delivers a complete code collaboration platform in a single Go binary that runs comfortably on 512 MB of RAM — providing full Git hosting with SSH and HTTPS, pull requests with inline code review, issue tracking with labels and milestones, kanban project boards, wikis, and an integrated package registry supporting Docker, npm, PyPI, Maven, NuGet, and Cargo. Forgejo Actions provides GitHub Actions-compatible CI/CD with reusable workflows, OpenID Connect for secure third-party access, ephemeral runners for autoscaling, and dynamic matrix support for complex build pipelines. The platform implements ActivityPub-based forge federation allowing issues, pull requests, and stars to work across independent instances — enabling a decentralized development ecosystem similar to how Mastodon federates social networks. Organizations and team permissions provide fine-grained access control, while LDAP, OAuth2, and OpenID authentication integrate with existing identity infrastructure. Code search indexes repositories for fast discovery, LFS handles large files efficiently, and mirror synchronization imports repositories from GitHub, GitLab, and other forges. Deploy via a single static binary, Docker container, or official Helm charts with SQLite for small instances or PostgreSQL and MySQL for production workloads. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPLv3+ licensed.
Checkmate
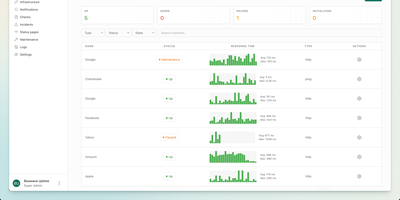
With 10,400 GitHub stars, 153 contributors, and no per-monitor pricing to worry about, Checkmate delivers comprehensive infrastructure monitoring from a single self-hosted dashboard — tracking uptime, page speed, server hardware, Docker containers, and even game servers without sending a byte of telemetry off your network. Ten monitor types cover HTTP, ping, TCP, gRPC, WebSocket, DNS, SSL certificate expiry, Docker container health, Lighthouse page speed with Core Web Vitals tracking, and game server status for over 100 server types including Minecraft and CS2. The Globalping integration enables geo-distributed monitoring from six continents, running ping and HTTP checks from Africa, Asia, Europe, North America, South America, and Oceania with results plotted on an interactive map. The optional Capture agent written in Go collects CPU, RAM, disk usage, temperature, and network metrics from any Linux, Windows, Mac, or Raspberry Pi host. Public status pages ship with four built-in themes and custom branding support, showing per-service uptime bars and incident history on a single shareable URL. Alert notifications reach teams through email, Discord, Slack, PagerDuty, Microsoft Teams, Telegram, Matrix, ntfy, Twilio SMS, and webhooks. Deploy via a single Docker Compose file requiring roughly 1 GB RAM — up and running in under five minutes on any Docker host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Briefer
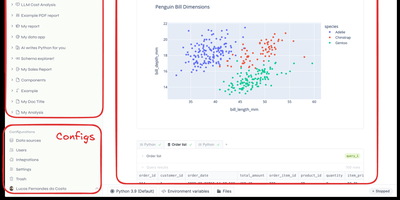
Backed by Y Combinator with 4,300 GitHub stars and growing rapidly since its September 2024 launch, Briefer delivers the first truly unified notebook-and-dashboard platform that eliminates the fragmented workflow of juggling Jupyter for analysis, Tableau for visualization, and Notion for documentation — combining all three in a single Notion-like workspace where SQL query results automatically become Python DataFrames accessible in subsequent code blocks. The built-in AI analyst understands your database schema and notebook context to generate SQL queries, write Python transformations, create visualizations, and fix errors on demand using configurable OpenAI or private LLM backends. Connect directly to PostgreSQL, MySQL, BigQuery, Redshift, Snowflake, and Amazon Athena as data sources, or upload CSV files for immediate analysis. Native point-and-click visualizations produce charts, tables, and dashboards without writing code, while interactive data apps use inputs, dropdowns, and date pickers to create parameterized reports for non-technical stakeholders. Scheduled execution runs notebooks and dashboards periodically with results delivered via Slack integration or public shareable links. Write-back queries modify production data directly from notebooks for ad-hoc pipeline testing. The architecture runs as three Docker containers — web frontend, API server, and optional AI service — backed by PostgreSQL and a Jupyter server for Python execution, deployable via single Docker command, Docker Compose, or Helm charts for Kubernetes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Prefect
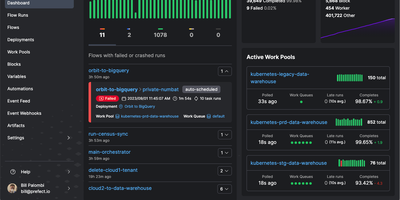
With 23,600 GitHub stars, 13 million monthly PyPI downloads, and 425+ contributors automating over 200 million data tasks monthly for Fortune 50 companies like Progressive Insurance and disruptors like Cash App, Prefect is the most widely deployed open-source workflow orchestration framework for Python — turning any script into a resilient production pipeline with a single @flow decorator while eliminating rigid DAG structures entirely. The durable execution engine persists task results and automatically resumes from failures without replaying expensive upstream work, guaranteeing exactly-once execution for any Python function. Event-driven automation triggers workflows from webhooks, cloud events, or state changes through a real-time event bus that detects what happens or fails to happen across your entire data platform. Work pools decouple workflow code from infrastructure, enabling seamless switching between Docker, Kubernetes, AWS ECS, Azure Container Instances, GCP Cloud Run, and serverless environments without modifying pipeline logic. Native Ray and Dask task runners extend execution across clusters for compute-intensive workloads. The self-hosted server provides a monitoring dashboard with flow run timelines, task state visualization, scheduling, and automation configuration. The third-generation engine reduces overhead by over 90 percent compared to Prefect 2, supporting batch, event-driven, interactive, and background task workflows. Deploy via Docker Compose with PostgreSQL, Redis, server, background services, and worker containers, or use official Helm charts for production Kubernetes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Dagster
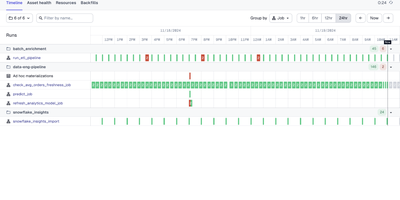
With nearly 16,000 GitHub stars, 5.7 million monthly PyPI downloads, and 400+ contributors, Dagster is the most widely adopted asset-centric data orchestration platform — replacing task-oriented schedulers like Apache Airflow with a declarative model where every pipeline is defined as Python functions producing data assets such as tables, datasets, machine learning models, and reports. The built-in asset graph provides automatic lineage tracking across your entire data platform, showing exactly how data flows from ingestion through transformation to downstream consumption in a single unified view. Declarative Automation goes beyond cron scheduling with event-driven conditions that intelligently trigger materializations based on upstream freshness, data quality signals, and dependency state. The integrated data catalog auto-generates documentation from asset metadata, ensuring it never drifts out of sync with production. Native first-class integrations connect dbt, Snowflake, BigQuery, Databricks, Fivetran, Airbyte, Spark, Great Expectations, Tableau, Power BI, AWS, GCP, and Azure without custom glue code. The web UI visualizes asset graphs, run history, schedules, sensors, and partitioned materializations with built-in alerting via Slack and PagerDuty. Dagster Pipes enables executing arbitrary code in external environments including Spark clusters, Kubernetes Jobs, and cloud functions. Deploy via Docker Compose on a single VM with separate containers for the webserver, daemon, and code locations, or use official Helm charts for production Kubernetes with K8sRunLauncher scaling each run as an independent Job. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
InsForge
With 12,600 GitHub stars and 52 releases in under a year of development, InsForge is the fastest-growing open-source backend platform purpose-built for AI coding agents — giving Claude, Cursor, and any MCP-compatible tool direct access to database, authentication, storage, compute, and AI model infrastructure through a single self-hosted stack. The native MCP server exposes every InsForge operation as callable tools, letting coding agents autonomously create database tables, manage user authentication, upload files, deploy edge functions, and ship complete full-stack applications without human intervention. The Model Gateway provides an OpenAI-compatible API that routes requests across multiple LLM providers (OpenAI, Anthropic, Google, and open-source models) with unified billing, rate limiting, and fallback logic. PostgreSQL with pgvector handles both relational data and vector embeddings for RAG pipelines, while S3-compatible storage manages file uploads and static assets. Edge Functions run serverless TypeScript code on Deno with sub-millisecond cold starts for API endpoints, webhooks, and scheduled tasks. The authentication system provides user management, OAuth2 flows, sessions, and magic links with JWT token handling built in. Site Deployment builds and serves frontend applications with automatic SSL and custom domain configuration. The CLI paired with Agent Skills enables terminal-based workflows where agents invoke InsForge operations directly from the command line. Deploy via Docker with PostgreSQL as the only required external dependency. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.