RepoCloud RepoCloud
  • Browse
  • Deploy
  • MCP
  • Pricing
  • Docs
  • Log In
  • Start for Free
Explore
All Apps 2083 Most Stars Most Watching Most Forks Newly Added Trending
SaaS Alternative
Notion Datadog Dropbox Confluence ChatGPT New Relic Google Drive WeTransfer Asana YNAB GitBook OpenRouter
Categories
Developer Tools DevOps self-hosted Productivity Automation AI Agents Monitoring AI Collaboration Privacy Analytics Security Knowledge Base Infrastructure Observability LLM Knowledge Management Docker Dashboard MCP Media Server API File Sharing Project Management

No matching categories.

RepoCloud
  • Browse
  • Submit
  • Pricing
  • Docs
  • Deploy
  • Agent MCP
  • API Docs
  • llms.txt
  • Support
  • Affiliates
  • Guide
  • Status
  • Sign In
  • Register
  • Terms
  • Privacy
1 app LLM Deployment
ReadyLLM screenshot thumbnail

ReadyLLM

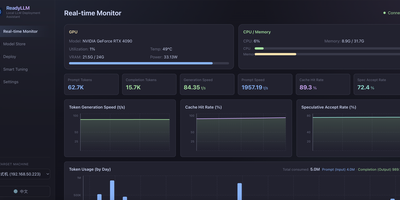
Your inference server should not sit mostly idle while a model crawls along at ten tokens per second, so ReadyLLM gives you a visual way to deploy, watch, and tune LLMs until the hardware is actually earning its keep. Add the machine under your desk or a remote box over SSH, let hardware detection read its GPU, VRAM, CPU, and memory, and get model recommendations that fit what you own instead of wishful downloads. A model store catalogs text, image, and video models with parameter counts, precision, resolutions, and real weight filenames, background downloads from multiple sources, and integrity checks when they land. One click starts or stops llama.cpp, vLLM, or SGLang services, installs a missing engine matched to your GPU backend, and leaves runtime parameters open for manual tweaks. Live curves track GPU utilization, memory, throughput, and latency as requests flow. When speed disappoints, two-phase auto tuning searches the knobs that matter, checks VRAM feasibility before it wastes your time, and benchmarks honestly against latency, throughput, or prefill goals; an AI tuning mode can reason through the same loop across several rounds. Beyond chat models, ComfyUI generation covers text-to-image and text-to-video, storyboards, shot-by-shot long video, and upscaling, with prompts optionally expanded first. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.

Deploy
  • 1
Browse RepoCloud
Explore
All Apps 2083 Most Stars Most Watching Most Forks Newly Added Trending
SaaS Alternative
Notion Datadog Dropbox Confluence ChatGPT New Relic Google Drive WeTransfer Asana YNAB GitBook OpenRouter
Categories
Developer Tools DevOps self-hosted Productivity Automation AI Agents Monitoring AI Collaboration Privacy Analytics Security Knowledge Base Infrastructure Observability LLM Knowledge Management Docker Dashboard MCP Media Server API File Sharing Project Management

No matching categories.

RepoCloud
  • Browse
  • Submit
  • Pricing
  • Docs
  • Deploy
  • Agent MCP
  • API Docs
  • llms.txt
  • Support
  • Affiliates
  • Guide
  • Status
  • Sign In
  • Register
  • Terms
  • Privacy

Get started for free

Sign up and get free credit for your first 30 days at RepoCloud

Get Started

This offer applies to new customers

RepoCloud RepoCloud

Deploy open source apps in one click, at half the cost.

RepoCloud - One-click deploy 200+ SaaS alternatives, elastic autoscaling | Product Hunt
  • Browse
  • Submit
  • Pricing
  • Docs
  • Deploy
  • Agent MCP
  • API Docs
  • llms.txt
  • Support
  • Affiliates
  • Guide
  • Status
  • Sign In
  • Register
  • Terms
  • Privacy