Stuntd
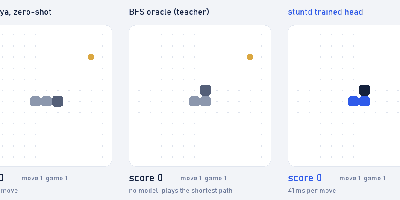
If your app asks an LLM the same routing, triage, or moderation question thousands of times a day, stuntd is the local proxy that learns those answers and stops paying for them. It sits in front of OpenAI or Anthropic as a drop-in replacement for the provider base URL, recording typed requests while relaying everything else byte for byte, and distils each decision site into a small head on a frozen Laya encoder. Once trained, the head answers in about 20 milliseconds with no tokens and no round trip; when its calibrated confidence falls below the site threshold, or the novelty gate flags the input, the question goes back to the provider instead of being guessed at. It speaks four protocols on one daemon: Jev System One with choice, score, and noul questions, the OpenAI Decisions API, Chat Completions, and the Anthropic Messages API, and every response carries an X-Stuntd header showing who answered. Run it keyless and the base Laya checkpoint answers zero-shot locally, put the paid Jev API in front to teach from real traffic, or import labelled rows and train directly. A few thousand rows close the gap: in the banking demo, the risk question climbs from 30.0 to 72.5 percent. A shipped Claude Code PreToolUse hook answers "may this command run" in about 50 milliseconds, without sending every command to a provider. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Subpool
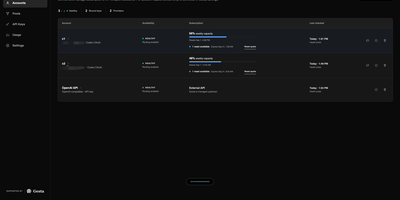
Your company pays for AI subscriptions nobody can see, scattered across personal accounts and team plans, and Subpool is the self-hosted control plane that pools that authorized capacity and hands every employee one key with limits you govern. Administrators combine subscription and API accounts into pools behind a single managed endpoint, then allocate employee-specific keys across whichever provider accounts are healthy. The console watches account health, remaining subscription capacity, and when each plan window resets, and routing prefers subscription capacity first, falling back to paid API accounts under the very same employee key when a window runs dry. Rate-limit, expire, or revoke any person's access independently, and keep every key-to-account assignment visible and auditable instead of buried in a shared credential nobody can trace. The employee API speaks OpenAI-compatible Responses and Chat Completions, so existing tools point at your pool unchanged, while aggregate input and output token telemetry is tracked per key in provider-native units. For OpenAI accounts, a Costs API estimate shows the remaining grant balance; Bailian Token Plan accounts display their five-hour, weekly, or monthly quota windows. Upstream credentials stay encrypted, and prompts, responses, and source code are never persisted. One Go service with an embedded console and PostgreSQL runs from Docker Compose, with sign-in on port 8081 and the employee API on 8080. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.