Olla
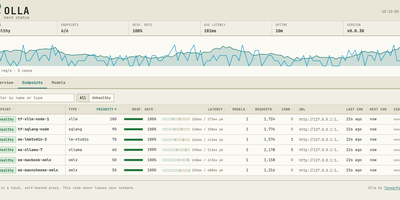
One endpoint for every inference box you own: Olla is a proxy and load balancer that fronts your self-hosted LLM backends and routes each request to a healthy node. Your apps keep calling a single OpenAI-compatible address on port 40114, and Olla picks the backend by priority, response rate, and live health. When a node drops, requests retry on the next endpoint automatically and the failed node rejoins after recovery, with circuit breakers keeping bad nodes out of rotation. Multi-turn conversations stick to one backend so its KV cache stays warm across the chat. Model lists from every provider merge into one catalogue, and the same model served by several nodes appears once, ready to route anywhere. Backends with native Anthropic support receive Messages API calls untouched, and other backends get automatic translation, so Claude Code and similar tools can drive your local models. Text embeddings and rerank requests route to the host that serves them, and outbound authentication covers backends that expect API keys. The embedded Herd Dashboard shows fleet health, per-endpoint latency, and the discovered model inventory from the binary itself. The whole proxy runs in under 50 MB of RAM. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Stuntd
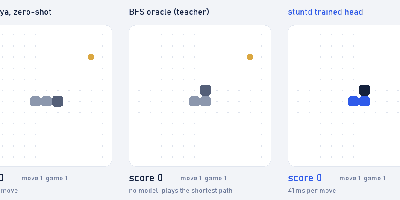
If your app asks an LLM the same routing, triage, or moderation question thousands of times a day, stuntd is the local proxy that learns those answers and stops paying for them. It sits in front of OpenAI or Anthropic as a drop-in replacement for the provider base URL, recording typed requests while relaying everything else byte for byte, and distils each decision site into a small head on a frozen Laya encoder. Once trained, the head answers in about 20 milliseconds with no tokens and no round trip; when its calibrated confidence falls below the site threshold, or the novelty gate flags the input, the question goes back to the provider instead of being guessed at. It speaks four protocols on one daemon: Jev System One with choice, score, and noul questions, the OpenAI Decisions API, Chat Completions, and the Anthropic Messages API, and every response carries an X-Stuntd header showing who answered. Run it keyless and the base Laya checkpoint answers zero-shot locally, put the paid Jev API in front to teach from real traffic, or import labelled rows and train directly. A few thousand rows close the gap: in the banking demo, the risk question climbs from 30.0 to 72.5 percent. A shipped Claude Code PreToolUse hook answers "may this command run" in about 50 milliseconds, without sending every command to a provider. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.