Zenko CloudServer
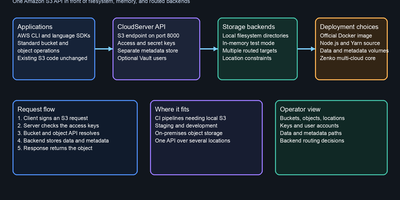
Zenko CloudServer is an open-source object storage server that speaks the Amazon S3 API, giving your applications one familiar endpoint for buckets and objects while the data itself lands on local disk or across several storage backends you choose. Developers point the standard AWS tools and SDKs at the server on port 8000, create buckets, and store objects with the same calls they would use against the public cloud, which makes it a practical stand-in for S3 in continuous integration pipelines, staging environments, and on-premises deployments that cannot send data outside the building. Single-backend mode writes to a filesystem directory you configure, an in-memory mode serves tests that need fast disposable storage, and multiple-backend mode routes each object by location constraint, so one bucket can keep hot data nearby and push colder copies to another target. Access keys and secret keys control who can read and write, metadata is stored separately from object data, and optional Vault integration handles user management for larger installations. The server ships as a Docker image for quick deployment and runs from source with Node.js and Yarn, and because it is the storage core of the Zenko multi-cloud data controller, the same API also fronts public cloud backends for teams building a single access layer over data stored in several places. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Alarik
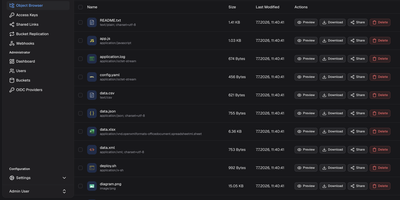
Alarik is a self-hosted S3-compatible object storage server that lets you store files, backups, media, and application data on your own hardware while keeping the S3 APIs your tools already expect. Create buckets, upload objects with multipart support for large files, and retrieve them again through core operations, range reads, presigned URLs, and bucket or object tagging. Versioning keeps earlier copies, delete markers, and listings under your control, while lifecycle rules expire old versions and clean up incomplete uploads automatically. The web console lets you drag and drop files or whole folders, search recursively across nested folders, edit metadata in place, preview individual versions, and share time limited public links. Administrators manage users, access keys, bucket policies, and public access blocks from the same console, with live charts for CPU, memory, traffic, and storage. Bucket webhooks send event notifications when objects change, and replication rules continuously copy data to remote S3 compatible targets, synchronously or asynchronously per rule. Clusters add erasure coded storage across nodes, read repair, bit rot scrubbing, and automatic rebalancing when nodes join, drain, or return. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.