Kvrocks
Every Redis client you already use connects to Kvrocks without a single code change, but instead of holding your entire dataset in RAM, data lives on SSD through RocksDB, turning terabytes of memory cost into pennies of disk. An Apache Software Foundation top-level project, Kvrocks supports strings, hashes, lists, sets, sorted sets, streams, bitmaps, JSON documents, TimeSeries data points, Bloom filters, Cuckoo filters, and HyperLogLog structures, all persisted to disk with in-memory caching for hot data access. Asynchronous replication using binlog similar to MySQL provides data durability across replicas, while Redis Sentinel integration enables automatic failover when master or replica nodes fail. The proxyless centralized cluster architecture distributes data across shards while remaining fully compatible with standard Redis cluster SDKs and clients. Token-based namespaces provide multi-tenant isolation with authentication per namespace, going beyond Redis SELECT's numbered database model. RocksDB's LSM-tree storage engine provides efficient compression through configurable compaction strategies, reducing disk footprint dramatically while maintaining sub-millisecond reads for cached keys. Migration tooling includes RedisShake for Redis-to-Kvrocks live migration and kvrocks2redis for reverse migration, enabling gradual adoption without service interruption. The kvrocks_exporter exposes Prometheus-compatible metrics for monitoring, and OpenTelemetry integration provides distributed tracing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Apache Druid
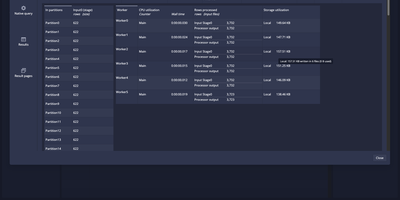
When dashboards must answer in under a second over billions of streaming events, Apache Druid is the real-time analytics database built for the job. Point a supervisor at an Apache Kafka topic or Amazon Kinesis stream and events are queryable on arrival, late data included, with exactly-once guarantees. Batch loads run as SQL: INSERT and REPLACE statements ingest files, and EXTERN reads external sources. Schema auto-discovery adds new columns and types as data lands. Joins run at ingestion or at query time. A web console gathers the daily work in one place: a tabbed Query view with EXPLAIN PLAN and query history, a Connect external data wizard, and pages for datasources, segments, retention rules, supervisors, tasks, services, and lookups. Configurable tiers place hot and cold data on different hardware. Quality-of-service settings shield priority workloads from heavy ones. Clickstream analytics, ad campaign reporting, network telemetry, application performance tracking, and IoT metrics all fit. Applications connect over the HTTP SQL API or the Avatica JDBC driver, and native JSON queries remain available for advanced needs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.