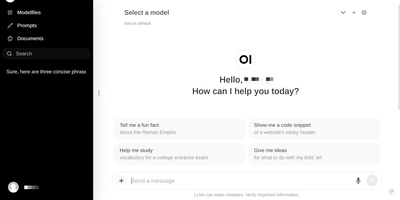
Open WebUI
Large language models get a polished front end that can run fully offline: Open WebUI is the self-hosted front end of choice. It talks to local model runners, primarily Ollama, and to any OpenAI-compatible API, so LM Studio, vLLM, Groq, Mistral, OpenRouter, and cloud providers all plug into the same chat interface and can be mixed per conversation. RAG is built in: upload files to knowledge bases or reference them in chat with the # command, backed by a choice of nine vector databases (ChromaDB and PGVector officially maintained) and multiple extraction engines including Tika and Docling, with hybrid BM25-plus-vector search and cross-encoder reranking. Web search results from providers like SearXNG, Brave, and Tavily inject directly into conversations. Extensibility comes from Python tools and functions that run inside the chat, a Pipelines plugin framework, and native MCP support. Multi-user features include RBAC, SSO, and group permissions, and the instance itself exposes an OpenAI-compatible API your own apps can call.
AnythingLLM
Chat with your own documents: AnythingLLM, from Mintplex Labs, wraps retrieval-augmented generation (RAG) in an open-source application anyone can run. You organize content into workspaces, each an isolated namespace with its own documents, vector embeddings, chat history, and settings, so one instance can hold several separate knowledge bases. Upload PDFs, DOCX, TXT, and other formats, or scrape web pages; the built-in collector parses and chunks them into a vector database (LanceDB by default, with Pinecone, Chroma, Qdrant, and others supported). Answers cite their source documents. It works with both cloud LLMs (OpenAI, Anthropic, Gemini) and local ones via Ollama or LM Studio, and the embedding model is separately configurable. Beyond RAG chat, it includes AI agents that can browse the web and run tools, an embeddable chat widget for your website, a developer API, and multi-user mode with admin, manager, and default roles plus per-workspace access control. Context assembly is smarter than naive RAG: pinned documents, attached files, vector search hits, and recent chat history are combined under a token budget so the model's context window is filled efficiently, and each workspace supports multiple independent conversation threads against the same knowledge base. Because the embedding model, vector store, and chat LLM are all independently swappable, you can move between providers without re-ingesting a single document. The stack is Node.js with a React frontend, MIT-licensed.
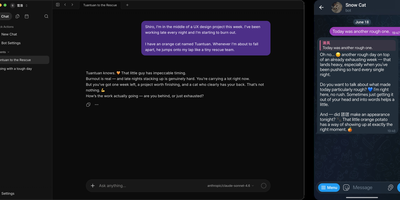
Memoh
Memoh delivers an open-source multi-agent platform where every AI agent gets its own computer — not a chat window but a fully isolated container with dedicated filesystem, desktop environment, browser, network stack, and persistent long-term memory that survives across sessions, days, and platforms. The containerd-based runtime ensures each bot operates in complete isolation with snapshot and data import/export capabilities. The memory engine uses LLM-driven fact extraction with hybrid retrieval combining dense embeddings via Qdrant, sparse vectors, and BM25, plus 24-hour context loading and automatic compaction — with Mem0 and OpenViking as drop-in alternatives. Ten communication channels connect agents to users through Telegram, Discord, Lark, QQ, Matrix, WeCom, WeChat, Email, Web UI, and group chats with cross-platform identity binding. MCP tool calling enables agents to interact with external services, while browser automation drives GUI workflows for web research and data extraction. Agent hosting supports running external coding agents like Codex and Claude Code inside Memoh workspaces via ACP with per-bot configuration. Scheduled tasks run without human triggers, and agents proactively reach out when needed. The web dashboard built with Vue 3 and Tailwind CSS provides streaming chat, tool call visualization, file management, model and provider configuration, and bot lifecycle management. Deploy via Docker Compose with PostgreSQL, Qdrant, sparse service, and the Go backend server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
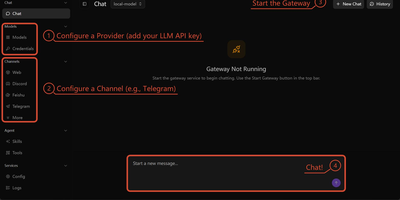
PicoClaw
An 8MB Go binary that boots in under one second, uses less than 10MB of RAM, yet delivers full AI agent capabilities across 16+ chat platforms simultaneously. PicoClaw connects to Telegram, Discord, Matrix, IRC, Slack, WeCom, DingTalk, WeChat, LINE, and QQ while supporting LLM providers spanning OpenAI, Anthropic, Gemini, DeepSeek, AWS Bedrock, Azure, and local models via Ollama. Native Model Context Protocol support enables standardized tool integration, and the built-in smart routing engine directs simple queries to lightweight models to reduce API costs while sending complex tasks to capable models. Tool capabilities include secure shell execution, filesystem access, web search, cron scheduling for recurring tasks, and sub-agent spawning with status tracking. Gateway mode transforms PicoClaw into a full AI backend with REST API endpoints accessible from any client. The Skills system loads hierarchical behavior definitions from SKILL.md files, enabling customizable agent personalities and workflows. Compiles for x86_64, ARM64, ARMv7, RISC-V, MIPS, and LoongArch, making it deployable on hardware as cheap as a $10 Sipeed LicheeRV Nano. Achieved nearly 30,000 stars within six months of its February 2026 release. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Typebot
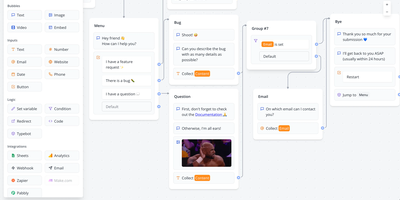
A fair-source chatbot and conversational-form builder: Typebot assembles conversations in a visual graph editor. In a visual graph editor you chain blocks from four categories: bubbles display text, images, video, audio, and embeds; inputs collect data through text fields, email, phone, buttons, picture choices, date pickers, file uploads, and Stripe payments; logic blocks handle conditional branching, variables, URL redirects, A/B testing, and custom JavaScript; integration blocks call webhooks, OpenAI, Google Sheets, Google Analytics, Meta Pixel, Zapier, Make, and Chatwoot. Build once, deploy anywhere: custom domains, WhatsApp, or embedded in any site as a container, popup, or chat bubble through a fast native JS library with no iframe and no external dependencies - plus an HTTP API for executing bots programmatically from any language. Theming covers fonts, colors, roundness, and shadows with custom CSS and reusable templates, and results arrive in real time with drop-off and completion analytics plus CSV export. Two Next.js apps (builder and viewer) self-host via Docker under the Functional Source License, which converts to Apache 2.0 after two years.
QwenPaw
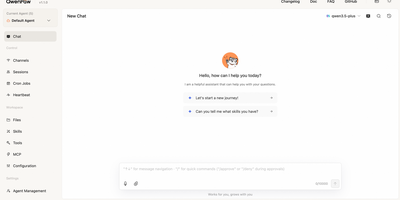
Designed as a unified personal AI workstation, QwenPaw operates as an autonomous digital copilot that coordinates scheduled automations, interactive coding sessions, and multi-channel team communication across everyday messaging apps. Users can dispatch long-running research tasks, process office documents including PDF, Excel, and Word files, and execute browser-based data collection without manual intervention. The built-in web console and terminal interface provide full visibility into agent reasoning, allowing operators to inspect intermediate thinking steps, review proposed file edits, and approve sensitive tool calls. Through direct connectors for Discord, Telegram, DingTalk, Lark, and WeChat, teams can trigger specialized skills or query shared workspaces directly from their existing group channels. A self-evolving personal memory system continuously indexes chat interactions and local resources into editable Markdown files, ensuring knowledge persists across restarts and task delegations. Built-in guardrails including a sandboxed execution runtime, tool access policies, and automated skill scanners protect underlying host files from unauthorized modifications during autonomous scripting runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Synaplan
Instead of a separate chatbot for each channel, Synaplan runs one self-hosted AI assistant for your team, website visitors, WhatsApp line, and inbox, and shows what every reply cost. In the web app, connect OpenAI, Anthropic, Gemini, Groq, Mistral, xAI, Hugging Face, or local Ollama. Each kind of work gets its own model, from chat and image to video and audio, and every answer carries a Free, Low, Mid, or High cost badge. A planner splits a big request into a task graph and sends each step to the model that fits. On your website, one script tag adds a chat widget, and a human operator can take over any conversation live. On WhatsApp Business and email, the assistant replies on the channel where the question arrived. Behind every channel sits one knowledge base: upload PDFs, Word and Excel files, or images with OCR, and semantic search feeds them into answers. Saved tasks run on demand or on a schedule, approvals pause any action that writes, and watched pages mail you a diff when a URL changes. Connections reach Microsoft 365, Dropbox, Nextcloud, ownCloud, WebDAV, CalDAV, Jira, and Confluence. An MCP server and an Anthropic-compatible endpoint let Claude, Cursor, and Claude Code use your instance. Users and groups share folders and assistants, and admins see usage and health. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Letta
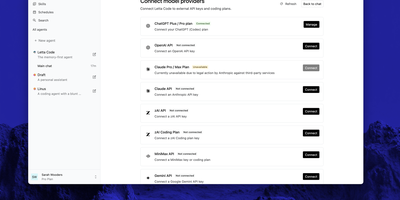
With over 24,000 GitHub stars and origins in the MemGPT research paper on virtual context management, Letta has evolved into the leading open-source platform for building AI agents that maintain persistent memory, identity, and continuity across sessions rather than operating as stateless prompt-response loops. The core architecture uses memory blocks — structured, labeled text chunks that reside permanently in the agent's context window — allowing agents to programmatically rewrite their own memory, learn new skills, and improve through a sleeptime dreaming process that runs reflection and memory organization during idle periods. The self-hosted App Server deploys via Docker and exposes a WebSocket API on port 4500, letting the TypeScript Agent SDK connect from any application using local, remote, or cloud backends. Agents support git-versioned memory through MemFS where every memory change is tracked and auditable, multi-agent communication via subagents, scheduled tasks, and integration with messaging platforms including Slack, Discord, Telegram, WhatsApp, and Signal. The platform is fully model-agnostic, routing to OpenAI, Anthropic, xAI, or self-hosted open-weight models through Ollama depending on cost, performance, and data residency requirements. The Agent File format serializes complete agent state — memory, skills, prompts, and conversation history — into portable snapshots. Desktop applications for macOS, Windows, and Linux provide native interfaces alongside the terminal CLI and web chat at chat.letta.com. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Serviette
Your documents change every day, and your RAG answers should change with them: Serviette keeps a chat and REST API continuously in sync with the files you point it at, no re-indexing jobs to remember. Point it at a local folder, Google Drive, S3 or MinIO bucket, SharePoint library, or even an FTP or WebDAV share, and edits, additions, and deletions flow into the index in real time. One YAML file, or the interactive wizard, chooses among eight vector databases, from embedded DuckDB with zero setup to pgvector, Qdrant, Milvus, Chroma, Weaviate, Pinecone, or MongoDB Atlas. Text, Office files, PDFs with tables, and scanned images are parsed and answerable by default, with audio and video joining when you add the keys. Embeddings can run fully locally with no credentials, and keyless answers simply quote the retrieved passages with their sources. The indexer and the stateless server scale independently, the server shards across workers with one config line, and both a ChatGPT-style web chat and a versioned /api/v1 retrieval API answer on the same port. A free license key from Pathway activates the engine, and benchmarks cover corpora up to 50 GB of text. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Codync
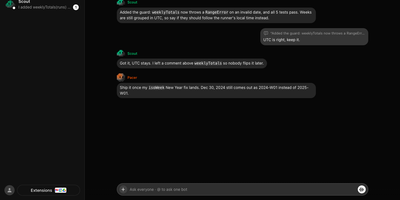
Codync turns the coding agents already installed on your computer into named bots you can message from your phone, so the Claude Code or Codex session on your desk keeps working while you are away. Each bot wraps one agent in one project folder, with its own standing instructions, memory, and approval rules, and several bots run side by side on one machine. Message any bot from the iPhone app, the desktop app, or a terminal; group rooms put bots in one thread, and an @name mention routes a question to exactly one of them. Bots ask each other for reviews inside the room and quote-reply to specific messages. File changes arrive as approval cards naming the file and computer, with Allow once, Always allow, or Deny; finished and blocked work both ping you as push notifications. The connection between phone and computer is end-to-end encrypted through a free relay, your own relay, or directly over the same Wi-Fi or Tailscale. Watch the computer's screen from your phone, hand a bot a computer-use tool, or talk to it in a voice call, and approve every new device per computer with a six-digit code. Your existing agent subscription does the work; Codync never calls a provider API with your login, and there is no paid tier. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Octop
Modern engineering teams and busy households deploy Octop to run private, autonomous AI agents equipped with persistent memory workspaces, scheduled cron jobs, and direct browser automation. Users can orchestrate specialist agents tailored for software development, IT operations, content generation, and system diagnostics through an interactive React dashboard. The platform connects directly to Discord, Feishu, DingTalk, and WeCom, allowing team members to delegate complex tasks without leaving their everyday messaging apps. An integrated remote desktop and browser control engine lets agents navigate websites, capture screenshots, fill forms, and operate graphical software autonomously. Administrators can assign distinct MBTI personality profiles to agents, establish granular role-based permissions, configure scheduled cron workflows, and integrate custom Model Context Protocol servers for external tool access. Long-term memory persists across conversations through dedicated workspace files, ensuring contextual continuity whenever switching between underlying language models or team collaborators. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Lobe Chat
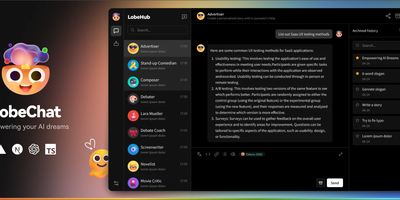
A private ChatGPT built with Next.js: Lobe Chat is the open-source AI chat interface teams self-host instead. Its main advantage is provider breadth: one interface connects to 40+ model providers, including OpenAI, Anthropic Claude, Google Gemini, Mistral, Groq, AWS Bedrock, Azure, and local models served through Ollama, so you can switch models per conversation and compare outputs. It handles multi-modal work: image recognition, image generation, text-to-speech, and speech-to-text. A plugin system based on function calling and the Model Context Protocol (MCP) adds external tools like web search and code execution. Run it in standalone mode as a single container with settings in browser storage, or in database mode with PostgreSQL and S3-compatible storage for persistent history, multi-user auth, and RAG knowledge bases built from uploaded documents with pgvector retrieval. Because tools arrive through function calling and MCP rather than a proprietary plugin format, custom internal tools can be exposed to the assistant with a standard server over STDIO or HTTP. Hundreds of pre-configured assistant roles import from the community marketplace. For teams the cost model matters: provider API keys billed per token typically undercut a ChatGPT Plus seat per person, and self-hosting keeps API keys, uploaded files, embeddings, and conversation history entirely on your own server.
Botpress
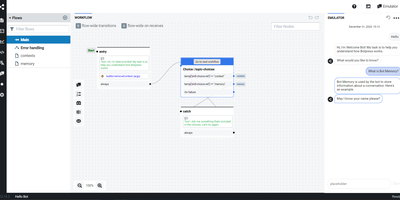
Build, deploy, and monitor chatbots and LLM-powered agents on one open-source conversational AI platform: Botpress. Its Studio is a visual development environment: a drag-and-drop canvas arranges conversation logic with nodes for messages, questions, choices, and actions, while a built-in emulator simulates conversations for debugging before anything goes live. Agents ground their answers in a knowledge base assembled from uploaded documents, ingested websites, and past conversations via retrieval-augmented generation, and the LLM layer connects to multiple model providers - GPT-4, Claude, Mistral - with a configurable model strategy. An autonomous engine handles reasoning, tool orchestration, persistent memory across sessions, and sandboxed code execution, and custom code actions in TypeScript extend agents past prebuilt workflows. Over 100 integrations deploy the same bot to WhatsApp, Telegram, Slack, Microsoft Teams, and web chat, and connect it to HubSpot, Zendesk, Zapier, and arbitrary APIs and webhooks. Human handoff, conversation analytics, and quality monitoring cover production operation. Originating in 2017 from a Montreal team, the community edition is developed openly on GitHub.
Flowise
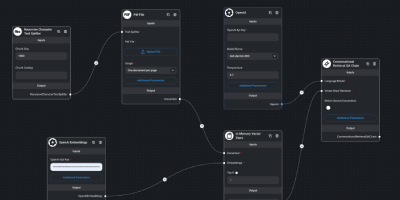
Drag nodes onto a canvas and ship an LLM app: Flowise is an open-source visual builder for AI agents and LLM applications, written in Node.js on LangChain.js and licensed Apache-2.0. You assemble flows by dragging nodes onto a canvas: models, prompts, memory, vector stores, retrievers, and tools, then wire them together and test in the built-in chat panel. Three builder types cover increasing complexity: Assistant for simple RAG chat over uploaded files, Chatflow for single-agent systems with techniques like rerankers and Graph RAG, and Agentflow for multi-agent orchestration with branching, looping, shared flow state, and human-in-the-loop checkpoints. Over 100 integrations connect data sources, vector databases, and both proprietary and open-source models, plus MCP client and server nodes for standard tool interop. Finished flows are exposed as REST APIs, embedded chat widgets, or via JS and Python SDKs - each flow gets an endpoint the moment it is saved, removing the deployment gap between a working prototype and something your application can call. Execution logs, visual step debugging, and external log streaming trace behavior, while input moderation and rate limiting act as guardrails; RBAC, SSO, and workspaces cover team deployments. Self-hosting keeps prompts, encrypted credentials, and conversation data on your own instance, which matters when flows handle internal documents or customer data - and wiring a model, prompt, memory, and vector store on the canvas replaces the boilerplate a hand-coded LangChain project would need.
Evolution API
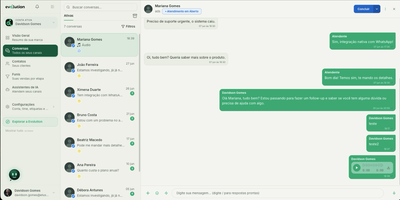
Evolution API gives your applications a production-ready REST interface to WhatsApp, supporting both free Baileys-based Web connections and Meta's official Business Cloud API from the same server. With 9,200+ stars and 7,100+ forks, it is the most widely deployed WhatsApp integration layer available. Each installation handles unlimited isolated instances (one per phone number) with independent auth, webhooks, and database separation via Prisma ORM against PostgreSQL or MySQL, cached through Redis. Message types include text, images, audio, video, documents, contacts, locations, interactive buttons, list messages, carousel cards, and PIX payment links through unified endpoints. Native integrations connect to Typebot for chatbot flows, Chatwoot for multi-agent support, Dify and OpenAI for AI conversations, N8N and Flowise for workflow automation, and RabbitMQ, Kafka, or SQS for enterprise event streaming. Socket.io delivers real-time message and connection events. Amazon S3 or MinIO handles media offloading. The Evolution Manager v2 dashboard provides visual instance creation, QR code scanning, connection monitoring, and integration configuration without touching the API directly. Docker Compose bundles the server, PostgreSQL, and Redis with environment-variable-driven setup. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
EDDI
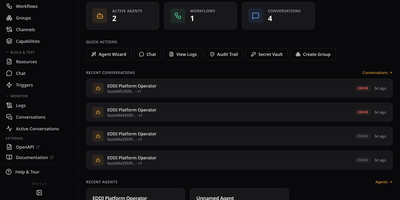
Deploy autonomous conversational AI agents and coordinate complex multi-agent workflows through EDDI, an open-source orchestration middleware that turns declarative configuration files into secure, production-grade enterprise assistants. Engineering teams connect AI models from twelve different commercial and local providers, using bilateral Model Context Protocol tools to let external desktop clients and coding assistants interact directly with running conversational services. Autonomous agents collaborate through structured group interaction patterns including round table discussions, peer reviews, Delphi consensus rounds, and devil's advocate debates to refine generated solutions before delivery. Declarative workflow extensions automate external REST API calls with dynamic request templating, extracting structured properties into persistent conversation memory and chaining multi-step service interactions without custom script glue. Built-in secret vaults safely manage sensitive API credentials, while the centralized web dashboard provides live conversation inspection, token quota enforcement, and comprehensive audit logging for regulatory compliance. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
big-AGI
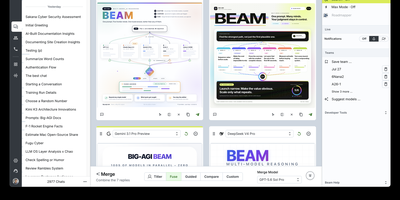
big-AGI is an open-source generative AI workspace that provides a unified, local-first interface for orchestrating multi-model reasoning, automated code execution, and custom persona workflows across private infrastructure. Users query multiple large language models simultaneously through the Beam scatter-gather engine, which prompts independent AI systems in parallel, compares candidate completions side by side, and merges optimal passages into a single refined response. Knowledge workers assemble tailored AI personas equipped with specialized system instructions, custom temperature settings, and predefined document context to handle domain-specific tasks ranging from architectural design reviews to legal contract analysis. The application renders rich multimedia outputs including interactive Mermaid sequence diagrams, LaTeX mathematical formulas, syntax-highlighted code blocks with live execution previews, and AI-generated image generation canvases. Teams integrate local inference servers like Ollama and LocalAI alongside commercial API endpoints to route confidential datasets strictly through internal networks while monitoring per-prompt token usage and operational latency. Users attach complex PDF documents, spreadsheets, and source code repositories for automatic parsing and semantic retrieval, while local-first storage engines ensure private chat transcripts and custom presets remain encrypted on host drives. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
PandaWiki
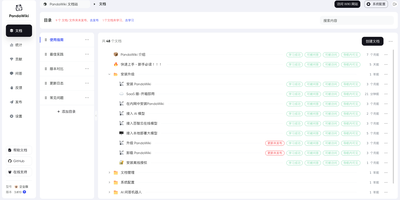
In seven wizard steps, PandaWiki sets up a product docs, manual, FAQ, or blog site whose built-in AI answers visitors using only your own content. Those visitors can chat with an assistant that cites its sources and accepts image questions, or switch to a docs-only search that lists ranked pages with summaries. Publishing stays under control: each document has three switches, visible in navigation, reachable by URL, and answerable by AI, and nothing appears or gets learned until it is published. Authors write in a Markdown and HTML editor, or import from URLs, RSS and Atom feeds, sitemaps, offline .txt, .md, .xlsx, .docx, and .pdf files, Notion, Yuque, SiYuan, Wiki.js, Feishu, Confluence, and DingTalk. Pages export to Word, PDF, or Markdown. The wizard covers models, domain, HTTP or HTTPS ports, import, publishing, answer testing, and page decoration. One knowledge base can also feed a web widget and DingTalk, Feishu, WeCom, and Discord bots. Administrators get a dashboard of visits, questions, visitor regions, hot documents, and referring domains. Chat models come from Baizhi Cloud, DeepSeek, OpenAI, or Ollama, while vector and reranking models are built in. The open-source edition covers one wiki site, 300 documents, and one admin, and its console and documentation are in Chinese. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.