n8n
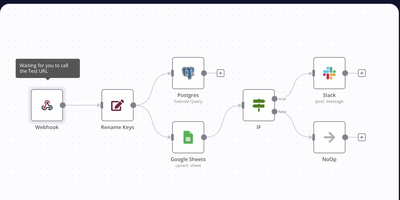
Webhooks, cron schedules, and app events trigger chains of nodes that fetch, transform, and route data: n8n is a workflow automation platform built around a visual, node-based editor. It ships with 400+ built-in integrations covering databases like Postgres, SaaS tools like Slack and HubSpot, and every major AI provider. When a pre-built node does not exist, the HTTP Request node calls any REST API, and the Code node runs JavaScript or Python inline, so you are never blocked by a missing connector. Workflows execute as directed graphs with branching, loops, error handling, and sub-workflows, and every run is logged for inspection and replay during debugging. It also includes LangChain-based nodes for building AI agents with tool calling and memory. Self-hosting on RepoCloud gives you unlimited workflow executions with no per-task pricing, and all data stays on your instance. Runs on Node.js with SQLite by default; add Postgres and Redis queue mode when you need to scale workers horizontally.
OpnForm
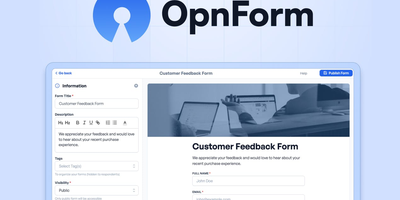
With 3,500+ GitHub stars and 100+ pre-built templates, OpnForm delivers a drag-and-drop form builder that handles everything from simple contact forms to multi-page surveys with conditional branching, calculations, and payment collection. The Laravel 11 API paired with a Nuxt 3 Vue frontend provides a responsive no-code editor supporting 20+ field types including text, date, file upload, signature capture, star ratings, phone numbers with country codes, and rich text. Conditional logic enables dynamic show/hide rules, required-field toggling, and calculated values that react to user input in real time. Submissions flow through configurable integrations — Slack notifications, Discord webhooks, Zapier connections to 5,000+ apps, Google Sheets sync, and custom webhook endpoints with full payload control. AI-powered form generation lets users describe a form in plain language and receive a ready-to-publish result. OIDC single sign-on with configurable state enforcement secures multi-user workspaces, while form-level passwords and CAPTCHA protection guard public-facing pages. Analytics dashboards track submission rates, completion times, and drop-off points. Forms embed via iframe on any website, Notion page, or custom domain with removable branding and custom CSS/JavaScript injection. The Docker Compose stack bundles the API, queue worker, scheduler, Nuxt client, PostgreSQL 16, Redis 7, and Nginx ingress proxy for a single-command deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Teable
An Airtable-style spreadsheet interface directly on PostgreSQL: Teable is an open-source no-code database where every table is a real Postgres table. Unlike tools that store records in a metadata abstraction layer, every Teable table is a real Postgres table with standard column types, so filtering, sorting, and grouping run at database speed, million-row tables answer complex filters in roughly 200 milliseconds without index tuning, and any PostgreSQL-compatible tool - psql, BI dashboards, ETL pipelines - can query the same data directly. The interface offers Grid, Kanban, Gallery, Calendar, and Form views as non-destructive overlays with their own filters and hidden fields, plus 20+ field types, formulas, comments, attachments, batch editing, undo/redo, and edit history. Collaboration is real-time with live cursors and instant sync across views, backed by Redis, and a REST API is auto-generated per table, largely compatible with Airtable API clients - alongside native SQL access for BI tools, analytics pipelines, and your own applications to JOIN and query directly, with no exports, API rate limits, or sync jobs. Global search spans all records, chart plugins handle quick visualization, and CSV and Excel import/export cover migrations. Where Airtable caps paid plans at 100K-500K rows and charges roughly $20 per user per month, a self-hosted Teable instance has neither limit: the Postgres database itself is the export if you ever leave. Built in TypeScript with NestJS, deployed via Docker with PostgreSQL and Redis, and licensed AGPL-3.0.
Supabase
With over 107,000 GitHub stars and adoption by teams at Mozilla, 1Password, Peerlist, and thousands of startups, Supabase has become the most widely deployed open-source Firebase alternative — built entirely on PostgreSQL rather than a proprietary NoSQL store. Every project provisions a dedicated Postgres database with 40+ preinstalled extensions, auto-generating REST APIs via PostgREST, GraphQL via pg_graphql, and real-time change streams via an Elixir-based WebSocket engine that supports database change listeners, user presence tracking, and arbitrary broadcast messaging. Authentication covers email and password, phone OTP, magic links, and 20+ social providers including Google, GitHub, Apple, Azure, and SAML SSO, all enforced through Postgres Row Level Security policies that run inside the database itself. S3-compatible object storage delivers files through a CDN spanning 285+ cities with on-the-fly image transformations powered by imgproxy. Edge Functions run globally distributed TypeScript on the Deno runtime with Node.js compatibility and access to over two million NPM packages. The pgvector extension stores, indexes, and queries vector embeddings for AI-powered semantic search and retrieval-augmented generation workflows. Supabase Studio provides a browser-based dashboard with a table editor, SQL editor, schema visualizer, and log explorer. Official client SDKs ship for JavaScript, Python, Flutter, Swift, Kotlin, C#, Go, and Ruby. The self-hosted Docker Compose stack runs fourteen coordinated services including Kong API gateway, Supavisor connection pooler, and Logflare analytics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Firecrawl
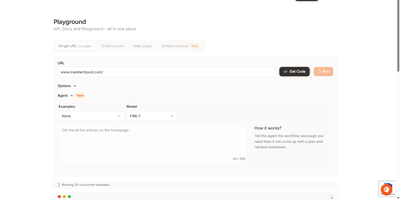
With over 164,000 GitHub stars and one of the fastest-growing open-source projects in the AI tooling ecosystem, Firecrawl is the web context API that turns any website into clean markdown, structured JSON, or screenshots optimized for large language models. The Scrape endpoint converts a single URL into LLM-ready output with approximately 67% fewer tokens than raw HTML, handling JavaScript rendering, rotating proxies, anti-bot bypasses, and dynamic content extraction with zero configuration. The Crawl endpoint recursively scrapes entire websites from a single request with configurable depth, URL filters, and concurrent page limits. The Map endpoint discovers all URLs on a domain instantly for sitemap generation. The Search endpoint performs web searches and returns full page content from results. The Interact endpoint scrapes a page then continues working with it — clicking buttons, filling forms, and extracting dynamic content using AI prompts or code. The Agent endpoint provides autonomous web data gathering where users describe what they need in plain English. SDKs are available for Python, Node.js, Go, Rust, Ruby, PHP, Java, C#/.NET, and Elixir, with an MCP server for connecting to any AI agent or MCP client. Self-hosting deploys via Docker Compose and requires Redis and a Playwright-based browser service for JavaScript rendering. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
WhoDB
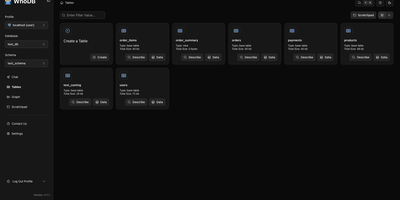
With nearly 5,000 GitHub stars earned in under two years, WhoDB has rapidly emerged as the lightweight alternative to heavyweight database clients like DBeaver and DataGrip by delivering a sub-50MB binary that starts in under a second and connects to 18+ database systems from a single interface. The Go backend serves the React and TypeScript frontend with table virtualization for efficient rendering of large result sets, lazy loading, and query result streaming that keeps the interface responsive even when browsing tables with millions of rows. The Community Edition connects to PostgreSQL, CockroachDB, YugabyteDB, MySQL, MariaDB, TiDB, SQLite, DuckDB, MongoDB, FerretDB, Redis, Valkey, Dragonfly, Elasticsearch, OpenSearch, ClickHouse, QuestDB, and Memcached through a unified credential selector that switches between databases with minimal configuration. Interactive schema diagrams render entity-relationship graphs showing table structures, foreign keys, and column types for visual database exploration. The Jupyter-style query scratchpad provides SQL autocomplete, syntax highlighting, and multi-statement execution with paginated results. AI integration optionally connects to Ollama, OpenAI, Anthropic, LM Studio, or any OpenAI-compatible provider for natural language database queries — ask questions in plain English and receive generated SQL. Data management includes inline row editing, CSV export, and filtered data views. Docker deployment runs a single container exposing port 8080. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OpenRemote
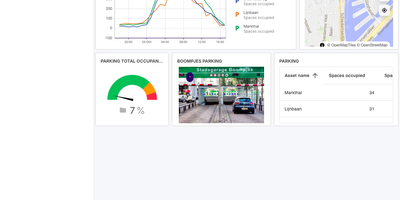
OpenRemote is an IoT platform that models every building, EV charger, solar panel, and street light as an asset in one tree, then maps, charts, and automates them from a single web dashboard. Define your own asset types, and give each attribute live readings, writable setpoints, history, and forecasts. Connect hardware with protocol agents for HTTP, MQTT, Modbus, KNX, Z-Wave, LoRaWAN, SNMP, and serial, discovering devices or importing project files where the protocol allows. Plot assets on a map with live position and heading, tint markers by attribute value, and add geofences and GeoJSON layers. Automate with When-Then rules, a drag-and-drop Flow editor, or Groovy and JavaScript rules, and run them on a schedule. Raise e-mails, push notifications, webhooks, or assignable alarms from the result. Compose shareable dashboards in Insights from nine widget types, including charts, KPIs, gauges, maps, and tables. Give each customer a realm with its own users, roles, and white-label branding. Sync edge gateways to a central instance and open them remotely through tunnels. Let devices with X.509 certificates register themselves. Read and write every attribute over REST, MQTT, or WebSocket, and let AI assistants manage assets in plain language through the MCP server. Typical projects span smart cities, building and energy management, and equipment fleets, in an interface that speaks nine languages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
MatrixOne
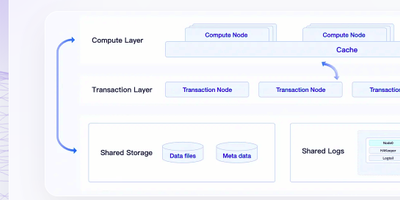
Transactions, analytics, full-text search, and vector retrieval stop needing four separate systems: MatrixOne folds them into one hyper-converged database engine that speaks the MySQL 8.0 wire protocol, so existing drivers, JDBC applications, Navicat, and BI tools connect unchanged. A single TAE storage engine serves OLTP and OLAP together, with compute and storage separated so query nodes scale independently of the data they scan. Vector columns carry IVF and HNSW indexes with L2, cosine, and inner-product distance, powering RAG and semantic search at billions scale beside your relational tables instead of in a sidecar database. Full-text indexing joins the same query, so hybrid searches combine keyword relevance and embedding similarity in one statement. Git-style version control for data lets teams clone, branch, and roll back datasets the way they already treat code, which makes experiments and audits reproducible. Streaming ingestion through Kafka connectors keeps analytical tables current, and the 4.2 line sharpens window-query performance, composite-index planning, and physical backup and restore that preserves table history. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Nuclio
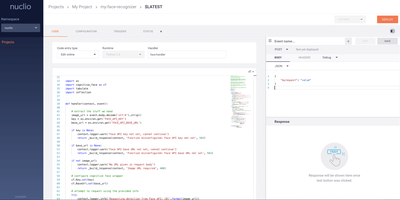
Serverless platforms promise to run your code only when it is needed; Nuclio adds the part they usually skip, raw throughput for data-heavy work, with a single function instance able to process hundreds of thousands of HTTP requests or records per second. You write functions in Python, Go, Node.js, Java, .NET, or plain Shell, and deploy them from the dashboard on port 8070, from the nuctl command line, or from Jupyter through the Nuclio SDK. Events reach your code through HTTP calls, cron schedules, Kafka and Kinesis streams, MQTT and NATS messages, RabbitMQ queues, or Azure Event Hubs, so the same function model covers APIs, stream processors, and scheduled jobs. Each function ships as its own container, built securely with Kaniko, and scales on plain Docker for a single server or on Kubernetes when the workload outgrows one machine, with GPU support for inference and media pipelines. Projects organise functions with shared configuration, secrets, and API gateways, and the dashboard shows invocations, logs, and metrics while templates for common jobs get a first function running in minutes. Data science teams plug Nuclio into MLRun and Kubeflow Pipelines to serve models and automate ML workflows without a separate serving tier. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Apache RocketMQ
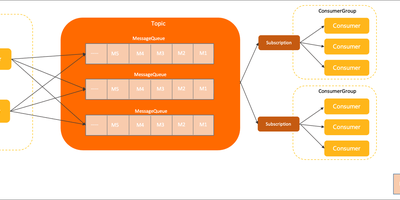
When your services need to talk without waiting on each other, Apache RocketMQ carries the conversation: a distributed messaging platform where producers publish to topics and consumers process at their own pace, with delivery guarantees you can build money movement on. Send ordinary messages for fire-and-forget events, transactional messages that commit or roll back with your local database transaction, ordered and FIFO messages for sequences that must not shuffle, and delayed messages that arrive seconds or days later on schedule. Consumers pull with long polling, filter by tag or SQL expression at the broker, and retry failures through built-in retry queues and dead letter queues instead of losing work. Clusters scale by adding brokers, while Controller mode elects broker replicas automatically so a failed node stops being a page. The Proxy component speaks gRPC with modern multi-language clients and adds POP consumption, where messages become invisible while processed and reappear if the consumer never acknowledges. Tiered storage offloads cold messages to cheaper object storage while hot data stays on local disk, and RocketMQ Streams, Connect, and an MQTT bridge extend the same cluster into stream processing, data integration, and device messaging. Lite Mode trims subscription overhead for AI workloads, and the separate RocketMQ Dashboard gives operators a web console for topics, consumers, and message tracing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Baserow
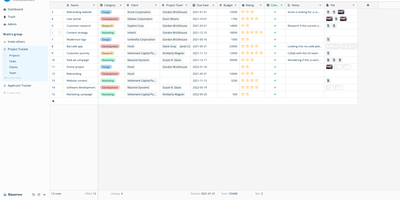
Airtable's spreadsheet-database model, self-hostable and open-source: that is Baserow. It presents data in a spreadsheet-style grid, but underneath each table is a real relational structure with typed fields, links between tables, filters, sorts, and multiple views (grid, gallery, form, kanban, calendar). Beyond the database core, it includes an application builder for composing pages and portals on your data, workflow automations, and dashboards. Everything is API-first: each table exposes a REST endpoint with token auth and webhooks, so it plugs directly into n8n, Zapier, or custom scripts. The stack is Django (Python) on the backend, Vue.js on the frontend, PostgreSQL for storage, with Redis for async tasks. Core features are MIT-licensed; premium features are a paid add-on. The self-hosted version has no row, storage, or API request limits - Airtable's per-base record caps and monthly API quotas simply don't exist here, and capacity is bounded only by your PostgreSQL database and disk. Existing Airtable bases, CSVs, and Excel files import directly with structure preserved, so migration doesn't start from a blank slate, and both the backend and frontend support plugins for custom field types and integrations without forking the core. For non-technical teammates the interface behaves like a spreadsheet; for engineers, the data model is the API.
Apache IoTDB
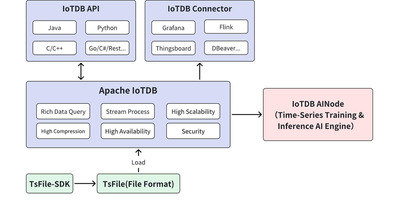
Sensors on factory floors, wind turbines, and connected vehicles produce readings every second, and Apache IoTDB is the time-series database built to store those readings and answer questions over them. Devices write through client sessions that tolerate out-of-order, delayed, and multi-frequency arrivals, so a gateway that reconnects after an outage can backfill history without corrupting the timeline. Series live in a device hierarchy you can browse like a directory tree, or in tables queried with standard SQL, common table expressions, set operations, and more than one hundred built-in aggregation and time-series functions. The TsFile columnar format shares one time column across aligned series and applies encodings designed for sensor data, which keeps high-frequency archives compact while Spark and Hadoop jobs read the same files directly for larger analysis. Pipe synchronization streams records or transfers whole TsFiles between edge sites and central clusters with path and device filtering, so plants keep collecting locally while headquarters queries a continuous copy. AINode brings forecasting, anomaly detection, and missing-value imputation into the database itself: register a model with SQL, then ask for predictions in the same query language instead of shipping measurements to a separate machine learning service. A low-memory Edge edition runs collection on constrained gateways, and clusters scale by adding DataNodes under ConfigNode coordination with automatic load balancing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Dagster
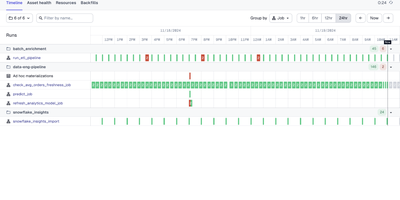
With nearly 16,000 GitHub stars, 5.7 million monthly PyPI downloads, and 400+ contributors, Dagster is the most widely adopted asset-centric data orchestration platform — replacing task-oriented schedulers like Apache Airflow with a declarative model where every pipeline is defined as Python functions producing data assets such as tables, datasets, machine learning models, and reports. The built-in asset graph provides automatic lineage tracking across your entire data platform, showing exactly how data flows from ingestion through transformation to downstream consumption in a single unified view. Declarative Automation goes beyond cron scheduling with event-driven conditions that intelligently trigger materializations based on upstream freshness, data quality signals, and dependency state. The integrated data catalog auto-generates documentation from asset metadata, ensuring it never drifts out of sync with production. Native first-class integrations connect dbt, Snowflake, BigQuery, Databricks, Fivetran, Airbyte, Spark, Great Expectations, Tableau, Power BI, AWS, GCP, and Azure without custom glue code. The web UI visualizes asset graphs, run history, schedules, sensors, and partitioned materializations with built-in alerting via Slack and PagerDuty. Dagster Pipes enables executing arbitrary code in external environments including Spark clusters, Kubernetes Jobs, and cloud functions. Deploy via Docker Compose on a single VM with separate containers for the webserver, daemon, and code locations, or use official Helm charts for production Kubernetes with K8sRunLauncher scaling each run as an independent Job. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
CyberChef
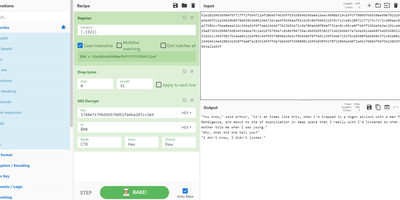
GCHQ open-sourced its "Cyber Swiss Army Knife", and CyberChef became the web app security analysts, incident responders, and CTF players reach for when data needs decoding, decrypting, or dissecting. Its interface is four panes: paste or drag input (files up to 2GB), search a categorized library of hundreds of operations, drag them into a recipe with arguments, and read the output. Operations span Base64, hex, and XOR encoding; AES, DES, and Blowfish encryption; classical ciphers from Caesar to Railfence; hashes and checksums; compression; regex and string extraction of IPs, domains, and URLs; timestamp conversion; and parsers for IPv6, X.509 certificates, and more. Recipes chain arbitrarily - convert from a hexdump then decompress, decrypt AES pulling the IV from the cipher stream, or let the Magic operation auto-detect several layers of nested encoding. Auto Bake re-runs the recipe live as input or arguments change, Step executes one operation at a time for debugging, and flow control (forks, subsections, registers) applies different operations to different parts of the data. Recipes save to files or share as URLs encoding the full pipeline. Crucially, CyberChef is entirely client-side JavaScript - nothing uploads anywhere - and self-hosting guarantees an unmodified copy inside your own network, where malware artifacts belong.
Mathesar
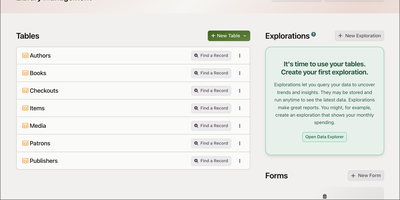
Mathesar puts a spreadsheet in front of your PostgreSQL database, letting anyone on the team browse, edit, filter, sort, and query tables without writing a line of SQL. Connect it to any existing PostgreSQL instance and immediately navigate schemas, tables, and records through an intuitive grid interface with inline editing, grouping, and summarization. The query builder joins tables across foreign key relationships, creates custom views with aggregations, and exports results to CSV. Rather than inventing its own permission layer, Mathesar maps each user or team to a native PostgreSQL role with granular schema-level and table-level privileges enforced at the database engine level, so there is never a gap between what the UI allows and what the database permits. Record summary templates display human-readable representations of linked records, making foreign key relationships immediately understandable instead of showing raw IDs. Import data from CSV files, create new tables and columns with proper PostgreSQL types including arrays, JSON, and custom domains, and modify schema structure through the web interface. Mathesar scales as well as the underlying PostgreSQL instance with no artificial limits on database size or complexity. Maintained by the Mathesar Foundation, a 501(c)(3) nonprofit, with a permanent commitment against vendor lock-in or licensing changes. Docker deployment connects to existing PostgreSQL instances or a bundled database in minutes. 5,000+ GitHub stars. GPL-3.0 licensed.
Nocobase
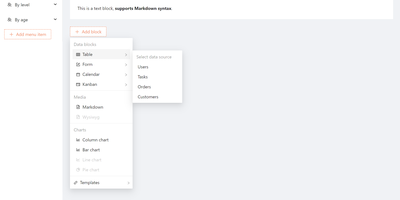
CRMs, project trackers, inventory tools - NocoBase is an open-source no-code/low-code platform for building business systems like these. Its architecture is data-model driven: you define collections and relationships first, then compose any number of interface blocks (tables, forms, kanban, charts) on top of the same model, so data structure is never coupled to a particular view. The core is a microkernel where every feature is a plugin, WordPress-style; you enable official plugins, install marketplace ones, or write your own as npm packages with server and client parts. Data sources include the main PostgreSQL or MySQL database, external databases, and third-party APIs - so you can build admin panels over existing production data instead of migrating it. Built-in infrastructure covers role-based permissions down to collection, record, and field level, workflow automation with approval steps and scheduled triggers, and audit logs; a one-click switch flips between usage and configuration modes. Because custom features live in isolated plugins with a documented lifecycle, core upgrades do not overwrite your customizations, and swapping UIs never requires data migrations since interfaces sit on independent models. Written in TypeScript on Node.js, Koa, and React under the AGPL license, it is light enough for one person to run and extend - and where no-code SaaS platforms charge per seat and per app, a self-hosted instance runs unlimited applications for unlimited users at hosting cost alone.
Mirobody
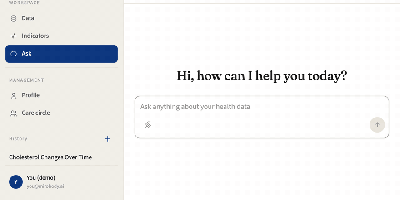
Three lab PDFs, a phone photo of a printed slip, and a spreadsheet become one cholesterol trend in Mirobody, a health data engine you host yourself, with the source file behind every number. Upload reports in 23 file types, import an Apple Health export, or connect Garmin, Oura, and Whoop, and every reading keeps a link to the page it was read from. Test names in English, Chinese, Japanese, and other languages resolve offline to LOINC codes and UCUM units, so HbA1c and Glycated Hemoglobin land on one series, and a name it cannot place stays unresolved instead of guessed. Ask questions in plain language and the agent shows each step as it works, charts the trend, and opens the reading and file behind every figure. A health journal turns one typed sentence into coded symptoms, blood pressure readings, and a medication entry, and a denied symptom like no fever is never logged. Genetic exports from 23andMe, AncestryDNA, and WeGene, or a VCF, can be queried by rsID, gene, or region. A care circle lets relatives share their own records on their own terms, and Claude Code, Codex, and Cursor can read your record through the built-in MCP endpoint. Choose OpenRouter, OpenAI, Gemini, Anthropic, or DeepSeek for answers, or keep every model on your own machine. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Google Maps Scraper
The leading open-source tool for extracting business leads from Google Maps at production scale. The Go-based engine processes approximately 120 places per minute with optimized concurrency, extracting 33+ data points per listing including business name, address, phone number, website URL, rating, review count, latitude and longitude, opening hours, price level, and optionally crawling business websites for email addresses. Three interfaces serve different workflows: the CLI accepts query files for cron jobs and CI/CD pipelines with output to CSV, JSON, PostgreSQL, S3, or LeadsDB; the Web UI provides a browser-based dashboard with real-time job monitoring, a map view of scraped places, and interactive query submission; and the REST API at /api/v1 enables programmatic integration with full Swagger documentation at /api/docs. Built-in proxy rotation supports SOCKS5, HTTP, and HTTPS with authentication for large-scale runs, while the architecture scales from a laptop to Kubernetes clusters with queue-based worker distribution. The SaaS edition adds multi-user access with API key management, admin UI with 2FA, job queue orchestration, and one-command cloud deployment via an interactive wizard. An AI Agent Skill enables coding agents to run scrapes programmatically. Deploy via Docker or build from source requiring Go 1.26.5+. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.