Mediarium
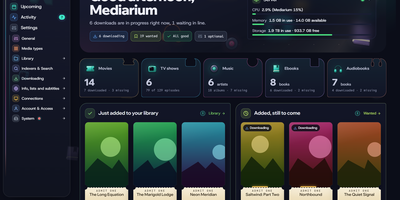
Find a title tonight and wake up to it named, filed, and ready to play: Mediarium is a self-hosted media manager that finds, downloads, repairs, and organizes movies, TV, music, ebooks, and audiobooks from one web page on your own server. Search once and it queries your Usenet and torrent indexers together, grabs the best release, unpacks it, applies your naming rules, and places it where Plex, Jellyfin, or Emby expects it. Quality profiles with upgrades and fallbacks keep hunting better copies automatically, while delay profiles, a blocklist with retries, and tags such as Kids or 4K keep the wrong releases out and collections tidy. Subtitles are matched to your exact file, with a timing fix when one runs out of sync. Family accounts carry permissions of their own: relatives who cannot add titles send requests you approve, and watch history read from your media server drives statistics and optional cleanup rules. The built-in Books app reads ebooks, plays audiobooks chapter by chapter, remembers your place everywhere, and even opens Kindle books. Torrents can run behind a built-in WireGuard VPN with a kill switch, downloads repair and unpack themselves, and notifications, backups, and a post-import script keep the routine invisible. Moving over reads your Radarr, Sonarr, Prowlarr, SABnzbd, and other existing setups without changing them. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Shelfarr
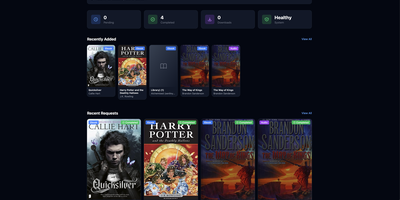
Shelfarr is the request button your book library was missing: anyone in your household can search millions of ebooks and audiobooks, request the format they want, and let automation fetch and shelve it. Discovery searches Open Library, Hardcover, and Google Books with covers, series, editions, and narrator details, so picking between the ebook and the audiobook takes a glance. Hardcover shelves and public reading lists can be previewed and requested, and following an author means their next release surfaces without a manual search. Requests wait for an admin's approval or move straight to searching, where your indexers are queried and every result is scored against your preferred formats, bitrate, and language. The winning release goes to the download client you route it to; finished files are renamed with your templates and delivered into your library's watched folders, which are told to rescan. Nothing found is not the end: searches retry with back-off and flag the request for attention instead of losing it. Family members get their own accounts with roles, two-factor authentication or single sign-on, notifications in the app or on Discord and Telegram, and admins keep manual uploads, API tokens, and download routing under their control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Stump
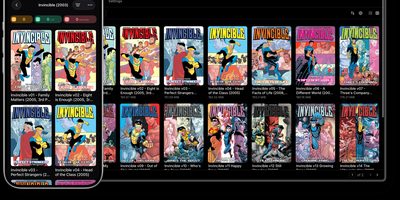
Curating digital comic archives, serialized manga, and electronic book libraries becomes effortless with Stump, a high-performance reading server that streams media collections over OPDS protocols directly to web browsers and e-reader hardware. Readers can organize extensive collections across CBZ, CBR, PDF, and EPUB formats, utilizing automated scanners that extract embedded ComicInfo XML and Calibre metadata tags. The built-in web reader renders high-resolution comic spreads, continuous vertical webtoon scrolls, and reflowable text with customizable color themes, font scaling, and reading direction toggles. Users can highlight passages, create persistent notes inside EPUB editions, and organize complex franchises into custom reading lists, oneshots, and smart filter collections. Bi-directional synchronization integrates with Kobo and KOReader hardware devices, maintaining page progression and bookmark states across handhelds and desktop sessions. Server administrators can configure multi-user access rules, enforce age restriction thresholds, and provision user-scoped API tokens for automated script pipelines and third-party companion tools. GraphQL and REST endpoints expose the entire catalog structure, allowing media collectors to integrate external metadata scrapers and trigger background library indexing tasks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Kumiho
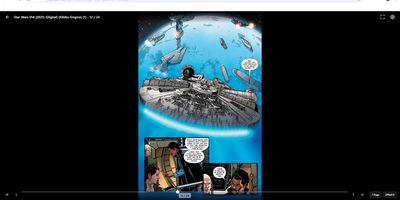
Drop a hard drive's worth of comics, e-books, and audiobooks into folders, point Kumiho at them, and the whole collection becomes a library you can browse and read from any browser. The scanner walks nested folders recursively and treats the folders that actually hold pages or files as series, so an existing collection works as it is, with no metadata matching ritual before the first read. Comics and manga open in a responsive viewer built for the format: page turning on a desktop, continuous webtoon scrolling on a phone or tablet. E-books in EPUB, PDF, and TXT open in the same library, while archives in ZIP and CBZ are read directly without unpacking. Audiobooks get a real player, with a chapter list, resume playback that remembers where you stopped, progress tracking, bookmarks, and a sleep timer for listening at night. A series folder can even carry its own soundtrack: an MP3 whose filename matches starts playing as background music while you read. Everything runs from one lightweight Go server in a single Docker container, storing its database and configuration in mounted volumes, so the library sits comfortably on a small VPS next to the files it serves. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.