Berth
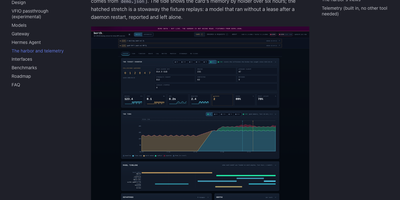
A single GPU can only hold so many models at once, and when a chat server, an image pipeline, and a voice engine all grab VRAM together, somebody runs out of memory and crashes. Berth fixes the scramble by making every engine lease the card: wrap a launch in berth run and the daemon grants memory in turn, queues the rest with an honest place in line and a start estimate, and drains a holder cleanly before the next load begins. The broker learns each engine's real footprint from its runs, so grants are sized by measured peaks instead of guesses, and processes that grab memory without a lease are reported as stowaways, never killed, with contested grants flagged in plain sight. A collisions board counts what the scheduling prevented: avoided collisions, VRAM handed off, drains, stuck releases, and refusals, and every count links back to a gap free event log you can follow live. The Harbor web UI turns that into a departures board of leases, a six hour tide of memory by holder, engine cards with decode throughput and a token ledger, plus a per model leaderboard and thirty days of stored history. Alerts reach your desktop or a webhook, Prometheus scrapes the metrics endpoint, and multi GPU machines can even pass one card through to a VM while the others keep serving. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Deploy