SubLane
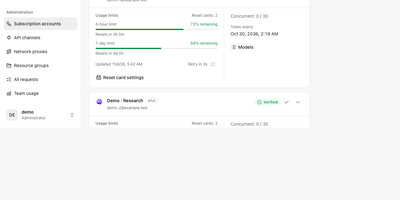
Five teammates sharing three AI subscriptions usually means a password in a group chat; SubLane replaces that with a gateway you host, where accounts are pooled and every person gets a managed key. Connect Codex, Claude, Antigravity, and Grok Build subscriptions once, by browser OAuth or credential import, and the gateway snapshots each account's quota windows and allowances so routing knows who still has room. Add API channels for OpenAI-compatible services alongside the subscriptions, then group everything into resource pools with model allowlists, conversation affinity, concurrency controls, and cooldown recovery for accounts that hit a limit. Each member receives a personal key scoped to one group, with its own expiry, rate and concurrency limits, and an allowance measured in tokens, internal dollars, or estimated quota share; keys can be paused or revoked without touching anyone else. Whatever the client speaks, the gateway answers: OpenAI Responses and Chat Completions, Claude Messages, and Gemini formats flow over HTTP, SSE, or WebSocket, independent of which subscription actually serves the request. Administrators watch per-member and per-model usage charts, activity heatmaps, and request diagnostics, bind a fixed outbound proxy to any account, and apply workspace content rules before dispatch. It all runs as one Go process with SQLite and an embedded dashboard, backed up and restored from the interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Deploy