Open Agent Builder
Open Agent Builder delivers a visual canvas for orchestrating AI agent workflows without writing Python scripts or managing complex codebases. The React Flow-powered drag-and-drop interface supports seven node types — Agent, Scraper, Transform, If/Else, Loop, User Approval, and MCP Tool — each configurable with provider-specific settings for Anthropic Claude (Haiku 4.5 and Sonnet 4.5), OpenAI GPT-5, Groq, or any OpenAI-compatible endpoint. The LangGraph orchestration engine handles state management, conditional routing, and human-in-the-loop approval gates while Firecrawl integration converts any website into structured, LLM-ready data through scrape, crawl, and map operations. E2B sandboxed code execution powers Transform nodes for secure data manipulation without risking host system integrity. Real-time streaming updates show execution progress node-by-node as workflows run, with Convex providing reactive database synchronization for workflow state and execution history. The TypeScript-first architecture (96.8% TypeScript) built on Next.js 16 App Router with Tailwind CSS delivers a responsive interface across devices. Clerk handles multi-user authentication with JWT integration for secure workspace isolation. Deploy via npm install and environment configuration with Firecrawl, Convex, and Clerk API keys. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
CyberScraper 2077
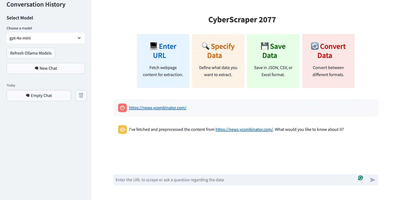
With 3,100+ GitHub stars, CyberScraper 2077 replaces brittle CSS selectors and XPath queries with natural language data extraction powered by Large Language Models. Users paste a URL, describe the data they want in plain English, and the AI extracts structured results from any website — no HTML parsing knowledge required. The tool supports three LLM backends: OpenAI GPT models for maximum accuracy, Google Gemini for cost-effective extraction, and local Ollama instances for fully private scraping where URLs and data never leave your server. Built on Python asyncio with Playwright browser automation, it handles concurrent page fetching with content-based and query-based LRU caching to minimize redundant API calls. The Streamlit web interface runs on port 8501 and provides one-click export to JSON, CSV, HTML, SQL, Excel, and direct Google Sheets upload. Tor network integration routes requests through onion routing for anonymous scraping of both clearnet and .onion hidden service sites with automatic circuit management and stream isolation. Stealth mode randomizes user agents, manages cookies, and controls JavaScript execution timing to bypass bot detection systems. Multi-page scraping navigates through paginated results with automatic URL pattern detection. Docker deployment packages all dependencies including Playwright browsers into a single container. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.