MatrixOne
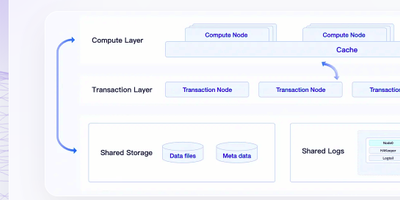
Transactions, analytics, full-text search, and vector retrieval stop needing four separate systems: MatrixOne folds them into one hyper-converged database engine that speaks the MySQL 8.0 wire protocol, so existing drivers, JDBC applications, Navicat, and BI tools connect unchanged. A single TAE storage engine serves OLTP and OLAP together, with compute and storage separated so query nodes scale independently of the data they scan. Vector columns carry IVF and HNSW indexes with L2, cosine, and inner-product distance, powering RAG and semantic search at billions scale beside your relational tables instead of in a sidecar database. Full-text indexing joins the same query, so hybrid searches combine keyword relevance and embedding similarity in one statement. Git-style version control for data lets teams clone, branch, and roll back datasets the way they already treat code, which makes experiments and audits reproducible. Streaming ingestion through Kafka connectors keeps analytical tables current, and the 4.2 line sharpens window-query performance, composite-index planning, and physical backup and restore that preserves table history. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
LightRAG
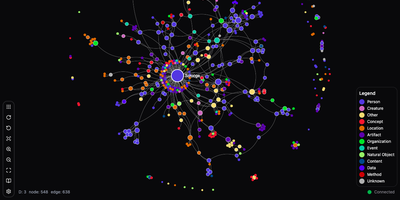
Plain chunk retrieval hands an LLM disconnected excerpts; LightRAG builds a knowledge graph from your documents so answers can join facts spread across many files. Ask about one named person, product, or clause and local mode pulls its details. Ask for themes across the whole library and global mode follows the links between entities. Hybrid blends the two, naive falls back to plain chunk search, and mix combines all three. Mix is the default. Upload text, Markdown, PDF, Word, PowerPoint, and Excel files; MinerU, Docling, or the native parser can extract images, tables, and formulas. The admin console manages documents, explores the graph visually, and debugs queries, while a query-only workspace page gives everyday colleagues a clean chat screen that works on phones. A REST API covers indexing and queries, and an Ollama-compatible endpoint lets chat front ends such as Open WebUI use the knowledge base as a model. New files merge into the existing graph without a full reindex, and deleting a document rebuilds only the entities and relationships it touched from cached results. Separate model roles let an inexpensive model extract entities while a stronger one writes answers. An API key or accounts protect the server, and named workspaces keep several knowledge bases apart. Pair it with local Ollama models and no document text leaves the server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Milvus
With over 45,000 GitHub stars and 100 million Docker pulls, Milvus is the most widely adopted open-source vector database, powering production AI systems at NVIDIA, Salesforce, eBay, Airbnb, and DoorDash. The distributed architecture separates compute and storage with stateless microservices on Kubernetes, horizontally scaling query nodes for read-heavy workloads and data nodes for write-heavy ingestion independently. Milvus 3.0 introduces lake-native retrieval that builds and serves indexes directly over vector data in object storage and open formats including Parquet, Lance, Iceberg, and Vortex without maintaining separate copies. Native hybrid search unifies lexical BM25 full-text retrieval and semantic vector search in a single engine with metadata filtering, eliminating the need for separate search infrastructure. Hardware-accelerated ANN indexing supports IVF, HNSW, DiskANN, and GPU-based indexes with BitQ 1-bit quantization cutting memory usage by 72 percent. SDKs for Python, Go, Node.js, and Java provide programmatic access, while Milvus Lite offers lightweight embedding for local development via pip install. Server-side aggregation, sorting, faceted search, StructArray for nested document structures, and ColBERT multi-vector scoring move ranking and result processing into the engine. The Path Index enables 100x faster JSON filtering with support for 100,000+ collections per cluster for multi-tenant deployments. Self-hosting deploys via Docker Standalone or Kubernetes with Helm charts using S3-compatible, GCS, or Azure Blob storage backends. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Serviette
Your documents change every day, and your RAG answers should change with them: Serviette keeps a chat and REST API continuously in sync with the files you point it at, no re-indexing jobs to remember. Point it at a local folder, Google Drive, S3 or MinIO bucket, SharePoint library, or even an FTP or WebDAV share, and edits, additions, and deletions flow into the index in real time. One YAML file, or the interactive wizard, chooses among eight vector databases, from embedded DuckDB with zero setup to pgvector, Qdrant, Milvus, Chroma, Weaviate, Pinecone, or MongoDB Atlas. Text, Office files, PDFs with tables, and scanned images are parsed and answerable by default, with audio and video joining when you add the keys. Embeddings can run fully locally with no credentials, and keyless answers simply quote the retrieved passages with their sources. The indexer and the stateless server scale independently, the server shards across workers with one config line, and both a ChatGPT-style web chat and a versioned /api/v1 retrieval API answer on the same port. A free license key from Pathway activates the engine, and benchmarks cover corpora up to 50 GB of text. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Chroma
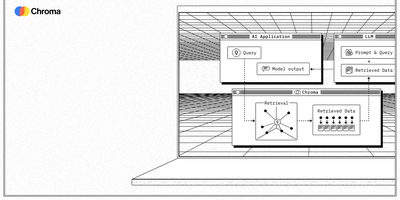
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OpenViking
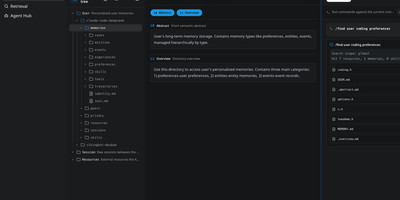
OpenViking is a self-hosted context database that gives AI agents persistent, structured memory by organizing knowledge, skills, and session history into a hierarchical virtual filesystem accessible through the viking:// URI protocol. Instead of dumping everything into a flat vector store and hoping semantic search finds the right chunks, agents navigate their context with familiar commands like ls, tree, and find, locating exactly the information they need through deterministic paths combined with semantic search. Every resource is automatically processed into three layers: a 100-token L0 abstract for quick filtering, a 2,000-token L1 overview for content navigation, and the full L2 detail loaded only when confirmed necessary. This tiered approach cuts token consumption by 83 to 96 percent compared to conventional RAG while improving task completion rates by 15 to 49 percent on benchmark tests. The built-in memory self-iteration loop automatically analyzes task execution and user feedback, updating agent memory directories so the system continuously learns and improves. You can connect to any LLM provider, including Ollama for fully local inference, OpenAI, or compatible gateways. The Web Studio UI at the /studio endpoint provides visual browsing of the entire context filesystem, and the REST API on port 1933 supports programmatic access. Deploy via Docker, Kubernetes with the included Helm chart, or as a standalone service. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
RushDB
RushDB is a database your AI agents can actually understand, because it remembers the shape of everything you write. Send nested JSON and each object becomes a record, automatically linked to its parent, while field names, types, and values are cataloged on every write. Agents introspect that catalog before querying, so they ask questions the data can answer instead of hallucinating tables that never existed. The same records answer five query styles: a JSON query language, SQL over the PostgreSQL wire protocol, Cypher over HTTP or Bolt, Gremlin, and Mongo-style document queries. Vector, full-text, and hybrid search run against the same store, so an agent can find the record that mentions a phrase and the records merely similar to it. Everything ships as one binary with one data directory, speaking HTTP on port 3000, PostgreSQL on 5432, and Bolt on 7687 to the drivers and tools you already use. Point your SDKs, SQL clients, BI tools, or local MCP-connected agents at it, and back it up, replicate it, or restore to a point in time with the engine's own tooling. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
LLemonStack
One CLI command deploys a complete AI development environment: n8n, Flowise, Supabase, Ollama, Qdrant, LiteLLM, Langfuse, Open WebUI, LightRAG, Browser-Use, Firecrawl, Crawl4AI, and more, all pre-wired with networking, credentials, and database connections. LLemonStack eliminates the hours of Docker Compose configuration that typically precede any local AI agent project. The llmn CLI initializes isolated project environments with auto-generated secure credentials, starts services in dependency order (databases first, then middleware, then apps), and displays a dashboard showing every service URL and access token. n8n brings 400+ workflow integrations, Flowise provides visual agent building, Ollama runs local LLMs like Llama and Mistral, Qdrant stores vectors at high performance, Open WebUI offers ChatGPT-style model interaction, and LiteLLM proxies requests to any provider with cost tracking. Langfuse automatically logs traces for every LiteLLM query, providing full observability. Each project maintains isolated Postgres schemas preventing data collision across parallel stacks. Firecrawl and Crawl4AI extract web content into LLM-ready formats for RAG pipelines feeding LightRAG or Qdrant. Dozzle streams live container logs for debugging. Import/export tooling migrates workflows between projects with automatic credential reconfiguration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.