Distr
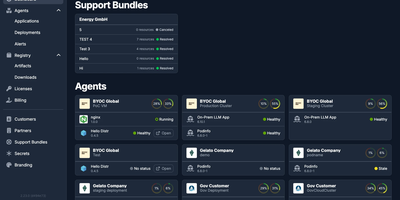
Shipping commercial software to customer-managed infrastructure demands a reliable distribution hub, and Distr provides that control plane for vendors who sell into VPCs, on-prem data centers, and air-gapped networks. Vendors define Docker Compose, Docker Swarm, or Helm applications with versions and configuration templates, then roll releases out to every customer deployment from a single vendor portal. Prebuilt deployment controllers installed in customer environments apply updates and report status, container logs, live host metrics, and alerts back, so support teams can diagnose problems without touching anyone's infrastructure. Customers get a white-labeled portal with your branding, install instructions, registry credentials, version management, and customer-initiated support bundles. A built-in OCI registry distributes Docker images, Helm charts, Zarf packages, and other artifacts with per-customer tag access, pull-through caching, and download analytics showing which customer pulls which version. Entitlements control which application versions each customer may deploy, and Ed25519-signed JWT license keys let your own software verify usage limits offline, which keeps licensing working in air-gapped sites. An OpenTofu controller provisions and reconciles BYOC cloud infrastructure, while a REST API and SDK automate onboarding, releases, and entitlements from CI pipelines. Role-based access control manages permissions across vendor and customer organizations, while the Kubernetes compatibility matrix and vulnerability scanning help validate releases before they ship. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
LocalAI
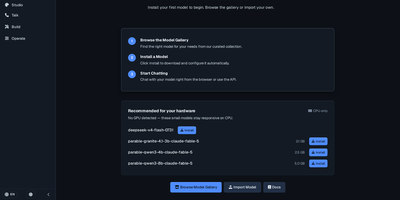
With over 48,000 GitHub stars and monthly releases since March 2023, LocalAI is the self-hosted AI engine that replaces every OpenAI endpoint with a single Docker container running on your own infrastructure — serving chat completions, image generation, text-to-speech, speech-to-text, embeddings, vision, video generation, and function calling through identical API schemas that require zero application code changes. The composable backend architecture isolates each inference engine as a separate gRPC service running in its own OCI container, so llama.cpp, vLLM, SGLang, transformers, whisper.cpp, diffusers, MLX, Stable Diffusion, and Flux install on demand without touching the core, can run on separate machines, and a fault in one never affects others. Hardware acceleration spans NVIDIA CUDA 12 and 13, AMD ROCm, Intel oneAPI/SYCL, Apple Silicon Metal, Vulkan, and NVIDIA Jetson L4T — or runs entirely on CPU without any GPU. Built-in AI agents support autonomous tool use, retrieval-augmented generation, Model Context Protocol integration, and skill-based workflows directly in the web interface. The model gallery provides curated YAML configuration files for hundreds of models that install with a single command, while P2P federated inference distributes model shards across multiple machines for running models larger than any single node's memory. Multi-user API key authentication with quotas and role-based access enables team deployments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenLLM
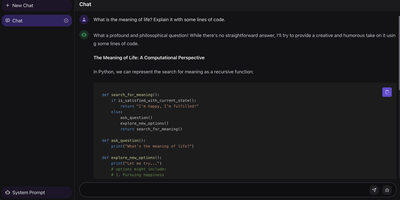
OpenLLM serves any large language model as an OpenAI-compatible API endpoint from a single CLI command, handling model download, backend selection, quantization, and port binding automatically. It supports the full spectrum of popular models including Llama 3.3, Qwen2.5, DeepSeek, Mistral, and Phi3, choosing between vLLM and PyTorch inference backends based on hardware capabilities. When vLLM is available, continuous batching with PagedAttention achieves up to 23x throughput improvement over naive serving, while GPTQ and bitsandbytes quantization reduces memory requirements for GPU-constrained deployments. The server exposes a RESTful API on port 3000 with full OpenAI client library compatibility, enabling drop-in replacement for commercial providers in any application using the standard chat completions format. A built-in web chat UI at the /chat endpoint provides immediate interactive testing without external clients. Custom model repositories allow teams to maintain private catalogs of fine-tuned models alongside the default repository that tracks the latest releases. Deployment workflows generate production-ready Docker images automatically, with Kubernetes manifest support for orchestrated scaling. Native integration with LangChain and LlamaIndex supports RAG pipelines, Transformers Agents enables tool-calling workflows, and HuggingFace Hub handles model discovery. Server-Sent Events enable real-time token streaming across all API endpoints. Backed by BentoML's production ML infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.