Argilla
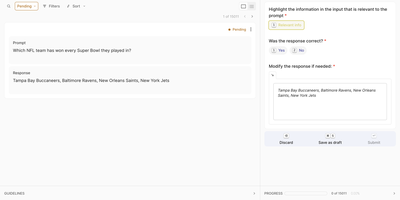
Before a language model learns from your data, someone has to label it well; Argilla gives AI engineers and domain experts a shared workspace to label, review, and refine the datasets that fine-tune language models and train NLP pipelines. You build each dataset from the Python SDK, mixing text, chat, and image fields with the exact questions your task needs: single-label classification for intent detection, span questions for named entities, ratings for response quality, rankings for preference tuning, or free text for corrections. Annotators then work through records in a focused labeling interface where model predictions already sit attached as suggestions, turning most reviews into a fast confirm-or-correct decision instead of a blank-page exercise. Full-text search, metadata filters, and status filters slice a hundred thousand records down to the ones needing attention, while vector-based semantic search finds lookalike examples, near-duplicates, and the disagreement hotspots where guidelines need sharpening. Dataset owners watch completion progress, manage who has responded to what, and split work across workspaces with owner, admin, and annotator roles for each team or client. Finished datasets export with responses, suggestions, and metadata intact, locally or straight to the Hugging Face Hub, ready for fine-tuning and evaluation runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Deploy