Apache SeaTunnel
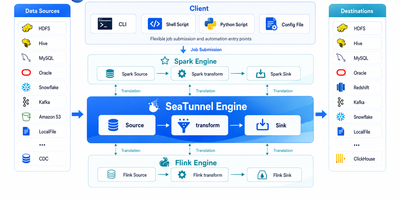
Apache SeaTunnel is a distributed integration platform that runs batch, streaming, and change-data-capture pipelines between databases, message queues, data lakes, lakehouses, and SaaS applications without hand-rolled scripts. Pipelines are declared once in a configuration file and executed on your choice of the native Zeta engine, Apache Flink, or Apache Spark, so the same job definition travels across engines without connector rewrites. Real-time CDC captures row changes from major databases with a snapshot-first handoff that never locks the source, while checkpoint-backed recovery restarts jobs from the last completed checkpoint with exactly-once semantics. When an upstream table gains a column, schema evolution propagates the change downstream automatically instead of pausing the pipeline for manual surgery. Roughly two hundred connectors cover relational databases, Kafka, object storage, search indexes, vector stores, and business apps, and the multi-table routing keeps every record on the right destination path. Engineers can dry-run configurations against sampled data before a full launch, isolate failures per table, and route bad records to dead-letter queues. Release 3.0.0 adds AI-assisted configuration generation from natural language, Python sources and transforms, and document parsing with text chunking for RAG preparation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Duckle
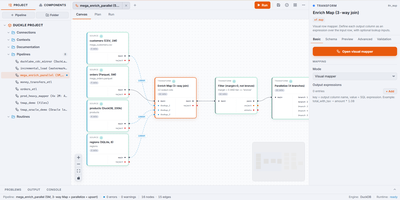
Duckle compiles visual data integration pipelines into vectorized analytical SQL executed on an embedded columnar engine, eliminating the overhead and cloud egress costs of traditional ETL infrastructure. Engineers can construct data pipelines on a drag-and-drop canvas, connecting hundreds of data sources spanning relational databases, cloud object storage, streaming event buses, vector databases, and SaaS application programming interfaces. An interactive mapping editor enables complex joins between primary data inputs and lookup streams with typed transform expressions and live sample inspections. Built-in transformation blocks execute change data capture, slowly changing dimensions, aggregation rollups, and integrated dbt models with zero row-based metering or cloud egress fees. Teams schedule headless production executions through a dedicated web console equipped with role-based access management, execution audit trails, and automated failure alerts dispatched to webhook endpoints. Embedded Model Context Protocol capabilities allow AI coding assistants to validate schema configurations, inspect execution logs, and trigger batch workflows directly through conversational commands. Workspaces store entire pipeline definitions as individual files in version control, ensuring reproducible deployments across staging and production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.