Cube
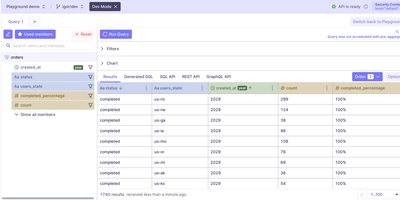
BI tools, customer-facing apps, and AI agents all receive the same governed answer from Cube Core, an open-source semantic layer where every metric is defined once, in code. Models are written in YAML or JavaScript. Cubes describe business entities with measures, dimensions, and joins. Views curate datasets for consumers. Git holds every version, with code review and CI like any other codebase. Queries arrive through a Postgres-compatible SQL API with a MEASURE function, through REST returning JSON, or through GraphQL, which means any tool that speaks Postgres connects without custom drivers. Sources include Snowflake, BigQuery, Databricks, Amazon Athena, Presto, and Postgres. Pre-aggregations declared in the model refresh in the background and live in Cube Store. An aggregate-aware planner routes matching queries to those rollups, and dashboards answer in milliseconds without rescanning the warehouse. Access policies set member-level visibility, row-level filters, and data masking from the security context. Multi-tenant SaaS analytics becomes practical: each customer sees only their own rows, whichever API asks. A development-mode Playground, meant for local use and never for public exposure, composes queries from measures and dimensions, shows the generated SQL, charts the results, and copies ready-made SQL, REST, and GraphQL calls. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
CubeJS
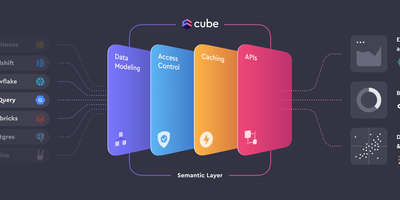
Between your databases and everything that consumes data - BI tools, embedded analytics, AI agents - sits Cube (formerly Cube.js), an open-source semantic layer. Metrics, dimensions, joins, and access rules are defined once as code in YAML, JavaScript, or Python, forming a governed data model that every downstream consumer shares, so "revenue" means the same thing in every dashboard. Caching is two-level: an in-memory cache absorbs bursts of identical queries, and declared pre-aggregations - rollup tables built in the warehouse or in Cube Store, Cube's distributed columnar engine, and refreshed in the background - deliver sub-second latency while cutting warehouse compute costs. The query planner routes each request to cache, rollup, or source automatically. Consumers connect through a Postgres-compatible SQL API (any tool that speaks Postgres works), plus REST, GraphQL, and a Meta API for model introspection. Row-level security and multi-tenancy are enforced in the layer itself, upstream of every client. Sources include Snowflake, BigQuery, Databricks, Postgres, MySQL, Presto, and Athena. Headless by design - bring your own UI.