Webclaw
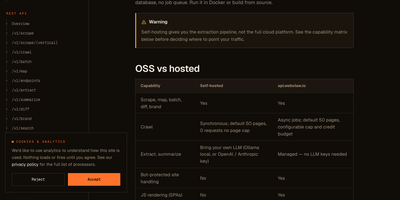
Webclaw turns messy web pages into clean content your AI tools can actually use, extracting the meaningful text and leaving the navigation, ads, and boilerplate behind. You point it at a URL and get back Markdown, plain text, structured JSON, raw HTML, or a format trimmed for language model input, with images stripped, links deduplicated, and whitespace cleaned. Crawl a whole site by following same-origin links page after page, map a domain first to discover every URL from its sitemap before deciding what to fetch, or batch many URLs at once and stream the results as they finish. CSS selectors let you include only the part of a page you care about or exclude the parts you never want, and main-content filtering keeps the article while dropping the chrome around it. Compare today's page against an earlier snapshot to see exactly what changed, or pull a site's colors, fonts, and logo into a brand profile. With your own language model connected, extraction follows a JSON schema or a plain prompt, and summaries come back at the length you ask for. Agents reach the same engine through an MCP server, scripts through the command line, and applications through the REST API. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Deploy