AudioMuse-AI
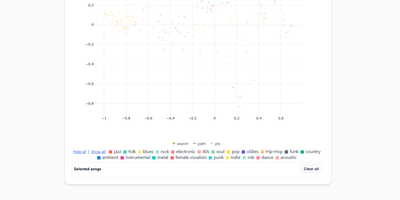
AudioMuse-AI transforms your self-hosted music collection into an intelligent sonic discovery universe that generates groove-aware playlists without relying on tag metadata or external streaming APIs. The platform scans audio files directly to extract acoustic properties, rhythmic cadence, harmonic density, and lyrical themes across seventy-two supported languages. Listeners can explore their library through a dynamic two-dimensional interactive music map, discover hidden sonic connections between distant genres, or chart smooth transitional song paths between two completely different tracks. Custom prompt-based querying lets users request niche vibes like late-night lo-fi piano, while automated clustering groups acoustically similar tracks into fresh, genre-defying collections. With Song Alchemy, curators fine-tune playlist moods by interactively adding or subtracting acoustic traits before exporting clean tracklists back to Navidrome, Jellyfin, LMS, Lyrion, Emby, or Plex. A built-in acoustic fingerprinting engine even identifies mystery tracks from twenty-second audio snippets, deduplicating songs across multi-server topologies so every file is processed only once. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
BookLore
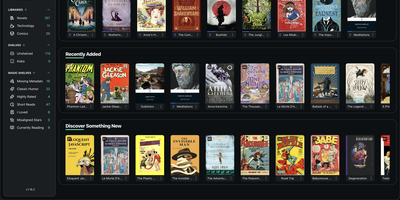
BookLore centralizes personal electronic book, audiobook, and comic collections into an organized private media server equipped with automated metadata scrapers and e-reader synchronization. Users can drop EPUB, PDF, CBZ, and MOBI files into a watched BookDrop directory to trigger automated format parsing, background cover retrieval, and staged queue imports. Integrated metadata scrapers query Google Books, Open Library, Goodreads, and Amazon to automatically fill synopsis summaries, author records, publishing dates, and review scores. Dynamic Magic Shelves categorize volumes through custom rule-based filters, author collections, and full-text search indexes across your complete literature catalog. The browser-based reader renders documents with adjustable typography, night modes, audio playback controls, text annotations, and persistent bookmarking. Hardware e-readers and mobile devices connect through native Kobo Store emulation APIs, bidirectional KOReader progress synchronization, and OPDS catalog feeds. Multi-tenant permissions provide each household member with private reading statistics, personalized shelves, email book delivery, and direct send-to-Kindle dispatch. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPLv3 licensed.
Reclip
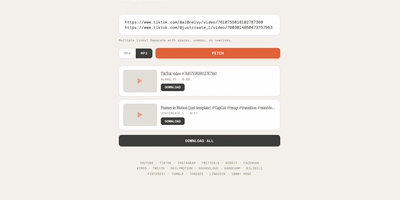
Reclip is a self-hosted web downloader that turns links from YouTube, TikTok, Instagram, and more than a thousand other video sites into MP4 or MP3 files saved on your own server. Paste one link or a whole batch of URLs, and Reclip fetches each video's title, thumbnail, duration, and uploader before you commit to anything. A quality picker lists every available resolution, so a lecture can be grabbed at 360p for a phone while a concert film comes down at full height with the best audio stream merged in. MP3 mode strips the picture away entirely, which makes it painless to archive podcasts, DJ sets, and spoken-word clips as plain audio files. Playlists expand into their individual videos automatically, repeated URLs are deduplicated before any bandwidth is spent, and a Download All button works through the whole queue without babysitting. Each job runs in a background thread with live status in the interface, so the page stays responsive while ffmpeg finishes merging streams behind the scenes. Everything lives behind one clean page with no accounts, no uploads to third-party converters, and no expiring download links, and finished files land in a downloads folder you control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Mediarium
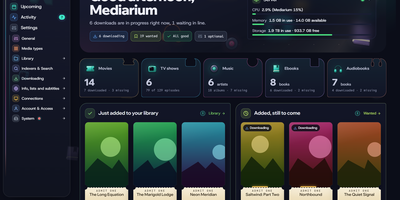
Find a title tonight and wake up to it named, filed, and ready to play: Mediarium is a self-hosted media manager that finds, downloads, repairs, and organizes movies, TV, music, ebooks, and audiobooks from one web page on your own server. Search once and it queries your Usenet and torrent indexers together, grabs the best release, unpacks it, applies your naming rules, and places it where Plex, Jellyfin, or Emby expects it. Quality profiles with upgrades and fallbacks keep hunting better copies automatically, while delay profiles, a blocklist with retries, and tags such as Kids or 4K keep the wrong releases out and collections tidy. Subtitles are matched to your exact file, with a timing fix when one runs out of sync. Family accounts carry permissions of their own: relatives who cannot add titles send requests you approve, and watch history read from your media server drives statistics and optional cleanup rules. The built-in Books app reads ebooks, plays audiobooks chapter by chapter, remembers your place everywhere, and even opens Kindle books. Torrents can run behind a built-in WireGuard VPN with a kill switch, downloads repair and unpack themselves, and notifications, backups, and a post-import script keep the routine invisible. Moving over reads your Radarr, Sonarr, Prowlarr, SABnzbd, and other existing setups without changing them. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Universal Media Server
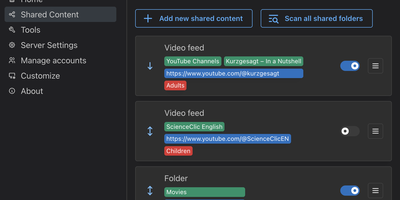
Every screen in the house (browser, TV, game console, or phone) can open the same library of videos, music, and photos once Universal Media Server shares it, with transcoding handled automatically for whichever device asks. A file the device can already play passes through untouched. Anything else is converted on the fly to suit the network, the device, and the preferred language. Folders open at once, with no wait for library scans, and disc drives and disc images play directly. In the web interface, every title gets a page with cover art, cast, and genre details from TMDB, Discogs, and MusicBrainz, and filters narrow the library by actor, director, genre, year, or artist. YouTube channels, online radio, podcasts, and RSS feeds appear beside local files on every connected device. Users and groups, with optional avatars and four-digit PINs, decide which shared folders each person sees; content for children stays apart from the library for adults. A list of detected renderers shows every connected device, and the configuration file of each device can be edited to fix browsing, playback, or transcoding on an unsupported TV. Builds exist for Windows, Linux, and macOS, with AppImage and Docker options for servers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-2.0 licensed.
Bragibooks
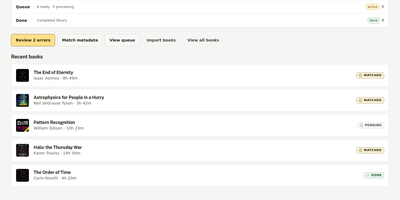
A folder of loose audiobook chapters goes in; a single, perfectly tagged m4b library comes out. Bragibooks is the operations board for that transformation: you select a batch of audiobook folders from your server, and it searches AudiobookDB to match each one with the right title, author, narrator, and release, with a custom search on hand when the first match is wrong. Confirmed books enter a processing queue where m4b-merge merges split mp3, m4a, and m4b parts, converts formats, strips stale metadata, and writes clean, consistently tagged files while you watch the live job output in your browser. Saved output profiles let you route different batches to different directories or path formats, and the books library keeps every finished title with its metadata, files, and processing history a click away. The whole thing runs as one container with the interface built in, a SQLite database on a mounted config volume, and access restricted to your local network by default, with an optional API key for external tools. Audiobook collectors use it to tame download folders before importing into their player of choice, and hoarders of split-chapter rips finally get uniform Chapter 01 style files. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Feishin
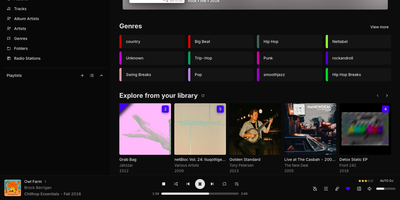
A streaming-style music player for your own Navidrome, Jellyfin, or OpenSubsonic server, on the desktop or in a browser. Home leads with a featured carousel, genre shortcuts, most played, and newly added releases. Browse by album, artist, genre, folder, or radio station. Queue, lyrics, and visualizer panels can each sit in the player sidebar. Japanese lyrics can show furigana and romaji. Star ratings, favorite hearts, and scrobbling to your server come built in. Shape the sound with a parametric equalizer, a compressor, ReplayGain, and optional transcoding. Auto DJ tops up a dwindling queue with songs or whole albums. Navidrome smart playlists get a visual rule editor with match-all or match-any groups. Choose from 32 built-in themes and 39 interface languages. The catch: Feishin is only the player, so the music server stays separate. In a browser it plays through the web player backend, while the desktop app adds MPV and built-in lyrics fetching. Docker environment variables can preset and lock the server, so guests only type a username and password. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
AzuraCast
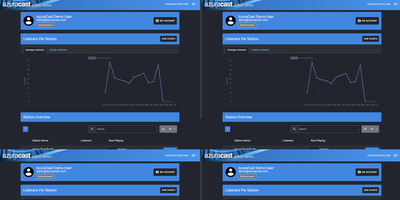
AzuraCast is a solution for running internet radio stations, packaging the entire broadcast stack into a single Docker installation that gets you on air in minutes. Built on PHP with a Vue.js frontend, it uses Liquidsoap as the AutoDJ engine to compile media from playlists, live DJ inputs, and scheduled programming into composited output streams, then broadcasts via Icecast-KH, SHOUTcast 2 DNAS, or Rocket Streaming Audio Server to thousands of concurrent listeners. The media library supports drag-and-drop uploads with automatic metadata extraction, while playlist management handles sequential, random, weighted, and time-scheduled rotations. Live DJ accounts let remote broadcasters connect via BUTT, Mixxx, or any Icecast-compatible software, with automatic crossfade transitions between AutoDJ and live input. The built-in Web DJ tool enables broadcasting directly from the browser without additional software. Each station includes public-facing player pages with now-playing metadata, album art, song history, and embeddable widgets for external websites. The listener request system lets audiences queue songs through the public interface. Multi-station administration hosts unlimited stations on a single server with individual user accounts and granular role-based permissions. Comprehensive analytics track listener counts, geographic distribution, unique listeners, and listening duration with exportable reports. HLS streaming delivers adaptive bitrate broadcasts for mobile compatibility. LADSPA audio plugins enable professional equalization and processing in the stream pipeline. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Chatterbox TTS
With 26,000 GitHub stars and consistent victories over ElevenLabs in blind evaluations, Chatterbox delivers state-of-the-art text-to-speech with zero-shot voice cloning requiring only 5 seconds of reference audio. The model family spans three architectures: Chatterbox Multilingual V3 (500M parameters, 23+ languages including Arabic, Chinese, Japanese, Korean, Hindi, French, German, Spanish, and Portuguese), Chatterbox-Turbo (350M parameters optimized for voice agents with a single-step distilled decoder achieving ~200ms time-to-first-speech), and Chatterbox-Nano (110M parameters running 3x faster than realtime on 8 CPU cores for edge deployment). Unique among open-source TTS systems, Chatterbox introduces emotion exaggeration control — adjusting intensity from monotone to dramatically expressive via a single parameter — and native paralinguistic tagging where tokens like [laugh], [cough], [chuckle], and [gasp] inject natural vocal reactions inline without post-processing. The alignment-informed inference pipeline eliminates hallucinations and repetition artifacts common in autoregressive TTS. Built-in PerTh neural watermarking embeds imperceptible forensic identifiers in generated audio for provenance tracking. Trained on 500,000 hours of cleaned speech data across all supported languages. Voice conversion scripts enable transforming existing audio into any cloned voice. Deploy via pip install with PyTorch, serve through Gradio interfaces or custom FastAPI endpoints, and expose via HTTP streaming or WebSocket for sub-200ms conversational applications. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
multi-scrobbler
Listening to music across Spotify on your commute, Jellyfin at your desk, and Sonos in the living room usually leaves your play history fragmented across walled gardens, which is why multi-scrobbler unifies over 30 music sources and routes every track to your chosen scrobble backends automatically. Instead of relying on brittle browser plugins per device, you configure active polling or ingress webhooks once for sources including Plex, Navidrome, Subsonic, Apple Music, Deezer, YouTube Music, MPD, VLC, Chromecast, and Music Assistant. Every detected play passes through an intelligent pipeline that verifies listen duration thresholds, cleans messy track titles or featured artist tags using regex rules, and enriches missing metadata against the MusicBrainz, Spotify, or Rocksky catalogs. Before forwarding a play to Last.fm, ListenBrainz, Libre.fm, Maloja, Koito, teal.fm, Discord Now Playing, or Tuneshine, the engine checks temporal and title similarity scores to block duplicate scrobbles. When a downstream service goes offline, failed scrobbles enter a persistent retry queue so you never lose listening history, while Gotify, Ntfy, and Apprise webhooks alert you to source issues. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Shelfarr
Shelfarr is the request button your book library was missing: anyone in your household can search millions of ebooks and audiobooks, request the format they want, and let automation fetch and shelve it. Discovery searches Open Library, Hardcover, and Google Books with covers, series, editions, and narrator details, so picking between the ebook and the audiobook takes a glance. Hardcover shelves and public reading lists can be previewed and requested, and following an author means their next release surfaces without a manual search. Requests wait for an admin's approval or move straight to searching, where your indexers are queried and every result is scored against your preferred formats, bitrate, and language. The winning release goes to the download client you route it to; finished files are renamed with your templates and delivered into your library's watched folders, which are told to rescan. Nothing found is not the end: searches retry with back-off and flag the request for attention instead of losing it. Family members get their own accounts with roles, two-factor authentication or single sign-on, notifications in the app or on Discord and Telegram, and admins keep manual uploads, API tokens, and download routing under their control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Tagr
When a music library is full of wrong tags, missing covers, and blank ratings, Tagr lets you fix the whole collection from any browser, on desktop or phone. Three roles divide the work on your own server. Admins mount a music folder, press scan, and get a searchable table of every track, with sortable and filterable columns, more than 40 editable fields, and room for custom tags. Taggers make the changes: edit fields inline, swap album art, and match one song or a whole selection against MusicBrainz, ticking which fields to overwrite. Mistakes are cheap, because every edit is stored in a persistent change history with a revert action, viewable per song or per folder. Rule-based smart playlists, such as every track with an empty comment, show what still needs attention. Listeners browse and play without edit rights, using the waveform player, a Recently played view, and optional ListenBrainz scrobbling that each person connects to their own account. Supported formats include MP3, FLAC, WAV, AAC, OGG, M4A, M4B, WMA, AIFF, and Opus, with changes written straight back into the files. Swipe-friendly panels, an installable PWA, and five interface languages make the phone a comfortable place to work. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
BookOrbit
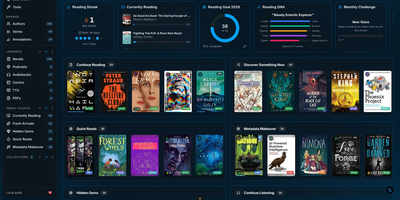
Consolidate your entire digital library into a self-hosted reading sanctuary with BookOrbit, an open-source media platform that organizes ebooks, audiobooks, comic archives, and research PDFs within a personal private cloud. Readers can enjoy multi-format media directly through responsive browser readers that support EPUB, CBZ, and M4B formats without external browser extensions. The platform synchronizes reading bookmarks, highlights, and completion statuses across web interfaces, Kobo ereaders, and KOReader devices. An automated metadata enrichment engine queries fourteen upstream bibliographic indexes, downloading cover artwork, chapter breakdowns, author biographies, and series taxonomies. The staging workspace allows librarians to inspect incoming files, review suggested metadata revisions, and embed updated tags directly into physical storage archives before shelving. Custom reading dashboards track annual book goals, calculate daily streaks, and plot reading habit radar charts. Multi-user configurations support distinct per-user collections, granular content permissions, and single sign-on authentication through OpenID Connect providers. Power users can export private OPDS feeds to external mobile reading applications or push books directly to connected Kindle hardware. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPL v3.0 licensed.
Navidrome
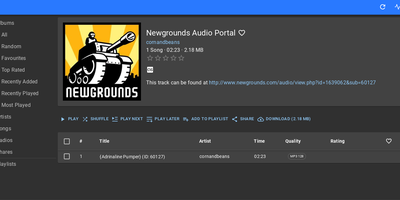
Spotify economics without the subscription or catalog gaps: Navidrome, the reference self-hosted music server, streams your own FLAC, MP3, and ALAC collection from a single Go binary with a React/Material UI web player. Its Subsonic/OpenSubsonic API compatibility is the superpower: 50+ existing clients work out of the box, from Symfonium and DSub on Android to Feishin and Sonixd on desktop, plus Android Auto, CarPlay, and Android TV apps. Transcoding is server-managed and FFmpeg-backed - FLAC direct-plays at home and downsamples to MP3, AAC, or Opus over mobile bandwidth, with the OpenSubsonic transcoding extension letting clients declare capabilities and receive per-track direct-play or transcode decisions automatically. Multi-user support gives every account its own play counts, favorites, ratings, and playlists, and multi-library support scopes different collections to different users. The feature list covers serious listening: Last.fm and ListenBrainz scrobbling, artist bios and images, embedded and external lyrics, audiobook bookmarks, saved play queues that resume on another device, internet radio, jukebox mode, and M3U playlist auto-import kept in sync with your folder. Resource usage is famously low - it runs happily on a Raspberry Pi and scales to six-figure track counts.
PodFetch
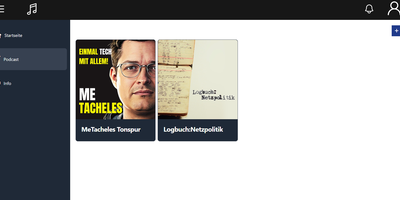
Podcast enthusiasts and homelab archivers automate digital episode preservation and stream personal audio feeds using PodFetch, an open-source self-hosted podcast manager that combines scheduled RSS downloads, Podcasting 2.0 transcript indexing, and browser playback into a modern listening platform. Listeners can subscribe to international podcast channels through direct feed URLs, Apple Podcasts directory searches, or bulk OPML subscription imports, configuring background polling timers to download new releases automatically upon publication. The integrated audio player supports variable speed playback, episode bookmarks, listening histories, and fullscreen visualization modes directly inside responsive desktop and mobile browser sessions. Advanced search capabilities leverage Podcasting 2.0 synchronized transcripts and automated speech-to-text generation via OpenAI-compatible Whisper APIs, allowing collectors to run full-text keyword searches across every spoken phrase in their audio archive. Built-in GPodder API synchronization maintains subscription lists and playback positions across popular smartphone apps like AntennaPod and native companion clients without relying on commercial cloud accounts. Server operators can assign multi-user accounts with private favorites lists, export customized RSS aggregation streams, and route storage paths between fast solid-state drives and large secondary mechanical hard disks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
ScribeCrate
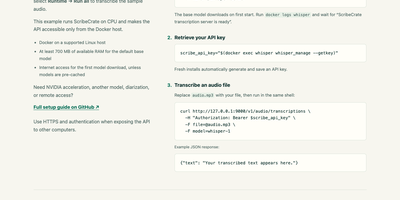
ScribeCrate is a self-hosted speech-to-text API that turns recordings into transcripts, subtitles, and English translations on your own server. It speaks the OpenAI Whisper API fluently: point any compatible client at your server's address, swap in your API key, and uploads come back as text. Ask for plain text, JSON with timestamps, or ready-to-publish SRT and WebVTT subtitle files, and for long recordings the segments can stream back over SSE as they are decoded. Turn on speaker diarization and every segment is labeled with who is speaking, which makes interview and meeting transcripts readable at a glance. Choose the model that fits the job, from tiny for quick drafts to large-v3 for maximum accuracy, and run it on a modest CPU, a Raspberry Pi class ARM board, or an NVIDIA GPU. Almost any recording works: MP3, M4A, WAV, WebM, OGG, and FLAC are all accepted, and with models cached in advance the server keeps transcribing with no internet connection at all. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Kokoro FastAPI
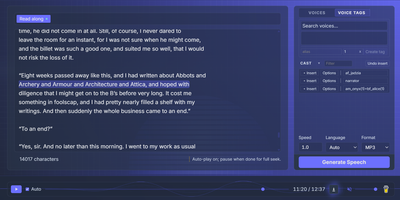
Kokoro-FastAPI turns text into natural-sounding speech across eight languages by serving the 82-million-parameter Kokoro-82M model through an OpenAI-compatible REST API, so any existing OpenAI SDK client can generate audio by just changing the base URL. With over 5,300 GitHub stars since December 2024, the fully Dockerized FastAPI server covers American English, British English, Spanish, French, Hindi, Italian, Japanese, Brazilian Portuguese, and Mandarin Chinese with language-specific phoneme processing. Inline voice mixing blends multiple profiles using weighted ratios like af_bella(2)+af_heart(1), automatically normalizing weights and caching combined voicepacks as PyTorch tensor files for reuse. Audio streams in real time over HTTP with configurable chunk sizes, or generates complete files in MP3, WAV, OPUS, FLAC, AAC, or PCM formats with speed control from 0.25x to 4.0x. Per-word timestamped captions with speaker-tagged voice labels enable subtitle generation for podcasts, audiobooks, and accessibility workflows. Pre-built Docker images support NVIDIA GPU acceleration via CUDA, experimental AMD GPU inference via ROCm, and CPU-only deployment on linux/amd64 and linux/arm64 architectures, with Apple Silicon MPS support available through direct UV execution. The integrated web interface at port 8880 provides browser-based speech generation, while the Swagger UI at /docs exposes the full API reference. Debug endpoints report system statistics for monitoring inference load. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Mstream
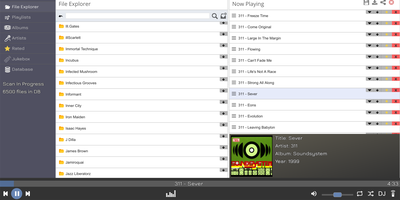
"The easiest music streaming server available" is mStream's own billing, and the claim holds up: a lightweight Node.js app that turns a folder of audio files into a private streaming service in minutes, no external database required. Its filesystem-based design is the clever part - the API mirrors your folder structure, so you can browse and play music immediately, before any library scan finishes, and your organization on disk is your organization in the app. It streams flac, mp3, wav, ogg, opus, aac, and m4a, which matters to the audiophile crowd: FLAC plays uncompressed, bit-perfect, with gapless playback for live albums and continuous mixes. The web player runs anywhere a browser does and packs personality - a Milkdrop-style visualizer (Butterchurn), playlist sharing via links, and drag-and-drop uploads straight through the file explorer. Native iOS and Android apps add the feature streaming subscriptions can't match: sync your collection to your phone for true offline playback of music you own. Multi-user support assigns separate directories and permissions per account. Resource usage is famously light - mStream is tested on multi-terabyte libraries and runs happily on a Raspberry Pi, so a small RepoCloud instance serves a lifetime's collection. GPL-licensed, with zero listening-habit telemetry.