Teable
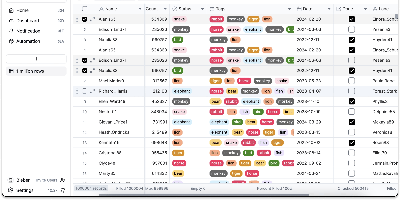
An Airtable-style spreadsheet interface directly on PostgreSQL: Teable is an open-source no-code database where every table is a real Postgres table. Unlike tools that store records in a metadata abstraction layer, every Teable table is a real Postgres table with standard column types, so filtering, sorting, and grouping run at database speed, million-row tables answer complex filters in roughly 200 milliseconds without index tuning, and any PostgreSQL-compatible tool - psql, BI dashboards, ETL pipelines - can query the same data directly. The interface offers Grid, Kanban, Gallery, Calendar, and Form views as non-destructive overlays with their own filters and hidden fields, plus 20+ field types, formulas, comments, attachments, batch editing, undo/redo, and edit history. Collaboration is real-time with live cursors and instant sync across views, backed by Redis, and a REST API is auto-generated per table, largely compatible with Airtable API clients - alongside native SQL access for BI tools, analytics pipelines, and your own applications to JOIN and query directly, with no exports, API rate limits, or sync jobs. Global search spans all records, chart plugins handle quick visualization, and CSV and Excel import/export cover migrations. Where Airtable caps paid plans at 100K-500K rows and charges roughly $20 per user per month, a self-hosted Teable instance has neither limit: the Postgres database itself is the export if you ever leave. Built in TypeScript with NestJS, deployed via Docker with PostgreSQL and Redis, and licensed AGPL-3.0.
Mathesar
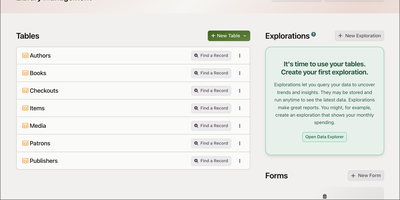
Mathesar puts a spreadsheet in front of your PostgreSQL database, letting anyone on the team browse, edit, filter, sort, and query tables without writing a line of SQL. Connect it to any existing PostgreSQL instance and immediately navigate schemas, tables, and records through an intuitive grid interface with inline editing, grouping, and summarization. The query builder joins tables across foreign key relationships, creates custom views with aggregations, and exports results to CSV. Rather than inventing its own permission layer, Mathesar maps each user or team to a native PostgreSQL role with granular schema-level and table-level privileges enforced at the database engine level, so there is never a gap between what the UI allows and what the database permits. Record summary templates display human-readable representations of linked records, making foreign key relationships immediately understandable instead of showing raw IDs. Import data from CSV files, create new tables and columns with proper PostgreSQL types including arrays, JSON, and custom domains, and modify schema structure through the web interface. Mathesar scales as well as the underlying PostgreSQL instance with no artificial limits on database size or complexity. Maintained by the Mathesar Foundation, a 501(c)(3) nonprofit, with a permanent commitment against vendor lock-in or licensing changes. Docker deployment connects to existing PostgreSQL instances or a bundled database in minutes. 5,000+ GitHub stars. GPL-3.0 licensed.
DbGate
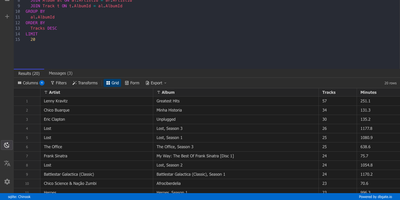
One browser tab can hold every database you manage, from MySQL and PostgreSQL to MongoDB and Redis, so there is no separate client to install for each engine. Connections are unlimited, and each can use its own SSH tunnel or SSL certificates. Tables open in an Excel-like grid where you edit cells inline, filter rows with expressions, and sort by any column. The SQL editor offers schema-aware code completion, a formatter, a join helper that builds clauses from foreign keys, query parameters, and a history of past runs, while result sets appear in separate tabs that you can filter, sort, and export. ER diagrams chart tables and their relations. The table editor creates columns, keys, and indexes and previews the SQL before anything is applied. Import and export move data between databases and files as SQL, CSV, JSON, XML, NDJSON, Excel, DBF, or YAML. Administrators can preconfigure connections through environment variables, mark them read-only, and protect the interface with logins that carry per-user permissions. Light and dark themes, customizable keyboard shortcuts, and translations into many languages keep daily work comfortable. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Tabularis
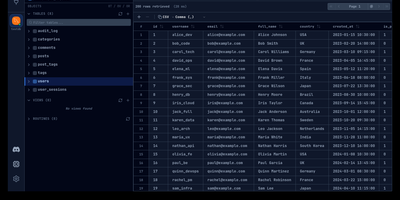
Instead of installing a different client for every database engine on your servers, Tabularis gives you one SQL workspace in the browser that speaks to PostgreSQL, MySQL, MariaDB, and SQLite directly, and to 26 more engines through installable driver plugins. The SQL editor autocompletes real table and column names as you type, runs multi-statement batches into separate result tabs, and can draw any result set as a bar or line chart. Notebooks mix executable SQL cells with Markdown and charts, sharing variables across cells for repeatable reports and investigations. You can edit rows inline in a virtualized grid that tracks pending changes before committing, build queries by dragging tables onto a canvas that writes the SQL for you, and generate an ER diagram from the live schema to see how everything connects. Natural-language prompts turn into SQL through OpenAI, Anthropic, Ollama, or any compatible endpoint you configure. Results export to CSV, JSON, or Markdown, whole databases dump to SQL files, and scheduled daily backups keep copies without manual effort. Connections reach databases through SSH or Kubernetes tunnels, and the built-in MCP server lets agents like Claude and Cursor inspect schemas and run queries under your control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
NocoDB
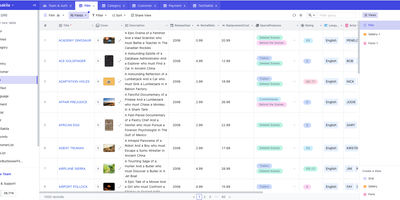
Any existing relational database becomes a collaborative, Airtable-style smart spreadsheet under NocoDB. It connects to PostgreSQL, MySQL, MariaDB, SQL Server, or SQLite, introspects the schema - tables, relationships, indexes - and renders it as interactive Grid, Gallery, Kanban, Calendar, and Form views without migrating a single row. Your business data stays in your database; NocoDB keeps only its own metadata (view configs, permissions, webhooks) in a separate store. Every connected table automatically gets REST APIs with Swagger documentation, effectively turning legacy databases into modern backends. The spreadsheet layer adds 20+ field types including formulas, lookups, rollups, links, attachments, and currency, plus sorting, filtering, grouping, and multi-field editing. Views can be locked or shared publicly with password protection, role-based access control scopes permissions per user, and webhooks plus CSV, Excel, and Airtable import round out integration. An ERD view visualizes the schema. Built with Node.js and Vue, deployed via Docker, handling millions of rows.
CockroachDB
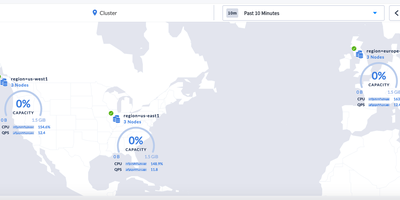
With over 32,000 GitHub stars and adoption by DoorDash, Netflix, and Bose, CockroachDB is the distributed SQL database designed to survive disk failures, machine outages, rack losses, and entire datacenter failures while maintaining strongly-consistent ACID transactions with serializable isolation by default. The architecture layers SQL on a transactional key-value store using the Raft consensus protocol for synchronous replication, automatically splitting data into ranges that distribute and rebalance without manual sharding. PostgreSQL wire protocol compatibility means existing drivers, ORMs, and tools including psycopg2, pgx, ActiveRecord, Django ORM, GORM, Hibernate, and Prisma work without modification. Multi-region capabilities include configurable survival goals at region or zone level, table-level locality settings for pinning data to specific geographies for GDPR compliance, and follower reads for low-latency global queries. The built-in DB Console provides cluster overview dashboards, node maps showing geographical distribution, SQL activity pages tracking statement fingerprints, transaction latency percentiles, session details, and real-time metrics for queries per second, storage capacity, and replication status. Change data capture streams row-level changes to Apache Kafka, Google Cloud Pub/Sub, or webhook endpoints for event-driven architectures. Online schema changes execute ALTER TABLE without locking or downtime, and distributed backup supports full and incremental snapshots to S3, GCS, Azure Blob, and NFS. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. CockroachDB Software License (source-available).
eLabFTW
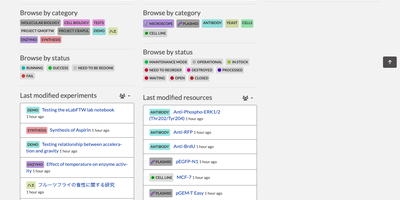
For research teams that need to show what was recorded and when, eLabFTW® is an electronic lab notebook that keeps experiments, lab inventory, and equipment bookings in one shared, searchable system. Each experiment holds rich-text notes, tables, images, checkable steps, custom metadata fields, tags, statuses, and attached files. Templates turn a protocol you repeat into a one-click starting point. A separate resource database catalogs antibodies, plasmids, cell lines, chemicals, and instruments, and typing # in an experiment links straight to any of them. Compounds import from PubChem by CID or CAS number, arriving with formulas, identifiers, and hazard data. The inventory tree maps buildings and their sub-locations, records where each container is stored, and tracks quantity and unit. Book a microscope by dragging a slot on the scheduler, and permissions decide who may reserve what. Entries can be signed with Ed25519 keys and timestamped through RFC 3161 authorities such as DFN, Digicert, and GlobalSign, or anchored on the Bloxberg blockchain; a timestamp archive can never be edited or deleted. Export to PDF, ZIP, CSV, JSON, or .eln archives, and import .eln or CSV files when moving from spreadsheets or another notebook. Users sign in locally or through SAML2 or LDAP, and an API with per-user keys lets instruments and scripts read and write entries. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Grist
With over 11,200 GitHub stars and adoption by France's sovereign digital workspace LaSuite serving 20,000+ government users, Grist is the relational spreadsheet that ends the false choice between fragile Excel files and expensive custom database development — storing all data in portable SQLite files while providing true relational structure where VLOOKUPs become actual linked records that update instantly across entire documents. Python-powered formulas replace complex Excel syntax with clear, readable logic using the full Python standard library, while familiar Excel functions remain available for users who prefer them. Granular access rules control permissions at row, column, table, and cell levels — not just entire sheets — enabling multi-department documents where each team sees only their authorized data. The flexible layout system combines spreadsheets, card views, charts, calendars, and custom widgets on configurable dashboard pages that transform raw data into operational interfaces. Real-time collaboration lets multiple users edit simultaneously with automatic snapshot history capturing every change for full audit trails and point-in-time recovery. AI formula assistance connects to OpenAI, Llama, or any OpenAI-compatible endpoint via OpenRouter to generate formulas from natural language descriptions. The REST API and webhooks enable integration with n8n, Zapier, and custom automation, while incremental imports keep external data sources synchronized. Deployable via Docker with OIDC, SAML, and SCIM authentication support. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
DSpace
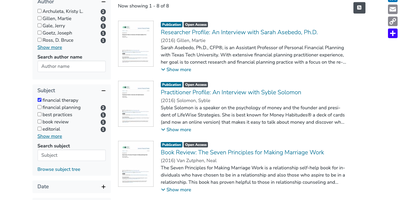
With DSpace, a library or research office can give every thesis, journal article, and dataset its own permanent web address, a searchable metadata record, and files visitors download from the archive. Content sits in a tree of communities and collections, and each collection decides who may deposit and how many review steps follow; reviewers accept a submission or reject it with a note that sends it back to the author. Embargoes hold files back until a set date, access policies limit other files to chosen groups, and sign-in works through LDAP, Shibboleth, SAML, OpenID Connect, or ORCID. Search covers metadata and the extracted full text of uploaded files, facets narrow the results, and browse pages sort by title, issue date, author, or subject. Editors can correct a published item through the submission form. Administrators inspect an audit trail and rewrite homepage news from an admin form. Entity types for people, organizations, projects, journals, and datasets link each publication to the work behind it, and DOIs can be registered through Crossref. Optional settings let authors keep an email address private on their researcher profile and download their own restricted files. Usage reports count visits, downloads, and top countries per item. REST, OAI-PMH, SWORD, and Google Scholar metadata connect the archive to harvesters, deposit tools, and search engines. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD-3-Clause licensed.
Directus
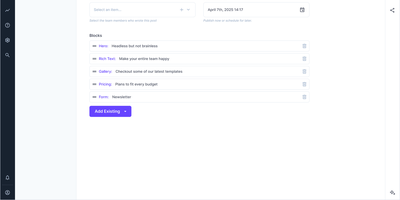
With 37,000 GitHub stars and over 45 million downloads powering 500,000+ deployed projects, Directus is the most widely adopted open-source backend platform that connects to your existing SQL database without requiring schema migrations or data duplication. Point it at PostgreSQL, MySQL, MariaDB, MS SQL, SQLite, OracleDB, or CockroachDB and it instantly generates production-ready REST and GraphQL APIs complete with filtering, sorting, pagination, field selection, and relational queries — all derived from your actual schema with zero configuration. The visual Studio provides a full no-code management interface where non-technical teammates create content, manage assets, build dashboards, and configure access policies without engineering involvement. Field-level granular permissions govern every API request and Studio action through composable policies applied to roles, users, and AI agents identically. A built-in AI Assistant writes copy, translates content across languages, creates records, and routes items for review directly within the Studio interface. The native Model Context Protocol server connects Claude Desktop, Cursor, ChatGPT, or any MCP-compatible tool to your live data governed by the same access policies. Real-time WebSocket subscriptions push collection changes instantly for collaborative editing and live dashboards. Extensibility covers custom endpoints, hooks, interfaces, displays, layouts, modules, and operations. Deploy via Docker with environment-variable configuration or use Directus Cloud for managed hosting. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL-1.1 licensed with free self-hosting.
CKAN
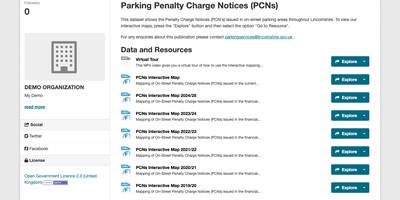
CKAN lets governments, research institutions, and companies publish data as a searchable catalog, where every dataset carries its description, license, tags, and downloadable files. Organizations own their datasets, and members, editors, and admins get different rights, so a dataset can stay private until someone with publishing rights releases it. Visitors narrow results with faceted filters on tags, formats, and organizations, or write fielded queries with wildcards and fuzzy matching. Resource pages preview spreadsheets in a grid and, when the data fits, as maps and charts, and they also display images, PDFs, and HTML. The DataStore keeps tabular resources as queryable tables, serving filtered rows with range conditions and nested AND/OR logic. Everything the web interface does is also available through the Action API. Groups gather related datasets, and custom metadata fields extend each record. Per-dataset activity streams document how data changes, and follow buttons feed a personal news feed. Files can be stored on local disk or, with extensions, in S3, Google Cloud Storage, or Azure Blob Storage. Extensions add geospatial search, harvesting for federated portals, multilingual metadata, and more chart types, and themes restyle the portal to match your brand. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Baserow
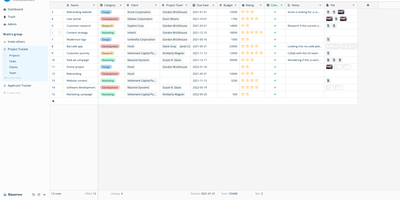
Airtable's spreadsheet-database model, self-hostable and open-source: that is Baserow. It presents data in a spreadsheet-style grid, but underneath each table is a real relational structure with typed fields, links between tables, filters, sorts, and multiple views (grid, gallery, form, kanban, calendar). Beyond the database core, it includes an application builder for composing pages and portals on your data, workflow automations, and dashboards. Everything is API-first: each table exposes a REST endpoint with token auth and webhooks, so it plugs directly into n8n, Zapier, or custom scripts. The stack is Django (Python) on the backend, Vue.js on the frontend, PostgreSQL for storage, with Redis for async tasks. Core features are MIT-licensed; premium features are a paid add-on. The self-hosted version has no row, storage, or API request limits - Airtable's per-base record caps and monthly API quotas simply don't exist here, and capacity is bounded only by your PostgreSQL database and disk. Existing Airtable bases, CSVs, and Excel files import directly with structure preserved, so migration doesn't start from a blank slate, and both the backend and frontend support plugins for custom field types and integrations without forking the core. For non-technical teammates the interface behaves like a spreadsheet; for engineers, the data model is the API.
Doccano
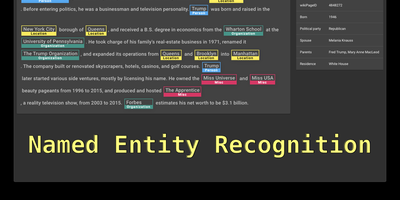
Doccano is a text annotation platforms for building machine learning training datasets. The web-based interface supports text classification for sentiment analysis and document categorization, sequence labeling for named entity recognition with overlapping entity support and relation extraction between labeled spans, and sequence-to-sequence annotation for text summarization and machine translation pairs. Collaborative annotation enables multiple annotators to work on the same project simultaneously with per-user progress tracking, annotation guidelines, example assignment to specific members, and filtering by assignee. Auto-labeling integrates with external machine learning model APIs through configurable request and response mapping templates, allowing pre-annotation that annotators can review and correct. Data import accepts plain text, JSONL, CoNLL, and Excel formats, while export produces JSONL and CoNLL datasets compatible with spaCy, Hugging Face Transformers, PaddleNLP, and other training frameworks through the doccano-transformer library. The Django backend with Django REST Framework exposes a complete RESTful API for programmatic project creation, dataset management, and annotation retrieval via the official doccano-client Python library. Celery handles background tasks including dataset import and export processing with Flower providing task monitoring. One-click deployment supports AWS CloudFormation and Heroku alongside Docker Compose for self-hosted environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Undb
Undb turns a browser tab into a full-featured database with spreadsheet-style editing, auto-generated REST APIs, and five configurable views for every table. The platform organizes data through Spaces, Bases, and Tables, offering grid view for traditional editing, Kanban boards for workflow tracking, calendar for date-based planning, gallery for image-rich records, and pivot tables for analytical summaries, each with independent filtering, sorting, color coding, and field selection. An ANTLR4-powered formula engine provides Airtable-style calculated fields with proper syntax validation, variadic argument handling, and type-checked function signatures that go beyond simple string interpolation. Every table automatically generates a fully documented OpenAPI REST endpoint with Swagger UI, letting developers integrate Undb data into external applications through standard HTTP methods without additional configuration. The Drizzle ORM abstraction layer supports four database backends (SQLite, PostgreSQL, MySQL, and Turso edge-distributed SQLite) with separate migration configurations for each adapter. Authentication uses Lucia with OAuth2 via Arctic for GitHub login and Oslo for TOTP two-factor authentication. The SvelteKit 5 frontend renders through Houdini's compile-time GraphQL client and TanStack Svelte Query, while the Elysia.js backend compiles into a single executable via Bun's --compile flag, embedding all assets into one portable binary. File attachments store in any S3-compatible backend including MinIO. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
db-ui
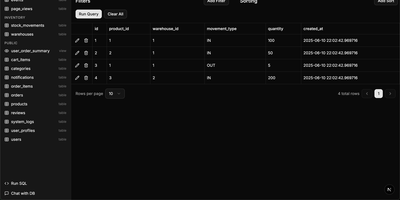
Traditional database management tools like pgAdmin and phpMyAdmin were built for DBAs, not for the rest of the team that just needs to look up a record or run a quick query. db-ui strips away the complexity and gives you a clean, modern interface that anyone can use. Browse tables in a paginated grid view with inline editing, filtering, and sorting built right into the column headers. The sidebar lists every table and view across all schemas with fuzzy search (Cmd+K to focus) that filters results as you type. Click any table to see its data, or switch to the schema introspection view to visualize columns, types, constraints, and relationships without writing a single query. The SQL editor provides syntax highlighting, result visualization in tabular format, and one-click CSV export for downstream analysis. For questions about your data model, the integrated AI chat assistant has full access to your database schema and can help you understand table relationships, write complex queries, suggest indexes, and provide optimization recommendations with streaming responses. Connect to PostgreSQL, MySQL, or Microsoft SQL Server through environment variables and deploy the whole application as a single Docker container. On RepoCloud, deploy db-ui on a dedicated VPS with root SSH access and direct connectivity to your database servers under the MIT license.