WhoDB
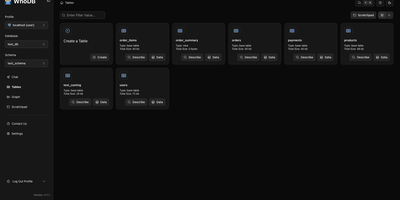
With nearly 5,000 GitHub stars earned in under two years, WhoDB has rapidly emerged as the lightweight alternative to heavyweight database clients like DBeaver and DataGrip by delivering a sub-50MB binary that starts in under a second and connects to 18+ database systems from a single interface. The Go backend serves the React and TypeScript frontend with table virtualization for efficient rendering of large result sets, lazy loading, and query result streaming that keeps the interface responsive even when browsing tables with millions of rows. The Community Edition connects to PostgreSQL, CockroachDB, YugabyteDB, MySQL, MariaDB, TiDB, SQLite, DuckDB, MongoDB, FerretDB, Redis, Valkey, Dragonfly, Elasticsearch, OpenSearch, ClickHouse, QuestDB, and Memcached through a unified credential selector that switches between databases with minimal configuration. Interactive schema diagrams render entity-relationship graphs showing table structures, foreign keys, and column types for visual database exploration. The Jupyter-style query scratchpad provides SQL autocomplete, syntax highlighting, and multi-statement execution with paginated results. AI integration optionally connects to Ollama, OpenAI, Anthropic, LM Studio, or any OpenAI-compatible provider for natural language database queries — ask questions in plain English and receive generated SQL. Data management includes inline row editing, CSV export, and filtered data views. Docker deployment runs a single container exposing port 8080. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OpenRemote
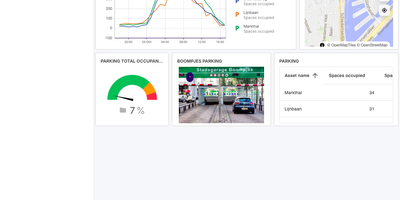
OpenRemote is an IoT platform that models every building, EV charger, solar panel, and street light as an asset in one tree, then maps, charts, and automates them from a single web dashboard. Define your own asset types, and give each attribute live readings, writable setpoints, history, and forecasts. Connect hardware with protocol agents for HTTP, MQTT, Modbus, KNX, Z-Wave, LoRaWAN, SNMP, and serial, discovering devices or importing project files where the protocol allows. Plot assets on a map with live position and heading, tint markers by attribute value, and add geofences and GeoJSON layers. Automate with When-Then rules, a drag-and-drop Flow editor, or Groovy and JavaScript rules, and run them on a schedule. Raise e-mails, push notifications, webhooks, or assignable alarms from the result. Compose shareable dashboards in Insights from nine widget types, including charts, KPIs, gauges, maps, and tables. Give each customer a realm with its own users, roles, and white-label branding. Sync edge gateways to a central instance and open them remotely through tunnels. Let devices with X.509 certificates register themselves. Read and write every attribute over REST, MQTT, or WebSocket, and let AI assistants manage assets in plain language through the MCP server. Typical projects span smart cities, building and energy management, and equipment fleets, in an interface that speaks nine languages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Apache Superset
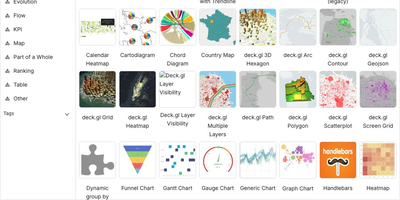
Powering data analytics at companies like Airbnb, Twitter, and Lyft where it originated, Apache Superset has become the leading open-source business intelligence platform with over 65,000 GitHub stars and an Apache Software Foundation top-level project designation. The platform ships with over forty visualization types out of the box including geographic maps, time-series charts, pivot tables, heatmaps, treemaps, and Sankey diagrams, all rendered with Apache ECharts for publication-quality output. Its SQL Lab provides a full-featured IDE experience with syntax highlighting, autocomplete, query history, and result caching for interactive data exploration. Superset connects natively to PostgreSQL, MySQL, ClickHouse, Trino, Presto, BigQuery, Snowflake, Apache Druid, Apache Hive, and dozens more databases through SQLAlchemy connectors, with support for custom database drivers via Python plugins. The semantic layer allows data teams to define calculated columns, metrics, and virtual datasets that business users can query without writing SQL. Role-based access control with row-level security enables fine-grained data governance, while the embedded analytics SDK lets you integrate dashboards directly into external applications via iframes with SSO pass-through. The caching layer supports Redis and Memcached for query result caching, and the asynchronous query execution engine powered by Celery handles long-running queries without blocking the UI. Alerts and reports can be scheduled via email or Slack with PNG or CSV attachments generated from any chart or dashboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Redash
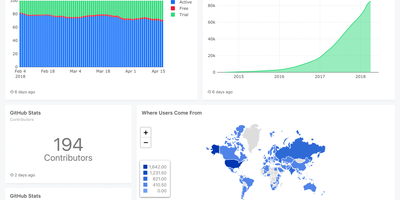
Used by millions of users at thousands of organizations worldwide and holding 29,000+ GitHub stars, Redash is the most established open-source SQL-first business intelligence tool — enabling anyone from analysts to executives to query databases, visualize results, and share dashboards without writing a single line of application code. The browser-based query editor supports SQL and NoSQL with schema browsing, auto-complete, query snippets, and parameterized queries that turn static reports into interactive data applications. Native connectors span 35+ data sources including PostgreSQL, MySQL, Amazon Redshift, Google BigQuery, Snowflake, ClickHouse, MongoDB, Elasticsearch, Databricks, Apache Presto, Microsoft SQL Server, and REST APIs — with an extensible data source API for custom integrations. Visualization types cover line, bar, area, pie, scatter, box plot, funnel, cohort, sankey, sunburst, choropleth map, and pivot tables, all draggable onto shared dashboards with cross-filtering parameters. Scheduled refreshes automatically update query results at configurable intervals, while threshold-based alerts notify teams via email, Slack, or webhook when metrics cross defined boundaries. SAML and Google OAuth SSO integration, role-based access control, API key management, and query-level permissions ensure enterprise-grade security for sensitive datasets. The self-hosted stack deploys via Docker Compose with PostgreSQL for metadata storage, Redis for job queuing, and Celery workers for background task execution. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 2-Clause licensed.
Immich Insights
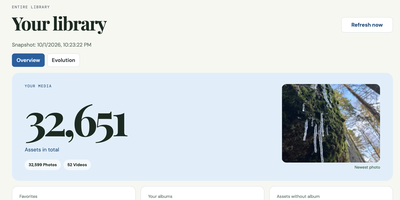
Immich Insights turns the photo library you already keep in Immich into a year-in-review style dashboard of how you actually shoot. Connect it with your own Immich API key and it reads your asset metadata into a local snapshot, without copying your original photos, then builds the overview Immich itself never shows: total photos and videos, storage used, favorites, albums, and your newest additions. Pick any year or a custom date range and see that period's shooting volume, favorites, albums, and devices. Camera statistics break your library down by device and manufacturer, with leaderboards you can correct when the same camera appears under different names. Exposure analysis shows your ISO, focal length, and shutter speed distributions, the focal lengths you reach for most, and how your settings shift by hour of day. Rhythm charts map your shooting by month, weekday, and hour, with a calendar heatmap of your most active days. A zoomable timeline marks the moments that matter: first photo, a new device joining the library, your longest gap, your busiest day ever. People and location views count faces and mapped places by country and continent, and a photography profile scores your habits. Clicking any chart value opens the matching photo thumbnails, and reports export as PDF, CSV, or JPG. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
ToolJet
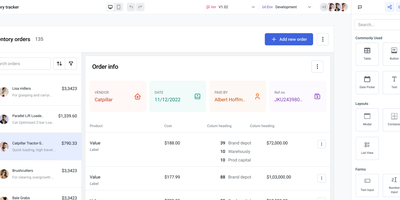
Retool's job, self-hosted: ToolJet is an open-source low-code platform for building internal tools, dashboards, and admin panels. Apps are assembled in a drag-and-drop visual builder with 60+ responsive components, including tables, charts, forms, and lists, and connected to 80+ data sources: PostgreSQL, MySQL, MongoDB, REST and GraphQL APIs, cloud storage, and common SaaS tools. When visual configuration is not enough, you can run JavaScript or Python inline for queries and transformations. A built-in no-code database (ToolJet Database) covers apps that need their own tables without provisioning an external database, Workflows add node-based automation for background jobs with dedicated worker containers and a Redis-backed queue, and multi-page apps with multiplayer editing, inline comments, and mentions support team development. Security is designed for internal data: credentials are AES-256-GCM encrypted, data flows proxy-only through your server so database contents never reach a third-party cloud, and granular per-app access control plus SSO gate each tool. Where Retool-style platforms bill per builder and sometimes per end user, the self-hosted Community Edition serves unlimited builders and users at hosting cost, and full source availability means the platform itself can be forked, audited, and extended. The stack is Node.js and React on PostgreSQL, deployed via Docker.
Dreeve
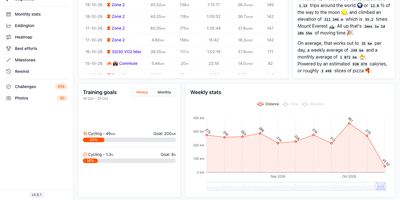
Every ride, run, hike, and swim you have ever recorded finds a home in Dreeve, a private fitness dashboard that lives on your own server rather than in a social feed. Import FIT, TCX, or GPX files from a watch folder, sync Strava, or add connectors for Garmin Connect, Wahoo, Polar Flow, Hammerhead, and Zepp/Amazfit. Weekly charts follow distance, time, and elevation beside training goals, heart rate zones, and training load analysis, and monthly stats pair per-sport totals with an interactive calendar. A heatmap paints every kilometer you have covered. Best efforts rank your fastest 5k, 10k, 50k, and 100k across every sport, while Eddington numbers, a milestones timeline, and a yearly Rewind mark the long game. Strava sync also brings segments, segment efforts, and challenges. Gear pages total the distance on each bike and shoe, and maintenance tasks send alerts through ntfy, Gotify, Discord, Telegram, Slack, or email when an interval comes due. Automation rules assign gear, flag commutes, and set sport types by device, distance, weekday, time of day, or location, so new imports arrive organized. Ask the AI workout assistant about your training, using cloud models, OpenRouter, or a local Ollama model. An installable mobile app and embeddable badges carry your stats to phones and blogs, and a password-protected admin panel keeps the settings. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
LightDash
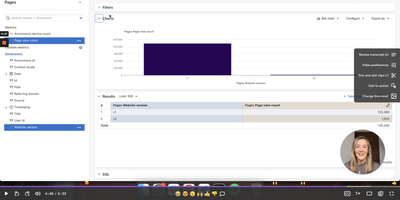
With 5,600+ GitHub stars and deep dbt integration, Lightdash is the open-source Agentic BI platform that treats analytics like software — defining metrics, dimensions, joins, permissions, and caching in a governed context layer that powers dashboards, AI agents, data apps, embedded analytics, and MCP server endpoints simultaneously. The dbt Write-Back feature lets business users create custom metrics and models in the UI, then automatically generates pull requests in GitHub or GitLab so every change flows through code review and CI validation before reaching production. Context-specific AI analysts automatically select relevant models and metrics, build queries, and present insights in plain English, while row-level security, user attributes, and customer-facing permissions ensure data governance at every layer. The platform connects to BigQuery, Snowflake, Redshift, Databricks, PostgreSQL, Trino, and ClickHouse through warehouse adapters, with the TypeScript monorepo built on React, Mantine, Vite, and TanStack Query on the frontend plus Node.js, Express, Knex, and PostgreSQL on the backend. Data teams build analytics with coding agents, preview changes from the CLI, validate in CI pipelines, and review charts and dashboards in pull requests — making the entire analytics lifecycle version-controlled and reproducible. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
DAC
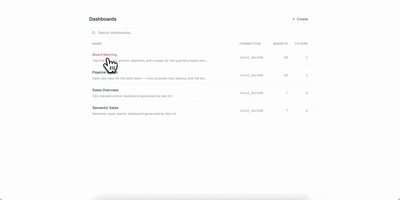
Your dashboards deserve version control, code review, and reproducible builds, just like the rest of your stack. DAC lets you define interactive data dashboards in YAML or TSX, validate them in CI, and serve them from a single Go binary that embeds a full React frontend. Choose from 21 chart types including line, bar, area, pie, scatter, bubble, funnel, sankey, heatmap, calendar, sparkline, waterfall, gauge, treemap, radar, and candlestick, plus metric cards, data tables, text blocks, and image widgets. The built-in semantic layer lets you define metrics and dimensions once in reusable model files, then reference them from any widget while DAC generates the SQL automatically. Connect to Postgres, MySQL, Snowflake, BigQuery, Redshift, Databricks, and DuckDB through standard Bruin connection configs. Interactive filters with date pickers, dropdowns, multiselects, and search inputs inject values via Jinja templating and re-execute only affected widgets. Live reload via Server-Sent Events refreshes connected browsers instantly when you save a file. Export dashboards as self-contained static HTML with baked-in query results for S3, GitHub Pages, or offline sharing, and render slide decks via the Google Slides export command. On RepoCloud, deploy DAC on a dedicated VPS with root SSH access and persistent storage for your dashboard definitions and database connections under the AGPL-3.0 license.
Frappe Insights
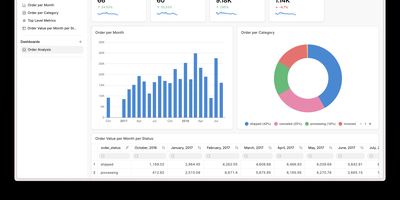
Frappe Insights delivers a self-hosted business intelligence platform where non-technical users build complex analytical queries without writing SQL. The visual query builder uses Ibis under the hood to compose optimized SQL from drag-and-drop column selections, filters, aggregations, and group-by operations — translating point-and-click interactions into performant database queries across MySQL, PostgreSQL, DuckDB, and BigQuery. The join editor provides a graphical interface for defining multi-table relationships, letting analysts connect data across schemas without understanding foreign keys or join types. The chart builder renders interactive visualizations using Apache eCharts with support for bar, line, area, pie, scatter, funnel, and pivot table chart types — each configurable with axes, colors, legends, and formatting options. Dashboards combine multiple charts into shareable views with layout customization, auto-refresh intervals, and filter propagation across widgets. Data source management handles connection pooling across multiple databases simultaneously, enabling cross-database analysis in single queries. Server scripts extend query capabilities with custom Python transformations for complex business logic that visual tools cannot express. Built on the Frappe Framework's full-stack architecture, deployment uses Docker via the official easy-install script that provisions the complete stack including MariaDB, Redis, and Nginx. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
uMap
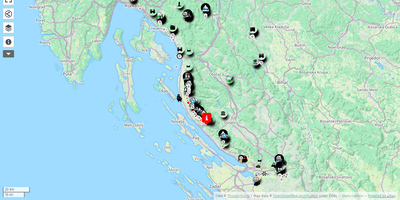
uMap turns OpenStreetMap into a personal mapmaking canvas: draw markers, lines and polygons in the browser, layer your own data over detailed street maps, and embed the finished map in any website. Each map is built from data layers you can style independently, choosing marker shapes, colors, icons and popups that show names, descriptions, photos or videos when clicked. You can sketch points of interest by hand or batch import whole datasets in GeoJSON, GPX, KML or OSM format, then let clustering group dense markers or a heatmap reveal where things concentrate. Backgrounds come from a choice of OpenStreetMap based tile layers, so the same map can sit on a street plan or a cycling map depending on the audience. Finished maps embed with a snippet of HTML, stay interactive inside the page, and can be downloaded or shared by link with read only access for viewers. Permissions decide who owns, edits or only views each map, and with real time collaboration switched on, several editors can draw on the same map simultaneously and watch each other's changes appear live. A slideshow mode turns layers into a guided story, stepping viewers through places in order with text and media attached to each stop. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Chartbrew
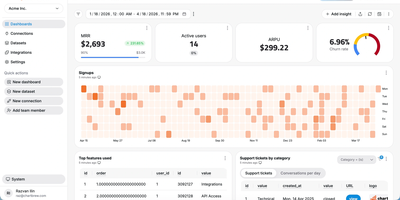
Chartbrew transforms raw database queries and API responses into polished, shareable dashboards without requiring a data engineering team. Connect to MySQL, PostgreSQL, MongoDB, Firestore, or any REST API, then build datasets using the visual query editor with syntax highlighting and auto-completion. Charts render through Chart.js with line, bar, pie, donut, radar, polar, KPI card, and table visualizations, each customizable with colors, legends, filters, and goal indicators. An AI assistant accelerates dashboard creation by generating queries and suggesting chart configurations from natural language descriptions of the metrics you want to track. Reusable datasets let teams prepare data transformations once and share them across multiple charts, while automatic scheduling through BullMQ and Redis refreshes data at intervals from every 10 minutes to monthly. The embed feature generates standalone chart URLs for insertion into external websites, internal tools, or customer portals, and the Reporting API enables programmatic dashboard management and automated report delivery. Team workspaces with role-based permissions control who can view, edit, or manage data connections. Nearly 4,000 GitHub stars reflect steady community adoption. The platform runs on Node.js with Express and Sequelize ORM, supporting MySQL or PostgreSQL as its application database. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. FSL-1.1-MIT licensed (converts to MIT two years after each release).
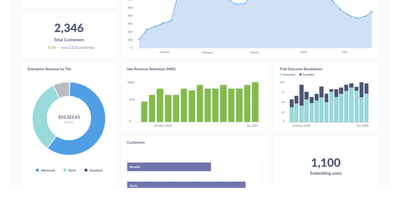
Metabase
The most widely deployed open-source BI tool, Metabase is a visualization and query layer that sits on top of your existing databases without ingesting or copying data. Non-technical users ask questions through a visual query builder with drill-through menus that answer follow-ups like "broken down by month" without writing a new query, while analysts use the native SQL editor with variables and templates for complex work. Questions assemble into interactive dashboards with filters, auto-refresh, fullscreen mode, and custom click behavior, and dashboard subscriptions email or Slack scheduled reports to stakeholders. It connects to 20+ data sources including PostgreSQL, MySQL, MongoDB, SQL Server, BigQuery, Snowflake, Redshift, and ClickHouse - always querying in place, so there is no second data store to secure, sync, or pay for, and results are always current. Models and metrics let a data team define official, reusable starting points so self-service stays consistent, collections with permissions organize content, and alerts fire when a metric crosses a threshold. The practical effect is cutting the ad-hoc query queue that lands on the data team, since non-technical staff can answer their own questions. Written in Clojure, licensed AGPL, and shipped as a single JAR or Docker image with an embedded application database - a working BI instance runs before most tools finish their installer - the open-source edition has no limits on users, dashboards, or connected databases, where commercial BI platforms price per viewer as well as per creator.
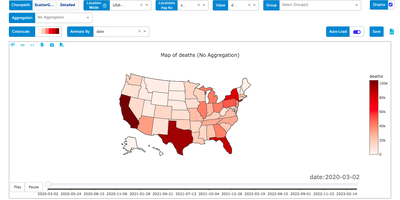
D-Tale
If your data lives in a pandas DataFrame, D-Tale gives it a spreadsheet-style grid, a column profiler, and a chart builder in the browser, started with one call from a notebook or script. In the grid you sort, filter, and edit cells inline, lock, hide, reorder, rename, or reformat columns from their menus, and open a Describe view with each column's distribution, summary statistics, outliers, and missing values, while highlight modes color dtypes, outliers, and numeric ranges across the whole table. Correlation matrices, a predictive power score, and duplicate reports sit beside dataframe functions that add numeric, binned, date, random, and type-converted columns, and Merge & Stack combines dataframes, including ones uploaded from Excel files. The chart builder draws line, bar, stacked, pie, wordcloud, heatmap, 3D scatter, surface, and map charts with grouping and aggregation, exports them as standalone HTML, and a network viewer graphs relationships between nodes. Whatever you build in the interface can be exported as reproducible Python code, and data can be saved as CSV or TSV. Launch it from Jupyter, Google Colab, Kaggle, a terminal, or the command line with a CSV path, protect it with optional authentication, and choose light or dark themes and English or Chinese. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. LGPL-2.1 licensed.
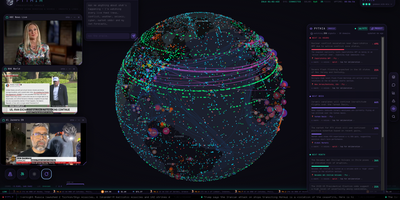
Pythia
With over 400 GitHub stars and growing, Pythia transforms a local LLM into a self-calibrating geopolitical oracle that watches the entire planet and predicts what happens next — no API keys, no cloud, no cost. The Osiris-based Three.js globe frontend streams 30+ concurrent live feeds including GDELT geopolitics, armed conflict events, USGS earthquakes, NWS storm polygons, EONET disasters, FIRMS wildfires, Polymarket crowd odds, cryptocurrency and commodity prices, UNHCR displacement data, WHO disease outbreaks, and WFP food insecurity indicators. The FastAPI backend fuses these heterogeneous sources into a unified world brief, pipes it through Ollama, and generates located predictions across 24-hour, weekly, monthly, and yearly horizons — each carrying a probability, reasoning, and geocoordinates that fly the globe to the event. A council of four specialist swarm agents — Strategist, Economist, Naturalist, and Skeptic — re-scores every forecast, surfacing consensus, dissent, and splits through Brier-weighted voting where historically accurate personas earn louder votes. The engine maintains a persistent ledger graded by an LLM judge against archived world state, producing running Brier scores and calibration charts. Signal rules fire browser notifications and webhooks when conditions match, a morning brief digest summarizes overnight changes, and the agent API at port 8088 delivers the complete world view in a single JSON call compressed to approximately 50 tokens for AI agent consumption. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
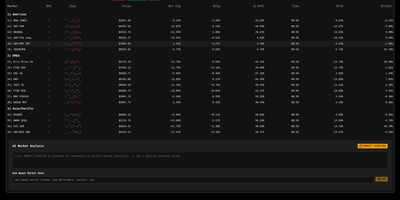
Bloomberg Terminal
With 1,450+ GitHub stars and a live demo on Vercel, this Bloomberg Terminal clone delivers a professional-grade financial dashboard without the $24,000 annual seat license. The Next.js 15 App Router with React 19 and TypeScript serves a single-page terminal interface optimized for constantly mutating financial data, with partial pre-rendering enabling sub-500ms initial loads even on data-heavy views. Upstash Redis caches AlphaVantage market data to minimize API calls while maintaining sub-second update latency through React Query polling with configurable refresh rates. OpenAI integration provides AI-powered market insights, sentiment analysis, and trend interpretation directly within the terminal interface. Multiple specialized views cover market data tables with bid/ask spreads, financial news aggregation with category filtering, market movers highlighting top gainers and losers, and volatility analysis with historical comparison charts. Jotai atoms manage local state for watchlists, layout preferences, and terminal sessions while React Query handles server-state synchronization with aggressive stale-while-revalidate caching. The shadcn/ui component library with Tailwind CSS delivers accessible, keyboard-navigable interface elements styled after Bloomberg's iconic dark terminal aesthetic. Security features include origin restriction, rate limiting via Redis, and Zod-based input validation on all API routes. Motion (formerly Framer Motion) animates transitions between views and data updates without layout shift. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
CloudBeaver
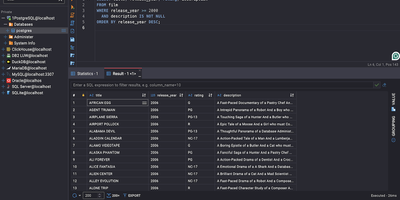
CloudBeaver puts a full-featured database management environment in your browser, connecting to PostgreSQL, MySQL, SQL Server, Oracle, ClickHouse, and over 100 additional engines through one unified interface that requires no desktop client installation. The Java server exposes a TypeScript/React frontend through a GraphQL API where teams can browse schemas, edit data, visualize relationships, and execute queries across all connected databases in a single workspace. The SQL Editor provides syntax highlighting, auto-completion with fuzzy search, AI-assisted SQL generation from natural language prompts, script management with save/download/upload capabilities, execution plan visualization, and multi-tab result display. The Data Editor enables direct cell editing, filtering, sorting, and bulk data modification with support for spatial GIS data rendering. Database administrators access a Navigator panel for browsing schemas, tables, views, foreign tables, triggers, dependencies, and stored procedures across all connected databases. ER Diagrams visualize table relationships and schema structure, while the Visual Query Builder constructs queries without hand-writing SQL. Multi-user administration provides role-based access control, connection sharing with configurable permissions, and session management. SSH tunneling secures remote database connections, and data can be exported or imported in multiple formats. Query History tracks all executed statements with timestamps and execution statistics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Maloja
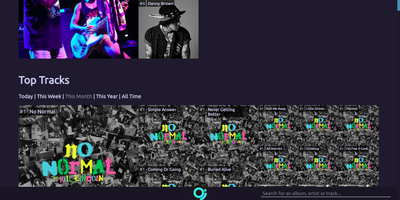
Maloja's one job is to be your own scrobble database, charting what you listen to from a server you control. Players and media servers that speak the native JSON API or a ListenBrainz, GNU FM, or Audioscrobbler 1.2 compatible protocol can scrobble with their own API keys. Vinyl sessions and background music can be logged by hand on a manual scrobble page. Existing history moves in from a Last.fm export, a Spotify data export, a ListenBrainz export, or another Maloja instance, while a proxy option forwards new scrobbles to Last.fm or a second Maloja server. The start page ranks top artists, tracks, and albums for today, this week, this month, this year, or all time, alongside a pulse chart of listening volume and a feed of the latest scrobbles. Artist and album pages add performance charts that follow chart position over time. Collaborations credit every artist on a track, and subunits, solo projects, and main acts can be combined or separated in charts at any time. Gold, Platinum, and Diamond awards mark tracks and albums that pass scrobble thresholds you set. Artwork can come from Last.fm, Spotify, Deezer, TheAudioDB, or MusicBrainz lookups, or from images you upload yourself. Week start, timezone, theme, and tile layout are all settings, and an API explorer lists endpoints for scripts. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.