DeepSeek Harness
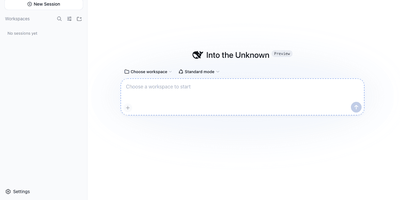
DeepSeek Harness gained over 60,000 GitHub stars within hours of its August 2026 launch, establishing itself as the first fully modular open-source agent runtime where literally every component is a swappable plugin. Built on the Cordis framework—a programming paradigm for spatiotemporal composability—dsh decomposes the entire agent stack into independently replaceable pieces: model adapters for DeepSeek, Anthropic, OpenAI, AWS Bedrock, Azure, and Google Gemini; tool registries covering bash execution, file system operations, web search, subagent delegation, and todo management; plus session stores, sandboxes, approval policies, orchestration loops, and the user interface itself. Four operating modes serve different workflows: Standard provides the full toolset, Code mode uses model-generated code to compose multi-round tool calls, Minimal strips down to a shell and editor for benchmarking, and Creator mode lets developers inspect the running runtime and test Cordis plugins in memory. The kernel handles plugin mounting, unmounting, and dependency resolution while typed events and services coordinate between components. Profiles and bundles allow the same codebase to produce entirely different products—a terminal coding agent, a browser-based workspace, a headless automation service, or an ACP/JSON-RPC endpoint—by swapping YAML configuration layers. Session history is stored as an append-only event stream for full trajectory replay, and project-level hooks on agent lifecycle events enable fine-grained behavioral customization. MCP client integration connects to external tool servers, while Agent Client Protocol enables programmatic orchestration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
TrueForge
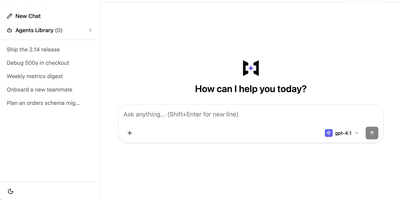
With over 2,100 GitHub stars in its first month and benchmarked at 30-75% lower cost than Claude Managed Agents on enterprise task suites, TrueForge is the open-source agent harness that provides the complete runtime layer for turning any LLM into a working production agent on your own infrastructure. The TypeScript server runs the full execution loop — streaming every step, routing tool calls through MCP servers with centralized header-auth and in-chat OAuth, delegating parallelizable work to isolated subagents, and pausing for human approval on sensitive actions. Context engineering keeps token costs low: deferred tool-schema loading delays MCP schemas until invoked, large-result offloading moves oversized outputs to files, Code Mode processes structured data through sandboxed execution, and automatic compaction summarizes older history at a configurable 50,000-token threshold while preserving the full transcript. The sandbox-as-a-tool architecture provisions isolated Daytona environments only when code execution is required, allowing one server to run many concurrent agents without idle overhead. Agents are configured from shipped YAML catalogs of models, MCP servers, git-backed SKILL.md instruction packs, and sandbox providers, then saved to an Agents Library accessible via the chat UI, TypeScript SDK, or embeddable React UI SDK. Run locally with SQLite via a single npx command, or deploy for teams with Docker Compose or Helm using Postgres and Redis with OIDC authentication. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenHands
With 83,000+ GitHub stars and $18.8M in Series A funding, OpenHands delivers the leading open-source platform for AI coding agents that scored 68.4% on SWE-bench Verified with Claude Opus 4.6, outperforming Devin 2.0's publicly reported 45.8%. The Agent Canvas web UI organizes work into persistent conversations where agents edit files, run shell commands, browse the web, and execute multi-step development tasks inside isolated Docker sandbox containers. The observe-plan-act loop drives agent behavior: the Python controller manages LLM abstraction via LiteLLM routing to 100+ providers including OpenAI, Anthropic, Google, DeepSeek, Qwen, Llama, and local Ollama models. Built-in skills for code review, Docker management, PRD generation, repo-rules enforcement, release notes, and test running attach to conversations automatically via auto-discovery or trigger-based activation. The Automations system schedules recurring agent tasks with configurable templates for CI workflows, dependency updates, and documentation generation. MCP server integration enables agents to access external tools and data sources. The REST API powers an OpenAI-compatible endpoint for connecting agents to chat UIs, IDEs, and voice platforms. GitHub, GitLab, Slack, and Jira integrations enable pull request reviews, issue resolution, and team notifications. The SDK provides Python and REST APIs for embedding agents in custom tools with local or cloud execution, custom agent behaviors, and Kubernetes deployment. On RepoCloud, deploy OpenHands on a dedicated VPS with Docker socket access, persistent project storage, root SSH access, and complete control over your AI development infrastructure, all under the MIT license.
Cognee
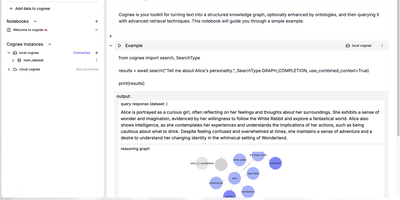
Cognee gives AI agents persistent long-term memory that survives across sessions, replacing the traditional stack of separate graph, vector, and session databases with a unified engine running on a single PostgreSQL instance. The memory-native API exposes four verbs (remember, recall, forget, and improve) enabling agents to persist context, retrieve cited answers, prune outdated knowledge, and self-improve from feedback. Under the hood, Cognee combines pgvector embeddings with a PostgreSQL-native graph store and cognitive-science-grounded ontology generation, delivering hybrid retrieval that fuses semantic similarity, structural graph traversal, and lexical search in a single query. Integrations span Claude Code, Cursor, LangGraph, OpenAI Agents, and any MCP-compatible client through a dedicated MCP server on port 8001, while the Python and TypeScript SDKs provide direct programmatic access. The platform supports swappable backends including Neo4j, FalkorDB, Qdrant, ChromaDB, Weaviate, Milvus, and LanceDB for teams with existing infrastructure. Built-in OpenTelemetry tracing, an experimental dashboard with knowledge graph visualization, multi-tenant user isolation, and audit trails ensure production readiness. Deploy via Docker Compose with optional profiles for PostgreSQL, Neo4j, Redis, and the web frontend. Reached v1.0 in April 2026 with 30,000+ stars. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Milvus
With over 45,000 GitHub stars and 100 million Docker pulls, Milvus is the most widely adopted open-source vector database, powering production AI systems at NVIDIA, Salesforce, eBay, Airbnb, and DoorDash. The distributed architecture separates compute and storage with stateless microservices on Kubernetes, horizontally scaling query nodes for read-heavy workloads and data nodes for write-heavy ingestion independently. Milvus 3.0 introduces lake-native retrieval that builds and serves indexes directly over vector data in object storage and open formats including Parquet, Lance, Iceberg, and Vortex without maintaining separate copies. Native hybrid search unifies lexical BM25 full-text retrieval and semantic vector search in a single engine with metadata filtering, eliminating the need for separate search infrastructure. Hardware-accelerated ANN indexing supports IVF, HNSW, DiskANN, and GPU-based indexes with BitQ 1-bit quantization cutting memory usage by 72 percent. SDKs for Python, Go, Node.js, and Java provide programmatic access, while Milvus Lite offers lightweight embedding for local development via pip install. Server-side aggregation, sorting, faceted search, StructArray for nested document structures, and ColBERT multi-vector scoring move ranking and result processing into the engine. The Path Index enables 100x faster JSON filtering with support for 100,000+ collections per cluster for multi-tenant deployments. Self-hosting deploys via Docker Standalone or Kubernetes with Helm charts using S3-compatible, GCS, or Azure Blob storage backends. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Gorse
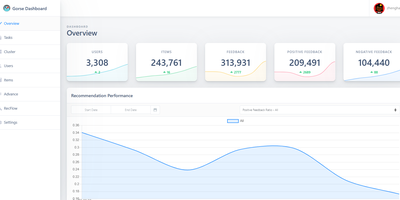
Gorse generates personalized recommendations from your application's user interaction data through automatically trained models, requiring no machine learning expertise to deploy or operate. Over 10,000 GitHub stars and production deployments processing millions of interactions validate a multi-source architecture that merges candidates from latest-item, user-to-user, item-to-item, and collaborative filtering recommenders, then ranks them using factorization machines or LLM-based rerankers with configurable query and document templates. Multimodal content support processes text, images, and video metadata via embedding vectors stored in BF16 format, with optional Qdrant, Weaviate, or Milvus integration for distributed similarity search. The visual RecFlow editor provides a drag-and-drop interface for designing recommendation pipelines, connecting data sources to recommenders and rankers without writing configuration files. A distributed cluster separates concerns across master nodes for model training and dashboard hosting, worker nodes for offline recommendation generation, and server nodes for real-time API endpoints, all scaling horizontally behind load balancers. Online evaluation analyzes recommendation quality from recent user feedback with configurable cache sizes and expiration intervals. RESTful APIs expose CRUD endpoints for users, items, and feedback alongside recommendation retrieval with category filters and API key authentication. Stores data in MySQL, PostgreSQL, MongoDB, or ClickHouse with Redis caching. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Letta
With over 24,000 GitHub stars and origins in the MemGPT research paper on virtual context management, Letta has evolved into the leading open-source platform for building AI agents that maintain persistent memory, identity, and continuity across sessions rather than operating as stateless prompt-response loops. The core architecture uses memory blocks — structured, labeled text chunks that reside permanently in the agent's context window — allowing agents to programmatically rewrite their own memory, learn new skills, and improve through a sleeptime dreaming process that runs reflection and memory organization during idle periods. The self-hosted App Server deploys via Docker and exposes a WebSocket API on port 4500, letting the TypeScript Agent SDK connect from any application using local, remote, or cloud backends. Agents support git-versioned memory through MemFS where every memory change is tracked and auditable, multi-agent communication via subagents, scheduled tasks, and integration with messaging platforms including Slack, Discord, Telegram, WhatsApp, and Signal. The platform is fully model-agnostic, routing to OpenAI, Anthropic, xAI, or self-hosted open-weight models through Ollama depending on cost, performance, and data residency requirements. The Agent File format serializes complete agent state — memory, skills, prompts, and conversation history — into portable snapshots. Desktop applications for macOS, Windows, and Linux provide native interfaces alongside the terminal CLI and web chat at chat.letta.com. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Ollaya
Ollaya serves decision models that answer typed questions about a message, ticket, or document with calibrated probabilities, through a self-hosted API shaped like the hosted service it can replace. Send a state, which can be an email, a support ticket, or any JSON, plus typed choice, score, and yes or no questions, and the model answers in one forward pass in milliseconds without generating text. Pull models by name the way Ollama users already know, with run, list, ps, show, copy, and remove commands managing the local store. Downloads verify every layer against its sha256 digest, resume when interrupted, and share blobs between models so storage stays lean. Existing TypeSafe code keeps working by changing one environment variable, because the /v1/systemone and /v1/decisions endpoints are wire-identical and the official SDK sends its key the same way. The native /api adds routing information and timings, model loading and unloading, and streamed pull progress for your own tooling. Put it to work triaging inboxes, routing requests to the right model or team, screening prompts for injection and jailbreak attempts, or replacing per-token LLM classification calls with a local answer. Agents reach the same engine through the bundled MCP server, and LiteLLM, LangChain, DSPy, LlamaIndex, n8n, and Dify connect through their existing integrations. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OmniRoute
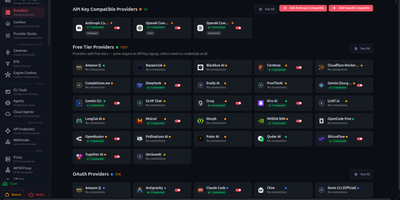
OmniRoute is an AI gateway, aggregating 338 LLM providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Kimi, MiniMax, and GLM into a single OpenAI-compatible endpoint at localhost:20128. The gateway catalogs over 1,200 models across 90 free-tier providers and 40 free-forever providers, automatically rotating through tier-1, tier-2, and tier-3 fallback chains when any provider exhausts its quota or returns errors. RTK plus Caveman stacked token compression reduces eligible context by 15 to 95 percent before forwarding requests, cutting API costs dramatically without degrading output quality. OmniRoute exposes its full routing engine through a built-in MCP server with 104 tools across 31 scopes over stdio, HTTP, and SSE transports, plus an A2A protocol server with six autonomous agent skills and JSON-RPC 2.0 streaming. The gateway integrates directly with Claude Code, Cursor, GitHub Copilot, Codex CLI, OpenCode, and Cline through standard base-URL configuration. Seventeen routing strategies include latency-optimized, cost-minimized, and auto-scoring modes that evaluate candidates on success rate, context fit, model fitness, quota state, and circuit-breaker health. The Next.js dashboard provides real-time provider status, usage analytics, combo chain configuration, and model catalog browsing via a responsive PWA. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Dify
Dify turns the notoriously complex process of building production-grade AI applications into a visual drag-and-drop experience that teams can actually ship and maintain. With over 87,000 GitHub stars and backing from prominent investors, the platform has become the go-to open-source LLMOps solution for organizations that refuse to be locked into proprietary AI stacks. The visual workflow canvas lets developers wire together LLM calls, conditional logic, iteration loops, tool invocations, and human-in-the-loop checkpoints without writing boilerplate integration code. Its RAG pipeline engine handles the full document lifecycle from ingestion of PDFs, Word documents, and HTML through configurable chunking strategies, embedding with models from OpenAI or open-source alternatives, vector storage in Weaviate, Qdrant, Pinecone, or pgvector, and hybrid semantic-plus-keyword retrieval with citation tracking. Dify integrates with hundreds of model providers including OpenAI GPT-4o, Anthropic Claude, Google Gemini, Mistral, Llama, and any OpenAI-compatible endpoint like Ollama for fully local inference. The agent framework supports both ReAct and function-calling strategies with 50-plus built-in tools spanning Google Search, DALL-E, Stable Diffusion, WolframAlpha, and custom API definitions. Published apps can be deployed as hosted web interfaces, embedded chat widgets, REST API endpoints, or MCP-compatible tools. Enterprise features include role-based access control, SSO integration, and audit logging. A built-in marketplace enables teams to share and reuse model providers, tools, and workflow templates across projects. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed with an open-source community edition.
Crawl4AI
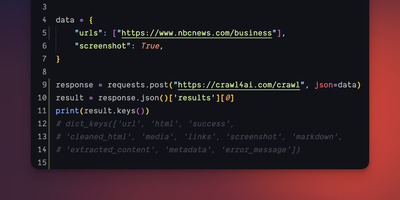
With over 77,000 GitHub stars, Crawl4AI is the most-starred open-source web crawler on GitHub and the go-to tool for converting the web into AI-ready data. Built on Python and Playwright, it transforms any website into clean Markdown with headings, tables, code blocks, and citation hints optimized for LLM ingestion, or extracts structured JSON via CSS selectors, XPath expressions, or direct LLM-based schema extraction through OpenAI, Anthropic, and Ollama providers. The self-hosted Docker server exposes a REST API on port 11235 with endpoints for crawling, streaming results, screenshots, PDF generation, JavaScript execution, and LLM-powered extraction. Version 0.9.x introduced secure-by-default operation with mandatory JWT authentication, strict request validation, declarative hooks replacing inline code, and bounded job queues. Adaptive crawling uses information foraging algorithms to determine when sufficient data has been gathered, while deep crawl mode traverses link graphs intelligently. The async browser pool manages concurrent sessions with stealth plugins, proxy rotation, custom headers, and session persistence for authenticated scraping. A built-in MCP server enables direct integration with Claude, ChatGPT, and Cursor for AI-driven web research workflows. Content filtering applies BM25 and TF-IDF relevance scoring to extract only pertinent sections from noisy pages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OpenSearch
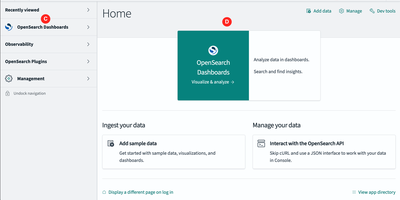
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
LocalAI
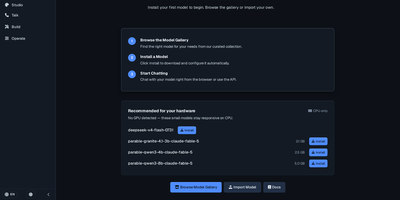
With over 48,000 GitHub stars and monthly releases since March 2023, LocalAI is the self-hosted AI engine that replaces every OpenAI endpoint with a single Docker container running on your own infrastructure — serving chat completions, image generation, text-to-speech, speech-to-text, embeddings, vision, video generation, and function calling through identical API schemas that require zero application code changes. The composable backend architecture isolates each inference engine as a separate gRPC service running in its own OCI container, so llama.cpp, vLLM, SGLang, transformers, whisper.cpp, diffusers, MLX, Stable Diffusion, and Flux install on demand without touching the core, can run on separate machines, and a fault in one never affects others. Hardware acceleration spans NVIDIA CUDA 12 and 13, AMD ROCm, Intel oneAPI/SYCL, Apple Silicon Metal, Vulkan, and NVIDIA Jetson L4T — or runs entirely on CPU without any GPU. Built-in AI agents support autonomous tool use, retrieval-augmented generation, Model Context Protocol integration, and skill-based workflows directly in the web interface. The model gallery provides curated YAML configuration files for hundreds of models that install with a single command, while P2P federated inference distributes model shards across multiple machines for running models larger than any single node's memory. Multi-user API key authentication with quotas and role-based access enables team deployments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LibrePhotos
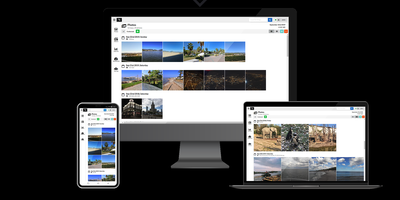
With over 8,000 GitHub stars and continuous development since 2020, LibrePhotos delivers the core intelligence of Google Photos — face recognition, object detection, semantic search, and automatic album generation — entirely on your own hardware without sending a single photo to a third-party server. The Django 5 backend processes uploaded media through a machine learning pipeline that runs face detection via the face_recognition library, clusters identified faces using scikit-learn and HDBSCAN, generates image captions through BLIP and Moondream 2, and classifies scenes using Places365 or Google's SigLIP 2 vision-language model with zero-shot classification against 900+ real-world tags. Semantic search lets you find photos by natural language queries like "sunset at the beach" without manual tagging, while metadata search filters by person, camera, lens, file type, and filesystem path. The React 18 frontend built with Vite presents a timeline view, fullscreen lightbox with slideshow mode, photo detail sidebar showing location and people, and a folder navigation view with breadcrumb paths. RAW files from any camera are converted via ImageMagick, videos processed through FFmpeg, and Live Photos paired with their RAW+JPEG counterparts as unified entries. Public album sharing via link provides fine-grained privacy controls, and duplicate detection uses perceptual hashing to identify near-identical images. Deployment runs as a single unified Docker container or via Docker Compose with Kubernetes manifests also available. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Chroma
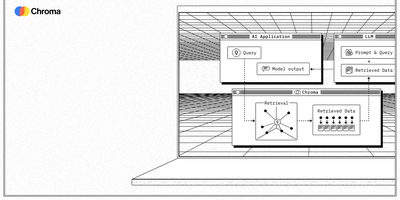
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Paperclip
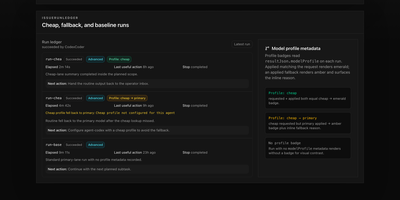
With over 77,000 GitHub stars accumulated in under five months since its March 2026 launch, Paperclip has become the default control plane for teams running multiple AI agents in production. Rather than juggling dozens of terminal tabs with Claude Code sessions, Codex instances, and Gemini CLI workers, Paperclip organizes all agents into a company structure with org charts, reporting lines, role-based permissions, and per-agent monthly budgets that trigger hard-stops when exceeded. The platform supports any runtime through its adapter system — Process adapters manage local CLI agents like Claude Code, Codex, Cursor, Pi, and OpenCode as child processes, while HTTP adapters trigger remote agents via webhooks to OpenClaw, serverless platforms, or custom endpoints. Heartbeat-based execution wakes agents on configurable schedules, injecting goal context, budget state, and workspace paths directly into the invocation payload. The Work and Task System provides atomic checkout with execution locks, first-class blocker dependencies, and structured work products to eliminate duplicate effort. Governance features include approval workflows, decision tracking, emergency stops, and full audit trails tracing every mutation to an actor. Deployment runs as a single Node.js process with embedded PostgreSQL locally or scales to external Postgres for production, installable in one command via npx paperclipai onboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
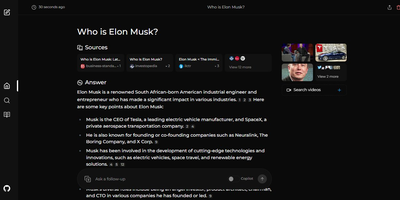
Vane
Perplexity's search experience without Perplexity: Vane deploys Perplexica, an open-source AI answer engine built as the self-hosted alternative. Instead of returning a page of links, it reads your question, searches the live web through the SearxNG metasearch engine, and composes a direct answer with cited sources. Retrieval quality comes from embeddings and similarity search: fetched pages are re-ranked against the query so the model answers from the most relevant passages rather than whatever ranked first. Two query modes cover different needs - Normal mode runs a straightforward web search, while Copilot mode generates multiple reformulated queries and actively pulls content from top matches for harder questions. Focus modes specialize retrieval for academic papers, YouTube, Reddit discussions, Wolfram Alpha calculations, or the general web. The answering model is your choice: OpenAI-compatible APIs or fully local LLMs such as Llama 3 and Mixtral through Ollama, which keeps queries entirely on your infrastructure. Because SearxNG pulls live results, answers reflect current information, and no search history is tracked.
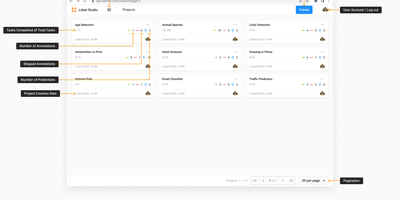
Label Studio
Images, text, audio, video, HTML, PDFs, and time series, labeled in one tool with a standardized output format: Label Studio is the open-source data labeling platform for building training datasets. Computer vision tasks cover classification, object detection (boxes, polygons, ellipses, keypoints), and semantic segmentation; audio work spans transcription, speaker diarization, and emotion recognition; NLP handles named entity recognition and document classification with taxonomies up to 10,000 classes; and GenAI workflows support LLM fine-tuning data and RLHF response ranking. Labeling interfaces are fully configurable with an XML-like templating language, so the UI matches the task instead of the reverse. The ML backend SDK turns any model into a connected web server for pre-annotation (model predicts, humans verify), interactive labeling (real-time predictions as annotators draw regions or highlight text), and model evaluation - cutting annotation time dramatically on large datasets. Data imports from S3, GCS, or file uploads; the Data Manager filters and explores tasks; exports convert to the format your ML library expects via label-studio-converter. Multi-user accounts tie every annotation to its author, and webhooks, a Python SDK, and REST API embed labeling into any pipeline. Self-hosting keeps proprietary training data - often a company's most sensitive asset - entirely on your infrastructure.