ntopng
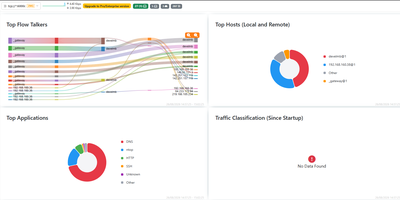
Network traffic stops being a mystery once ntopng names the hosts, applications, and protocols behind every flow, live in your browser. To find the host saturating an uplink, open the dashboard, which ranks top talkers, countries, autonomous systems, and protocols beside historical charts. To see what a suspicious host is contacting, open its page for traffic, ports, DNS queries, TLS details, and visited sites, plus a map of its conversations. Deep packet inspection recognizes applications such as Facebook, YouTube, and BitTorrent, so charts name the app behind the bytes instead of relying on port numbers alone. The console reads packets from a SPAN port or TAP and NetFlow, sFlow, or IPFIX records from routers and switches through nProbe, so it can cover a single switch or many remote sites. Behavioural checks raise alerts for flows, hosts, and interfaces and send them to email, Discord, Telegram, or webhooks. Active monitoring probes remote hosts over ICMP and HTTP/S, and network discovery lists the devices on your local network. A REST API and Lua scripting pull statistics into your own tools and add custom checks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Levelrail
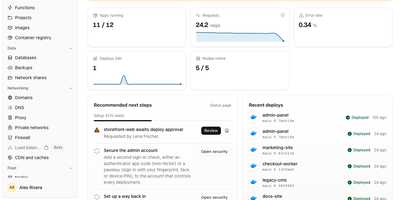
Push to git, watch the deploy go live over HTTPS, and roll back in one click, all on servers you own: Levelrail is a self-hosted platform for running apps and databases without Kubernetes. Deploys start from GitHub, GitLab, Bitbucket, or Gitea webhooks and build from a Dockerfile, Compose file, image, or framework preset such as Next.js, Go, React, or Spring Boot, with preview environments per pull request, canary and blue-green rollouts, approvals, and freezes. Embedded Caddy gives every app a domain with HTTPS: self-signed by default, Let's Encrypt with one toggle, a free sslip.io address when no domain exists, or your own uploaded certificate. Provision Postgres, MySQL, MariaDB, MongoDB, Redis, ClickHouse, and more with scheduled backups that are re-downloaded and verified, Postgres point-in-time recovery, and password rotation. Metrics with deploy markers, searchable live logs, alerts, and a public status page need no separate monitoring stack. Roughly 360 one-click templates and a Cmd+K search across apps, databases, and nodes speed up daily work. Extra servers enroll with a one-time token and a reverse-dialed agent that needs no inbound ports. Sign in with passkeys, TOTP, OAuth from 20 providers, or OIDC, then scope access with IAM policies, encrypted secrets, and a tamper-evident audit log. A CLI, HTTP API, and MCP server let scripts and coding agents deploy and roll back. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Oh My CPA
Oh My CPA gives a CLIProxyAPI gateway a proper control room, where providers, OAuth credentials, client keys, model routing, and the cost of every request are managed and watched from one self-hosted console. You add providers such as Codex, Claude, Gemini, xAI, DeepSeek, Vertex AI, and OpenAI-compatible services, each with credentials, retry and error policies, priority, weight, and an enable switch the gateway actually enforces. OAuth accounts are signed in from the console, with quota window readings, refresh schedules, and per-credential model aliases kept next to the keys they belong to. Client keys can be created, named, and revoked, and those names follow the traffic into request records and filters so you always know which key spent what. The dashboard follows request volume, token throughput, cache hit rate, and cost from the last fifteen minutes out to ninety days, with a year-long token heatmap for the long view. Insights compare keys, models, providers, and credentials against the previous period, while the live routing view shows which credential each request travelled to and whether it was rerouted. Every request stays searchable, with duration, time to first token, token breakdown, and the raw log in a detail drawer. A playground tests any routed model with text and images before your users do. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LogTide
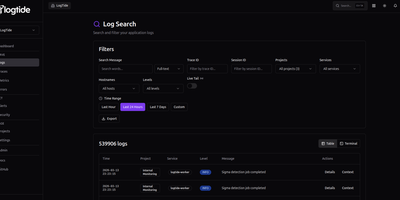
Every production incident starts the same way: someone asks "what do the logs say?" and the answer takes 45 minutes to find. LogTide collapses that search into seconds with a unified observability platform that indexes logs, traces, and metrics into a single queryable interface, backed by your choice of TimescaleDB, ClickHouse, or MongoDB. The log search interface supports full-text queries across millions of entries with filters for trace ID, session ID, project, service, hostname, and severity level, plus a live tail mode that streams new log lines as they arrive. Distributed traces render as waterfall timelines showing every span, its duration, and cross-service dependencies, while correlated logs for each trace are one click away. The metrics explorer visualizes OTLP gauge and counter data from your applications with system CPU, memory, disk, and network panels that update in near real-time. Where LogTide diverges from standard observability is its built-in SIEM engine: Sigma-compatible detection rules scan incoming logs for security threats like SQL injection, privilege escalation, lateral movement, and C2 communication, surfacing findings on a dedicated security dashboard with severity distribution, detection timelines, and affected service breakdowns. Alerting pushes notifications to Email, Slack, or Discord webhooks when thresholds trip or security rules fire. Native SDKs for Node.js, Python, Go, PHP, Kotlin, and Ruby ship logs with retry logic and circuit breakers, and the platform accepts OpenTelemetry data natively. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Langfuse
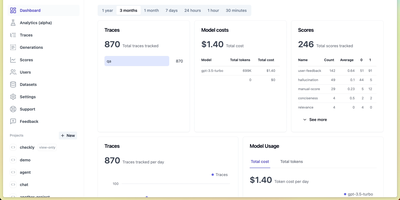
Backed by Y Combinator and trusted by over 2,300 companies processing billions of observations monthly, Langfuse is the most widely adopted open-source platform for building, monitoring, evaluating, and debugging LLM applications. The hierarchical tracing engine captures every LLM call, tool invocation, retrieval step, and agent action as nested spans based on OpenTelemetry, with automatic cost calculation, latency tracking, and token usage attribution across sessions and users. Prompt Management separates prompts from code with versioned artifacts, label-based deployments, one-click rollbacks, and runtime SDK fetching with server-side caching, while linking every generation back to its exact prompt version for attribution analytics. The evaluation system supports LLM-as-a-judge scoring, heuristic code evaluators, user feedback collection, and manual annotation workflows that run automatically on production traces or against curated datasets. The Playground enables interactive prompt testing on real production inputs with side-by-side model comparison across providers. Datasets and Experiments define test cases for systematic benchmarking with comparative result visualization. Native SDKs for Python and TypeScript provide decorator-based instrumentation, while 100+ integrations cover LangChain, LlamaIndex, OpenAI SDK, LiteLLM, Vercel AI SDK, and any OpenTelemetry-instrumented framework. The analytics dashboard surfaces cost breakdowns, quality scores, latency percentiles, and usage trends across models and prompt versions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
HyperDX
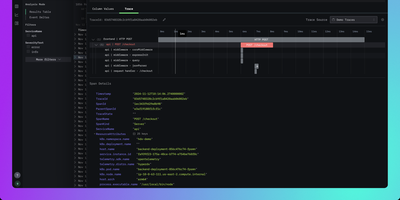
HyperDX correlates logs, metrics, traces, session replays, and errors in a single interface so engineers can resolve production incidents in minutes instead of hours. Nearly 10,000 GitHub stars reflect its role as the integrated UI layer for the ClickStack blueprint endorsed by ClickHouse. The platform connects to any ClickHouse cluster as its storage backend, working with existing table structures without requiring data migration or proprietary ingestion formats. An intuitive Lucene-like search syntax supports full-text queries and property filtering like level:err or service.name:api without needing SQL, while native JSON string querying and event delta analysis surface anomalies in high-cardinality datasets. One-click cross-signal correlation lets you jump from a log line to its distributed trace, from a slow span to associated logs, or from a frontend session replay to the backend errors it triggered. The OpenTelemetry Collector accepts telemetry via OTLP on gRPC port 4317 and HTTP port 4318, supporting automatic instrumentation for Node.js, Python, Java, Go, Ruby, and browser applications. APM tracks HTTP request latency, database query duration, and external service calls with trace waterfall visualizations. Configurable alerts trigger via webhook, Slack, PagerDuty, or email when thresholds are breached. Deploys via Docker Compose with ClickHouse, MongoDB, Redis, and the OpenTelemetry Collector. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpsiMate
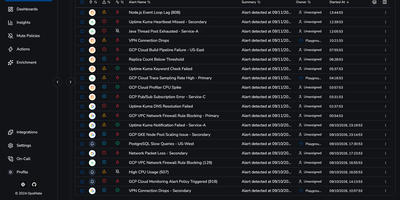
OpsiMate gives on-call teams one queue for alerts that would otherwise arrive in five different dashboards, each demanding attention in its own tab. Connect Grafana, Datadog, Zabbix, Uptime Kuma, Google Cloud, or any custom webhook source and watch incoming alerts land in one table with their source, service, severity, tags, and status attached. Filter the noise down to the team or service you own, group related alerts so one incident does not look like forty separate emergencies, and use mute policies when a known problem should stop paging people. Acknowledge work with one click, assign ownership so nobody wonders who is responding, resolve alerts from the same screen, and follow deep links back into Grafana or Zabbix when you need the original chart or trigger. Let supported integrations auto-resolve alerts when the underlying monitor recovers, and use root-cause notes and insights to keep the next responder from starting at zero. Discover services running in Docker, Kubernetes, and Linux virtual machines so the alert queue stays connected to the infrastructure behind it. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Exceptionless
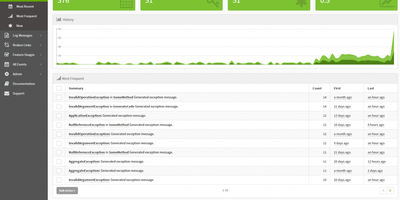
Exceptionless has earned over 2,400 GitHub stars and has been processing production errors since 2014 as the real-time event monitoring platform that captures far more than crashes. Built with ASP.NET Core on Elasticsearch for storage and Redis for caching, Exceptionless ingests exceptions, log messages, feature usage events, broken links, and custom event types through official SDKs for JavaScript, Node.js, .NET Core, ASP.NET, WPF, Web API, WebForms, Console apps, and React Native. Automatic event stacking groups related occurrences by exception type, message, and call stack into single actionable items, while manual stacking keys let developers create custom groupings for specific features or workflows. The real-time dashboard displays Most Frequent, Most Recent, and New event views with filtering by project, date range, environment, and custom tags. Stack management tracks resolution status with version-aware regression detection that automatically reopens resolved issues when the same error surfaces in a newer release. Webhook integrations connect to Slack, Discord, and external services through Zapier for automated issue tracking in GitHub Issues and Jira. Per-project notification settings control email and chat alerts for new errors, regressions, and critical events. OpenTelemetry support captures distributed traces alongside error data. The v8.6.0 release introduced a hosted Model Context Protocol server at the /mcp endpoint, enabling AI tools to query error data via OAuth-authenticated access. Deploy via Docker with the exceptionless/exceptionless image alongside Elasticsearch and Redis. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OpenLIT
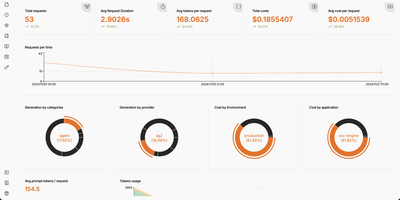
Your AI application is burning through API tokens faster than you can refresh the billing page, and you have no idea which prompt template is responsible. OpenLIT plugs that visibility gap with a self-hosted observability platform built specifically for LLM workloads. Add one line of code to instrument 90+ LLM providers, agent frameworks, and vector databases, then watch every request flow through a tracing dashboard that shows tokens consumed, latency measured, and dollars spent per call, per model, per environment. The requests view lists every LLM interaction with provider, model, cost, and token breakdown in a filterable table, while the trace detail panel lets you drill into individual spans to read the exact prompt sent and response received. Prompt Hub turns prompts into versioned artifacts you deploy, rollback, and A/B test without touching application code. OpenGround compares models side by side on the same input, so you can evaluate cost-versus-quality tradeoffs before committing to a provider. Automated evaluations run LLM-as-a-judge scoring on live production traces, flagging hallucinations, bias, and toxicity in real time. The Vault stores and rotates API keys centrally so secrets stay out of your codebase. Custom dashboards let you build drag-and-drop monitoring views with charts, stat cards, and tables backed by SQL queries against ClickHouse. GPU utilization, memory, temperature, and power metrics feed into the same platform for end-to-end infrastructure visibility. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
VictoriaMetrics
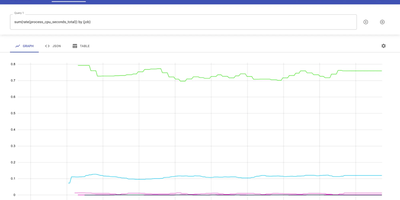
Trusted by thousands of organizations processing billions of time series data points and backed by 17,000+ GitHub stars, VictoriaMetrics delivers a monitoring and time series database that outperforms Prometheus by 16x on query speed while consuming 2.5x less disk space through its optimized compression and storage engine. The architecture supports both single-node deployments handling 10M+ active time series and a horizontally scalable cluster version with vminsert, vmstorage, and vmselect components providing multi-tenancy, replication, and independent namespace isolation. Data ingestion accepts both push protocols including InfluxDB line protocol, Graphite plaintext, OpenTSDB HTTP, CSV, and OpenTelemetry OTLP alongside pull-based Prometheus scraping and remote write, enabling drop-in replacement of existing monitoring stacks without reconfiguring exporters. MetricsQL extends standard PromQL with additional functions, subqueries, and implicit time range alignment while maintaining full backward compatibility with existing Prometheus alerts and Grafana dashboards. The vmalert component processes recording and alerting rules with Alertmanager integration, while vmbackup and vmrestore enable point-in-time snapshots to S3, GCS, and Azure Blob Storage. Stream aggregation operates as a StatsD alternative for pre-aggregating high-cardinality metrics before storage. NFS-compatible storage backends including Amazon EFS and Google Filestore allow shared persistent volumes across cluster nodes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Grafana
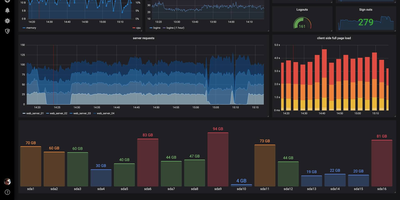
The de facto dashboard of observability: Grafana is the open-source frontend that turns the data stores you already run into interactive graphs. It does not store metrics itself; it connects to the data stores you already run and turns their contents into interactive dashboards. Supported sources number over 150 via plugins: Prometheus, Loki, Tempo, InfluxDB, Elasticsearch, MySQL, PostgreSQL, Microsoft SQL Server, AWS CloudWatch, Azure Monitor, Google Cloud Monitoring, and many more. Dashboards are built from a large library of panel types (time series, heatmaps, tables, gauges, logs) with template variables for reusable, parameterized views. Unified alerting evaluates rules against any connected data source, not just Prometheus, and routes notifications to Slack, PagerDuty, email, and other channels with grouping and silencing - unlike Prometheus Alertmanager, a single rule can combine a Loki log pattern, a PostgreSQL query result, and a CloudWatch metric. Dashboards serialize to JSON and data sources configure via provisioning files, so the entire observability setup can live in Git and deploy repeatably across environments. Explore mode adds ad-hoc querying outside dashboards, with split view for correlating a metric spike against the matching log lines, and access control spans organizations, teams, folder permissions, and OAuth, LDAP, and SAML integration. Written in Go and TypeScript, AGPL-licensed. Self-hosting gives you unlimited users, dashboards, and queries at flat hosting cost, without Grafana Cloud's usage-based pricing.
Graylog
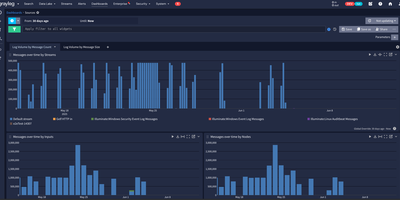
Trusted by over 60,000 organizations worldwide with more than 8,100 GitHub stars since 2010, Graylog has established itself as one of the fastest paths from raw log data to operational visibility, delivering centralized log management, security analytics, and compliance auditing through a purpose-built web interface with sub-second search at scale. The platform ingests logs from virtually any source via syslog, GELF, Beats, raw TCP/UDP, HTTP, CEF, IPFIX, and Netflow protocols, processing each message through configurable pipelines that parse fields, apply transformations, enrich events with GeoIP data from MaxMind or IPinfo lookup tables, and route messages to appropriate streams based on content rules. OpenSearch handles full-text indexing and storage with dynamic shard sizing that automatically calculates appropriate sizes from available node memory, while MongoDB stores configuration metadata including user accounts, roles, dashboards, alert rules, and pipeline definitions. The alerting system integrates with Slack, PagerDuty, and email with customizable notification templates and Replay Search links for immediate investigation context. Version 7.0 introduced MCP server integration for connecting preferred LLMs to perform AI-assisted log analysis and automation, while version 7.1 added Sigma detection rule import from private GitHub, GitLab, and Bitbucket repositories for detection-as-code workflows. The Sidecar agent management system centrally configures and deploys Filebeat, Winlogbeat, and nxlog collectors across infrastructure from the Graylog web interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. SSPL licensed.
CHMonitor
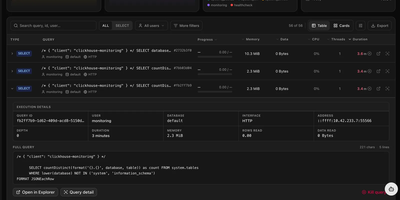
When a ClickHouse cluster slows down, the answers are buried in system tables nobody wants to query by hand; CHMonitor turns those tables into an operations dashboard that explains what the cluster is doing and what to fix next. Live views cover running queries with elapsed time, memory, and a kill action, while history, failed, slowest, and most-expensive pages rank finished work by CPU, duration, and rows read, each with the full statement and one-click EXPLAIN. Thread-level analysis shows how a single query parallelized, and per-user summaries reveal which analyst or service is eating the cluster. Beyond queries, you get a merge and part-lifecycle timeline, replication queue and Keeper health, a live topology map of shards and replicas, storage breakdowns by database, table, and part, and a query activity heatmap spanning a year. An AI advisor reviews the workload and recommends skip indexes, projections, PREWHERE clauses, and TTL changes ranked by impact, with an MCP interface and built-in agent for asking questions in plain English; it recommends only and never applies DDL. Threshold-based health checks alert to Slack, Discord, PagerDuty, or Opsgenie, multiple ClickHouse hosts are watched from one dashboard, and a companion terminal UI covers quick checks from the shell. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Dagster
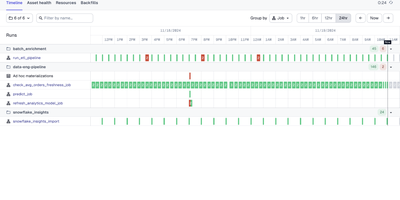
With nearly 16,000 GitHub stars, 5.7 million monthly PyPI downloads, and 400+ contributors, Dagster is the most widely adopted asset-centric data orchestration platform — replacing task-oriented schedulers like Apache Airflow with a declarative model where every pipeline is defined as Python functions producing data assets such as tables, datasets, machine learning models, and reports. The built-in asset graph provides automatic lineage tracking across your entire data platform, showing exactly how data flows from ingestion through transformation to downstream consumption in a single unified view. Declarative Automation goes beyond cron scheduling with event-driven conditions that intelligently trigger materializations based on upstream freshness, data quality signals, and dependency state. The integrated data catalog auto-generates documentation from asset metadata, ensuring it never drifts out of sync with production. Native first-class integrations connect dbt, Snowflake, BigQuery, Databricks, Fivetran, Airbyte, Spark, Great Expectations, Tableau, Power BI, AWS, GCP, and Azure without custom glue code. The web UI visualizes asset graphs, run history, schedules, sensors, and partitioned materializations with built-in alerting via Slack and PagerDuty. Dagster Pipes enables executing arbitrary code in external environments including Spark clusters, Kubernetes Jobs, and cloud functions. Deploy via Docker Compose on a single VM with separate containers for the webserver, daemon, and code locations, or use official Helm charts for production Kubernetes with K8sRunLauncher scaling each run as an independent Job. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Opik
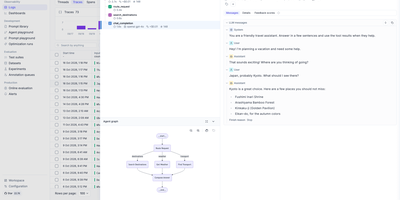
When an AI agent goes wrong at step seven of twelve, Opik, an open-source LLM observability platform, shows the exact trace, tool call, and prompt behind it, then scores your fix against test datasets. Full trace trees capture every LLM call, retrieval step, and tool execution, and you can annotate traces and spans with feedback scores in the UI or through the SDK. Native integrations for OpenAI, Anthropic, LangChain, LlamaIndex, CrewAI, Google ADK, and DSPy, plus OpenTelemetry for any language with an OpenTelemetry SDK, feed traces in, or add the @track decorator to your own functions. Datasets and experiments compare prompt and model versions, scored by LLM-as-a-judge metrics for hallucination, moderation, and RAG relevance, with a PyTest integration to run evaluations in CI. A Prompt Playground tests prompts across models, and the Agent Optimizer SDK helps improve prompts and agents. Production dashboards track feedback scores, trace counts, and token usage, online evaluation rules score live traces, and optional guardrails add safety checks. An MCP server lets Claude Code, Cursor, VS Code Copilot, Codex, or opencode read traces and run evaluations from chat. Run it yourself with the ./opik.sh script on Docker Compose, or a Helm chart on Kubernetes, so trace data stays in your infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Monoscope
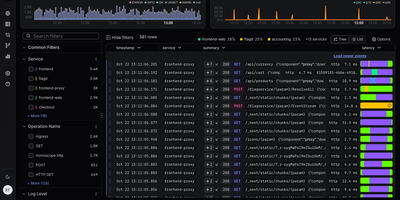
Across logs, traces, and metrics, Monoscope gives engineering teams one self-hosted workspace for finding what broke, asking questions in plain English, and hearing about problems before users do. Start in the Explorer: search events with KQL or an Ask AI prompt, flip between log rows, bar and line charts, log patterns, and sessions, and narrow results with facets for service, level, and HTTP status. Open any span to read its attributes, then follow the full trace across services in a waterfall, timeline, or map view. Live Tail streams new events as they arrive, and the Service Map draws every dependency with its error rate, latency, and requests per second. Build dashboards from widgets with copyable KQL and SQL, then set scheduled monitors with warn and alert thresholds, cron monitors, and uptime checks. An Issues inbox gathers API changes, errors, and log patterns so each one can be acknowledged, archived, or marked as spam, while Reports send scheduled summaries by email. Telemetry arrives over OTLP gRPC on port 4317 from OpenTelemetry SDKs and collectors. The monoscope CLI emits JSON for scripts, and an MCP server at /api/v1/mcp lets Claude, Cursor, and Cline search events and triage issues. Natural-language search uses the OpenAI-compatible model you configure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Komari
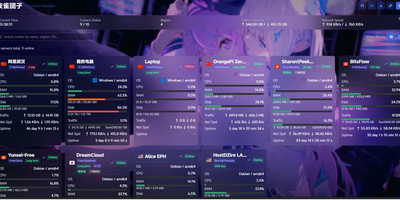
Komari turns a scattered fleet of VPS boxes into one clean status wall that shows which servers are alive, struggling, or about to expire. Every node reports CPU, GPU, memory, swap, disk, load, network speed, traffic totals, and uptime to a real-time dashboard, with history views from ten minutes to thirty days or any custom range. Flip between a card grid and a table, search by name, region, or operating system, and tag each machine with its price, billing cycle, and days until renewal. Latency tasks send ICMP, TCP, or HTTP probes and plot the results in per-node charts. Offline alerts wait out a per-node grace period before firing, expiry reminders warn before a plan lapses, and Webhook and custom JavaScript channels deliver them. A multi-tab browser terminal that reattaches after disconnects, remote command execution, and a remote file manager with an editor let you fix problems without leaving the panel. Agents install with a script, a binary, Docker, or an auto-discovery key for batch rollouts, and administrators can switch an agent's version remotely. Plugins run on an embedded JavaScript runtime and can add scheduled jobs, HTTP hooks, static pages, and notification channels. Administrators can add two-factor authentication, OAuth sign-in, API keys for a JSON-RPC 2.0 endpoint, themes from a theme market, and backups. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
CPA Manager Plus
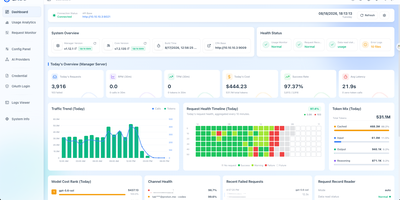
CPA Manager Plus is a self-hosted observability dashboard and management panel that tracks every AI request flowing through your CLI Proxy API gateway, breaking down failures, costs, and account health across providers like OpenAI, Anthropic, xAI, and Codex in one interface. When a request fails, drill into the persistent history to see status codes, affected models, latency, and redacted failure evidence without exposing raw response bodies. The cost analytics engine breaks down token consumption and estimated spend by model, provider, account, API key, project, channel, and time range while tracking input, output, reasoning, cache, and service-tier pricing semantics separately. Model prices sync automatically from models.dev with LiteLLM and OpenRouter fallbacks, and you can add local overrides for aliases or internal models. For teams running Codex or xAI accounts, the health inspector reads quota windows, reset evidence, credential state, and workspace status on a configurable schedule, routing credential failures into an action queue for review rather than letting them silently degrade throughput. Deploy the Lightweight Panel to replace your existing CPA management UI without adding another service, or run Full Mode as a single Docker container that adds the Manager Server with persistent SQLite storage for request history, historical analytics, and automated account inspections. Export or import request history as JSONL for external analysis, and back up the SQLite files alongside your encrypted management keys. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.