Prime Agent
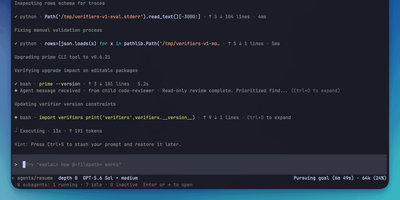
With over 14,000 GitHub stars and 41 releases since its May 2026 launch, Prime Agent delivers a fundamentally different approach to AI coding agents by treating the agent's own operating environment as programmable state that improves through use. The Recursive Language Model architecture provides the model exactly one tool — a persistent IPython kernel — where file operations, shell commands, subagent delegation via rlm() function calls, and context management all happen through code rather than rigid tool-calling schemas. Subagents launch as independent sessions with their own model, kernel, and history, communicating results through agent_message.send() without blocking the parent. The Continual Harness stores supplemental prompts, memories, skill descriptions, and reusable subagent specifications as durable state that the /refine command updates through small, evidence-backed edits with full rollback by ID. Daemon-backed sessions keep running when the terminal disconnects, with automatic context compaction summarizing older messages while preserving recent state. The TUI provides an Agent View for monitoring, switching between, and steering multiple live sessions simultaneously. Autonomous mode operates within configurable turn, token, and time budgets with user-defined quality gates. Persistent goals, heartbeats, and scheduled prompts maintain continuity across terminal sessions. Compatible with Anthropic Claude, OpenAI, Google Gemini, local models via Ollama or vLLM, and Prime Inference endpoints. Install via a single curl command on Linux or macOS. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Odysseus
Agents with tool use, deep research, a document editor, an IMAP/SMTP email client with AI triage, notes, tasks, and a CalDAV-synced calendar - Odysseus bundles all of it into one open-source, self-hosted AI workspace. It runs local models through Ollama, vLLM, or llama.cpp and cloud APIs like OpenAI and OpenRouter, with a hardware-aware Cookbook that scans your machine and recommends quantized models that fit. Persistent memory uses ChromaDB with hybrid vector-plus-keyword retrieval, web search runs through a bundled SearXNG instance, and agents can use MCP servers, files, and shell access with safety controls, plus custom skills and scheduled agent tasks. A blind Compare mode runs side-by-side model duels with identities hidden and accumulates Elo-style ratings from your votes, so model selection is based on your actual workloads rather than leaderboard claims. Deep research mode - adapted from the Tongyi DeepResearch approach - reads sources through SearXNG and produces cited reports, while the email client tags, summarizes, sets reminders, and drafts replies locally rather than through a third-party mail AI. The writing-first document editor adds AI edits, Markdown and HTML support, and version history. The stack is Python 3.11 with FastAPI, SQLite for state, and a vanilla JS frontend, licensed AGPL-3.0 with zero telemetry. Because agents can read email and execute commands, keep authentication enabled and never expose it as a public unauthenticated service.
DeerFlow
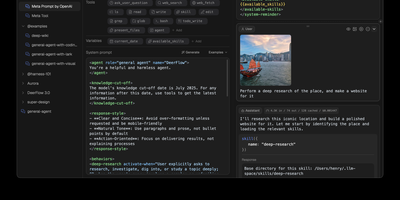
DeerFlow 2.0 is ByteDance's ground-up rewrite that transforms what began as a Deep Research framework into a batteries-included super agent harness handling tasks lasting minutes to hours autonomously. Built on LangGraph and LangChain, the runtime orchestrates a lead agent that plans, decomposes, and delegates to sub-agents executing in isolated Docker or Kubernetes sandboxes with persistent filesystem access, while an extensible skills system lets developers add capabilities as Python functions or MCP servers with OAuth token flows. The harness ships with long-term memory using persistent event loops with per-agent isolation, scheduled task execution via cron, context engineering with manual compaction, and a web UI at localhost:2026 for interactive sessions. Model support spans OpenAI GPT-4o/GPT-5, Anthropic Claude via OAuth, Google Gemini, DeepSeek, Qwen via vLLM, and OpenRouter-compatible gateways with per-model pricing configuration. IM channel integration connects Telegram, Slack, Feishu/Lark, Discord, WeChat, WeCom, DingTalk, and Buzz without requiring a public IP — all using long-polling or WebSocket transports. Production deployment uses Docker Compose with nginx reverse proxy, PostgreSQL or SQLite persistence, Redis stream bridges for multi-worker scaling, and lease-based run ownership with automatic orphan recovery. The terminal workbench TUI enables headless operation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Overleaf
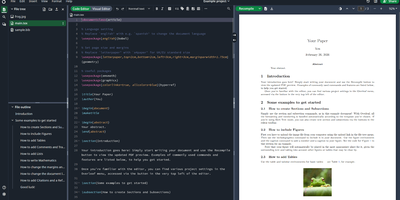
Multiple authors can edit the same LaTeX document simultaneously in the browser with live cursor tracking, conflict-free merging, and instant PDF compilation on every save. Overleaf Community Edition brings the collaborative editing experience that millions of researchers and academics rely on, with no compile time limits, storage quotas, or collaborator caps imposed by the hosted tiers. The web editor provides syntax highlighting, auto-completion, and bracket matching alongside an integrated PDF preview panel powered by a bundled TeX Live distribution supporting pdfLaTeX, XeLaTeX, and LuaLaTeX engines. The file tree panel organizes multi-file projects with separate files for chapters, figures, bibliography references, and style definitions. BibTeX and Biber handle bibliography management, and detailed compilation logs offer clickable error navigation to the exact source line causing each issue. Users upload images, PDFs, and data files directly through the browser, and a template gallery provides starting points for journal articles, conference papers, theses, presentations, and CVs. Over 17,800 GitHub stars and a decade of active development anchor the project. The application runs as containerized microservices including the Node.js web application, MongoDB for persistence, and Redis for session management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
AI Researcher
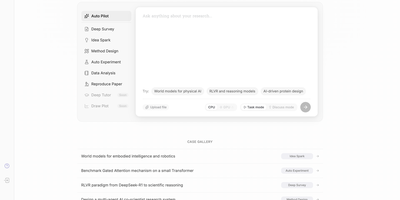
Accepted as a NeurIPS 2025 Spotlight paper and rapidly approaching 6,000 GitHub stars, AI-Researcher from the Hong Kong University Data Science Lab delivers the first fully autonomous scientific research system — a multi-agent platform that takes a list of reference papers and returns a complete research contribution with working code, validated experiments, and a formatted academic manuscript. The pipeline orchestrates five distinct phases: a Resource Collector systematically gathers materials from arXiv, IEEE Xplore, ACM Digital Library, Google Scholar, GitHub, and Hugging Face; an Idea Generator performs gap analysis against semantic embeddings to produce 3-5 novel hypotheses with feasibility scores; an Algorithm Designer transforms concepts into functional implementations; a Validation Engine automates testing, performance evaluation, and iterative optimization; and a Manuscript Creator generates polished full-length papers with figures, tables, and citations. The Gradio-based web GUI provides intuitive tabs for environment configuration, example selection, and real-time monitoring of research progress, while the production deployment at novix.science offers immediate browser access without local setup. Scientist-Bench provides a standardized benchmark comprising state-of-the-art papers across diverse AI research domains for evaluating autonomous research capabilities. The system supports multiple LLM providers including OpenAI, Anthropic, Google Gemini, and OpenRouter models with per-task routing for cost optimization. Deploy via Python with pip dependencies or Docker containerization. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Morphic
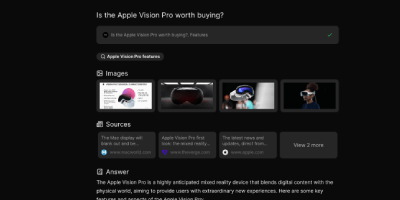
Perplexity's answer-engine experience, self-hostable and open-source: Morphic searches the web and writes cited answers. Instead of returning a list of links, it searches the web, reads the sources, and generates a complete answer with inline numbered citations. The generative UI streams rich components, source cards with thumbnails, image grids, syntax-highlighted code, and LaTeX math, rather than plain markdown. Quick mode answers fast; Adaptive mode runs deeper multi-step research. Search backends are pluggable: the Docker Compose bundle ships with a private SearXNG instance so no search API key is required, and Tavily, Brave, and Exa are supported alternatives. LLM providers include OpenAI, Anthropic, Google, Ollama, and any OpenAI-compatible endpoint, with per-mode model mapping - fast, cheap models for quick searches, stronger models for adaptive research, tuning the cost-quality trade-off per query type. An inspector panel exposes tool execution during multi-step research, and AI-suggested follow-up questions keep an investigation moving. Chat history persists in PostgreSQL, results are shareable by URL, file uploads feed context into queries, and optional Supabase authentication adds multi-user or guest access. Because the default search path is your private SearXNG instance, research topics never hit a commercial search API - and with local Ollama models the marginal cost of a query approaches zero. Built with Next.js, TypeScript, and the Vercel AI SDK under Apache 2.0.
SurfSense
Positioned as the open-source NotebookLM alternative for AI agents, SurfSense delivers a live web research platform where your agents access structured data from Reddit, YouTube, Instagram, TikTok, Amazon, Walmart, Google Maps, Google Search, Indeed, and any page on the open web through one REST API or MCP server. Scheduled and event-triggered agents transform findings into briefs, alerts, podcasts, and presentations, while a built-in knowledge base keeps every discovery searchable with Perplexity-style cited answers using hybrid semantic and full-text search powered by PostgreSQL with pgvector. Upload PDFs, Office documents, images, and audio files, or sync Google Drive, OneDrive, and Dropbox — 50+ file formats supported with AI file sorting that auto-organizes documents by source, date, and topic. The MCP server exposes scrapers, knowledge base, and workspaces as native tools for Claude, Cursor, and any MCP-compatible agent. Cross-country proxy rotation handles Reddit, TikTok, and Google Search scraping with geo-aware sticky sessions and captcha-aware anti-bot handling. The platform features collaborative chats, multi-format document export, git-native knowledge base with Open Knowledge Format export, and a desktop quick-ask panel with global shortcut. Docker Compose deployment manages nine services including Caddy proxy, PostgreSQL, Redis, FastAPI backend, Celery workers, zero-cache real-time sync, and Next.js frontend with automatic Watchtower updates. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Open Kritt
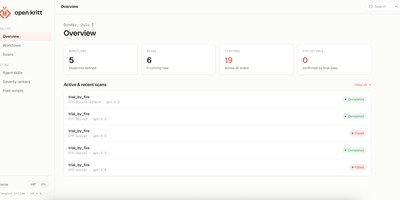
Big repositories, small questions: Open Kritt is a self-hosted platform that splits vulnerability research into focused tasks for AI agents and returns ranked, de-duplicated findings. Build a workflow as a tree of prompt steps, where each step declares the structured output it must produce and the next level launches one fresh agent per result. Scan remote or local repositories along with their dependencies, using Codex, Claude Code, or Grok Build as the harness. Every workflow ends in one fixed finding schema covering file, line, vulnerability type, trigger flow, and a malicious input example. Post-scripts then validate each finding, build a proof of concept, or write the report. Markdown severity rankers tell the model how to prioritize for your bounty program, and repeated findings collapse automatically. Model access comes from a Codex login or OpenAI, Anthropic, DeepSeek, OpenRouter, or xAI keys, with an Active switch to choose which accounts take new work. A dashboard tracks blueprints, scans, and findings, a headless command-line tool imports workflows and launches scans on servers without a browser, and finished scans export as one ZIP with a share-safe manifest. Built-in workflows, including an entry-point-driven hunt, give you a starting point. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
ArchiveBox
Backed by 27,700+ GitHub stars and actively developed with the v0.9.x architectural overhaul introducing an event-driven plugin ecosystem, ArchiveBox delivers the open-source self-hosted web archiving platform that preserves websites, bookmarks, social posts, media, source code, and research material in durable formats before link rot, platform shutdowns, and censorship erase them permanently. Feed it URLs one at a time or schedule automated imports from browser history, RSS feeds, Pocket, Pinboard, Instapaper, Wallabag, Shaarli, JSON, CSV, HTML bookmark exports, and browser extension captures. Each snapshot stores redundant copies as original HTML, rendered single-file HTML via SingleFile, full-page PDF, screenshot PNG, WARC archive, article text via Readability, favicons, HTTP headers, media files via yt-dlp, git repository clones, and structured metadata in SQLite. The Docker Compose deployment bundles Chrome, wget, curl, yt-dlp, SingleFile, and Readability parsers with automatic dependency management and isolation. Interact through the self-hosted web UI with search, tagging, and admin controls, the comprehensive CLI for batch operations, the REST API for programmatic access, or the Python API for custom integrations. The new abx-plugins system enables community extractors with per-plugin configuration, while the append-only-log architecture provides resumable crawls and audit trails. S3, B2, and Google Cloud storage backends sync archives to remote storage via rclone. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
GPT Researcher
A question goes in; a cited, long-form report comes out - GPT Researcher is an open-source autonomous research agent. A planner agent decomposes the query into sub-questions, execution agents crawl 20+ web sources in parallel with JavaScript-enabled scraping, and a publisher aggregates findings into a 2,000+ word report with inline citations, exportable to PDF, Word, and Markdown. The Deep Research mode extends this recursively: each result yields follow-up questions that are explored to configurable breadth and depth in a tree pattern, while accumulated learnings, citations, and visited URLs are shared across branches. It also researches local documents (PDF, CSV, Word) alongside the web. LLM and search providers are pluggable, including OpenAI, Anthropic, Google, DeepSeek, and Ollama for models, and Tavily, Google, Bing, DuckDuckGo, and SearXNG for retrieval. It ships as a Python package, a FastAPI server with web frontend, a Docker image, and an MCP server for use inside Claude or Cursor. MIT-licensed.
OHIF Viewer
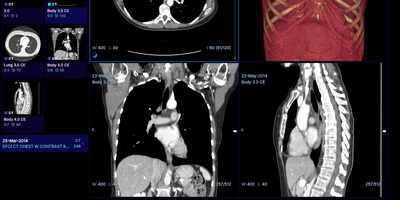
The OHIF Viewer reads CT, MR, PET, and slide microscopy studies straight from a DICOMweb archive and shows them in any browser tab, with no workstation software to install. The study list filters by patient name, MRN, study date, description, modality, and accession number. Each study launches into the workflow mode that fits its modalities. Basic Viewer mode tracks the measurements drawn on images and gathers them in a side panel for review. Layouts include MPR, four-up 3D, volume rendering, and PET/CT fusion with maximum intensity projection. Labelmap tools offer brush, eraser, threshold, and shape segmentation, and DICOM segmentation, RT Structure, and structured report objects display alongside the pixels. PDFs, video clips, ECG waveforms, 4D series, and whole slide microscopy open in the same interface. Hanging protocols arrange series the way each workflow expects. An iframe embed drops the viewer into a portal or research app. Pair it with Orthanc or DCM4CHEE for storage and Keycloak for sign-in. Oncology trial reads, imaging research, and web front ends for a PACS are the usual jobs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Vane
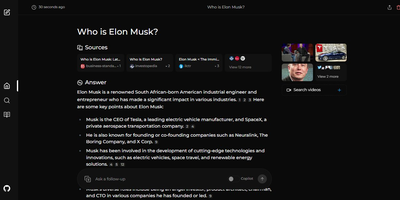
Perplexity's search experience without Perplexity: Vane deploys Perplexica, an open-source AI answer engine built as the self-hosted alternative. Instead of returning a page of links, it reads your question, searches the live web through the SearxNG metasearch engine, and composes a direct answer with cited sources. Retrieval quality comes from embeddings and similarity search: fetched pages are re-ranked against the query so the model answers from the most relevant passages rather than whatever ranked first. Two query modes cover different needs - Normal mode runs a straightforward web search, while Copilot mode generates multiple reformulated queries and actively pulls content from top matches for harder questions. Focus modes specialize retrieval for academic papers, YouTube, Reddit discussions, Wolfram Alpha calculations, or the general web. The answering model is your choice: OpenAI-compatible APIs or fully local LLMs such as Llama 3 and Mixtral through Ollama, which keeps queries entirely on your infrastructure. Because SearxNG pulls live results, answers reflect current information, and no search history is tracked.
Aldine
Paper co-authors usually trade .tex files by email or pay for a hosted editor seat by seat; Aldine replaces both with a self-hosted LaTeX workspace where the whole team types in one document at once and sees a typeset PDF seconds later. Live cursors and presence show who is editing which paragraph, and the underlying sync is conflict-free, so two authors can rewrite the same section without overwriting each other. Every project is a real git repository: branch a draft, edit it independently, and merge it back from the interface when the argument holds together. Connect GitHub, GitLab, Gitea, or Forgejo to push and pull without leaving the editor, watch ahead and behind indicators, resolve conflicts, and open a pull or merge request on the merged result. Moving in is painless, since an exported Overleaf project ZIP dropped on the home screen imports with its root file detected and its first typeset automatic. Citations come from your own Zotero library or a single collection, kept in sync as a .bib file and inserted from a search panel or \cite autocomplete. Reviewers select text and leave anchored, threaded comments, optionally with a suggested replacement the author accepts in one click. Compiles run in a sandboxed container with no network access, warm recompiles land in about two seconds, and errors jump to the offending line. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
SourceWeft
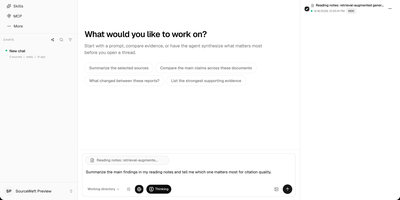
SourceWeft is an AI workstation you host yourself, where agents, your documents, and your model keys work in one place instead of scattering across chat tabs you do not control. Describe a job and a lead agent breaks it down, handing research, exploration, and execution to focused sub-agents that share the same working context and files. Agents draw on a skill library covering presentations, HTML pages, images, meeting summaries, and study guides, and you can add your own skills so good workflows become repeatable. MCP servers, web search, and web extraction connect agents to outside tools, while approved commands run inside a sandboxed environment that cannot touch the rest of your server. Feed it PDFs, web pages, notes, YouTube videos, Notion, Drive, Gmail, or Slack, then follow citations from any answer back to the source material it came from. Bring your own keys for the chat and indexing models you prefer, organize the team into workspaces with roles and access controls, and pick up any conversation from the web app or desktop clients. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
LLM Wiki v2
Instead of burying your documents in a vector index you cannot inspect, LLM Wiki v2 files them into a Markdown wiki you can read, browse, and question. Drop text, Markdown, or PDF files anywhere on the page and each one is catalogued automatically, filed into a folder that says what it holds, and linked to the notes it relates to. Ask a question and the answer cites the exact notes it used, with clickable sources you can open, verify, and correct. New documents update the note on their subject instead of piling up as disconnected chunks, so what you teach it stays taught. A small classifier routes filing and questions through the folder tree, keeping the wiki quick and cheap as it grows, and you can browse the tree, follow see-also links, move or delete notes, and watch the tokens spent by both the model and the classifier. Connect OpenRouter, OpenAI, Gemini, a local Ollama, or any compatible endpoint, and expose the same wiki to Claude Code or Codex as long-term memory they can recall from and write to. Because every note is plain Markdown in a folder you own, the whole knowledge base can live in git beside your other files. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
CaseCite
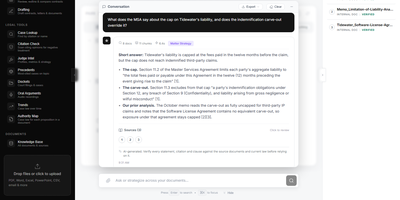
CaseCite puts a law firm's own files under questioning, returning cited answers, contract reviews, and drafted agreements without surrendering a single document to an outside legal platform. Ask a question across the indexed corpus and receive answers tied to the exact source passage, then narrow the search to selected files or a folder when only those should count. For bigger questions, deep research lays out a plan of sub-questions you can edit first, verifies every quote against its source, and keeps a step log of what was searched. Contracts can be analyzed, questioned one at a time, or compared clause by clause across two to four agreements against a baseline, with redlines exported as native Word tracked changes. Tabular review extracts the fields you define from hundreds of contracts at once, shows the supporting passage and estimated cost beside each value, and exports to Excel or CSV. Drafting starts from up to four precedent documents, and long agreements get a section plan for your approval before each section is written and reconciled. Each client engagement lives in its own matter workspace with controlled access and an activity feed, while case lookup, citation checking, judge analytics, dockets, oral arguments, and authority maps cover the caselaw side. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
eLabFTW
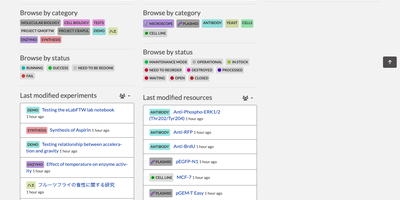
For research teams that need to show what was recorded and when, eLabFTW® is an electronic lab notebook that keeps experiments, lab inventory, and equipment bookings in one shared, searchable system. Each experiment holds rich-text notes, tables, images, checkable steps, custom metadata fields, tags, statuses, and attached files. Templates turn a protocol you repeat into a one-click starting point. A separate resource database catalogs antibodies, plasmids, cell lines, chemicals, and instruments, and typing # in an experiment links straight to any of them. Compounds import from PubChem by CID or CAS number, arriving with formulas, identifiers, and hazard data. The inventory tree maps buildings and their sub-locations, records where each container is stored, and tracks quantity and unit. Book a microscope by dragging a slot on the scheduler, and permissions decide who may reserve what. Entries can be signed with Ed25519 keys and timestamped through RFC 3161 authorities such as DFN, Digicert, and GlobalSign, or anchored on the Bloxberg blockchain; a timestamp archive can never be edited or deleted. Export to PDF, ZIP, CSV, JSON, or .eln archives, and import .eln or CSV files when moving from spreadsheets or another notebook. Users sign in locally or through SAML2 or LDAP, and an API with per-user keys lets instruments and scripts read and write entries. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Local Deep Research
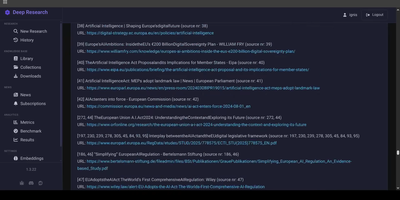
Execute comprehensive multi-angle investigations across scientific journals and web repositories using Local Deep Research, an autonomous intelligence engine designed for researchers, analysts, and knowledge workers. Users can submit complex analytical questions through a self-hosted web console to initiate agentic research cycles powered by LangGraph workflows. The application dynamically queries search providers including SearXNG, arXiv, PubMed, Wikipedia, and Google, iteratively evaluating discovered content to formulate targeted follow-up queries. Discovered academic papers and web sources can be indexed into an encrypted personal library to combine internal documentation with external search intelligence. Reports are synthesized with structured outlines, section headings, and verifiable academic citations that link directly to source references. Individual research sessions, system logs, and user credentials remain isolated in per-user SQLCipher databases protected by AES-256 encryption. Automated subscriptions deliver scheduled news digests and topic monitoring summaries directly to connected notification channels. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.