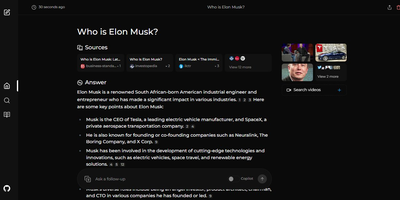
Vane
Perplexity's search experience without Perplexity: Vane deploys Perplexica, an open-source AI answer engine built as the self-hosted alternative. Instead of returning a page of links, it reads your question, searches the live web through the SearxNG metasearch engine, and composes a direct answer with cited sources. Retrieval quality comes from embeddings and similarity search: fetched pages are re-ranked against the query so the model answers from the most relevant passages rather than whatever ranked first. Two query modes cover different needs - Normal mode runs a straightforward web search, while Copilot mode generates multiple reformulated queries and actively pulls content from top matches for harder questions. Focus modes specialize retrieval for academic papers, YouTube, Reddit discussions, Wolfram Alpha calculations, or the general web. The answering model is your choice: OpenAI-compatible APIs or fully local LLMs such as Llama 3 and Mixtral through Ollama, which keeps queries entirely on your infrastructure. Because SearxNG pulls live results, answers reflect current information, and no search history is tracked.
SearXNG
Up to 280 search services - Google, Bing, DuckDuckGo, Brave, Qwant, Startpage - aggregated without tracking or profiling: SearXNG is a privacy-respecting metasearch engine (AGPL-3.0, successor to Searx). Your instance queries the upstream engines on your behalf: your IP address, cookies, and search history never reach them, tracker parameters are stripped from result URLs, and an optional image proxy fetches thumbnails server-side so result pages leak nothing. It can even route outbound queries through Tor for full anonymity. Search is organized into categories - general, images, videos, news, maps, music, IT, science, files - with bang shortcuts for targeting specific engines, and every source can be enabled, disabled, or weighted per category in settings.yml. A plugin system adds calculators, hash tools, tracker removal, and unit conversions inline, and preferences (themes, safe search, languages, engine selection) persist in cookies rather than server-side accounts. The real argument for running your own instance rather than trusting a public one is control: you decide the logging policy (none), the engine mix, rate limiting, and who gets access - making it the default search backend for browsers, families, and teams that want Google-quality results without the profile.
Manticore Search
With nearly 12,000 GitHub stars and a lineage tracing back to Sphinx Search, Manticore Search is the C++ search database that delivers the full-text, vector, and hybrid search capabilities of Elasticsearch at a fraction of the resource cost — starting in under a second and consuming just 40MB RAM for an empty instance. The SQL-first interface speaks the MySQL wire protocol, meaning mysql client, MySQL Workbench, and any MySQL-compatible driver connects natively without adapters, while the HTTP JSON API provides RESTful access for modern applications. Over 20 full-text operators handle proximity search, quorum matching, field-start and field-end constraints, MAYBE operators, and regex patterns, backed by stemming, lemmatization, stopwords, synonyms, wordforms, and advanced morphology in 70+ languages. Vector search with HNSW indexing enables semantic similarity queries, and hybrid mode combines keyword relevance with vector distance in a single ranked result set using a cost-based query optimizer. Real-time indexing delivers sub-second document availability after insert, sharded tables distribute data across nodes, and Galera-based synchronous replication ensures high availability. Conversational search via CREATE CHAT MODEL and CALL CHAT integrates LLM-backed responses with KNN retrieval and conversation history directly inside the database. Client libraries ship for PHP, Python, JavaScript, TypeScript, Java, Go, Rust, and Elixir. Columnar storage via the Manticore Columnar Library handles analytical workloads on large datasets. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPLv3 licensed.
Redis
Processing billions of operations per second across companies like Twitter, GitHub, Snapchat, and Stack Overflow, Redis is the world's fastest and most widely deployed in-memory data store. Redis 8 unifies previously separate modules into a single distribution: RediSearch for full-text indexing with BM25 scoring and vector similarity search via HNSW and FLAT algorithms, RedisJSON for native JSON document storage with JSONPath queries, RedisTimeSeries for timestamped data with configurable downsampling compaction rules, and RedisBloom for probabilistic data structures including Bloom filters, cuckoo filters, count-min sketches, top-k, and t-digest. The core engine provides strings, lists, sets, sorted sets, hashes, streams, HyperLogLog, bitmaps, bitfields, geospatial indexes, and the new array data structure introduced in Redis 8.8. Pub/Sub delivers lightweight real-time messaging between publishers and subscribers, while Streams provide an append-only log with consumer groups for event sourcing and complex consumption patterns. Redis Cluster distributes data across nodes with automatic sharding using 16,384 hash slots, and Sentinel provides high availability with automatic failover monitoring. Lua scripting and Redis Functions enable server-side computation, and ACL-based security provides granular per-command, per-key access control. Official clients exist for Python, Node.js, Java, Go, .NET, Rust, and PHP. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
RAGFlow
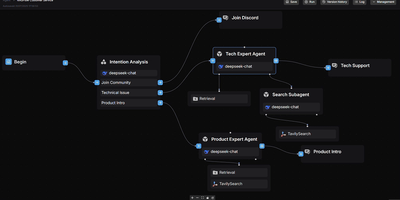
RAGFlow has established itself as one of the most widely adopted open-source RAG engines available, powering production AI systems that demand traceable, hallucination-free answers from complex enterprise data. The platform processes PDF, DOCX, Excel, and PPT files through vision-based deep document understanding with layout analysis and OCR, extracting structured knowledge from tables, charts, and images that simpler parsers miss entirely. RAGFlow's hybrid retrieval pipeline combines vector search with BM25 keyword matching and multi-stage reranking across configurable document stores including Elasticsearch, InfiniFlow's Infinity engine, OpenSearch, and OceanBase. Developers connect any combination of LLM providers — OpenAI, DeepSeek, Anthropic Claude, Google Gemini, and locally-hosted models via Ollama — through a unified configuration layer. The visual agent workflow system enables multi-step reasoning chains with persistent memory, tool calling, and pre-built templates for common enterprise scenarios. RAGFlow synchronizes data from Confluence, S3, Notion, and Google Drive, and delivers answers through chat integrations with Feishu, Discord, Telegram, and Line. The Python SDK and RESTful API on port 9380 provide programmatic access to knowledge base management, document parsing, and conversational retrieval. The full stack deploys via Docker Compose with MySQL for metadata, Redis for task orchestration, and MinIO for object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Elasticsearch
With over 70,000 GitHub stars and billions of documents indexed across enterprises like Uber, Netflix, and Wikipedia, Elasticsearch is the world's most deployed search engine, powering everything from application search to security analytics and AI-driven retrieval. Built on Apache Lucene, its inverted index architecture delivers sub-second full-text search across terabytes of data with BM25 relevance scoring, configurable analyzers for 30+ languages, and fuzzy matching for typo tolerance. The kNN vector search API uses the HNSW algorithm for approximate nearest neighbor queries on dense and sparse embeddings up to 4,096 dimensions, while reciprocal rank fusion enables hybrid search that combines lexical and semantic signals in a single query. Elasticsearch's aggregation framework supports metric, bucket, and pipeline aggregations for real-time analytics directly on indexed data without separate OLAP infrastructure. The cluster distributes data across shards with automatic rebalancing, replica allocation, and cross-cluster search for multi-datacenter deployments. Kibana provides the visualization layer with dashboards, Lens visual editor, Canvas for pixel-perfect reports, and Discover for ad-hoc log exploration. Ingest pipelines with processors like grok, dissect, GeoIP enrichment, and inference handle data transformation at index time, and ES|QL brings pipe-based query syntax with joins and columnar processing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
ZincSearch
ZincSearch runs full-text search as a single Go binary that consumes a fraction of the memory and CPU that Elasticsearch demands while staying API-compatible, earning 17,800+ GitHub stars as a lightweight alternative. The bluge-powered indexing library processes documents through analyzers, tokenizers, and token filters while maintaining Elasticsearch-compatible ingestion APIs for single-record and bulk operations, letting existing pipelines connect with minimal configuration changes. Schema-less document ingestion accepts JSON payloads without predefined mappings, allowing different documents within the same index to carry different field structures while the engine automatically detects and indexes field types. An embedded Vue.js web console provides a browser-based interface for creating indexes, querying with full-text syntax, browsing results with hit highlighting, managing users, and monitoring system status. A dual API architecture exposes native ZincSearch endpoints under /api alongside Elasticsearch-compatible endpoints under /es, supporting boolean operators, wildcards, phrase matching, fuzzy search, date ranges, and aggregation pipelines including terms, histogram, date histogram, and range aggregations. Multi-tenancy with user-level access control isolates data across teams. Official SDKs for Go, Python, and Node.js provide typed client libraries for programmatic integration. Deploys via Docker or direct binary download with no external dependencies beyond disk storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Chroma
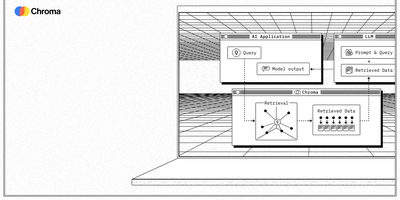
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Scira
Scira is an AI search engine that breaks complex research questions into sub-tasks, retrieves grounded answers from live sources, and cites every claim with clickable links to the original evidence. Formerly known as MiniPerplx and now backed by nearly 12,000 GitHub stars, the platform implements agentic research planning where language models decompose queries, select appropriate tools, retrieve information in parallel, and synthesize responses with inline citations. Seventeen distinct search modes cover Web, Academic, Extreme, X (Twitter), Reddit, GitHub, Stocks, Crypto, YouTube, and Prediction markets, each activating a curated subset of the 28 built-in tools. The Extreme mode deploys a deep research agent with multi-step planning, parallel source retrieval, code execution in sandboxed Daytona environments, and R2 artifact storage for generated charts. Model routing spans 50+ AI providers through a unified configuration layer supporting OpenAI, Anthropic, Google, xAI Grok, and custom models, with per-mode model assignment based on task requirements. The web search tool supports Exa, Tavily, and Firecrawl as interchangeable providers via a Strategy pattern. Lookouts schedule recurring research agents on cron schedules that monitor topics, track changes, and email summaries using Upstash QStash for reliable execution. PostgreSQL stores chat history, user preferences, and custom instructions while Redis handles caching and rate limiting. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
OpenSearch
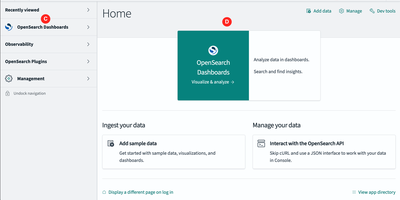
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Docspell
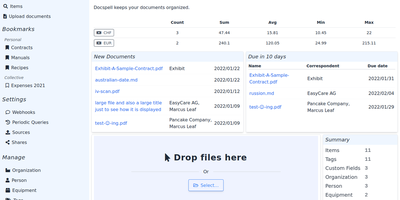
Convert paper archives, email attachments, and PDF records into an organized digital repository with Docspell, an open-source document management system that automates optical character recognition, metadata extraction, and full-text search. Users can ingest receipts and invoices through network scanners, monitored IMAP email mailboxes, mobile uploads, or drag-and-drop browser tools. The background processing pipeline executes optical character recognition via Tesseract, enhances image contrast with unpaper, and extracts text from Word documents and PDFs. Machine learning algorithms analyze document syntax to predict correspondents, suggest relevant organization tags, and identify due dates automatically. Team members can search their entire filing cabinet using complex Boolean queries and full-text indexing powered by Apache Solr or PostgreSQL. Administrators can configure multi-user collectives with isolated permissions, define custom metadata attributes, set up webhooks, and share time-limited document download links. Users can also merge multi-page scans, track processing job queues, and export curated document collections for tax filings or legal audits. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPL v3.0 licensed.
Quickwit
With over 11,000 GitHub stars and now backed by Datadog while remaining fully Apache 2.0 licensed, Quickwit delivers the search performance Elasticsearch users expect at a fraction of the infrastructure cost by moving the index to object storage instead of expensive local SSDs. The Rust-based engine, built on the Tantivy search library with SIMD-accelerated vectorized processing and zero garbage collection overhead, achieves sub-second search latency directly against Amazon S3, Azure Blob Storage, Google Cloud Storage, or any S3-compatible backend like MinIO and Ceph. The Elasticsearch-compatible REST API covers ingest, search, query DSL, and aggregations, enabling existing log shippers including Vector, Fluent Bit, and Syslog to migrate without rewriting configurations. Native OpenTelemetry Protocol endpoints accept logs and traces via gRPC, while Jaeger integration provides a drop-in distributed tracing backend. Ingestion from Apache Kafka, Amazon Kinesis, and Apache Pulsar supports streaming pipelines with multi-index partitioning, and the schemaless JSON indexing mode eliminates the need for upfront schema definitions. Stateless searchers and indexers scale horizontally on Kubernetes or bare metal, with a control plane that distributes indexing tasks and a janitor that manages retention policies and GDPR-compliant deletions. The built-in web UI displays search results and cluster state, while the official Grafana data source enables log exploration dashboards. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Websurfx
Websurfx aggregates results from multiple search engines into one private, ad-free interface that never tracks your queries. Written in Rust, the backend provides memory safety against buffer overflows and data races at the language level while handling concurrent requests across upstream providers like DuckDuckGo and Searx. A built-in re-ranking algorithm scores and merges results by relevance, producing a unified page that draws from many sources while appearing as one coherent search. Safe-search filtering operates across four levels from unrestricted to complete content blocking, with regex-based filter lists for parental controls in schools and organizations. Upstream requests route through configurable proxy chains or Tor, preventing search providers from correlating your queries with a specific IP address. Four Docker image variants target different caching strategies: hybrid Redis plus in-memory for maximum throughput, Redis-only, in-memory-only, or zero-persistence for environments where cached queries must never touch disk. The Lua configuration file controls engine selection, request timeouts, rate limiting thresholds, and production-mode delays that throttle upstream traffic to prevent abuse. Quick-result widgets handle calculations, currency conversions, and unit transformations inline without external redirects. Image search capabilities serve visual discovery for designers and researchers who need media results without surveillance. Runs on a RepoCloud VPS with dedicated resources and full root access. AGPL-3.0 licensed.
Farfalle
Live web search plus an LLM of your choice: Farfalle is an open-source, self-hosted answer engine in the Perplexity mold. Queries route through one of several search providers - self-hosted SearXNG for a fully independent stack, or Tavily, Serper, and Bing APIs - and the model composes a cited answer from the retrieved results. Model flexibility is the core design: run llama3, mistral, gemma, or phi3 locally through Ollama for zero per-query cost and full privacy, use cloud models like GPT-4o or Groq-hosted Llama 3 for speed, or route to any provider via LiteLLM. An Expert Search mode uses an agent that plans a multi-step search strategy and executes it for harder questions, and chat history keeps prior research sessions available. The stack is a Next.js and shadcn/ui frontend over a FastAPI backend with Redis rate limiting, shipped as a pre-built Docker image. A browser search-engine entry pointing at your instance makes it the default search from the address bar. Paired with SearXNG and Ollama, the whole pipeline runs with no external API at all.