Para
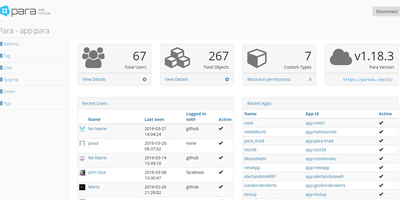
The name means steam in Bulgarian, and the job matches: Para is the boiler room that powers your application's backend so you never build one from scratch. You store plain JSON objects through a REST API and get them back persisted, indexed for full-text search, and cached on every write, without designing schemas or gluing three systems together yourself. One server hosts many applications at once, each with its own table, search index, and cache, so a client project, a side app, and an internal tool can share a single deployment without sharing data. Users sign in with social accounts, LDAP, or SAML and receive JSON Web Tokens, while resource permissions decide exactly which objects each client may touch. Queries go beyond key lookups: field, wildcard, geo point, and more-like-this searches all run against the same stored objects. Signed webhooks notify your own endpoints when data changes, and an MCP server lets AI assistants manage configuration, data, and search against the same backend. The admin Web Console handles users, objects, backups, and permissions from the browser, and client libraries cover JavaScript, PHP, Java, C#, Android, and iOS. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Knowhere
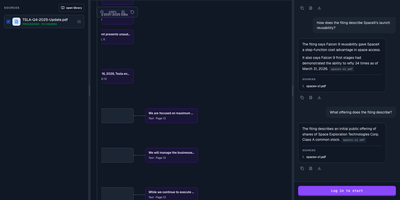
With 2,600+ GitHub stars since its May 2026 open-source launch, Knowhere solves the last-mile problem of document intelligence for AI systems — transforming complex unstructured PDFs, reports, and multi-page documents into structured JSON chunks that LLMs can consume without hallucination. The platform processes documents through an AI-native parsing pipeline that handles 20+ page documents with deep hierarchies, intricate tables, and multimodal content including images with OCR, achieving 95% precision in information extraction while reducing token costs by 50% compared to raw document ingestion. The knowledge tree architecture maintains historical context across multiple documents, enabling cross-document graph navigation for agentic retrieval that goes beyond simple chunk-based RAG. Built on Python 3.11+ with MinerU as the default PDF parser, the backend API runs alongside async workers that process document ingestion, graph construction, and embedding generation. The self-hosted Docker Compose stack packages the API server, processing workers, and Next.js dashboard for managing API keys, webhooks, and document-processing jobs, backed by PostgreSQL and Redis. Both Python and Node.js SDKs provide programmatic access for integration into existing AI pipelines and agent frameworks. LLM providers include DeepSeek and Alibaba Cloud DashScope with configurable key rotation for rate-limit management. Deploy on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.