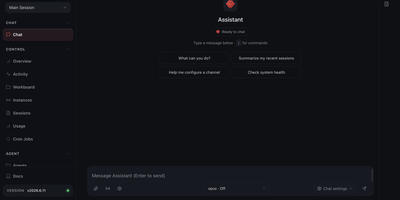
OpenClaw VPS
A personal AI assistant that remembers what it learns and reaches you wherever you are — OpenClaw is an open-source agent gateway built by the OpenClaw Foundation with 247,000+ GitHub stars. It connects to 200+ LLM models through providers like Anthropic, OpenRouter, and OpenAI, and meets you on 21+ messaging channels: Telegram, Slack, Discord, WhatsApp, Signal, iMessage, Matrix, and more. Persistent memory with full-text search lets the agent recall context across sessions, and a self-improving skills system means it gets more capable the longer it runs. Voice wake words and talk mode enable hands-free interaction on macOS, iOS, and Android. A live canvas provides an agent-driven visual workspace. Built-in browser automation, cron scheduling for unattended tasks, and subagent spawning for parallel workstreams round out the toolset. The gateway architecture keeps all sessions, credentials, and conversation history on your own server — nothing transits a third-party cloud unless you choose to connect one. The API key you provide for your chosen LLM provider powers the underlying calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
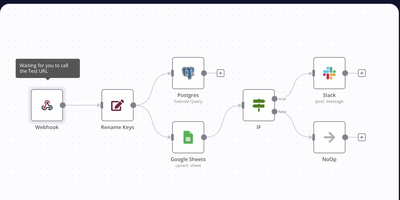
n8n
Webhooks, cron schedules, and app events trigger chains of nodes that fetch, transform, and route data: n8n is a workflow automation platform built around a visual, node-based editor. It ships with 400+ built-in integrations covering databases like Postgres, SaaS tools like Slack and HubSpot, and every major AI provider. When a pre-built node does not exist, the HTTP Request node calls any REST API, and the Code node runs JavaScript or Python inline, so you are never blocked by a missing connector. Workflows execute as directed graphs with branching, loops, error handling, and sub-workflows, and every run is logged for inspection and replay during debugging. It also includes LangChain-based nodes for building AI agents with tool calling and memory. Self-hosting on RepoCloud gives you unlimited workflow executions with no per-task pricing, and all data stays on your instance. Runs on Node.js with SQLite by default; add Postgres and Redis queue mode when you need to scale workers horizontally.
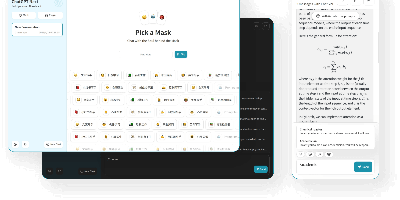
NextChat
Thirteen-plus LLM providers, one unified client: NextChat (formerly ChatGPT-Next-Web) is an open-source AI chat interface built on Next.js that spans OpenAI GPT-4, Anthropic Claude, Google Gemini, DeepSeek, Groq, Azure endpoints, and self-hosted backends like Ollama, LocalAI, and RWKV-Runner. Its defining trait is minimalism - the first screen loads in about 100 KB, the desktop client is roughly 5 MB, and there is no database or user system to operate; chat history lives locally in the browser with optional WebDAV or UpStash Redis sync. The Mask system saves reusable prompt-template personas you can share and debug, long conversations auto-compress to fit context windows, and Markdown rendering covers LaTeX, Mermaid diagrams, and code highlighting with streaming responses. Plugins add web search and calculators, MCP support enables external tool calling, and Artifacts previews generated content in a separate pane. Ships as a web app, Docker image, and Tauri desktop builds for Windows, macOS, and Linux, translated into 20+ languages. MIT-licensed.
Hermes Agent
OpenRouter's most-used application by token volume — over 17 trillion tokens processed — Hermes Agent is an open-source autonomous agent built by Nous Research that lives on your server and gets more capable every day. Define a goal in natural language and Hermes plans sub-tasks, executes them through tool integrations, observes results, handles errors, and refines until the job is done or it genuinely needs your input. Persistent memory with full-text search and LLM summarization lets it recall context across sessions, and an agent-created skills system self-improves after complex tasks. A messaging gateway connects Telegram, Discord, Slack, WhatsApp, Signal, and 16 more platforms with cross-channel conversation continuity. A built-in cron scheduler runs daily reports, nightly backups, and weekly audits unattended. Subagent spawning parallelizes workstreams, and six terminal backends — local, Docker, SSH, Singularity, Modal, and Daytona — fit any infrastructure. Works with any LLM provider: Nous Portal, OpenRouter for 400+ models from 70+ providers, OpenAI, Anthropic, or your own endpoint. The API key you supply powers all LLM calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Odoo
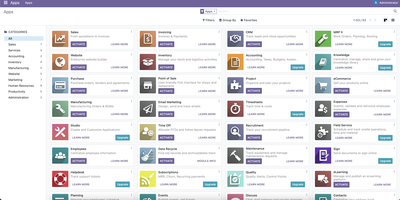
Roughly 40 integrated business apps forming a full ERP: Odoo's open-source suite runs companies end to end. The Community Edition, licensed LGPL-3.0, ships roughly 40 apps covering CRM, sales, invoicing, basic accounting (journals, chart of accounts, taxes, reconciliation), inventory and warehouse management with multi-step routes, manufacturing with BOMs and work orders, purchasing, project management, timesheets, HR, a website builder, and eCommerce. Each app works standalone, but they share one PostgreSQL database and one data model, so a confirmed sale updates stock, triggers procurement, and posts invoices without integration glue. The modular design means you enable only the apps you need and extend with 40,000+ community modules from the Odoo app store covering nearly any vertical requirement. Inventory supports multi-warehouse stock, reordering rules, and lot and serial tracking with barcode-ready operations; manufacturing ties BOMs, work orders, and work-center routing directly to sales demand and stock levels; and the website builder sells straight from your product catalog with payment provider integrations. You can start with just CRM and invoicing on day one and switch on inventory or eCommerce later - new apps integrate with existing data instantly because the schema is shared. The server is Python with an XML/JavaScript view layer, and because data lives in plain PostgreSQL there is no proprietary format: you can query, back up, migrate, and extend business data directly, with unlimited users and no per-seat licensing - where enterprise ERP pricing is per user per month, headcount here costs nothing.
DeepSeek Harness
DeepSeek Harness gained over 60,000 GitHub stars within hours of its August 2026 launch, establishing itself as the first fully modular open-source agent runtime where literally every component is a swappable plugin. Built on the Cordis framework—a programming paradigm for spatiotemporal composability—dsh decomposes the entire agent stack into independently replaceable pieces: model adapters for DeepSeek, Anthropic, OpenAI, AWS Bedrock, Azure, and Google Gemini; tool registries covering bash execution, file system operations, web search, subagent delegation, and todo management; plus session stores, sandboxes, approval policies, orchestration loops, and the user interface itself. Four operating modes serve different workflows: Standard provides the full toolset, Code mode uses model-generated code to compose multi-round tool calls, Minimal strips down to a shell and editor for benchmarking, and Creator mode lets developers inspect the running runtime and test Cordis plugins in memory. The kernel handles plugin mounting, unmounting, and dependency resolution while typed events and services coordinate between components. Profiles and bundles allow the same codebase to produce entirely different products—a terminal coding agent, a browser-based workspace, a headless automation service, or an ACP/JSON-RPC endpoint—by swapping YAML configuration layers. Session history is stored as an append-only event stream for full trajectory replay, and project-level hooks on agent lifecycle events enable fine-grained behavioral customization. MCP client integration connects to external tool servers, while Agent Client Protocol enables programmatic orchestration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Elasticsearch
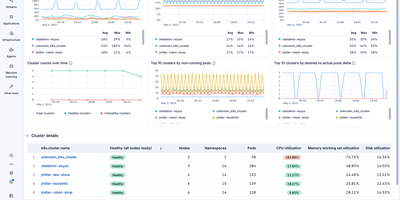
With over 70,000 GitHub stars and billions of documents indexed across enterprises like Uber, Netflix, and Wikipedia, Elasticsearch is the world's most deployed search engine, powering everything from application search to security analytics and AI-driven retrieval. Built on Apache Lucene, its inverted index architecture delivers sub-second full-text search across terabytes of data with BM25 relevance scoring, configurable analyzers for 30+ languages, and fuzzy matching for typo tolerance. The kNN vector search API uses the HNSW algorithm for approximate nearest neighbor queries on dense and sparse embeddings up to 4,096 dimensions, while reciprocal rank fusion enables hybrid search that combines lexical and semantic signals in a single query. Elasticsearch's aggregation framework supports metric, bucket, and pipeline aggregations for real-time analytics directly on indexed data without separate OLAP infrastructure. The cluster distributes data across shards with automatic rebalancing, replica allocation, and cross-cluster search for multi-datacenter deployments. Kibana provides the visualization layer with dashboards, Lens visual editor, Canvas for pixel-perfect reports, and Discover for ad-hoc log exploration. Ingest pipelines with processors like grok, dissect, GeoIP enrichment, and inference handle data transformation at index time, and ES|QL brings pipe-based query syntax with joins and columnar processing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
Flowise
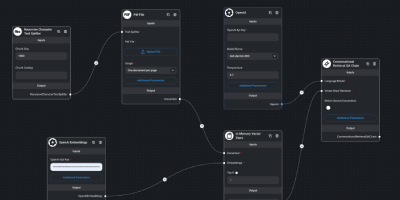
Drag nodes onto a canvas and ship an LLM app: Flowise is an open-source visual builder for AI agents and LLM applications, written in Node.js on LangChain.js and licensed Apache-2.0. You assemble flows by dragging nodes onto a canvas: models, prompts, memory, vector stores, retrievers, and tools, then wire them together and test in the built-in chat panel. Three builder types cover increasing complexity: Assistant for simple RAG chat over uploaded files, Chatflow for single-agent systems with techniques like rerankers and Graph RAG, and Agentflow for multi-agent orchestration with branching, looping, shared flow state, and human-in-the-loop checkpoints. Over 100 integrations connect data sources, vector databases, and both proprietary and open-source models, plus MCP client and server nodes for standard tool interop. Finished flows are exposed as REST APIs, embedded chat widgets, or via JS and Python SDKs - each flow gets an endpoint the moment it is saved, removing the deployment gap between a working prototype and something your application can call. Execution logs, visual step debugging, and external log streaming trace behavior, while input moderation and rate limiting act as guardrails; RBAC, SSO, and workspaces cover team deployments. Self-hosting keeps prompts, encrypted credentials, and conversation data on your own instance, which matters when flows handle internal documents or customer data - and wiring a model, prompt, memory, and vector store on the canvas replaces the boilerplate a hand-coded LangChain project would need.
Redis
Processing billions of operations per second across companies like Twitter, GitHub, Snapchat, and Stack Overflow, Redis is the world's fastest and most widely deployed in-memory data store. Redis 8 unifies previously separate modules into a single distribution: RediSearch for full-text indexing with BM25 scoring and vector similarity search via HNSW and FLAT algorithms, RedisJSON for native JSON document storage with JSONPath queries, RedisTimeSeries for timestamped data with configurable downsampling compaction rules, and RedisBloom for probabilistic data structures including Bloom filters, cuckoo filters, count-min sketches, top-k, and t-digest. The core engine provides strings, lists, sets, sorted sets, hashes, streams, HyperLogLog, bitmaps, bitfields, geospatial indexes, and the new array data structure introduced in Redis 8.8. Pub/Sub delivers lightweight real-time messaging between publishers and subscribers, while Streams provide an append-only log with consumer groups for event sourcing and complex consumption patterns. Redis Cluster distributes data across nodes with automatic sharding using 16,384 hash slots, and Sentinel provides high availability with automatic failover monitoring. Lua scripting and Redis Functions enable server-side computation, and ACL-based security provides granular per-command, per-key access control. Official clients exist for Python, Node.js, Java, Go, .NET, Rust, and PHP. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Dify
Dify turns the notoriously complex process of building production-grade AI applications into a visual drag-and-drop experience that teams can actually ship and maintain. With over 87,000 GitHub stars and backing from prominent investors, the platform has become the go-to open-source LLMOps solution for organizations that refuse to be locked into proprietary AI stacks. The visual workflow canvas lets developers wire together LLM calls, conditional logic, iteration loops, tool invocations, and human-in-the-loop checkpoints without writing boilerplate integration code. Its RAG pipeline engine handles the full document lifecycle from ingestion of PDFs, Word documents, and HTML through configurable chunking strategies, embedding with models from OpenAI or open-source alternatives, vector storage in Weaviate, Qdrant, Pinecone, or pgvector, and hybrid semantic-plus-keyword retrieval with citation tracking. Dify integrates with hundreds of model providers including OpenAI GPT-4o, Anthropic Claude, Google Gemini, Mistral, Llama, and any OpenAI-compatible endpoint like Ollama for fully local inference. The agent framework supports both ReAct and function-calling strategies with 50-plus built-in tools spanning Google Search, DALL-E, Stable Diffusion, WolframAlpha, and custom API definitions. Published apps can be deployed as hosted web interfaces, embedded chat widgets, REST API endpoints, or MCP-compatible tools. Enterprise features include role-based access control, SSO integration, and audit logging. A built-in marketplace enables teams to share and reuse model providers, tools, and workflow templates across projects. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed with an open-source community edition.
Open WebUI
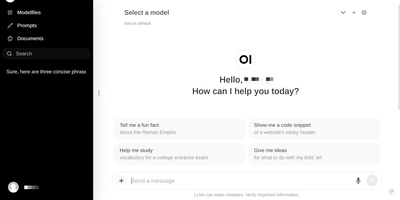
Large language models get a polished front end that can run fully offline: Open WebUI is the self-hosted front end of choice. It talks to local model runners, primarily Ollama, and to any OpenAI-compatible API, so LM Studio, vLLM, Groq, Mistral, OpenRouter, and cloud providers all plug into the same chat interface and can be mixed per conversation. RAG is built in: upload files to knowledge bases or reference them in chat with the # command, backed by a choice of nine vector databases (ChromaDB and PGVector officially maintained) and multiple extraction engines including Tika and Docling, with hybrid BM25-plus-vector search and cross-encoder reranking. Web search results from providers like SearXNG, Brave, and Tavily inject directly into conversations. Extensibility comes from Python tools and functions that run inside the chat, a Pipelines plugin framework, and native MCP support. Multi-user features include RBAC, SSO, and group permissions, and the instance itself exposes an OpenAI-compatible API your own apps can call.
Apache Superset
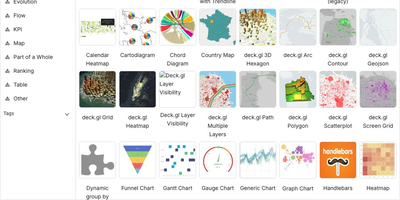
Powering data analytics at companies like Airbnb, Twitter, and Lyft where it originated, Apache Superset has become the leading open-source business intelligence platform with over 65,000 GitHub stars and an Apache Software Foundation top-level project designation. The platform ships with over forty visualization types out of the box including geographic maps, time-series charts, pivot tables, heatmaps, treemaps, and Sankey diagrams, all rendered with Apache ECharts for publication-quality output. Its SQL Lab provides a full-featured IDE experience with syntax highlighting, autocomplete, query history, and result caching for interactive data exploration. Superset connects natively to PostgreSQL, MySQL, ClickHouse, Trino, Presto, BigQuery, Snowflake, Apache Druid, Apache Hive, and dozens more databases through SQLAlchemy connectors, with support for custom database drivers via Python plugins. The semantic layer allows data teams to define calculated columns, metrics, and virtual datasets that business users can query without writing SQL. Role-based access control with row-level security enables fine-grained data governance, while the embedded analytics SDK lets you integrate dashboards directly into external applications via iframes with SSO pass-through. The caching layer supports Redis and Memcached for query result caching, and the asynchronous query execution engine powered by Celery handles long-running queries without blocking the UI. Alerts and reports can be scheduled via email or Slack with PNG or CSV attachments generated from any chart or dashboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Apache Airflow
With over 46,000 GitHub stars and one of the largest communities in data engineering, Apache Airflow is the workflow orchestration platform that lets teams define, schedule, and monitor complex data pipelines as Python code through directed acyclic graphs. Airflow 3.x introduced a modernized architecture with a task execution API, the Language Task SDK for writing task implementations in Java and Go alongside Python, asset-based partitioning with FanOutMapper and FixedKeyMapper for data-driven scheduling, a first-class state store for tasks and assets, pluggable retry policies, and a redesigned React-based web UI built on FastAPI. The provider ecosystem ships 80+ packages covering AWS, Google Cloud, Azure, Snowflake, Databricks, Apache Spark, Apache Kafka, PostgreSQL, MySQL, MongoDB, Slack, HTTP, SSH, Docker, Kubernetes, and dozens more, enabling a single deployment to orchestrate jobs across multi-cloud and on-premises infrastructure. The scheduler supports cron expressions, timetable plugins, data-aware scheduling triggered by asset events, and dynamic task generation through Python loops and conditionals. Built-in operators include BashOperator, PythonOperator, DockerOperator, KubernetesPodOperator, and sensor operators that poll external systems. The web UI provides DAG visualization with Gantt charts, grid views, and graph views, task instance logs, SLA monitoring, connection and variable management, and role-based access control. Deployment options include standalone mode, Docker Compose with CeleryExecutor or KubernetesExecutor, Helm charts for Kubernetes, and managed cloud services. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache License 2.0 licensed.
LobeHub
With over 82,000 GitHub stars and 700,000+ downloads, LobeHub has evolved from its origins as LobeChat into a comprehensive multi-agent AI collaboration platform where humans and autonomous agent teams co-evolve. The platform's Agent Harness architecture functions as an operating system between AI models and applications, handling prompt presets, tool orchestration, lifecycle hooks, planning, filesystem access, and sub-agent management across 25+ model providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Mistral, Groq, AWS Bedrock, Azure OpenAI, and local models through Ollama. Agent Groups enable sophisticated collaboration with sequential, parallel, iterative, and debate orchestration modes, allowing multiple specialized agents to tackle complex workflows simultaneously. The Agent Builder creates production-ready agents from natural language descriptions with auto-configuration, drawing from a marketplace of 505+ pre-built agents and 10,000+ MCP-compatible skills and plugins. Pages provide collaborative document editing with multi-agent co-authoring, while Schedules automate agent runs around the clock without human supervision. The knowledge base leverages PostgreSQL with pgvector for RAG-powered retrieval, and Personal Memory gives agents transparent, editable context that evolves through continual learning. The full self-hosted stack deploys via Docker Compose with PostgreSQL, Redis, RustFS for S3-compatible storage, and SearXNG for private web search, all configurable through environment variables. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. LobeHub Community licensed.
Lobe Chat
A private ChatGPT built with Next.js: Lobe Chat is the open-source AI chat interface teams self-host instead. Its main advantage is provider breadth: one interface connects to 40+ model providers, including OpenAI, Anthropic Claude, Google Gemini, Mistral, Groq, AWS Bedrock, Azure, and local models served through Ollama, so you can switch models per conversation and compare outputs. It handles multi-modal work: image recognition, image generation, text-to-speech, and speech-to-text. A plugin system based on function calling and the Model Context Protocol (MCP) adds external tools like web search and code execution. Run it in standalone mode as a single container with settings in browser storage, or in database mode with PostgreSQL and S3-compatible storage for persistent history, multi-user auth, and RAG knowledge bases built from uploaded documents with pgvector retrieval. Because tools arrive through function calling and MCP rather than a proprietary plugin format, custom internal tools can be exposed to the assistant with a standard server over STDIO or HTTP. Hundreds of pre-configured assistant roles import from the community marketplace. For teams the cost model matters: provider API keys billed per token typically undercut a ChatGPT Plus seat per person, and self-hosting keeps API keys, uploaded files, embeddings, and conversation history entirely on your own server.
ComfyUI
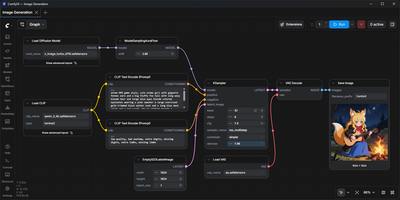
With over 126,000 GitHub stars and adoption across professional studios, research labs, and independent creators, ComfyUI has become the most widely used node-based interface for generative AI workflows — supporting image, video, audio, and 3D content creation through a single visual canvas. The graph editor natively supports Stable Diffusion 1.5, SDXL, SD3.5, Flux.1, Flux.2, HunyuanDiT, Lumina Image 2.0, HiDream, Qwen Image, and Pixart for image generation, plus Wan 2.1 and 2.2, LTX-Video, HunyuanVideo 1.5, CogVideoX, and Mochi for video, ACE-Step and Stable Audio for audio, and Hunyuan3D 2.0 for 3D models. Built-in tools handle inpainting, outpainting, ControlNet conditioning, LoRA and Hypernetwork loading, ESRGAN upscaling, area composition, model merging, and GLIGEN spatial control without writing code. The execution engine implements asynchronous queue processing with partial graph re-execution, running only changed nodes between iterations, and smart VRAM management that offloads models on GPUs with as little as 1 GB of memory. API nodes optionally connect to closed-source models through Comfy API while the core runs fully offline. Reusable subgraphs and App Mode expose complex workflows as simplified interfaces for non-technical users. The V3 custom node schema enables stateless execution with async support and process isolation. The TypeScript and Vue frontend ships as a PyPI package with stable releases every two weeks. Workflows save as JSON and embed in generated PNG, WebP, and FLAC files for reproducibility. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL v3.0 licensed.
Apache Kafka
Used by over 80% of Fortune 100 companies including LinkedIn, Netflix, Uber, and Goldman Sachs, Apache Kafka processes trillions of messages per day as the world's most widely deployed distributed event streaming platform. Since version 4.0 released in March 2025, Kafka operates exclusively with KRaft consensus, replacing Apache ZooKeeper entirely with an internal Raft-based metadata quorum managed by controller nodes, reducing operational complexity and eliminating external coordination dependencies. Topics are organized as append-only partitioned commit logs with configurable replication factors across brokers, delivering network-limited throughput with end-to-end latencies as low as 2 milliseconds. Kafka Streams provides a client library for building stateful stream processing applications with exactly-once semantics, windowed aggregations, joins across streams and tables, and interactive queries against local state stores. Kafka Connect integrates with hundreds of systems including PostgreSQL, MySQL, Elasticsearch, Amazon S3, MongoDB, HDFS, and JMS through a standardized connector framework with distributed worker mode and automatic offset management. Share Groups introduced in version 4.2 deliver queue-style consumption semantics alongside traditional consumer groups, enabling Kafka to serve both pub-sub and point-to-point messaging patterns natively. The Schema Registry enforces Avro, Protobuf, and JSON Schema compatibility rules across producers and consumers, preventing schema evolution from breaking downstream applications. Tiered Storage offloads older log segments to object storage like S3 while maintaining transparent consumer access, dramatically reducing local broker storage costs for long-retention topics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Excalidraw
Half the architecture sketches on the internet trace back to Excalidraw - the MIT-licensed virtual whiteboard whose hand-drawn aesthetic made technical diagramming feel approachable, at roughly 85,000 GitHub stars. The infinite canvas offers rectangles, ellipses, diamonds, arrows with smart binding and labels, free-draw, text, images, and an eraser, with full undo/redo, zoom, dark mode, and keyboard-first ergonomics. Community shape libraries add thousands of pre-built elements - AWS architecture icons, flowchart stencils, UI wireframe kits - and everything exports to PNG, SVG, the clipboard, or the open .excalidraw JSON format that keeps drawings diffable and portable. Live collaboration works on a share-a-link model with live cursors and a laser pointer for presenting, and it is end-to-end encrypted by design: the room key travels in the URL hash, which never reaches the server, so the WebSocket relay only ever sees ciphertext. The architecture is remarkably light - the app is a static bundle served by Nginx, drawings persist locally in the browser, and the stateless excalidraw-room relay handles multiplayer - so a self-hosted deployment gives unlimited boards and collaborators with near-zero resource cost, replacing per-editor whiteboard subscriptions.