Rivet
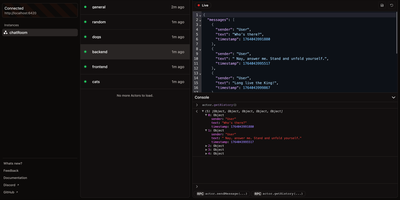
Stateful serverless actors that run indefinitely, sleep when idle, and persist state across restarts without external database round trips. Rivet provides a vendor-neutral alternative to Cloudflare Durable Objects, delivering long-running processes with co-located in-memory state and per-actor SQLite databases on any infrastructure you choose. The Rust engine comprises four packages: Pegboard for actor orchestration, Gasoline for durable execution, Guard for traffic routing via Envoy, and Epoxy implementing multi-region KV storage through EPaxos consensus. Each actor maintains instant-access in-memory state plus a dedicated SQLite database for relational queries, backed by RocksDB on single nodes or PostgreSQL with NATS pub/sub for multi-node clusters. RivetKit SDKs in TypeScript, Rust, and Python support built-in WebSocket connections, task queues, scheduling, and CRDT-based real-time collaboration. The v2.3 rewrite moved the core runtime from JavaScript to native Rust via WebAssembly, eliminating main-thread blocking across Node.js, Bun, Deno, and Cloudflare Workers. A built-in dashboard provides actor inspection with real-time Prometheus metrics. Deploys as a single Docker container on port 6420 with optional PostgreSQL for persistence. Available on RepoCloud with a dedicated VPS under the Apache 2.0 license.
Open-Meteo
High-resolution weather forecasts became a free commodity because of Open-Meteo - and this deployment puts the whole open-source engine on your own infrastructure. The public open-meteo.com service aggregates national weather models (NOAA GFS, DWD ICON, ECMWF, Meteo-France, and others) into one consistent JSON interface; self-hosting gives you that same API without rate limits, third-party dependency, or usage metering. The architecture is two cooperating services: the API server exposes forecast endpoints fully compatible with Open-Meteo query parameters - latitude, longitude, hourly and daily variables like temperature, precipitation, wind, and radiation - while a background sync worker downloads fresh weather model data on a configurable interval into a shared persistent volume at /app/data, so forecasts stay current and survive restarts without re-downloading. You control which weather models to mirror, which variables to store, how much historical depth to keep, and how often to refresh - meaning a lean deployment can sync only the model and region you actually query. Responses are plain HTTP/JSON, so integration with dashboards, Home Assistant-style automations, agricultural monitoring, IoT fleets, or any application takes minutes. For anyone making thousands of forecast calls a day, replacing a metered weather API with your own instance turns a recurring bill into a flat infrastructure cost.
StackStorm
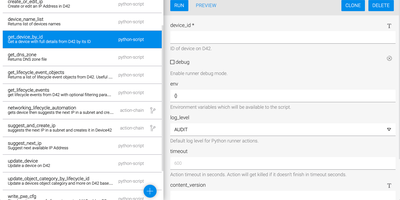
Sensors watch your infrastructure so your engineers do not have to watch it at 3 a.m. StackStorm is event-driven automation: Python sensors poll or listen to external systems (monitoring alerts, ticket updates, chat messages, webhooks, timers) and inject each event as a trigger. Rules match triggers against criteria you define and fire the response automatically, mapping the event payload straight into action parameters. Actions do the work: SSH commands, REST calls, and integrations for AWS, Docker, OpenStack, Puppet, Jira, Slack, and hundreds more from community packs, or your own scripts wrapped with a few lines of metadata. Multi-step responses become workflows that sequence actions with conditions, branching, and data passed between tasks, handling everything from disk-full remediation to full deployment pipelines. Everything bundles into packs, the shareable units that group sensors, rules, actions, and workflows per product or per automation, installable from the StackStorm Exchange or your own Git repositories. The web UI runs actions, explores workflow executions down to individual task results in real time, manages rules, and installs packs, while every execution, manual or automated, lands in an audit trail with its triggering context. ChatOps aliases even let the team trigger approved automations from chat. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Calibre-Web Automated
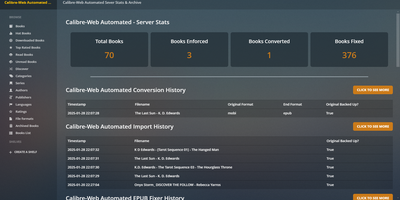
Turn any chaotic digital book archive into an autonomous, self-organizing reading portal using Calibre-Web Automated, a digital library manager featuring hands-free format conversions, metadata fetching, and e-reader synchronization. Readers can drop raw ebook files into the automated intake directory and watch the system instantly convert between twenty-eight distinct file types, repair malformed EPUB internal markup, and fetch enriched metadata from Hardcover, Kobo, and ISBN databases. The responsive web reader lets you browse collections, read directly in any desktop or mobile browser, and organize titles into dynamic rules-based Magic Shelves that update automatically. Built-in KOReader sync harmonizes reading progress and bookmarks across mobile devices and e-ink readers, while native OPDS feeds connect seamlessly to your favorite external reader applications. Administrative tools empower you to run hybrid SQL and fuzzy duplicate detection scans, perform batch metadata editing across entire series, enforce cover art changes directly into source files, and auto-dispatch newly ingested books to Kindle or Kobo devices via scheduled email delivery. Granular multi-user controls allow administrators to assign folder permissions, restrict downloads, enforce dark mode themes, and authenticate readers securely through OAuth and OpenID Connect identity providers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU General Public License v3.0 licensed.
GLPI
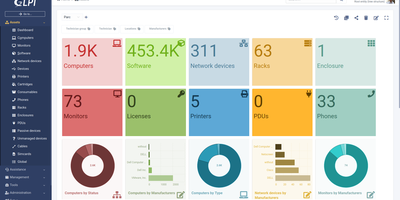
GLPI combines helpdesk ticketing, hardware inventory, license compliance, CMDB, and project management in a single PHP application with over 6,200 GitHub stars and 500,000+ Docker pulls, offering a unified ITSM platform that replaces ServiceNow, Freshservice, and ManageEngine without per-agent pricing. The ITIL-aligned service desk handles incidents, problems, changes, and service requests with configurable SLA management, approval workflows, satisfaction surveys, and business rules that automate ticket routing, escalation, and categorization. Native dynamic inventory through the GLPI Agent discovers Windows, Linux, and macOS endpoints with deep hardware profiling, while network discovery scans switches, printers, and infrastructure devices automatically. Software and license management tracks per-user and per-core license allocations with compliance reporting, expiration alerts, and financial cost tracking across the asset lifecycle from purchase through depreciation to disposal. Data center infrastructure management provides rack visualization with U-level positioning, PDU tracking, and connection mapping. The integrated forms editor builds custom request portals for end-users, while the self-service portal lets users submit tickets, browse the service catalog, and reserve assets. Webhooks trigger external HTTP calls on events, and the High-Level REST API v2 exposes every resource for automation. A plugin marketplace offers 90+ extensions for monitoring integration, advanced reporting, and authentication. Deploy via Docker with the glpi/glpi image alongside MySQL. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPLv3 licensed.
Zabbix
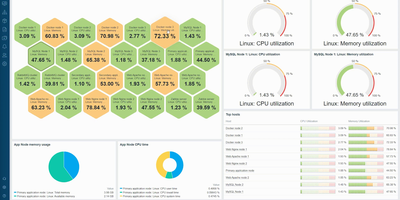
Monitoring everything from network switches to Kubernetes clusters since 2001 with over 6,200 GitHub stars and deployments exceeding 100,000 devices per installation, Zabbix has established itself as one of the most mature and feature-rich open-source monitoring platforms available, trusted by organizations including Dell, Salesforce, ICANN, and T-Mobile. The platform collects metrics from virtually any source using Zabbix Agent written in C, Zabbix Agent 2 written in Go with native plugin support, SNMP v1/v2c/v3 polling and trapping, IPMI for hardware health, JMX for Java applications, SSH and Telnet checks, HTTP/HTTPS polling, and ODBC database queries. Version 7.0 LTS introduced synthetic browser monitoring that executes user-defined JavaScript via WebDriver to simulate multi-step user interactions on websites, proxy load balancing with automatic host redistribution across proxy groups for high availability, in-memory proxy data buffering delivering up to 100x performance improvement, native multi-factor authentication with TOTP and Duo support, and just-in-time user provisioning from SAML and LDAP. Low-level discovery automatically detects file systems, network interfaces, SNMP OIDs, VMware resources, and Kubernetes pods, creating monitoring items and triggers dynamically. The alerting engine correlates events with configurable escalation chains, sending notifications through Slack, Microsoft Teams, PagerDuty, Jira, email, and SMS with customizable message templates. Over 1,000 official templates provide instant monitoring for Linux, Windows, VMware, AWS, Azure, Docker, PostgreSQL, MySQL, Apache, Nginx, and hundreds more. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
TrueForge
With over 2,100 GitHub stars in its first month and benchmarked at 30-75% lower cost than Claude Managed Agents on enterprise task suites, TrueForge is the open-source agent harness that provides the complete runtime layer for turning any LLM into a working production agent on your own infrastructure. The TypeScript server runs the full execution loop — streaming every step, routing tool calls through MCP servers with centralized header-auth and in-chat OAuth, delegating parallelizable work to isolated subagents, and pausing for human approval on sensitive actions. Context engineering keeps token costs low: deferred tool-schema loading delays MCP schemas until invoked, large-result offloading moves oversized outputs to files, Code Mode processes structured data through sandboxed execution, and automatic compaction summarizes older history at a configurable 50,000-token threshold while preserving the full transcript. The sandbox-as-a-tool architecture provisions isolated Daytona environments only when code execution is required, allowing one server to run many concurrent agents without idle overhead. Agents are configured from shipped YAML catalogs of models, MCP servers, git-backed SKILL.md instruction packs, and sandbox providers, then saved to an Agents Library accessible via the chat UI, TypeScript SDK, or embeddable React UI SDK. Run locally with SQLite via a single npx command, or deploy for teams with Docker Compose or Helm using Postgres and Redis with OIDC authentication. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Apache IoTDB
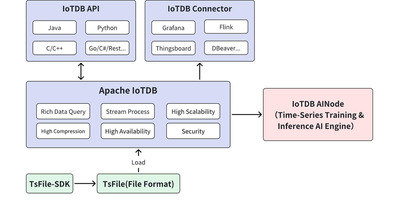
Sensors on factory floors, wind turbines, and connected vehicles produce readings every second, and Apache IoTDB is the time-series database built to store those readings and answer questions over them. Devices write through client sessions that tolerate out-of-order, delayed, and multi-frequency arrivals, so a gateway that reconnects after an outage can backfill history without corrupting the timeline. Series live in a device hierarchy you can browse like a directory tree, or in tables queried with standard SQL, common table expressions, set operations, and more than one hundred built-in aggregation and time-series functions. The TsFile columnar format shares one time column across aligned series and applies encodings designed for sensor data, which keeps high-frequency archives compact while Spark and Hadoop jobs read the same files directly for larger analysis. Pipe synchronization streams records or transfers whole TsFiles between edge sites and central clusters with path and device filtering, so plants keep collecting locally while headquarters queries a continuous copy. AINode brings forecasting, anomaly detection, and missing-value imputation into the database itself: register a model with SQL, then ask for predictions in the same query language instead of shipping measurements to a separate machine learning service. A low-memory Edge edition runs collection on constrained gateways, and clusters scale by adding DataNodes under ConfigNode coordination with automatic load balancing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
The Lounge
"Forget about bouncers" became a real sentence because of The Lounge: a Node.js web IRC client that holds persistent connections to your networks 24/7, logging everything while you sleep, so closing the browser tab never means missing a message or losing your place in a channel. Open it again from any device - desktop, phone, tablet - and you resume exactly where you left off, with full history synchronized. Because it combines bouncer and client in one process, the experience feels like a modern chat app rather than 1990s infrastructure: push notifications for highlights and private messages (with self-generated VAPID keys, so even Web Push needs no third-party service), automatic link previews, inline file and image uploads, and full IRCv3 protocol support. It installs as a progressive web app from any modern browser, so phones get a native-feel client without an app store. Multi-user support means one instance serves your whole team or community, each user with their own networks and history, and LDAP integration ties into existing authentication. A public mode alternatively serves as an open, registration-free web chat for events or support channels. MIT-licensed, born as a fork of Shout, and a fixture of self-hosting stacks since.
AgentsView
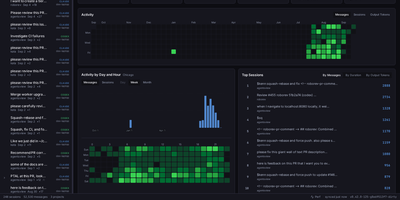
Software developers running Claude Code, Cursor, Codex, and Aider use AgentsView to trace token expenditures, search full session transcripts, and analyze multi-agent concurrency timelines. Engineers can search through historical developer sessions to locate specific code modifications, prompt chains, or debugging rationales across extensive programming workflows. The real-time activity timeline visualizes concurrent agent operations, revealing peak execution windows, task run durations, and automated tool invocations. The usage analytics engine calculates financial costs and token volumes per model by applying live pricing tables while accounting for prompt caching read discounts. Developers inspect granular turn-by-turn session transcripts complete with raw model payloads, file difference diffs, executed shell commands, and syntax errors. The recall browser extracts key technical context from past programming sessions, organizing facts into an indexed reference knowledge corpus for reuse across future project tasks. Administrators can replicate SQLite session tables into DuckDB analytics files or PostgreSQL warehouses to query longitudinal metrics using SQL analytical tools or custom reporting scripts. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
xyOps
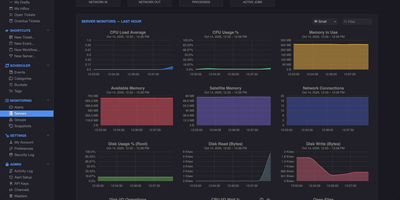
With 4,500+ GitHub stars and version 1.0.92 released August 2026, xyOps delivers a complete operations platform that unifies workflow automation, job scheduling, server monitoring, alerting, and incident response in one self-hosted system. The platform uses a distributed architecture where a central conductor coordinates lightweight xySat satellite agents running on Linux, macOS, or Windows worker nodes via persistent WebSocket connections. The visual workflow builder lets you chain events, triggers, actions, and monitors into multi-step pipelines with conditional logic, fan-out/fan-in parallelism, multiplex controllers for fleet-wide execution, and configurable resource limits. QuickMon provides per-second CPU, memory, disk, and network visibility streamed live to the web UI, while user-defined monitor plugins sample metrics every minute with time-series storage at hourly, daily, monthly, and yearly resolutions. Alert triggers evaluate expressions against live data and fire notifications via email, webhook, or custom actions, with full server snapshots attached showing every running process, network connection, and resource utilization at the moment of detection. Failed jobs and alerts automatically create tickets with linked logs, metrics history, and context for end-to-end incident tracking. The plugin marketplace supports extensions written in any language, and the Docker plugin enables container-based job execution. Deploy via Docker with persistent volumes on port 5522 for the web UI and 5523 for API access, running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD-3-Clause licensed.
GoToSocial
Mastodon serves single-user and small-community instances poorly; GoToSocial, an ActivityPub server written in Go, was built precisely for them. Where Mastodon demands Ruby, PostgreSQL, Redis, and Sidekiq, GoToSocial is one binary using roughly 250-350 MiB of RAM with SQLite as the default database (PostgreSQL optional) - it runs comfortably on a $5 VPS or a repurposed laptop. The deliberate design choice is having no built-in web client: the server exposes profile pages, a settings panel, and a faithful implementation of the Mastodon API, and you post through the client app you already like - Tusky on Android, Feditext on iOS, Pinafore or Phanpy in the browser. Federation is the point: your instance follows, boosts, and replies across Mastodon, Misskey, Pixelfed, and the rest of the Fediverse, with your identity anchored to your own domain. Safety is a stated focus, with granular per-post visibility and interaction controls, content warnings, custom emoji, hashtag following, domain allow/blocklists, and OIDC login support. Built-in Let's Encrypt provisioning simplifies the mandatory TLS. AGPL-3.0 licensed and in active beta, federating cleanly with the ecosystem's major servers.
Apache NiFi
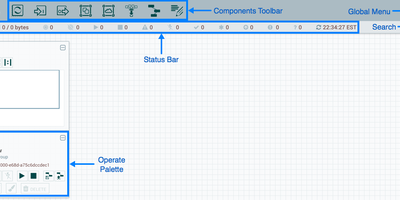
Deployed at thousands of enterprises across financial services, healthcare, government, and telecommunications, Apache NiFi is the industry-standard platform for building automated data pipelines through a visual drag-and-drop browser interface that requires zero coding for common integration patterns. The flow-based programming model connects over 300 built-in processors covering relational databases via ExecuteSQL and PutDatabaseRecord, Apache Kafka with PublishKafka and ConsumeKafka, HTTP endpoints through InvokeHTTP and ListenHTTP, cloud storage for AWS S3, Azure Blob, and Google Cloud Storage, SFTP/FTP file transfers, and JSON, XML, CSV, and Avro transformations. Data provenance tracking logs every routing decision, transformation, and delivery for every FlowFile, creating a searchable lineage graph from source to destination with full content replay capability for auditing and debugging. Guaranteed delivery uses configurable backpressure thresholds, prioritized queuing with latency or throughput optimization, and automatic retry with exponential backoff, ensuring no data loss even during downstream outages. The zero-leader clustering architecture distributes processing across nodes with automatic load balancing, while site-to-site protocol enables secure data transfer between NiFi instances across network boundaries. Security includes OpenID Connect and SAML 2.0 single sign-on, role-based access control with fine-grained policies per component, and TLS encryption for all communication. Custom processors can be written in Java and packaged as NAR bundles, or implemented directly in Python through the native scripting framework. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OpenCloud
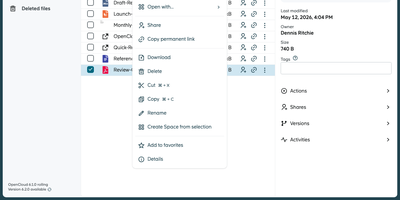
Organizations seeking complete data sovereignty over their documents, spreadsheets, and shared project folders can deploy OpenCloud as a self-hosted workspace for file sync, sharing, and real-time collaboration across web, desktop, iOS, and Android clients. Teams organize departmental assets inside dedicated Spaces where files belong to the project rather than individual user accounts, ensuring continuity when personnel change and enabling delegated space managers to assign granular read, edit, or upload permissions. Through built-in WOPI integration with Collabora Online, multiple colleagues can co-edit Microsoft Office and OpenDocument files simultaneously in the browser with automatic conflict locking and version history recovery. External partners and clients can access files via password-protected public links with custom expiration dates or upload deliverables into write-only File Drop folders without seeing existing directory contents. Cross-organization collaboration works seamlessly over the Open Cloud Mesh federation protocol, while full-text and tag-based search locates documents across personal and shared drives in seconds. Client devices synchronize changes in real time with support for virtual files on demand, resumable chunked uploads, and offline mobile access with camera document scanning. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Baserow
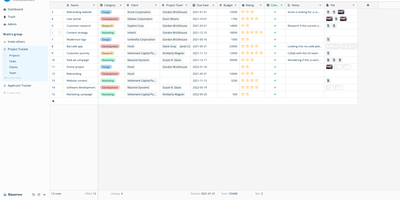
Airtable's spreadsheet-database model, self-hostable and open-source: that is Baserow. It presents data in a spreadsheet-style grid, but underneath each table is a real relational structure with typed fields, links between tables, filters, sorts, and multiple views (grid, gallery, form, kanban, calendar). Beyond the database core, it includes an application builder for composing pages and portals on your data, workflow automations, and dashboards. Everything is API-first: each table exposes a REST endpoint with token auth and webhooks, so it plugs directly into n8n, Zapier, or custom scripts. The stack is Django (Python) on the backend, Vue.js on the frontend, PostgreSQL for storage, with Redis for async tasks. Core features are MIT-licensed; premium features are a paid add-on. The self-hosted version has no row, storage, or API request limits - Airtable's per-base record caps and monthly API quotas simply don't exist here, and capacity is bounded only by your PostgreSQL database and disk. Existing Airtable bases, CSVs, and Excel files import directly with structure preserved, so migration doesn't start from a blank slate, and both the backend and frontend support plugins for custom field types and integrations without forking the core. For non-technical teammates the interface behaves like a spreadsheet; for engineers, the data model is the API.
Hister
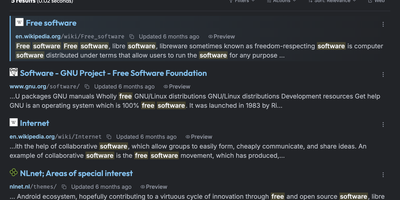
Hister is a private search engine for everything you have read or saved, indexing the full text of visited pages, local files, and imported browser history so one query finds the page you only half remember. Firefox and Chrome extensions capture each page as you browse, while a crawler and importers for browser history and bookmarks backfill earlier reading. Watched directories add local files to the same collection. Queries accept field filters, quoted phrases, wildcards, negation, date ranges, and aliases, with a readable stored preview beside each result. Opt-in semantic search matches documents by meaning through an Ollama, llama.cpp, or OpenAI-compatible embeddings endpoint. The same index answers in the browser, a terminal interface, the command line, an HTTP API, and an MCP server for AI assistants. Multi-user mode gives each person separate documents, rules, and access tokens, with password or OAuth sign-in, and public mode lets anonymous visitors search a curated index. Rebuild a research trail, recover a half-remembered article, or share one searchable knowledge base, with no telemetry. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
LightDash
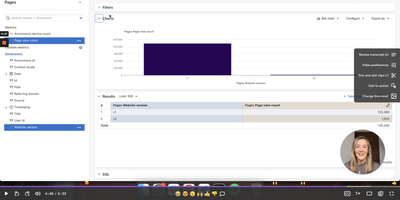
With 5,600+ GitHub stars and deep dbt integration, Lightdash is the open-source Agentic BI platform that treats analytics like software — defining metrics, dimensions, joins, permissions, and caching in a governed context layer that powers dashboards, AI agents, data apps, embedded analytics, and MCP server endpoints simultaneously. The dbt Write-Back feature lets business users create custom metrics and models in the UI, then automatically generates pull requests in GitHub or GitLab so every change flows through code review and CI validation before reaching production. Context-specific AI analysts automatically select relevant models and metrics, build queries, and present insights in plain English, while row-level security, user attributes, and customer-facing permissions ensure data governance at every layer. The platform connects to BigQuery, Snowflake, Redshift, Databricks, PostgreSQL, Trino, and ClickHouse through warehouse adapters, with the TypeScript monorepo built on React, Mantine, Vite, and TanStack Query on the frontend plus Node.js, Express, Knex, and PostgreSQL on the backend. Data teams build analytics with coding agents, preview changes from the CLI, validate in CI pipelines, and review charts and dashboards in pull requests — making the entire analytics lifecycle version-controlled and reproducible. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Passbolt
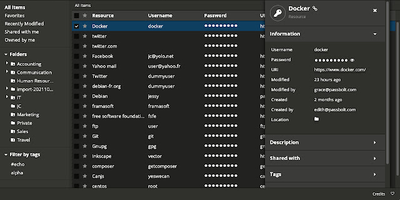
Security-conscious IT departments pick Passbolt for its cryptography: every user holds an OpenPGP key pair, and shared credentials are encrypted individually to each recipient's public key - real end-to-end encryption, not a vault password handed around. All crypto runs client-side in the mandatory browser extension (distributed and signed through the Chrome and Firefox stores, deliberately separating the crypto code from the server that stores ciphertext); private keys and passphrases never touch your instance, and the server admin cannot read a single secret. Authentication uses the challenge-based GpgAuth protocol, secrets are digitally signed to verify sender integrity, and metadata encryption extends protection to resource names and URLs. Day to day it behaves like a polished commercial manager: auto-fill and auto-save in forms, strong password generation, anti-phishing protection, TOTP storage, folder hierarchies shared per-user or per-group with fine-grained permissions and instant cryptographic revocation. Native iOS, Android, and desktop apps ship alongside a JSON API, CLI, and SDKs for CI/CD secret retrieval and rotation. The PHP server runs on MariaDB and is AGPL-licensed open source - including the paid tiers' codebase - with published security audits.