TencentDB Agent Memory
TencentDB Agent Memory provides a team-level memory hub that transforms AI agent conversations, documents, and codebases into four governed, shareable memory assets: Chat Memory for conversation history, Skills extracted from completed tasks, LLM-Wiki built from document ingestion, and Code-Graph generated from codebase analysis. The four-tier semantic pyramid structures long-term memory from L0 raw conversation capture through L1 episodic extraction and L2 scenario aggregation to L3 persona synthesis, enabling hierarchical drill-down via node and result references instead of flat vector recall. The Node.js Gateway sidecar handles capture, extraction, storage, recall, and pipeline scheduling through RESTful HTTP v2 endpoints on port 8420, while the Memory Proxy intercepts Anthropic-format API calls to inject team memory context into Claude Code, CodeBuddy, and other coding agents transparently. Local SQLite with the sqlite-vec extension provides the default storage backend with hybrid BM25 keyword plus vector embedding plus reciprocal rank fusion retrieval requiring zero external API dependencies. Teams manage ownership, versions, status, visibility, usage counts, and agent bindings through the Memory Hub dashboard with role-based access control separating System Admin and team-level Admin and Member permissions. Official TypeScript and Python SDKs provide programmatic access for custom framework integration beyond the built-in OpenClaw plugin and Hermes Agent adapter. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
FerretDB
FerretDB gives you the MongoDB developer experience without the SSPL: point your existing drivers at it and your document workloads land in PostgreSQL instead. It listens on the standard MongoDB port and translates wire-protocol queries into SQL, so applications, ORMs, and command-line tools connect unchanged, none the wiser. CRUD operations, aggregation pipelines, index creation, findAndModify, and sessions all work today, with new commands landing release after release as compatibility widens. Behind the proxy, Microsoft's open-source DocumentDB extension gives PostgreSQL a native BSON type and document operators, which is also the engine under Azure Cosmos DB for MongoDB vCore. That shared engine means workloads can move between your own FerretDB deployment and Cosmos DB without an export-import project in between. Vector search support covers embedding lookups for AI features, replication covers high availability, and SCRAM-SHA-256 authentication secures connections the way MongoDB operators already expect. Because the license is Apache 2.0, you can embed it, resell it, or offer it as a managed service to your own customers with no SSPL obligations attached. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Stalwart Mail
Stalwart replaces the traditional Postfix + Dovecot + SpamAssassin + calendar-server stack with one Rust binary that speaks every standard mail and collaboration protocol natively. JMAP, IMAP4rev2, POP3, SMTP, CalDAV, CardDAV, and WebDAV all run inside the same process — no glue scripts, no sidecar daemons, no version conflicts between components. The pluggable storage architecture lets operators choose RocksDB for single-node deployments, FoundationDB for distributed clusters, PostgreSQL, MySQL/MariaDB, or SQLite for the data store, S3/MinIO/Azure Blob for message blobs, and Elasticsearch or Meilisearch for full-text search, with Redis or the internal engine backing rate limiters and session state. Security features include S/MIME and OpenPGP encryption at rest, automated DKIM key generation with DNS publication, DANE and MTA-STS transport security, automatic ACME TLS provisioning, granular ACLs, rate limiting, and IP banning. The browser-based admin console manages accounts, domains, groups, mailing lists, SMTP queues, DMARC/TLS-RPT/ARF reports, and every configuration object without touching a config file, while the self-service portal at /account gives end users password reset and encryption key management. Multi-tenant support with per-tenant quotas enables hosting-platform deployments, and coordinator-less clustering via Zenoh or NATS scales horizontally by adding nodes. Deploy via Docker or the standalone binary. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
Dub
With 24,000 GitHub stars and infrastructure processing over 100 million clicks and 2 million links monthly for marketing teams at Twilio, Buffer, Framer, Perplexity, and Vercel, Dub is the most widely adopted open-source link attribution platform — unifying branded short links, real-time conversion analytics, and affiliate programs in a single self-hostable tool. Create short links on custom domains with built-in QR code generation, device and geographic targeting rules, A/B testing for destination URLs, deferred deep linking for mobile apps, and custom social media preview cards. The attribution engine tracks the complete customer journey from first click through lead capture to final sale, calculating lifetime value, retention rates, and multi-touch attribution across campaigns. Real-time analytics visualize clicks, leads, and revenue with filtering by geography, device, browser, referrer, operating system, and UTM parameters — plus an "Ask AI" feature that generates personalized reports from natural language queries. The partner program module enables embedded referral and affiliate programs with custom reward structures, automated payouts, and partner dashboards for product-led growth. Programmatic link creation via native SDKs for TypeScript, Python, Go, PHP, and Ruby supports enterprise-scale campaigns with real-time webhook notifications on link events. Migration assistants import existing links from Bitly, Rebrandly, and Short.io with redirects preserved. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
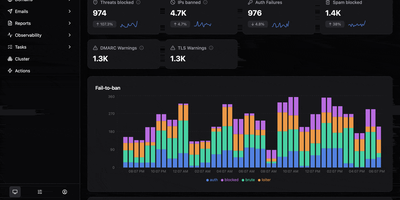
Stalwart
With 14,000 GitHub stars and 81 releases since March 2023, Stalwart is the most protocol-complete open-source mail server available — delivering JMAP, IMAP4rev2, IMAP4rev1, POP3, SMTP, CalDAV, CardDAV, and WebDAV from a single Rust binary that compiles to a memory-safe, zero-garbage-collection executable with predictable latency under load. The SMTP server implements DMARC, DKIMv2, DKIMv1, SPF, and ARC for complete message authentication with automatic DKIM key rotation, while transport security enforces DANE, MTA-STS, and SMTP TLS reporting to prevent downgrade attacks. Built-in spam filtering with statistical classifiers, DNS blocklists, and collaborative reputation databases eliminates the need for external Rspamd or SpamAssassin deployments. Encryption at rest protects stored messages with S/MIME or OpenPGP, and automatic TLS certificate provisioning via ACME supports TLS-ALPN-01, DNS-01, and HTTP-01 challenges without manual certificate management. The ManageSieve server enables server-side email filtering rules, while full-text search indexes message bodies and attachments for instant retrieval. Pluggable storage backends support RocksDB for embedded deployments, PostgreSQL, MySQL, and S3-compatible object storage for distributed architectures. LDAP and SQL-based authentication integrate with existing directory services, and the web administration panel manages domains, accounts, quotas, and DKIM keys. Security audited with memory safety guaranteed by Rust's ownership model. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Radicale
Calendars, to-do lists, journal entries, and contacts, synced over the open CalDAV and CardDAV standards nearly every client already speaks: Radicale is a small pure-Python server that works with Thunderbird, DAVx5 on Android, Apple Calendar and Contacts, GNOME, and many more. Its defining design choice is radical simplicity: there is no database. Events live as plain .ics files and contacts as .vcf files in an ordinary folder structure, which makes backup a copy command, migration a move, and disaster recovery a matter of reading text files. The server works out of the box with no complicated setup, then grows as needed: flexible authentication (htpasswd files among other methods), per-collection authorization rules, TLS-secured connections, and a plugin system for extending storage, auth, and rights handling. Built-in limits on parallel connections, file sizes, and failed authentication attempts harden it for network exposure behind a reverse proxy. A bundled web interface handles creating and managing calendars and address books - useful since many clients cannot create collections themselves. Maintained since 2011 with 140+ contributors, GPLv3-licensed, and light enough to run on the smallest VPS or a Raspberry Pi.
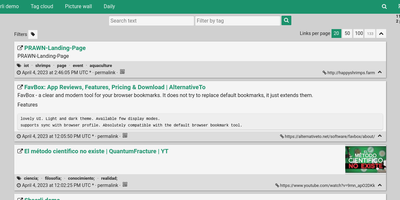
Shaarli
Personal, minimalist, database-free bookmarking - Shaarli is a philosophy as much as an app. Everything lives in a single compressed datastore file inside data/: no MySQL, no PostgreSQL, backup by copying one directory. That write-once/read-many file is usually served straight from OS disk caches, which is why a decade-old Shaarli instance with tens of thousands of links still responds instantly. Designed deliberately single-user, it saves URL, title, unlimited-length description, and tags (with autocomplete, renaming, and merging), marks entries public or private, and automatically strips utm_source and fb tracking parameters from saved URLs. That description field is why the community uses Shaarli as far more than bookmarks: a microblog, read-it-later queue, code-snippet base, pastebin, and shared clipboard between machines. Sharing is one click via bookmarklet or Android apps; consumption is per-tag RSS/Atom feeds plus a daily digest feed; search is full-text with tag filtering. A REST API opens it to any client, a plugin and theme system extends the PHP core (Markdown rendering, thumbnails), and import/export uses browser-standard Netscape HTML - your data enters and leaves freely. LDAP login is supported, no telemetry is sent anywhere, and the UI degrades gracefully without JavaScript. The anti-cloud Delicious.
Vendure
Vendure is a headless ecommerce framework where TypeScript plugins extend every aspect of commerce without forking the core, backed by 8,200+ GitHub stars and powering stores processing over 10,000 daily transactions. Two distinct GraphQL APIs serve different audiences: the Shop API powers storefronts while the Admin API handles back-office operations, both introspectable and type-safe through Apollo Server. NestJS modules with Vendure decorators inject services, modify schemas, subscribe to events, and add dashboard components, making extensibility a first-class concern rather than an afterthought. The React admin dashboard built with TailwindCSS and Shadcn UI provides order fulfillment workflows, catalog management, tiered pricing, dynamic promotion rules with side-effect hooks for free gift injection, and role-based access control across 14+ languages. Multi-channel support runs D2C, B2B, marketplace, and omnichannel from a single instance with channel-specific products, pricing, currencies, sellers, and permissions. Asset management handles images, videos, and documents with pluggable backends including AWS S3 and Minio, plus built-in image transformation via the AssetServerPlugin. Custom fields propagate automatically into GraphQL schemas and admin forms on every core entity. A dedicated worker process handles search indexing, email dispatch, and integration jobs with independent horizontal scaling. Deploys on PostgreSQL, MySQL, or MariaDB. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPLv3 licensed.
Passbolt
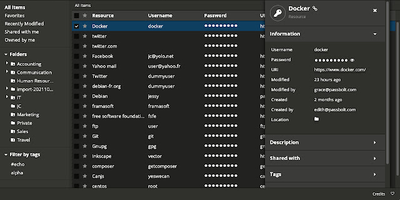
Security-conscious IT departments pick Passbolt for its cryptography: every user holds an OpenPGP key pair, and shared credentials are encrypted individually to each recipient's public key - real end-to-end encryption, not a vault password handed around. All crypto runs client-side in the mandatory browser extension (distributed and signed through the Chrome and Firefox stores, deliberately separating the crypto code from the server that stores ciphertext); private keys and passphrases never touch your instance, and the server admin cannot read a single secret. Authentication uses the challenge-based GpgAuth protocol, secrets are digitally signed to verify sender integrity, and metadata encryption extends protection to resource names and URLs. Day to day it behaves like a polished commercial manager: auto-fill and auto-save in forms, strong password generation, anti-phishing protection, TOTP storage, folder hierarchies shared per-user or per-group with fine-grained permissions and instant cryptographic revocation. Native iOS, Android, and desktop apps ship alongside a JSON API, CLI, and SDKs for CI/CD secret retrieval and rotation. The PHP server runs on MariaDB and is AGPL-licensed open source - including the paid tiers' codebase - with published security audits.
SurfSense
Positioned as the open-source NotebookLM alternative for AI agents, SurfSense delivers a live web research platform where your agents access structured data from Reddit, YouTube, Instagram, TikTok, Amazon, Walmart, Google Maps, Google Search, Indeed, and any page on the open web through one REST API or MCP server. Scheduled and event-triggered agents transform findings into briefs, alerts, podcasts, and presentations, while a built-in knowledge base keeps every discovery searchable with Perplexity-style cited answers using hybrid semantic and full-text search powered by PostgreSQL with pgvector. Upload PDFs, Office documents, images, and audio files, or sync Google Drive, OneDrive, and Dropbox — 50+ file formats supported with AI file sorting that auto-organizes documents by source, date, and topic. The MCP server exposes scrapers, knowledge base, and workspaces as native tools for Claude, Cursor, and any MCP-compatible agent. Cross-country proxy rotation handles Reddit, TikTok, and Google Search scraping with geo-aware sticky sessions and captcha-aware anti-bot handling. The platform features collaborative chats, multi-format document export, git-native knowledge base with Open Knowledge Format export, and a desktop quick-ask panel with global shortcut. Docker Compose deployment manages nine services including Caddy proxy, PostgreSQL, Redis, FastAPI backend, Celery workers, zero-cache real-time sync, and Next.js frontend with automatic Watchtower updates. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Fluxer
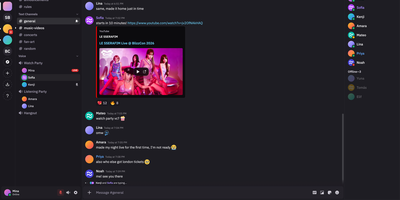
Fluxer gives friends, gaming groups, and private communities their own self-hosted instant messaging and VoIP platform that replaces Discord with private text channels, voice rooms, video calls, and screen sharing. Members can chat one-on-one in direct messages, form multi-person group conversations, or organize large community servers into categorized text and voice channels with threaded replies, reactions, and typing indicators. When a conversation moves to voice, participants can join low-latency audio and video rooms from multiple devices simultaneously, share application windows or full screens, and rely on built-in noise suppression and echo cancellation for clear calls. Rich media support allows users to share file attachments, preview embedded links, search animated GIFs through KLIPY, and upload custom community emojis and stickers. Server administrators control access through role-based permission hierarchies, member timeouts, kicks, bans, and detailed moderation audit logs that track every configuration change across the community. Integrated full-text search lets members quickly locate historical messages, code snippets, and shared files across every channel they can access. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
OpenReplay
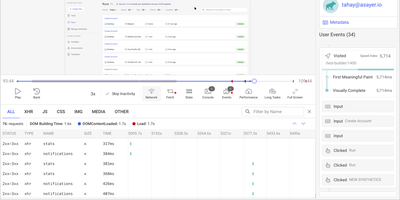
Backed by 12,400+ GitHub stars and positioned as the self-hosted alternative to FullStory and Hotjar, OpenReplay delivers the open-source session replay platform that keeps every byte of user behavior data on your own infrastructure. The JavaScript tracker captures pixel-perfect recordings of clicks, scrolls, form inputs, and navigation with automatic sensitive data masking, while simultaneously logging network requests, console errors, JavaScript exceptions, and Redux, VueX, MobX, NgRx, Pinia, and Zustand store state changes for complete technical context. DevTools mode reconstructs each session with full stack traces, GraphQL queries from Apollo and Relay, Fetch and Axios request payloads, CPU and memory metrics, and page speed waterfall charts — effectively giving developers a browser inspector tied to any user session. Product analytics surfaces conversion funnels, user journeys, click heatmaps, web vitals trends, and retention cohorts without requiring custom instrumentation. Co-browsing connects support agents to live user sessions with cursor control and WebRTC audio, enabling real-time assistance without third-party screen-sharing software. Integrations push session context into Sentry, Datadog, CloudWatch, Stackdriver, and Elastic for front-to-back debugging. Feature flags enable gradual rollouts with session-level targeting. The platform deploys to any cloud via Docker and Kubernetes with auto-scaling ingestion handling up to 50,000 sessions per month on the open-source edition. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Toonflow
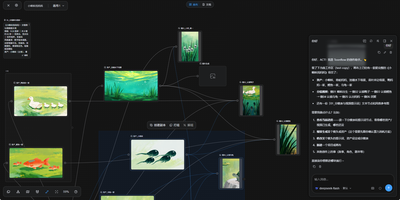
Toonflow, an open-source AI studio for short dramas, animated comics, and short videos, lets you plan, generate, and direct every shot as nodes on a canvas that runs on your own server. Text nodes hold the story, characters, and shot descriptions. Image generation nodes create character sheets with close-up, front, side, and back views. Video generation nodes take numbered reference images. Aspect ratio, resolution, and duration options depend on the selected model. Connectors link the nodes, so a character sheet made once is reusable in every shot. The 3D director's studio blocks a scene with camera framing, lighting, and keyframes. Export the scene as a video node. An assistant panel reads the project and reports which assets and videos have been generated. It offers next steps: generate a shot, revise a prompt, or start a new canvas. Finished images and clips preview on the canvas and download for further production work. Models come from third-party APIs, local ComfyUI workflows, or local language models. Plugins for nodes, skills, tools, and agents install from the marketplace. MCP links external tools and services. Projects, settings, and plugins live in one data directory. The interface offers 21 languages. There is no built-in login, so a firewall or an authenticating reverse proxy decides who can reach it. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Maxun
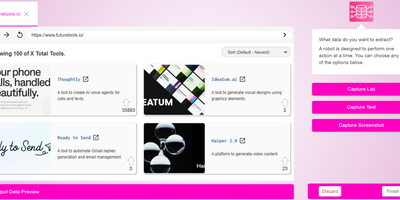
With over 16,800 GitHub stars and growing rapidly, Maxun has become the go-to open-source platform for teams who need structured web data without writing scrapers. The TypeScript-based platform provides a no-code visual recorder that captures point-and-click interactions in real-time browser sync, automatically generating reusable extraction robots that handle pagination, infinite scrolling, and dynamic content. LLM-powered extraction accepts natural language prompts like "Extract 10 companies from the Y Combinator website" without requiring a URL — Maxun identifies the source and performs the extraction autonomously. The platform handles authentication-protected pages, adapts automatically to website layout changes through self-healing selectors, and exports directly to Google Sheets, Airtable, or any destination via webhooks. Robots run on configurable schedules with cron-based timing, turning any website into a perpetually fresh RESTful API endpoint. The crawl engine discovers and processes linked pages across entire domains with configurable depth and URL filtering, while the search capability runs automated queries across multiple engines. Official Node.js and Python SDKs provide programmatic control over robot creation, execution, and data retrieval, with MCP integration enabling direct connection to AI tools like Claude. The n8n community node enables workflow automation without custom code. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Knowhere
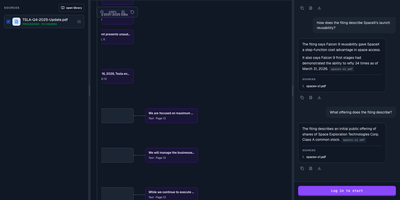
With 2,600+ GitHub stars since its May 2026 open-source launch, Knowhere solves the last-mile problem of document intelligence for AI systems — transforming complex unstructured PDFs, reports, and multi-page documents into structured JSON chunks that LLMs can consume without hallucination. The platform processes documents through an AI-native parsing pipeline that handles 20+ page documents with deep hierarchies, intricate tables, and multimodal content including images with OCR, achieving 95% precision in information extraction while reducing token costs by 50% compared to raw document ingestion. The knowledge tree architecture maintains historical context across multiple documents, enabling cross-document graph navigation for agentic retrieval that goes beyond simple chunk-based RAG. Built on Python 3.11+ with MinerU as the default PDF parser, the backend API runs alongside async workers that process document ingestion, graph construction, and embedding generation. The self-hosted Docker Compose stack packages the API server, processing workers, and Next.js dashboard for managing API keys, webhooks, and document-processing jobs, backed by PostgreSQL and Redis. Both Python and Node.js SDKs provide programmatic access for integration into existing AI pipelines and agent frameworks. LLM providers include DeepSeek and Alibaba Cloud DashScope with configurable key rotation for rate-limit management. Deploy on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Prime Agent
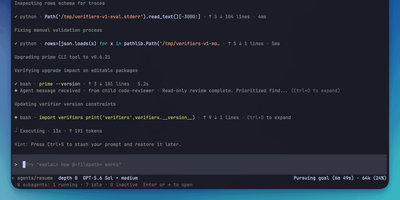
With over 14,000 GitHub stars and 41 releases since its May 2026 launch, Prime Agent delivers a fundamentally different approach to AI coding agents by treating the agent's own operating environment as programmable state that improves through use. The Recursive Language Model architecture provides the model exactly one tool — a persistent IPython kernel — where file operations, shell commands, subagent delegation via rlm() function calls, and context management all happen through code rather than rigid tool-calling schemas. Subagents launch as independent sessions with their own model, kernel, and history, communicating results through agent_message.send() without blocking the parent. The Continual Harness stores supplemental prompts, memories, skill descriptions, and reusable subagent specifications as durable state that the /refine command updates through small, evidence-backed edits with full rollback by ID. Daemon-backed sessions keep running when the terminal disconnects, with automatic context compaction summarizing older messages while preserving recent state. The TUI provides an Agent View for monitoring, switching between, and steering multiple live sessions simultaneously. Autonomous mode operates within configurable turn, token, and time budgets with user-defined quality gates. Persistent goals, heartbeats, and scheduled prompts maintain continuity across terminal sessions. Compatible with Anthropic Claude, OpenAI, Google Gemini, local models via Ollama or vLLM, and Prime Inference endpoints. Install via a single curl command on Linux or macOS. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
ChartDB
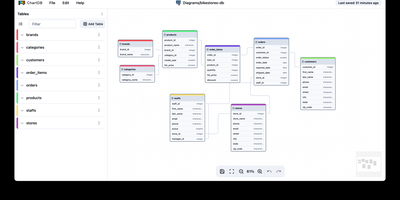
Paste one SQL query result into a browser and get an interactive entity-relationship diagram instantly, with no installations, no credentials, and no account required. ChartDB's "Smart Query" runs a single statement in your existing database client that exports table definitions, relationships, indexes, and column types as JSON metadata, meaning the application never touches your database passwords. The canvas renders draggable entities with cardinality markers, collapsible grouping areas, and sticky notes for documentation. AI-powered DDL export generates migration scripts between dialect pairs like PostgreSQL to MySQL or SQLite to CockroachDB, analyzing your schema to produce target-specific DDL with correct type mappings and constraint translations. Import paths cover Smart Query JSON, raw DDL scripts, and DBML files from tools like dbdiagram.io. The AI layer connects to OpenAI or any compatible inference server including local vLLM instances running models like Qwen2.5-32B. Database coverage includes PostgreSQL (with Supabase and Timescale extensions), MySQL, SQL Server, MariaDB, SQLite (with Cloudflare D1), CockroachDB, ClickHouse, and Oracle. Exports to SVG with inline styles or SQL DDL in any target dialect. Ships as a React/Vite frontend behind Nginx in Docker, deployable on RepoCloud with dedicated VPS resources under the AGPL-3.0 license.
libSQL
libSQL bridges the gap between SQLite's legendary simplicity and the server-accessible database model developers expect from PostgreSQL and MySQL, adding network access, replication, and vector search while maintaining full file format and API compatibility. The sqld (SQL daemon) component transforms SQLite into a network-accessible database server accepting queries via HTTP with JSON payloads, WebSocket connections, and a Hrana protocol optimized for low-latency edge access. Client libraries for TypeScript, JavaScript, Rust, Go, and Python connect to sqld identically to any traditional client-server database, while the LD_PRELOAD compatibility layer enables switching existing SQLite applications from local to remote mode without code changes. Embedded replicas synchronize a local SQLite copy inside your application process with the primary server, delivering sub-millisecond read latency while maintaining consistency through streaming replication. Bottomless replication continuously backs up database state to S3-compatible object storage with generation-based snapshots and WAL page shipping, providing point-in-time recovery without manual backup scheduling. Native vector search enables semantic similarity queries directly within SQL using cosine distance functions, eliminating the need for external vector database infrastructure. Read replica support distributes query load across multiple sqld instances, and integration with mvSQLite adds multi-version concurrency for high-availability deployments. Created by Turso with 17,100+ stars and active production deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.