Open Source App Cloud Marketplace
Deploy, host, and scale with one click, at half the cost. Then customize with AI agents.
Open WebUI
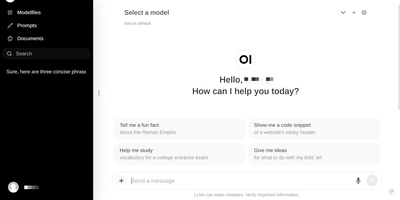
Large language models get a polished front end that can run fully offline: Open WebUI is the self-hosted front end of choice. It talks to local model runners, primarily Ollama, and to any OpenAI-compatible API, so LM Studio, vLLM, Groq, Mistral, OpenRouter, and cloud providers all plug into the same chat interface and can be mixed per conversation. RAG is built in: upload files to knowledge bases or reference them in chat with the # command, backed by a choice of nine vector databases (ChromaDB and PGVector officially maintained) and multiple extraction engines including Tika and Docling, with hybrid BM25-plus-vector search and cross-encoder reranking. Web search results from providers like SearXNG, Brave, and Tavily inject directly into conversations. Extensibility comes from Python tools and functions that run inside the chat, a Pipelines plugin framework, and native MCP support. Multi-user features include RBAC, SSO, and group permissions, and the instance itself exposes an OpenAI-compatible API your own apps can call.
LibreChat
Every major model provider behind one ChatGPT-style interface: LibreChat spans OpenAI, Anthropic, Google, Azure, AWS Bedrock, Vertex AI, Groq, Mistral, OpenRouter, DeepSeek, and any OpenAI-compatible endpoint including local Ollama. You can switch models mid-conversation and compare providers without changing tools. Its Agents framework builds no-code custom assistants with tool access via Model Context Protocol servers, file search over uploaded documents through an optional pgvector-backed RAG service, and a sandboxed Code Interpreter that executes Python, JavaScript, Go, C++, Java, PHP, and Rust. Artifacts render React components, HTML, and Mermaid diagrams directly in chat, and image generation works through DALL-E and other configured providers. Multi-user support is enterprise-grade, with OAuth, SAML, LDAP, and two-factor authentication, per-user conversation history in MongoDB, and Meilisearch-powered search across all messages and files, plus reusable presets, forkable threads, and persistent memory across conversations. The economics favor teams: instead of a ChatGPT Plus seat per person, everyone shares one instance billed per API token, with access to every provider rather than one - and providers see individual API calls, not your accumulated organizational knowledge. Deployment is Docker Compose; API keys and endpoints are configured through .env and librechat.yaml.
DeepSeek Harness
DeepSeek Harness gained over 60,000 GitHub stars within hours of its August 2026 launch, establishing itself as the first fully modular open-source agent runtime where literally every component is a swappable plugin. Built on the Cordis framework—a programming paradigm for spatiotemporal composability—dsh decomposes the entire agent stack into independently replaceable pieces: model adapters for DeepSeek, Anthropic, OpenAI, AWS Bedrock, Azure, and Google Gemini; tool registries covering bash execution, file system operations, web search, subagent delegation, and todo management; plus session stores, sandboxes, approval policies, orchestration loops, and the user interface itself. Four operating modes serve different workflows: Standard provides the full toolset, Code mode uses model-generated code to compose multi-round tool calls, Minimal strips down to a shell and editor for benchmarking, and Creator mode lets developers inspect the running runtime and test Cordis plugins in memory. The kernel handles plugin mounting, unmounting, and dependency resolution while typed events and services coordinate between components. Profiles and bundles allow the same codebase to produce entirely different products—a terminal coding agent, a browser-based workspace, a headless automation service, or an ACP/JSON-RPC endpoint—by swapping YAML configuration layers. Session history is stored as an append-only event stream for full trajectory replay, and project-level hooks on agent lifecycle events enable fine-grained behavioral customization. MCP client integration connects to external tool servers, while Agent Client Protocol enables programmatic orchestration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenBot
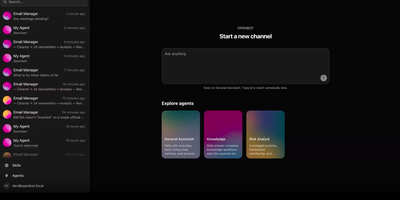
Open source GrokBot, built by the team behind the AG-UI protocol. OpenBot is the open-source enterprise agent platform that gives every AI coworker its own sandboxed computer — a real Chromium browser with its own login sessions, a private filesystem, and only the MCP tools you explicitly grant. The centralized gateway evaluates CEL policy rules against tool name, intent, bot identity, page URL, element attributes, and file paths before any action executes, writing an immutable audit row for every call and outcome. Any agent that speaks AG-UI — LangGraph, Mastra, CrewAI, Pydantic AI, Google ADK, or hand-written endpoints — registers as a Bot and receives its own channel with persistent conversation history. The take-the-wheel system lets humans assume control when an agent encounters login walls or two-factor prompts, recording control transfers as structured audit events. Knowledge documents from Google Drive and OneDrive carry source-based permissions where deny principals always win and ambiguous mappings refuse retrieval entirely. The React and Vite frontend provides live screen viewing of each agent's browser, channel-based chat, admin settings, and component galleries. The Hono API server on port 3001 handles authentication, role-based access, tenant packaging, and credential management backed by PostgreSQL with pgvector. Deploy via Docker Compose with the included supervisor that manages per-bot computer containers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Hermes Agent
OpenRouter's most-used application by token volume — over 17 trillion tokens processed — Hermes Agent is an open-source autonomous agent built by Nous Research that lives on your server and gets more capable every day. Define a goal in natural language and Hermes plans sub-tasks, executes them through tool integrations, observes results, handles errors, and refines until the job is done or it genuinely needs your input. Persistent memory with full-text search and LLM summarization lets it recall context across sessions, and an agent-created skills system self-improves after complex tasks. A messaging gateway connects Telegram, Discord, Slack, WhatsApp, Signal, and 16 more platforms with cross-channel conversation continuity. A built-in cron scheduler runs daily reports, nightly backups, and weekly audits unattended. Subagent spawning parallelizes workstreams, and six terminal backends — local, Docker, SSH, Singularity, Modal, and Daytona — fit any infrastructure. Works with any LLM provider: Nous Portal, OpenRouter for 400+ models from 70+ providers, OpenAI, Anthropic, or your own endpoint. The API key you supply powers all LLM calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Memoh
Memoh delivers an open-source multi-agent platform where every AI agent gets its own computer — not a chat window but a fully isolated container with dedicated filesystem, desktop environment, browser, network stack, and persistent long-term memory that survives across sessions, days, and platforms. The containerd-based runtime ensures each bot operates in complete isolation with snapshot and data import/export capabilities. The memory engine uses LLM-driven fact extraction with hybrid retrieval combining dense embeddings via Qdrant, sparse vectors, and BM25, plus 24-hour context loading and automatic compaction — with Mem0 and OpenViking as drop-in alternatives. Ten communication channels connect agents to users through Telegram, Discord, Lark, QQ, Matrix, WeCom, WeChat, Email, Web UI, and group chats with cross-platform identity binding. MCP tool calling enables agents to interact with external services, while browser automation drives GUI workflows for web research and data extraction. Agent hosting supports running external coding agents like Codex and Claude Code inside Memoh workspaces via ACP with per-bot configuration. Scheduled tasks run without human triggers, and agents proactively reach out when needed. The web dashboard built with Vue 3 and Tailwind CSS provides streaming chat, tool call visualization, file management, model and provider configuration, and bot lifecycle management. Deploy via Docker Compose with PostgreSQL, Qdrant, sparse service, and the Go backend server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
TrueForge
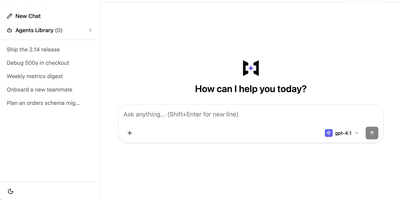
With over 2,100 GitHub stars in its first month and benchmarked at 30-75% lower cost than Claude Managed Agents on enterprise task suites, TrueForge is the open-source agent harness that provides the complete runtime layer for turning any LLM into a working production agent on your own infrastructure. The TypeScript server runs the full execution loop — streaming every step, routing tool calls through MCP servers with centralized header-auth and in-chat OAuth, delegating parallelizable work to isolated subagents, and pausing for human approval on sensitive actions. Context engineering keeps token costs low: deferred tool-schema loading delays MCP schemas until invoked, large-result offloading moves oversized outputs to files, Code Mode processes structured data through sandboxed execution, and automatic compaction summarizes older history at a configurable 50,000-token threshold while preserving the full transcript. The sandbox-as-a-tool architecture provisions isolated Daytona environments only when code execution is required, allowing one server to run many concurrent agents without idle overhead. Agents are configured from shipped YAML catalogs of models, MCP servers, git-backed SKILL.md instruction packs, and sandbox providers, then saved to an Agents Library accessible via the chat UI, TypeScript SDK, or embeddable React UI SDK. Run locally with SQLite via a single npx command, or deploy for teams with Docker Compose or Helm using Postgres and Redis with OIDC authentication. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Open Canvas
Open-source alternative to OpenAI's Canvas — a collaborative writing and coding environment where AI agents help you draft, edit, and refine documents through an agentic architecture built on LangGraph. The dual-mode editor combines a BlockNote rich text editor for live-rendered markdown with a CodeMirror-based code editor supporting syntax highlighting across multiple programming languages, letting you switch between prose and code artifacts within the same session. The built-in reflection agent automatically generates style rules and user insights from your chat history, storing them in a shared LangGraph memory store that persists across sessions for increasingly personalized assistance. Pre-built quick actions provide one-click access to common writing transformations including summarize, expand, simplify, and translate, while coding actions offer explain, refactor, add comments, and convert between languages. The monorepo architecture separates the Next.js 14 frontend from the LangGraph agent backend, connecting via HTTP and WebSocket protocols through the @langchain/langgraph-sdk client. Seven LLM providers are supported out of the box — OpenAI, Anthropic Claude, Google Gemini, Fireworks AI, Groq, Azure OpenAI, and local Ollama models — with Supabase handling authentication and data persistence. Deploy via Docker or build from source. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Buzz
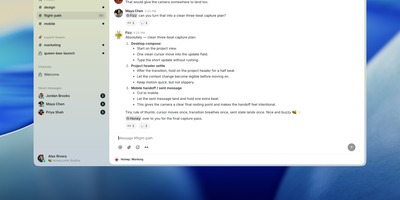
Buzz delivers the first production workspace where humans and AI agents operate as cryptographically equal team members on a self-hosted Nostr relay. The Rust-based backend stores every message, code patch, CI result, review comment, and workflow step as a signed Nostr event in a unified PostgreSQL-backed event log with Redis pub/sub for real-time presence and S3/MinIO for media storage. The integrated Git forge implements NIP-34, turning feature branches into dedicated channels where patches, reviews, and merge decisions live alongside the discussion that produced them — eliminating the split between chat tools and code hosts. Through the open Agent Client Protocol, Buzz natively supports Goose, Anthropic Claude Code, and OpenAI Codex as first-class channel members with scoped permissions, their own audit trails, and the ability to create patches, run workflows, and orchestrate multi-step automations via YAML-defined triggers including message events, reactions, schedules, and webhooks. The Tauri-based desktop client runs on macOS, Windows, and Linux, while buzz-cli provides agent-first JSON I/O for headless automation. Deploy via Docker Compose with the production bundle in deploy/compose/, Railway one-click, or build from source requiring Rust 1.88+, Node 24+, and pnpm. Multi-community mode scopes tenant data by domain with NIP-42 Schnorr authentication, rate limiting, and hash-chain audit logging. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Openship
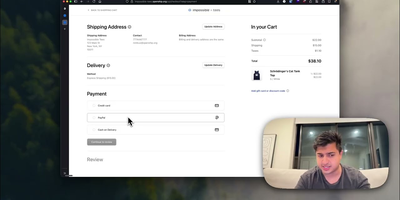
Point Openship at a GitHub repo, local folder, or prebuilt artifact and it detects your stack, builds a Docker container, provisions databases, configures domains with automatic Let's Encrypt TLS, and routes traffic through an OpenResty edge layer on ports 80 and 443. Already past 10,000 stars since launching in March 2026, it turns any Linux VPS into a managed application host. Language support covers Node.js, Python, Go, Rust, PHP, Ruby, Java, .NET, Docker, and monorepo projects with push-to-deploy CI/CD, pull request preview environments on unique subdomains, staging/production flows, and one-click rollbacks. Integrated backend services include managed Postgres, MySQL, MongoDB, Redis, persistent volumes, WebSocket proxying, object storage, and worker processes, all provisioned from the dashboard without compose files. A built-in SMTP server handles transactional email with automatic DKIM, SPF, and DMARC configuration, eliminating external email services. The edge layer serves HTTP/3 with Brotli compression, configurable cache rules, and instant purging. Real-time monitoring streams build logs, container metrics, visitor geography, and per-status-code analytics at 1.4 microsecond overhead with zero database writes. Scheduled backups cover databases and volumes with one-click restore and export. Three interfaces (web dashboard, desktop app for macOS/Windows/Linux, and the openship CLI) drive the same API, plus a Model Context Protocol endpoint for AI integration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Onyx
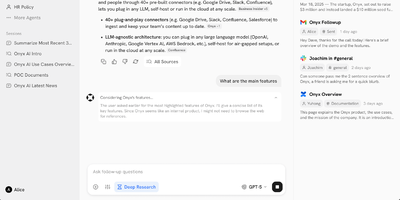
Formerly known as Danswer and now backed by over 31,000 GitHub stars with 253 releases, Onyx delivers a production-ready AI platform that turns any LLM into a context-aware enterprise assistant connected to your organization's actual knowledge. The agentic RAG pipeline combines BM-25 keyword search with prefix-aware embedding models in a hybrid index, then deploys AI agents to retrieve, verify, and synthesize answers with source citations from over 40 connected workplace tools including Google Drive, Confluence, Slack, Notion, Jira, SharePoint, GitHub, and Linear. Custom AI assistants with configurable prompts, backing knowledge sets, and document-level access control enable specialized agents for engineering, sales, support, and research workflows. The platform supports every major LLM provider — Anthropic Claude, OpenAI, Google Gemini, plus self-hosted options via Ollama, LiteLLM, and vLLM for fully air-gapped deployments. Beyond chat, Onyx provides web search with Serper, Google PSE, Brave, and SearXNG integration, an in-house web crawler, code execution, file creation, and multi-step deep research with report generation. Enterprise features include SSO via Google OAuth, OIDC, or SAML with SCIM provisioning, role-based access control, usage analytics by team and agent, query history auditing, PII removal through custom code hooks, and full whitelabeling. Deploy via Docker Compose on any infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed (Community Edition).
DeerFlow
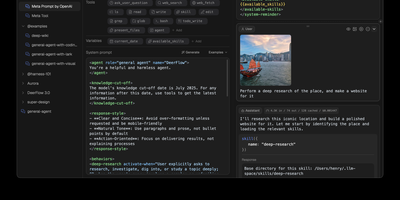
DeerFlow 2.0 is ByteDance's ground-up rewrite that transforms what began as a Deep Research framework into a batteries-included super agent harness handling tasks lasting minutes to hours autonomously. Built on LangGraph and LangChain, the runtime orchestrates a lead agent that plans, decomposes, and delegates to sub-agents executing in isolated Docker or Kubernetes sandboxes with persistent filesystem access, while an extensible skills system lets developers add capabilities as Python functions or MCP servers with OAuth token flows. The harness ships with long-term memory using persistent event loops with per-agent isolation, scheduled task execution via cron, context engineering with manual compaction, and a web UI at localhost:2026 for interactive sessions. Model support spans OpenAI GPT-4o/GPT-5, Anthropic Claude via OAuth, Google Gemini, DeepSeek, Qwen via vLLM, and OpenRouter-compatible gateways with per-model pricing configuration. IM channel integration connects Telegram, Slack, Feishu/Lark, Discord, WeChat, WeCom, DingTalk, and Buzz without requiring a public IP — all using long-polling or WebSocket transports. Production deployment uses Docker Compose with nginx reverse proxy, PostgreSQL or SQLite persistence, Redis stream bridges for multi-worker scaling, and lease-based run ownership with automatic orphan recovery. The terminal workbench TUI enables headless operation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenClaw VPS
A personal AI assistant that remembers what it learns and reaches you wherever you are — OpenClaw is an open-source agent gateway built by the OpenClaw Foundation with 247,000+ GitHub stars. It connects to 200+ LLM models through providers like Anthropic, OpenRouter, and OpenAI, and meets you on 21+ messaging channels: Telegram, Slack, Discord, WhatsApp, Signal, iMessage, Matrix, and more. Persistent memory with full-text search lets the agent recall context across sessions, and a self-improving skills system means it gets more capable the longer it runs. Voice wake words and talk mode enable hands-free interaction on macOS, iOS, and Android. A live canvas provides an agent-driven visual workspace. Built-in browser automation, cron scheduling for unattended tasks, and subagent spawning for parallel workstreams round out the toolset. The gateway architecture keeps all sessions, credentials, and conversation history on your own server — nothing transits a third-party cloud unless you choose to connect one. The API key you provide for your chosen LLM provider powers the underlying calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Open Lovable
Open Lovable from the Firecrawl team delivers the first truly open-source alternative to Lovable.dev — a chat-driven AI copilot that takes any website URL and regenerates it as a complete, editable React application with TypeScript and Tailwind CSS in seconds. The pipeline combines Firecrawl's intelligent web scraping for JavaScript-rendered pages and single-page applications with your choice of AI provider — Claude, GPT-4, Google Gemini, or Groq — to analyze HTML structure, extract layouts and styling, decompose pages into proper React components, and generate production-ready code following modern best practices. Live preview runs in a secure sandbox environment using Vercel Sandbox with OIDC authentication or E2B Cloud, letting you see results immediately and iterate through natural language chat to request changes like Tailwind migration, componentization, SEO improvements, accessibility fixes, or custom form implementations. The optional Morph LLM fast-apply path accelerates small edits by applying diffs directly without full regeneration. The provider-agnostic architecture means you control costs by routing to different models — use Groq for fast iterations and Claude for complex layouts. Project structure follows Next.js conventions with organized app, components, atoms, styles, utils, and hooks directories. Deploy via pnpm with Node.js 18+ requiring only a Firecrawl API key, one AI provider key, and a sandbox provider configuration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Dokploy VPS
Your own Heroku or Vercel on a dedicated server — Dokploy is the open-source PaaS that replaces cloud platform subscriptions with a single dashboard you control. Point it at a Git repository or a Docker image, and it builds and deploys the application using Dockerfiles, Nixpacks, or Heroku/Paketo buildpacks. Traefik handles reverse proxying, routing, load balancing, automatic Let's Encrypt SSL, and HTTP/3. Databases — MySQL, PostgreSQL, MongoDB, MariaDB, libsql, and Redis — provision from the UI with automated backups to any S3-compatible destination. Complex multi-service applications deploy through native Docker Compose support, and multi-node scaling uses Docker Swarm. The web dashboard covers environment variables, volumes, resource limits, real-time CPU/memory/network monitoring, and deployment logs, with a CLI and REST API for automation. Deploy notifications go to Slack, Discord, Telegram, or email. One-click templates install common open-source tools, and a single control plane can manage deployments across multiple remote servers. Because everything is standard Docker, there is no lock-in: Dockerfiles, Compose files, and data volumes work anywhere else Docker runs. The push-to-deploy workflow of a $20/seat cloud PaaS, running on a dedicated VPS with guaranteed CPU, RAM, SSD, and full root access — no per-app, per-environment, or per-seat fees regardless of how many applications you deploy. 26,000+ GitHub stars.
Mattermost
Teams that cannot send messages through someone else's cloud run Mattermost - the open-core, self-hosted alternative to Slack. It provides public and private channels, threaded discussions, unlimited search history, file sharing with previews, one-to-one audio calls, and screen sharing, with desktop clients for Windows, macOS, and Linux plus iOS and Android apps. Messages support full Markdown, which suits engineering conversations with code blocks and logs. Playbooks turn repeatable processes such as incident response and release management into checklist-driven workflows with automated triggers and retrospectives. Integration is a core strength: prebuilt connectors for GitHub, GitLab, Jira, ServiceNow, and PagerDuty, plus webhooks, slash commands, bots, a REST API, and a plugin marketplace with 700+ entries - together making it a working surface for ChatOps rather than just a chat room. Playbooks add keyword and event triggers, task assignment, status broadcasting, and post-incident retrospectives, so operational knowledge is not trapped in individuals' heads. The server is a single Go binary backed by PostgreSQL, with React clients, released monthly under MIT license and deployable fully air-gapped - which is why governments and defense organizations run it inside closed networks, and why the same control applies to any team with confidentiality requirements. The compiled Team Edition is free for unlimited users with no message history cutoff, so costs stay flat as the team grows.
Listmonk
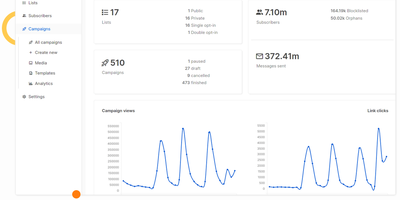
Seven million emails from a single binary peaking at 57 MB of RAM: listmonk is a high-performance newsletter and mailing list manager in Go with PostgreSQL as its only dependency - no Redis, no worker processes, no message broker. The project's own production benchmark sent 7+ million emails with the binary peaking around 57 MB of RAM, and throughput exceeds 100K emails per hour on modest hardware. Campaigns run through a multi-threaded, multi-SMTP queue with round-robin delivery, per-server concurrency, retries, and sliding-window rate limiting across providers like Amazon SES, SendGrid, Mailgun, or your own Postfix relay. Subscribers carry custom JSON attributes and are segmented with raw SQL queries, so any audience Postgres can express, listmonk can target. Templates use Go template syntax with 100+ functions for dynamic per-subscriber content, and the Vue dashboard reports opens, clicks, bounces, and unsubscribes with automated bounce processing. A REST API handles transactional email and programmatic control, a built-in media library hosts campaign assets, and CSV or API import migrates lists from hosted platforms. The economics are the headline: where Mailchimp pricing scales with list size, listmonk plus Amazon SES sends the same volume for hosting cost plus roughly $0.10 per thousand emails - commonly a 95% reduction - and your email list, a core business asset, stays on your own infrastructure. AGPLv3-licensed; bring your own SMTP provider for delivery.
Prime Agent
With over 14,000 GitHub stars and 41 releases since its May 2026 launch, Prime Agent delivers a fundamentally different approach to AI coding agents by treating the agent's own operating environment as programmable state that improves through use. The Recursive Language Model architecture provides the model exactly one tool — a persistent IPython kernel — where file operations, shell commands, subagent delegation via rlm() function calls, and context management all happen through code rather than rigid tool-calling schemas. Subagents launch as independent sessions with their own model, kernel, and history, communicating results through agent_message.send() without blocking the parent. The Continual Harness stores supplemental prompts, memories, skill descriptions, and reusable subagent specifications as durable state that the /refine command updates through small, evidence-backed edits with full rollback by ID. Daemon-backed sessions keep running when the terminal disconnects, with automatic context compaction summarizing older messages while preserving recent state. The TUI provides an Agent View for monitoring, switching between, and steering multiple live sessions simultaneously. Autonomous mode operates within configurable turn, token, and time budgets with user-defined quality gates. Persistent goals, heartbeats, and scheduled prompts maintain continuity across terminal sessions. Compatible with Anthropic Claude, OpenAI, Google Gemini, local models via Ollama or vLLM, and Prime Inference endpoints. Install via a single curl command on Linux or macOS. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.