Chat UI
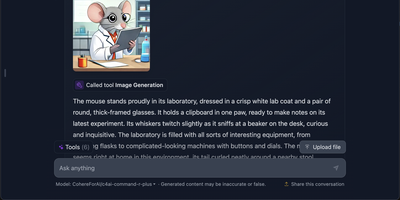
Self-hosting a language model is only half the job; people still need somewhere pleasant to talk to it, and Chat UI is that window, the same interface that powers HuggingChat. Point it at any OpenAI-compatible endpoint, your own Ollama or llama.cpp server, the Hugging Face router, or a hosted gateway like OpenRouter, and the models it serves appear in the picker automatically, with no per-model configuration. Conversations are saved to your database and stay browsable in the sidebar, so a thread from last week can be reopened, continued, and compared against a fresh answer from another model. Multimodal models accept image uploads right in the composer, and models that support it can call MCP tools mid-conversation to fetch data or run actions. For a shared team deployment, OpenID Connect sign-in keeps individual histories and settings separate, and per-user defaults travel with each account. Everything a consumer chatbot would keep on someone else's servers, prompts, uploaded files, and usage history, stays in the MongoDB you control on the same machine. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Platypus
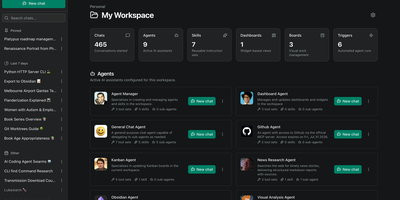
Platypus gives a whole team always-on AI agents that reason, call tools, and keep working on your own servers while everyone is offline. Build an agent once by choosing a provider and model, writing its instructions, and capping its tool-calling loop, then reuse that preset across chats and scheduled runs. Agents load reusable Skills on demand and delegate specialist work to sub-agents that appear to the parent as tools. Connect local and remote data through Model Context Protocol servers, or expose an agent to outside agents and chat platforms through A2A endpoints with a token per client. Triggers run agents on a cron schedule, as one-off jobs, or when workspace events such as a card moving on a board occur, and every run records its result. Kanban boards give agents work they can move and update themselves, while notifications and HMAC-signed webhooks push board and workspace events into your own systems with filtering and retries. Facts and preferences are extracted from conversations in the background and injected into future chats, so returning users are remembered. Sandbox backends give agents shell and filesystem access inside an isolated per-workspace environment instead of the host. Organizations and workspaces keep each team's agents and data separate, and blueprints package shared agents, skills, MCP servers, and providers so a new workspace starts pre-equipped. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Vocero CRM
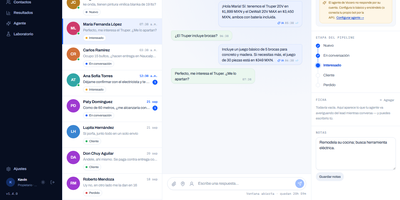
Vocero CRM turns WhatsApp into your sales floor, with a shared team inbox, a visual pipeline, and an AI agent that answers customers using only what your business taught it. Incoming messages land in a three-column inbox within two seconds, showing sent, delivered, and read states, enforcing the official 24-hour window, and offering approved templates when it closes. Every person who writes becomes a contact automatically and enters a Kanban pipeline you can rename, where dragging a card, adding notes, or archiving a lead takes seconds. The AI agent learns from question-and-answer pairs and free-text knowledge blocks, and answers only from what it knows. It bundles message bursts into one reply and hands the conversation to a human whenever the customer asks or the rules say so. Before the agent ever meets a real customer, the Laboratory sends six simulated customers at it, from the decided buyer to the angry one, and an independent judge scores each conversation from 0 to 100 with findings and one-click fixes you can re-test after every change. Owners create team accounts, message templates sync their approval status from Meta, and WhatsApp tokens sit encrypted at rest while every customer record stays on hardware you own. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
DeepTutor
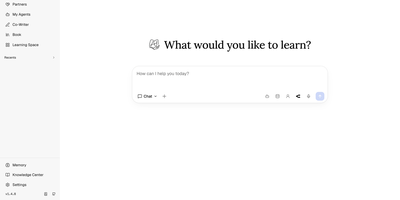
With 34,000+ GitHub stars and a v1.5 release driven by 36 merged community pull requests, DeepTutor from Hong Kong University's Data Science Lab delivers a full agent-native learning workspace that goes far beyond chatbot wrappers. Eight integrated surfaces — Chat, Deep Solve, Quiz Generation, Deep Research, Math Animator, Co-Writer, Book generation, and Mastery Practice — share a unified context so the objective follows the learner, not the tool. The platform's three-layer memory architecture (L1 working, L2 session, L3 long-term) makes personalization inspectable rather than opaque, letting users see exactly what the system remembers and why. Knowledge retrieval operates across five pluggable engines — LlamaIndex with FAISS vectors, PageIndex for page-level citations, GraphRAG for knowledge-graph traversal, LightRAG for local or server-offloaded retrieval, and linked Obsidian vaults — with document parsing via MinerU, Docling, markitdown, or PyMuPDF4LLM. Partners extend the tutoring brain to 15+ messaging platforms including Slack, Discord, Telegram, Matrix with E2EE, and Mattermost, each carrying private memory with branch, resume, and replay capabilities. Subagent integration brings Claude Code, Codex, Gemini, and Kimi directly into learning sessions. The system supports 30+ LLM providers from OpenAI and Anthropic to Ollama for fully local operation, with multi-user isolation, admin controls, and a full CLI interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Casibase
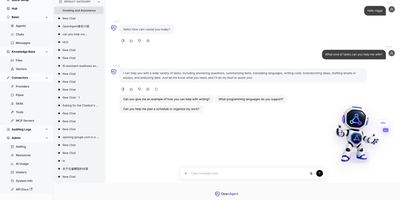
Casibase lets organizations build AI-powered knowledge bases that answer questions from their own documents, connecting to 30+ model providers through a unified admin interface with RAG retrieval and multi-agent orchestration via MCP and A2A protocols. The platform plugs into OpenAI GPT-4o, Anthropic Claude, Meta Llama, Google Gemini, DeepSeek, Ollama local models, HuggingFace, Azure OpenAI, and additional providers, while embedding APIs from OpenAI Ada and Baidu handle vector representation of ingested documents. Document ingestion parses TXT, Markdown, DOCX, PDF, CSV, XLSX, and PPTX files with intelligent chunking strategies for optimal retrieval accuracy. The built-in chat interface provides real-time AI conversations with manual session handover for human agent escalation, and comprehensive chat session logging enables audit trails for compliance. Enterprise identity management integrates Casdoor for Single Sign-On supporting GitHub, Google, WeChat, and OIDC providers with fine-grained access control via the Casbin permission engine. The multi-tenant architecture supports isolated knowledge bases per organization with role-based user management and configurable storage, model, and embedding providers per tenant. The React frontend with Ant Design v5 provides a polished admin dashboard for managing providers, knowledge stores, chat sessions, and user access, while the Go backend with Beego framework handles API logic with MySQL or MariaDB persistence. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
LobeHub
With over 82,000 GitHub stars and 700,000+ downloads, LobeHub has evolved from its origins as LobeChat into a comprehensive multi-agent AI collaboration platform where humans and autonomous agent teams co-evolve. The platform's Agent Harness architecture functions as an operating system between AI models and applications, handling prompt presets, tool orchestration, lifecycle hooks, planning, filesystem access, and sub-agent management across 25+ model providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Mistral, Groq, AWS Bedrock, Azure OpenAI, and local models through Ollama. Agent Groups enable sophisticated collaboration with sequential, parallel, iterative, and debate orchestration modes, allowing multiple specialized agents to tackle complex workflows simultaneously. The Agent Builder creates production-ready agents from natural language descriptions with auto-configuration, drawing from a marketplace of 505+ pre-built agents and 10,000+ MCP-compatible skills and plugins. Pages provide collaborative document editing with multi-agent co-authoring, while Schedules automate agent runs around the clock without human supervision. The knowledge base leverages PostgreSQL with pgvector for RAG-powered retrieval, and Personal Memory gives agents transparent, editable context that evolves through continual learning. The full self-hosted stack deploys via Docker Compose with PostgreSQL, Redis, RustFS for S3-compatible storage, and SearXNG for private web search, all configurable through environment variables. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. LobeHub Community licensed.
AstrBot
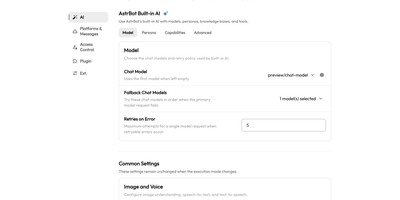
Getting a language model into the chat apps people already use takes a single self-hosted server running AstrBot, which answers in QQ, Telegram, Discord, Slack, Lark, DingTalk, LINE, and WeCom. The model itself is a setting. OpenAI-compatible endpoints, Anthropic, Google Gemini, DeepSeek, Ollama, and LM Studio all work, with fallback models and retry limits for failed requests, and Dify, Coze, or Alibaba Cloud Bailian can take over a conversation too. A bare model cannot act, so the built-in agent calls MCP servers and Skills, delegates to SubAgents, runs scheduled tasks, and executes code in an isolated sandbox. It cannot read your files either, so a knowledge base takes PDF, Word, Markdown, and EPUB uploads and searches them with hybrid dense and BM25 retrieval. Personas shape each bot's personality, and Whisper or Edge TTS adds speech. When an answer looks wrong, the ChatUI shows thinking, tool calls, token counts, and latency, and a per-message trace timeline shows how the bot got there. Because the panel steers the bot, administrator IDs, session whitelists, optional TOTP login, and HTTPS protect it. Backups live under System Settings, and the plugin market installs any of more than 1,000 extensions in one click. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Dialoqbase
Retrieval-augmented chatbots on your own knowledge base - that is the whole mission of Dialoqbase, an open-source bot-building platform. Feed it content through a broad set of data loaders - web pages and full crawls, sitemaps, PDFs, DOCX, CSV, plain text, GitHub repositories, YouTube videos, and MP3/MP4 audio - and it handles the whole RAG pipeline in one self-contained app: chunking, embedding, vector storage, and LLM querying. The distinguishing architecture choice is PostgreSQL with pgvector for embedding storage and similarity search, which removes the separate vector-database dependency, and Redis-backed Bull queues for ingesting large documents without blocking the API. Model choice is wide open: OpenAI, Anthropic Claude, Google Gemini, Cohere, Fireworks, Hugging Face, local models via Ollama, and any OpenAI-compatible endpoint, with an equally broad list of embedding providers. Finished bots embed on any website with customizable styling or deploy to Telegram, Discord, and WhatsApp, and an API creates and manages bots programmatically. Multi-user support adds registration limits and per-user bot quotas. MIT-licensed and free for commercial use.
OpeniLink Hub
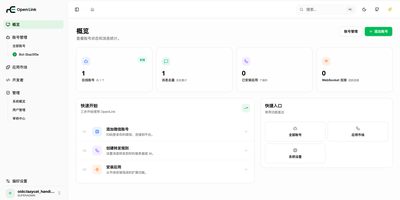
OpeniLink Hub turns a personal WeChat account into a programmable bot platform, with a web console, multi-bot management, and a one-click app marketplace that wires WeChat to Lark, Slack, GitHub, Notion, and twenty other services. Bind accounts by scanning a QR code, then watch every bot's status, expiry window, and message flow from one dashboard. Install marketplace apps without writing code: Lark gains 34 AI-callable tools across calendars, docs, tasks, and meetings, while GitHub brings 36 tools for issues, pull requests, and Actions. Every incoming message fans out in parallel over WebSocket for millisecond pushes, Webhook callbacks to your own servers, and an AI channel that answers through any OpenAI-compatible API. Message tracing follows each message from receipt to delivery, showing exactly which hop stalled when something breaks. Passkey sign-in with fingerprint or hardware keys keeps the console protected, with GitHub and LinuxDo OAuth as alternatives. Reminders, expense tracking, currency conversion, RSS digests, and cron-scheduled pushes run as installable apps, and expiry reminders warn you before the 24-hour reply window closes. Build your own integrations with official SDKs for Go, Node.js, Python, PHP, Java, C#, and Lua, or expose local CLI commands as chat-callable tools with the Runner app. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MaxKB
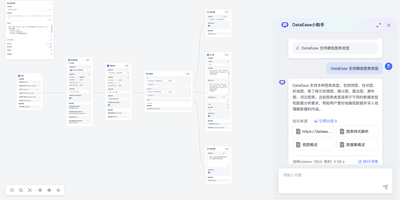
Support teams, IT departments, and researchers can put their own documents behind chatbots and AI agents built with MaxKB, an open-source platform that grounds answers in private knowledge. A support lead starts by uploading Markdown, DOCX, PDF, TXT, HTML, XLSX, XLS, or CSV files, or by syncing a web site, and MaxKB splits, vectorizes, and indexes the content on its own. An IT department can place the finished agent in any third-party site or internal tool with no coding, as a full-screen page, a mobile view, or a floating chat window. Researchers get replies that show, and let them download, the knowledge sources behind each answer. Simple agents pick tools, skills, and MCP connections from the question itself, while advanced agents are drawn as workflows with branching, multi-path recall, loops, and variables. Custom scripts, which AI can help write, plus schedules and event triggers extend what an agent can do. The model manager registers local models such as DeepSeek, Llama, and Qwen beside providers such as OpenAI, Claude, and Gemini, across language, embedding, reranking, vision, speech, and image generation. Conversation logs feed analysis for operations. Dozens of ready-made agent templates, knowledge base templates, tools, and skills in the template center and tool store shorten the first build. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Nanobot
With over 46,000 GitHub stars, nanobot is the ultra-lightweight personal AI agent framework that delivers full agentic capabilities — tools, persistent memory, multi-agent workflows, scheduled automation, and 10+ chat channel integrations — in approximately 4,000 lines of readable Python core code. The agent loop receives messages from any connected channel, builds context from session history and long-term memory files, calls the configured LLM provider, executes requested tools, and publishes replies back to the originating channel. Supported LLM providers include OpenAI, Anthropic, Google Gemini, DeepSeek, Qwen via DashScope, Moonshot/Kimi, Ollama, vLLM for local models, and any OpenAI-compatible API through OpenRouter or LiteLLM. Chat channels connect the agent to Telegram, Discord, Slack, WhatsApp, Feishu/Lark, DingTalk, Email via IMAP/SMTP, QQ, Matrix with end-to-end encryption, Mattermost, and the built-in browser WebUI served from the published Python wheel with no separate frontend build. Built-in tools include filesystem read/write/edit, shell execution with configurable sandboxing via bubblewrap, web search and fetch with SSRF protection, MCP server integration, cron scheduling, image generation, and subagent spawning for parallel task delegation. The Dream memory system consolidates session history into persistent markdown files for long-term context retention across conversations. Deployment runs as a CLI agent, a persistent gateway server, a Docker container with Docker Compose, or an OpenAI-compatible API server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
FastGPT
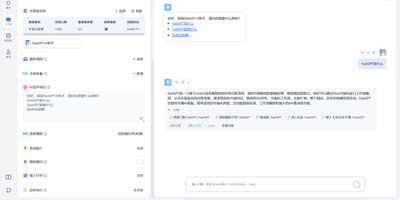
FastGPT lets you build production AI agents and knowledge base chatbots through a visual drag-and-drop workflow editor, connecting any LLM provider to your documents with retrieval-augmented generation that cites sources and reduces hallucination. The workflow canvas chains LLM calls, conditional branching, HTTP requests, code sandbox execution, and plugin nodes into complex conversation flows and agent skill pipelines without writing backend code. The knowledge base engine ingests documents in ten formats (TXT, Markdown, HTML, PDF, DOCX, PPTX, CSV, XLSX, URL scraping, and CSV batch import) then applies automatic chunking, hybrid vector retrieval with semantic reranking, and QA-pair splitting to deliver accurate, citation-backed answers. FastGPT connects to virtually any LLM provider through its AI Proxy aggregation layer: OpenAI GPT-4o, Anthropic Claude, Google Gemini, DeepSeek, Qwen, ERNIE Bot, and models hosted via Ollama all work through a unified OpenAI-compatible API. Bidirectional MCP support enables agents to call external tools and expose their own capabilities to other systems. Completed applications can be shared via login-free links, embedded as iframe widgets, or integrated with WeCom, Lark, DingTalk, and WeChat Official Accounts through the published REST API. Application operation logs, conversation annotation, and per-model usage analytics provide full lifecycle governance for compliance-sensitive deployments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. FastGPT Open Source License (Apache 2.0 based) licensed.
RAGFlow
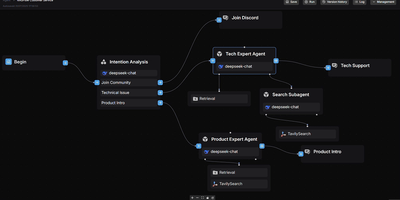
RAGFlow has established itself as one of the most widely adopted open-source RAG engines available, powering production AI systems that demand traceable, hallucination-free answers from complex enterprise data. The platform processes PDF, DOCX, Excel, and PPT files through vision-based deep document understanding with layout analysis and OCR, extracting structured knowledge from tables, charts, and images that simpler parsers miss entirely. RAGFlow's hybrid retrieval pipeline combines vector search with BM25 keyword matching and multi-stage reranking across configurable document stores including Elasticsearch, InfiniFlow's Infinity engine, OpenSearch, and OceanBase. Developers connect any combination of LLM providers — OpenAI, DeepSeek, Anthropic Claude, Google Gemini, and locally-hosted models via Ollama — through a unified configuration layer. The visual agent workflow system enables multi-step reasoning chains with persistent memory, tool calling, and pre-built templates for common enterprise scenarios. RAGFlow synchronizes data from Confluence, S3, Notion, and Google Drive, and delivers answers through chat integrations with Feishu, Discord, Telegram, and Line. The Python SDK and RESTful API on port 9380 provide programmatic access to knowledge base management, document parsing, and conversational retrieval. The full stack deploys via Docker Compose with MySQL for metadata, Redis for task orchestration, and MinIO for object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Rakazo
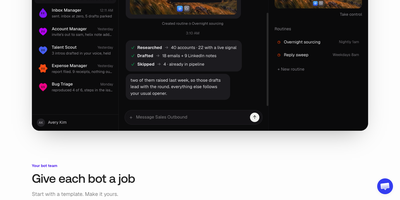
Rakazo lets you hire AI bots the way you would onboard teammates: each gets a job, persistent memory, its own sandboxed computer, and a schedule, and it reports back in chat while you check in from any device. Start from templates such as Sales Outbound, Inbox Manager, Talent Scout, Expense Manager, Coding Agent, or Chief of Staff, then tune the instructions, tools, and limits until the bot works the way your team works. Every bot can run on a different model, so research uses one provider while coding uses another, and a local model served by Ollama or LM Studio keeps sensitive work off third-party servers. Bots work on real computers with a browser, terminal, file system, and graphical desktop you can watch or take over, choosing shared team computers or isolated private ones. When a task outgrows one bot, it delegates pieces to peer bots or short-lived subagents and folds their results back into its own thread. Voice mode lets you dictate messages and hear spoken replies, while routines run on schedules so follow-ups, reports, and inbox sweeps happen while you are away. You decide which actions need your approval before a bot takes them, and integrations via Composio, Pipedream Connect, MCP servers, and OpenAPI documents connect bots to tools you already use. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Whatomate
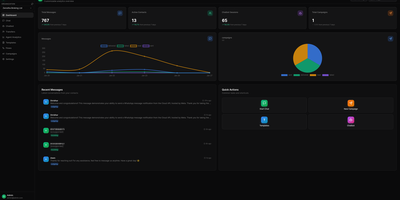
A complete WhatsApp Business Platform covering messaging, chatbot automation, and voice calling with IVR — a combination most self-hosted projects never attempt. The Fastglue/fasthttp backend processes WhatsApp Cloud API webhooks through PostgreSQL and Redis into a real-time WebSocket layer powering instant chat updates across a Vue 3 frontend built with shadcn-vue and TailwindCSS. Chatbot automation supports keyword triggers, multi-step conversation flows with branching logic, AI-powered responses from OpenAI, Anthropic, or Google models, knowledge base integration via vector stores, and seamless handoff to human agents when the bot gets stuck. The visual IVR builder uses a drag-and-drop node canvas where you wire greeting prompts, DTMF menu capture, HTTP callbacks to external APIs mid-call, business-hours routing by IANA timezone, agent team transfers with hold music, and reusable sub-flows. Every call recording streams encrypted to your S3-compatible bucket with retention you control. Multi-tenant architecture isolates organizations with separate data, roles, and API keys while a unified inbox presents both chat and call conversations to agents in a single dashboard. Meta-approved template management, bulk campaign messaging, analytics tracking, and a full REST API round out the platform. Deploy via Docker Compose with Postgres and Redis included. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
Live Helper Chat
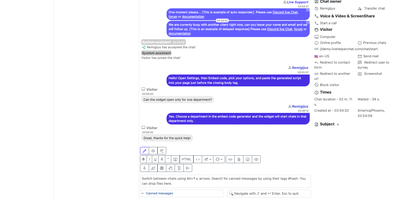
Add a live support desk to any website with Live Helper Chat, where visitors talk to operators or bots and you own every transcript. Site owners paste a generated embed snippet into any page, and the start-chat fields are customizable. Chats are routed by department, language, location, or custom attributes, wait in a priority queue, and move between agents. Operators, departments, and simultaneous chats are unlimited. Agents watch a visitor type before the message is sent, read pages visited and time on site in the online visitors list, and send proactive invitations to people who linger. Voice, video, and screen sharing run through Jitsi or Agora, and a screenshot shows what the visitor sees. Bot designers chain triggers and actions in a visual builder, call ChatGPT, Gemini, Ollama, Rasa, or any REST API, and hand the conversation to a person when needed. Incoming email becomes tickets beside chats, and extensions connect Telegram, WhatsApp, Facebook Messenger, and Twilio SMS. Staff answer from the browser, a desktop app, a Chrome extension, or iOS and Android apps. Management tools include roles, groups, statistics, transcripts, and an archive, and extensions add two-factor login, LDAP, and single sign-on. It suits banks, healthcare teams, universities, and game studios that must keep chat data in house. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Tiledesk
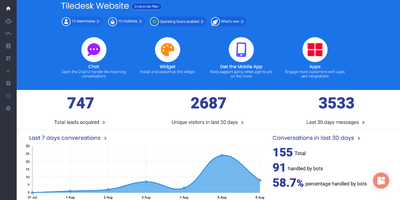
Tiledesk lets you build AI-powered conversational agents with a visual drag-and-drop designer, then deploy them simultaneously across web chat, WhatsApp, Telegram, Facebook Messenger, Instagram, email, and Slack without rebuilding per channel. The no-code Design Studio combines LLM-powered conversations with conditional logic, external API calls, and branching dialogue trees that work identically everywhere. Multi-RAG knowledge management separates content into isolated repositories with hybrid search combining traditional full-text retrieval and semantic understanding via Qdrant vector embeddings, enabling accurate answers even when users phrase queries in unexpected ways. LLM integration supports GPT-4, GPT-4o, Anthropic Claude, and any model exposing an OpenAI-compatible API including locally hosted models via Ollama for complete data sovereignty. The human-in-the-loop system provides seamless escalation from AI agents to live support staff with full conversation context preserved, while multi-agent workflows enable complex orchestration where specialized bots collaborate on different aspects of a customer interaction. REST and MQTT APIs power integration with external systems and webhook-triggered automations, and pre-designed templates accelerate common scenarios. Docker Compose deployment starts the full stack including server, dashboard, messaging engine, and widget. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Whirl
Whirl puts every top AI model in a single conversation and remembers what you were working on last week, so you can switch models mid-thought without losing the thread. Ask for a report, a chart, or a small interactive page and it appears as a living artifact in a side panel, still editable while you keep chatting, and shareable by link when it is ready to leave the conversation. Connect your own tools over MCP, with OAuth sign-in handled for you, or install skills that teach the app new tricks your team relies on. Long-term memory carries your preferences and project context from chat to chat, and live web search with page reading grounds answers in today's pages instead of the model's training data. Sensitive threads can be locked with a password that encrypts them on your device, where the server never sees the key and only zero-retention models may answer. Around those headline pieces sits the everyday kit: incognito mode, a message queue for when you think faster than the model replies, voice input, image generation, file attachments, folders, and sharing controls. An admin console manages the model catalog, integrations, and skills, and the interface itself switches between light and dark with your choice of accent color, installable as a mobile web app. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.