Firecrawl
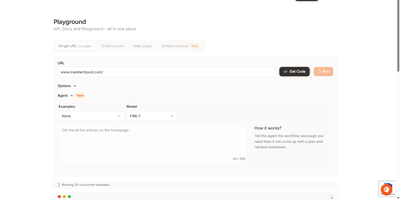
With over 164,000 GitHub stars and one of the fastest-growing open-source projects in the AI tooling ecosystem, Firecrawl is the web context API that turns any website into clean markdown, structured JSON, or screenshots optimized for large language models. The Scrape endpoint converts a single URL into LLM-ready output with approximately 67% fewer tokens than raw HTML, handling JavaScript rendering, rotating proxies, anti-bot bypasses, and dynamic content extraction with zero configuration. The Crawl endpoint recursively scrapes entire websites from a single request with configurable depth, URL filters, and concurrent page limits. The Map endpoint discovers all URLs on a domain instantly for sitemap generation. The Search endpoint performs web searches and returns full page content from results. The Interact endpoint scrapes a page then continues working with it — clicking buttons, filling forms, and extracting dynamic content using AI prompts or code. The Agent endpoint provides autonomous web data gathering where users describe what they need in plain English. SDKs are available for Python, Node.js, Go, Rust, Ruby, PHP, Java, C#/.NET, and Elixir, with an MCP server for connecting to any AI agent or MCP client. Self-hosting deploys via Docker Compose and requires Redis and a Playwright-based browser service for JavaScript rendering. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
PullMD
PullMD turns any URL or file you point it at into clean Markdown your AI agent can actually afford to read. Paste a web page and get back tidy body text with metadata tucked into frontmatter instead of navigation soup and cookie banners. Send it a Reddit or Hacker News thread and it returns the full comment tree with depth and count under your control. Hand it a PDF, Word file, PowerPoint, spreadsheet, or EPUB and it hands back Markdown, with an optional OCR tier for stubborn table-heavy documents. YouTube links come back as title, description, and a transcript with clickable timecodes, no API key required. The query-scoped mode answers a question about a long page by returning only the relevant sections, typically cutting 70 to 95 percent of the tokens. Every conversion gets a short share link that re-fetches the source when it goes stale and serves the last good snapshot if the original dies. Agents connect through the built-in MCP server with OAuth 2.1, a plain REST API, or a downloadable Claude Code skill, while you keep history, an archive, and cache statistics in the web app. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Google Maps Scraper
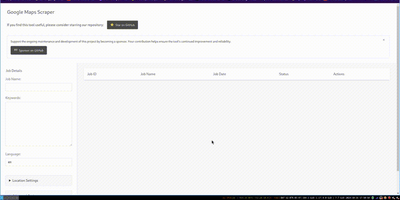
The leading open-source tool for extracting business leads from Google Maps at production scale. The Go-based engine processes approximately 120 places per minute with optimized concurrency, extracting 33+ data points per listing including business name, address, phone number, website URL, rating, review count, latitude and longitude, opening hours, price level, and optionally crawling business websites for email addresses. Three interfaces serve different workflows: the CLI accepts query files for cron jobs and CI/CD pipelines with output to CSV, JSON, PostgreSQL, S3, or LeadsDB; the Web UI provides a browser-based dashboard with real-time job monitoring, a map view of scraped places, and interactive query submission; and the REST API at /api/v1 enables programmatic integration with full Swagger documentation at /api/docs. Built-in proxy rotation supports SOCKS5, HTTP, and HTTPS with authentication for large-scale runs, while the architecture scales from a laptop to Kubernetes clusters with queue-based worker distribution. The SaaS edition adds multi-user access with API key management, admin UI with 2FA, job queue orchestration, and one-command cloud deployment via an interactive wizard. An AI Agent Skill enables coding agents to run scrapes programmatically. Deploy via Docker or build from source requiring Go 1.26.5+. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
SurfSense
Positioned as the open-source NotebookLM alternative for AI agents, SurfSense delivers a live web research platform where your agents access structured data from Reddit, YouTube, Instagram, TikTok, Amazon, Walmart, Google Maps, Google Search, Indeed, and any page on the open web through one REST API or MCP server. Scheduled and event-triggered agents transform findings into briefs, alerts, podcasts, and presentations, while a built-in knowledge base keeps every discovery searchable with Perplexity-style cited answers using hybrid semantic and full-text search powered by PostgreSQL with pgvector. Upload PDFs, Office documents, images, and audio files, or sync Google Drive, OneDrive, and Dropbox — 50+ file formats supported with AI file sorting that auto-organizes documents by source, date, and topic. The MCP server exposes scrapers, knowledge base, and workspaces as native tools for Claude, Cursor, and any MCP-compatible agent. Cross-country proxy rotation handles Reddit, TikTok, and Google Search scraping with geo-aware sticky sessions and captcha-aware anti-bot handling. The platform features collaborative chats, multi-format document export, git-native knowledge base with Open Knowledge Format export, and a desktop quick-ask panel with global shortcut. Docker Compose deployment manages nine services including Caddy proxy, PostgreSQL, Redis, FastAPI backend, Celery workers, zero-cache real-time sync, and Next.js frontend with automatic Watchtower updates. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Lightpanda
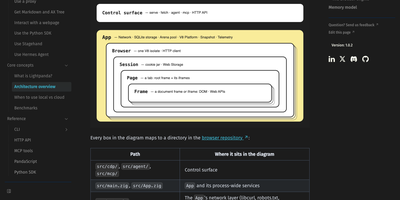
Lightpanda is a headless browser built for AI agents and automation that loads and runs web pages without ever drawing them, so crawling, scraping, and agent browsing finish far faster and lighter than in Chrome. You drive it with the tooling you already have: Puppeteer, Playwright, and Chromedp connect over the Chrome DevTools Protocol, Selenium works over WebDriver BiDi, and existing Chrome automation scripts keep running against the new endpoint. Scripts can execute JavaScript on real pages, wait for network activity, read and mutate the DOM, submit forms, and pull structured data out of dynamic sites that plain HTTP clients cannot see. An MCP server mode hands the browser to AI applications as a callable tool, so a model can open pages, follow links, and read content in the middle of an agent workflow. The built-in agent accepts plain-language browsing tasks and can export what it did as PandaScript, a replayable JavaScript file that runs later with no model call at runtime. A fetch command loads one or more URLs and prints the result as HTML or Markdown, which turns page extraction into a single shell step inside data pipelines. In the project's published crawl benchmark it processed pages roughly nine times faster than headless Chrome at a fraction of the memory, so one server can hold many more concurrent browsing sessions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Pagesift
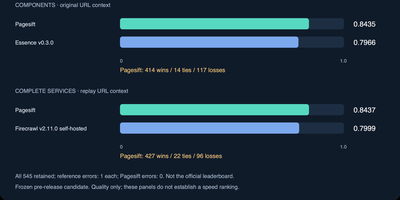
Pagesift converts messy web pages, PDFs, and Office documents into clean Markdown and structured JSON that language models can actually use, from one self-hosted binary you run yourself. Call it the way you already call Firecrawl: the HTTP API speaks the Firecrawl v1 and v2 formats, so existing scrape, crawl, and batch jobs point at your server instead, and a Jina Reader style endpoint answers simple /r/ URL requests. Scrape a single page, submit batches, or crawl whole sites with sitemap support, focused crawling by query, robots.txt respect, and per-host rate limits by default. Headless rendering kicks in only when a page needs JavaScript, keeping plain pages fast. Documents work offline too: Word, Excel, PowerPoint, EPUB, and CSV files become Markdown with titles, links, images, and publication metadata attached. Jobs persist so long crawls survive restarts, webhooks report completions, and per-API-key limits and quotas keep multi-tenant use civilized, with Prometheus metrics and a health endpoint for operators. AI agents can drive the same engine directly through the bundled MCP server over stdio or HTTP, while developers get Python, Node, and Rust libraries. Memory stays bounded under load by design, sized from container limits rather than hope. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
CRW
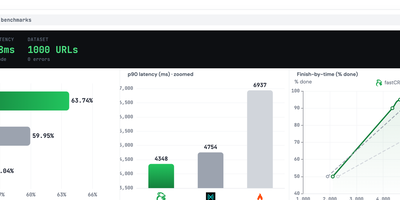
CRW gives your apps and AI agents a private web data API that scrapes pages, crawls sites, maps links, and searches the web without sending every request to a hosted scraping service. Post a URL to the scrape endpoint and receive clean Markdown, HTML, screenshots, links, or structured JSON shaped by a schema you supply. Start a crawl when a whole section matters, then poll for progress while CRW walks pages asynchronously and returns the collected content in one job. Use map first to discover the URLs on a site before spending effort extracting pages you do not need. Connect agent tools through the MCP endpoint so assistants can search, scrape, and crawl from the same self-hosted service your applications call. Add browser rendering when JavaScript-heavy pages hide content from a plain HTTP fetch, and keep simpler pages on the fast lightweight path. Protect a public deployment with Bearer token authentication, your own reverse proxy, logging, and rate limits, or keep the service inside a private network for internal tools. Run one Docker container for the core API, or use the Compose stack when you want bundled search and rendering sidecars beside it. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
PriceBuddy
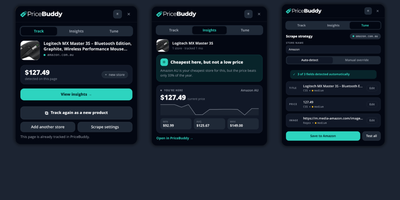
Waiting for the right moment to buy usually means refreshing product pages for weeks, so PriceBuddy does the refreshing for you and speaks up when the price is right. Paste a product URL and it fetches the details and price, then rechecks on a global schedule or a per-product interval from every 5 minutes to every 24 hours. Stores are scraped with CSS selectors, regular expressions, or JSONPath, a headless browser covers JavaScript-heavy shops, and an optional AI provider (OpenAI, Anthropic, Gemini, or local Ollama) can recover missing prices or repair broken selectors. Attach several URLs to one product to compare retailers or marketplace listings, with in-stock, pre-order, and discontinued states shown beside each source. Unit pricing reveals the real cost per tablet or bag when multi-packs distort shelf prices, while history charts show minimum, maximum, and average over time. Alerts fire on a target price, a drop threshold, or a back-in-stock event and arrive by in-app notice, email, Pushover, Gotify, Apprise, Telegram, Discord webhook, or ntfy. Tags sort products into draggable dashboard groups, with optional smart sections for what to buy now, recent drops, and failed checks. Each user keeps separate products and settings, a REST API with scoped tokens serves your scripts, and a Chrome and Edge extension tracks items from the page you are viewing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Crawl4AI
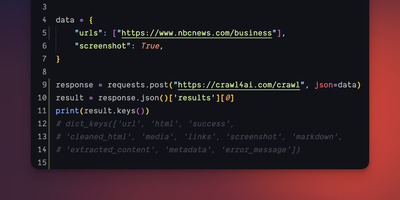
With over 77,000 GitHub stars, Crawl4AI is the most-starred open-source web crawler on GitHub and the go-to tool for converting the web into AI-ready data. Built on Python and Playwright, it transforms any website into clean Markdown with headings, tables, code blocks, and citation hints optimized for LLM ingestion, or extracts structured JSON via CSS selectors, XPath expressions, or direct LLM-based schema extraction through OpenAI, Anthropic, and Ollama providers. The self-hosted Docker server exposes a REST API on port 11235 with endpoints for crawling, streaming results, screenshots, PDF generation, JavaScript execution, and LLM-powered extraction. Version 0.9.x introduced secure-by-default operation with mandatory JWT authentication, strict request validation, declarative hooks replacing inline code, and bounded job queues. Adaptive crawling uses information foraging algorithms to determine when sufficient data has been gathered, while deep crawl mode traverses link graphs intelligently. The async browser pool manages concurrent sessions with stealth plugins, proxy rotation, custom headers, and session persistence for authenticated scraping. A built-in MCP server enables direct integration with Claude, ChatGPT, and Cursor for AI-driven web research workflows. Content filtering applies BM25 and TF-IDF relevance scoring to extract only pertinent sections from noisy pages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
RSS-Bridge
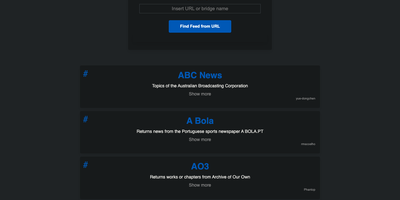
RSS-Bridge gives a feed to every website that never offered one, so social profiles, video channels, and news pages become subscriptions for any feed reader. Pick a bridge, enter a username or search term, and the generated URL returns Atom, JSON, HTML, MRSS, plaintext, or Sfeed output. Dedicated bridges cover YouTube channels and playlists, public Telegram channels, Reddit users and subreddits, Mastodon instances, Twitch channels, TikTok accounts, SoundCloud users, and Rumble channels. When a site has no bridge, CssSelectorBridge and XPathBridge scrape its pages into a feed from the CSS selectors or XPath expressions you provide. FilterBridge keeps or drops items by keyword, FeedMergeBridge folds several feeds into one stream, and FeedReducerBridge thins out noisy sources. Caching keeps upstream services from banning your server for repeated updates, and a token or HTTP basic authentication keeps a private instance closed to strangers. The enabled_bridges setting limits which bridges appear in the menu, and a failing bridge reports its error as a feed item, so your reader notifies you the moment one breaks. A new bridge is one small class file dropped into the bridges folder, and a mounted config folder carries your custom settings across container restarts. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Unlicense licensed.
JobNavigator
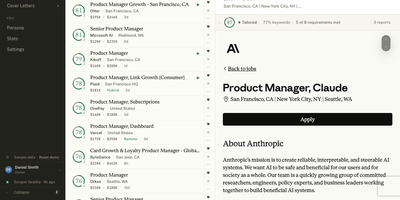
JobNavigator runs your whole job hunt as an automated pipeline, scraping career pages and job boards, scoring every posting against your résumés, and tracking each application to its outcome. Discovery fans out across company career pages through twelve ATS handlers, aggregators like LinkedIn, Indeed, and ZipRecruiter, and a Chrome extension that saves any posting you stumble on. Each new job is scored against your base résumés, lightly for a quick number or in full, with keyword coverage and requirement mapping that show exactly where you match and where you do not. Strong matches get a tailored résumé from eight PDF templates and a cover letter written from your persona, ready for your review before anything is sent. The extension then auto-fills application forms and drafts answers to free-text questions from your stored Q&A bank. Every application moves through stages and interviews in one tracker, while Gmail polling spots replies and updates the status for you, and Telegram delivers new-job alerts and a daily digest. A household can share one install with up to five accounts, each keeping its own jobs, résumés, and PIN, while scraping runs once for everyone. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Change Detection
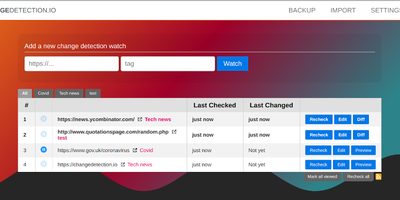
Price drops, restocks, job postings, government announcements, competitor edits - changedetection.io watches web pages and alerts you the moment anything changes, down to PDF text and checksums. Point it at a URL, set a check interval, and precise filters decide what counts as a change: a Visual Selector targets page elements by pointing and clicking, CSS selectors and XPath narrow scope, trigger-text and ignore-text rules (with regex support) cut noise, and JSONPath or jq handles API responses. A dedicated re-stock and price detection mode extracts product metadata and fires on thresholds - alert only when the price drops below your target or the percentage change exceeds a limit. JavaScript-heavy sites render through a real Chrome browser via Playwright, with the ability to execute JS steps first (log in, click, scroll) before extracting text. Notifications reach 85+ services through Apprise - Discord, Slack, Telegram, email, webhooks - optionally with a screenshot of the changed page, and AI-powered summaries (any OpenAI-compatible endpoint, including local Ollama) describe what changed. Per-watch proxies, custom headers, and POST/GET control cover hostile targets. Apache-2.0 licensed with local file-based storage: the URLs you monitor and why stay entirely your business.
Huginn
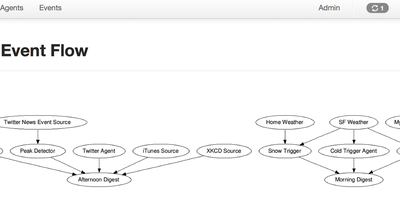
Huginn has established itself as the definitive open-source automation engine for developers who refuse to hand their workflow data to third-party cloud services. The platform lets you build agents that scrape websites, monitor RSS feeds, track weather via APIs, watch Twitter streams, aggregate news, detect price changes, and trigger notifications through email, SMS via Twilio, Slack webhooks, or social media posts to Twitter and Tumblr. Each agent creates and consumes JSON events, propagating them along a directed graph where complex multi-step workflows emerge from simple single-purpose components. The web interface provides visual agent management with drag-and-drop scenario building, real-time event logs, scheduling controls, and a built-in agent library covering dozens of use cases out of the box. Huginn supports Liquid templating for dynamic event transformation, regex-based content extraction, JavaScript-based data manipulation, and HumanTaskAgent for crowd-sourced workflow steps. Custom agents can be packaged as Ruby gems and loaded via the ADDITIONAL_GEMS environment variable without modifying core code. Deployment options include Docker with the official huginn/huginn all-in-one image or huginn/huginn-single-process for production multi-container setups with PostgreSQL or MySQL backends, plus native support for Heroku and OpenShift PaaS platforms. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
HeadlessX
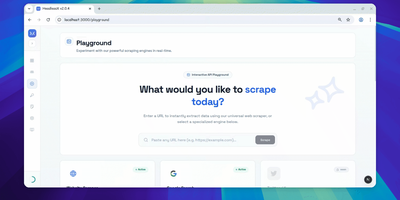
With 2,000 GitHub stars and 10 releases since its September 2025 launch, HeadlessX delivers a self-hosted browser automation platform that replaces Chromium-based scraping with Camoufox — a Firefox fork performing kernel-level fingerprint spoofing to achieve 0% detection across Cloudflare, DataDome, PerimeterX, and other anti-bot systems where Puppeteer and Playwright regularly fail. The web dashboard provides workspace-based job organization with a visual interface for configuring scrape targets, managing browser profiles, monitoring queue status, and viewing extracted results in real time. The protected REST API accepts requests with API key authentication for programmatic access, supporting HTML extraction, screenshot capture, PDF generation, and structured data parsing with configurable stealth parameters. Profile-based scraping maintains persistent browser contexts with cookie jars, localStorage, and fingerprint configurations that survive between requests — reducing cold-start latency from 25 seconds to under 2 seconds on subsequent requests. Queue-backed workflows enable batch processing of URLs with configurable concurrency, retry logic, and webhook notifications on completion. The Google AI Search integration provides AI-assisted web research workflows through dedicated endpoints. Remote MCP support exposes automation capabilities as tool endpoints for AI agent integration. Deploy via the official CLI with `headlessx init` and `headlessx start` commands, scaffolding a Docker Compose stack with Caddy reverse proxy for automatic HTTPS. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Maxun
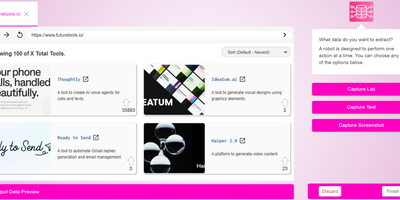
With over 16,800 GitHub stars and growing rapidly, Maxun has become the go-to open-source platform for teams who need structured web data without writing scrapers. The TypeScript-based platform provides a no-code visual recorder that captures point-and-click interactions in real-time browser sync, automatically generating reusable extraction robots that handle pagination, infinite scrolling, and dynamic content. LLM-powered extraction accepts natural language prompts like "Extract 10 companies from the Y Combinator website" without requiring a URL — Maxun identifies the source and performs the extraction autonomously. The platform handles authentication-protected pages, adapts automatically to website layout changes through self-healing selectors, and exports directly to Google Sheets, Airtable, or any destination via webhooks. Robots run on configurable schedules with cron-based timing, turning any website into a perpetually fresh RESTful API endpoint. The crawl engine discovers and processes linked pages across entire domains with configurable depth and URL filtering, while the search capability runs automated queries across multiple engines. Official Node.js and Python SDKs provide programmatic control over robot creation, execution, and data retrieval, with MCP integration enabling direct connection to AI tools like Claude. The n8n community node enables workflow automation without custom code. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Skyvern
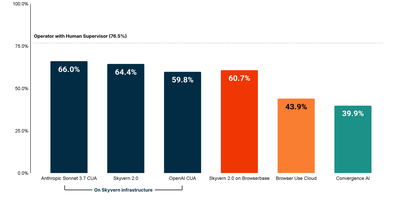
Scoring 64.4 on the WebBench benchmark — state-of-the-art among browser automation platforms — Skyvern replaces brittle XPath-based scripts with Vision LLM reasoning that adapts when websites change their layouts. The platform extends Playwright with AI-powered page methods including page.act(), page.extract(), and page.validate() that accept natural language prompts while still supporting traditional CSS selectors as fallback. The drag-and-drop Workflow Studio offers 17+ block types including navigation, extraction, login, loops, conditionals, code blocks, file download, and file upload — enabling non-technical users to build complex multi-step automations without writing code. Self-hosted deployments support bring-your-own-LLM with OpenAI, Anthropic, Gemini, and Ollama, while the multi-engine architecture allows swapping between Skyvern 2.0, OpenAI CUA, Anthropic CUA, or UI-TARS per task with a single parameter. Built-in infrastructure handles persistent browser sessions preserving cookies and localStorage across runs, automatic CAPTCHA solving for reCAPTCHA and hCaptcha, anti-bot bypass for Cloudflare and DataDome, residential proxy rotation across 20+ countries, and a credential vault integrating with Bitwarden and 1Password for secure 2FA management. Real-time session livestreaming via WebRTC enables visual debugging, while step-by-step action logs with screenshots and full LLM diagnostic traces provide production observability. The MCP server integration exposes Skyvern as a tool for Claude, Cursor, Windsurf, and any MCP-compatible AI agent. Connect to 6,000+ apps through Zapier, Make.com, or self-hosted N8N workflows. Deploy via Docker Compose or pip install with a two-command setup. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Anakin
Backed by Y Combinator and powering scraping infrastructure across 195 countries, Anakin delivers a production-grade web scraping API purpose-built for AI agents and RAG pipelines that need clean, structured data from sites that actively block conventional scrapers. The single Go binary server handles JavaScript-heavy SPAs through its Camoufox anti-detect browser service with automatic fingerprint rotation, while the HTTP-first handler chain tries lightweight extraction before escalating to full browser rendering — keeping response times under 2 seconds for static pages. The built-in React 19 dashboard provides visual scraping with live results, job tracking with status filters, domain configuration management with handler chain CRUD, and proxy performance monitoring via Thompson Sampling scoring. Structured JSON extraction leverages Gemini AI to transform raw HTML into typed schemas without manual selector maintenance. SDKs span Python, TypeScript, Go, .NET, Java, and Ruby, while the MCP server exposes all 21 tools directly to Claude, Cursor, Windsurf, and any Model Context Protocol-compatible agent. The hosted platform extends the open-source engine with AI web search returning full page content with citations, multi-source agentic research across 20+ sources per query, Wire pre-built actions covering 944 websites with 5,201 structured endpoints, persistent browser sessions for authenticated scraping, and website change monitoring with scheduled alerts. Deploy via Docker Compose with three containers or run the binary directly with optional PostgreSQL persistence. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Steel Browser
With over 7,400 GitHub stars and benchmarked at 0.89 seconds average session lifecycle — 1.7x to 9x faster than competing browser automation platforms — Steel Browser delivers production-grade headless Chrome infrastructure purpose-built for AI agents that need to interact with the modern web. The TypeScript-based server exposes a REST API providing on-demand browser sessions with full CDP (Chrome DevTools Protocol) access, allowing connections from Puppeteer, Playwright, or Selenium through standard WebSocket endpoints without framework lock-in. Each session maintains persistent state including cookies, localStorage, IndexedDB, and authentication credentials across requests, enabling stateful multi-step agent workflows that survive session restarts. Built-in anti-detection includes stealth plugins, browser fingerprint randomization, and configurable user-agent rotation, while the proxy chain manager handles IP rotation through residential, datacenter, or custom proxy pools. CAPTCHA solving integrates natively so agents encounter fewer blocking interrupts during autonomous navigation. The Session Viewer provides real-time WebRTC-streamed visual debugging of live sessions and playback of recorded sessions with full network request logging. Browser Tools APIs convert any page to clean Markdown, readability-optimized text, PDF documents, or high-resolution screenshots with a single API call. The MCP Server integration exposes Steel sessions as tools accessible to Claude, Cursor, and other Model Context Protocol-compatible AI agents. Deploy via Docker with a single container or use Docker Compose for production configurations with automatic resource cleanup and session lifecycle management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.