drawDB
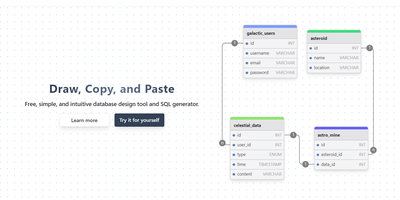
Schema design with no account and a few clicks: drawDB is the browser-based entity-relationship diagram editor and SQL generator - an AGPL-3.0 React project with over 37,000 GitHub stars. Draw tables with columns, data types, defaults, and constraints; connect fields to create foreign-key relationships; group tables into labeled subject areas; and annotate with notes. When the design is ready, one export produces CREATE TABLE DDL - with constraints, indexes, and foreign keys - targeted at MySQL, PostgreSQL, SQLite, MariaDB, SQL Server, or Oracle. Diagrams can be database-specific, unlocking every native type plus dialect features like PostgreSQL enums and composite custom types, or generic for portability across all supported flavors. The reverse direction works too: paste existing DDL into the import dialog and drawDB renders your live schema as a navigable diagram - the fastest way to document an inherited database. Versioning and migration-script generation track schema evolution, full editor ergonomics (undo/redo, copy/paste, duplicate, themes) keep iteration fast, and diagrams export as PNG, SVG, or shareable JSON. Everything runs client-side against browser storage - no backend database connection needed - so the self-hosted Docker deployment is a featherweight static app that keeps proprietary schema designs entirely on your infrastructure.
Mikochi
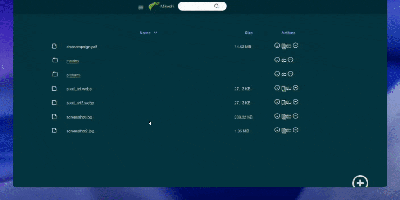
Point a browser at your server's folders and skip the FTP clients, the SSH tunnels, and the heavyweight cloud clones: Mikochi turns any directory on your machine into a clean web file browser you can open from anywhere. You browse nested folders in a fast list view, jump to files with fuzzy search, upload new material, create folders, rename items, and delete what is no longer needed. Whole directories come down as a single tar.gz archive, which makes backups and bulk transfers painless. Media files get a smarter treatment: Mikochi generates streaming links that open directly in VLC or mpv, so a film or album stored on the server plays on your screen without downloading gigabytes first. Access stays protected behind a username and password login with JWT sessions, and you can serve everything over TLS with your own certificates or disable authentication entirely on a trusted private network. Deployment takes one Docker command with a mounted data directory, and Kubernetes users get an official Helm chart. Homelab owners point it at a NAS share, developers drop it on a build box, and anyone tired of scp commands gets a permanent window into their files. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Bragibooks
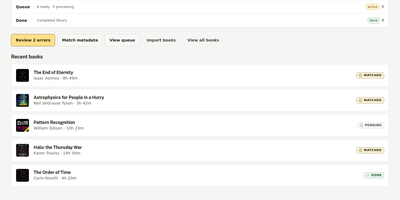
A folder of loose audiobook chapters goes in; a single, perfectly tagged m4b library comes out. Bragibooks is the operations board for that transformation: you select a batch of audiobook folders from your server, and it searches AudiobookDB to match each one with the right title, author, narrator, and release, with a custom search on hand when the first match is wrong. Confirmed books enter a processing queue where m4b-merge merges split mp3, m4a, and m4b parts, converts formats, strips stale metadata, and writes clean, consistently tagged files while you watch the live job output in your browser. Saved output profiles let you route different batches to different directories or path formats, and the books library keeps every finished title with its metadata, files, and processing history a click away. The whole thing runs as one container with the interface built in, a SQLite database on a mounted config volume, and access restricted to your local network by default, with an optional API key for external tools. Audiobook collectors use it to tame download folders before importing into their player of choice, and hoarders of split-chapter rips finally get uniform Chapter 01 style files. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Verdaccio
Private npm packages without shipping code to the public registry or paying for npm Enterprise: Verdaccio is the standard lightweight, zero-config private registry and caching proxy. It runs as a single Node.js process with its own tiny embedded database; no external database is required to start. Point npm, yarn, or pnpm at it and everything behaves as expected: install, publish, unpublish, dist-tags, and deprecation all work against the standard npm endpoints. The uplink system is where it earns its keep: packages not found locally are fetched from configured upstreams (npmjs.org, yarn, JFrog, Nexus, or another Verdaccio), cached as tarballs, and served locally thereafter - cutting CI latency and surviving registry outages. Multiple uplinks chain for failover, and per-package glob patterns in config.yaml route scopes to specific upstreams while controlling access, publish, and unpublish rights per group. You can even override a public package by publishing a patched version under the same name locally. A plugin architecture swaps in auth backends (htpasswd default, LDAP and others available), storage drivers (S3, Google Cloud Storage), middleware routes, and metadata filters. With official Docker images and a Kubernetes Helm chart, it slots into any pipeline in minutes.
RustXNG
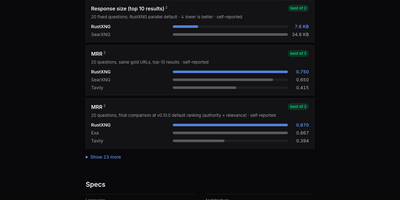
RustXNG gives your AI agents a private web search API that needs no keys, no accounts, and no per-search fees: ask once and get ranked results plus the text of the top pages, ready to ground an answer in real sources. A single request fans out to 180 search engines in parallel, drawn from 226 engine types covering general web, images, video, academic literature, package registries, and news, then merges what comes back with its own ranking that rewards term coverage and canonical-site authority instead of trusting any one engine's order. Engines that time out or keep answering nothing are suspended with backoff and rested automatically, so one dead source never stalls a task, and a repeated query returns from cache in about a hundredth of a second. Call it over HTTP with the familiar SearXNG-shaped JSON, CSV, RSS, or HTML formats, narrow results by domain, engine, or time range, or run the built-in MCP server and hand your agent native search and read_page tools with bounded, truncation-aware responses. Page fetches are hardened against untrusted URLs, an experimental local index can crawl your own corpus and merge it into results, and health, metrics, and per-engine status stay visible through the ops endpoints and the browser UI. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
JellyGlance
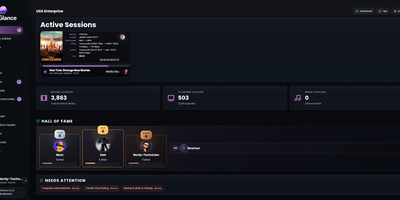
Running a Jellyfin or Emby server usually means a dozen open tabs; JellyGlance folds your whole media server into one screen you can leave open on a wall. Live sessions show who is watching what, from where, on which client, with direct play or transcode state, codec, bitrate, subtitles, and progress for every stream. Playback history accumulates in its own database, so statistics survive even when the media server forgets: top movies, series, libraries, clients, and users, watch-time trends, activity heatmaps, and weekly, monthly, and yearly recaps rendered as shareable cards. The home dashboard arranges by drag and drop, with presets, density controls, themes, kiosk mode for a wall display, and alert rules. Recently added shelves group by library, while library views surface totals and metadata gaps. Jellyseerr and Overseerr requests appear with poster cards, requester context, and admin actions, and the release calendar pulls upcoming titles from your *arr apps beside the queues of your torrent and Usenet clients, stalled items included. Wizarr invites, Tdarr transcodes, and Maintainerr cleanup connect from the same integrations area. Notifications travel by webhook, Discord, Gotify, and email newsletters, backups export to a plain folder, and sign-in spans local accounts, Jellyfin Quick Connect, and OIDC. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Papermark
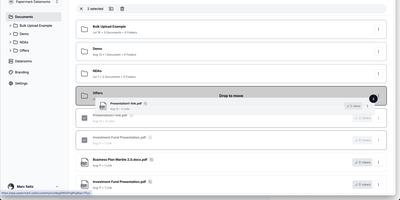
With nearly 9,000 GitHub stars and adoption by over 60,000 companies across 100 countries, Papermark is the open-source DocSend alternative that turns document sharing into a data-rich conversation between you and your viewers. Every shared document generates page-by-page analytics showing exactly which pages capture attention, how long viewers spend on each section, where they drop off, and whether they return for a second look, with real-time notifications the moment a document is opened. Virtual data rooms support unlimited folders with drag-and-drop organization, bulk uploads, granular per-viewer permissions, dynamic watermarking that stamps each page with the viewer's identity, and NDA gating that requires agreement before access. Custom branding applies your logo, colors, and custom domain to every shared link and download page, while email verification and password protection add authentication layers. The AI Data Room Copilot lets viewers chat with uploaded documents, ask questions, and receive contextual summaries directly within the data room interface. The developer platform exposes 43 REST API operations covering data rooms, documents, folders, links, visitors, and analytics, with an MCP server for AI agent integration and a CLI for automation. Built on Next.js with TypeScript, Prisma ORM, PostgreSQL, NextAuth.js authentication, and shadcn/ui components. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Deadair
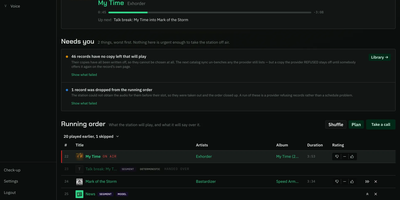
Somewhere in your house, a presenter is introducing the next record, and that presenter is a language model running on your own server. Deadair builds you a real radio station rather than another playlist: it picks records from your Navidrome, Jellyfin, Emby, or Plex library, or from Spotify, YouTube Music, Pandora, and Apple Music, writes what the host says between songs, speaks it in that host's own voice, and broadcasts the result as one shared live stream over Icecast, with no skip button and the same show for every listener. From the console you steer it in plain sentences: tell it "rap like Snoop Dogg" and the next hours programme themselves to that brief, or ask why the record on air was chosen and get an answer. The forward lineup runs several hours deep, visible and editable, and nothing reaches air until its audio is already on the machine, so the stream never stutters waiting on a download. Words and voice are separate choices, swapped live in Settings: break-writing can run on a hosted model while a local Kokoro or Chatterbox voice reads it, and a station with no model at all still talks. Twenty-seven bundled plugins cover music sources, metadata, news, weather, and speech, and third-party plugins install from the console. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
InfluxDB
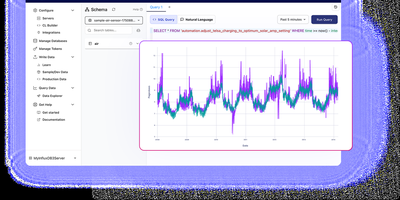
With over 31,600 GitHub stars and thousands of production deployments, InfluxDB 3 Core is the open-source time series database rebuilt in Rust on the FDAP stack — Apache Flight for high-throughput data transfer, DataFusion for vectorized SQL query execution, Arrow for columnar in-memory representation, and Parquet for compressed columnar storage. The engine delivers sub-10ms query response times on recent data and handles millions of writes per second through line protocol ingestion over HTTP, with unlimited tag cardinality eliminating the high-cardinality limitations that plagued earlier InfluxDB versions. The diskless architecture persists data as compressed Parquet files to S3-compatible object storage, Azure Blob, Google Cloud Storage, or local disk with configurable partitioning strategies, while the write-ahead log and in-memory buffer serve real-time queries against recent data before compaction. Native SQL support through DataFusion includes window functions, CTEs, subqueries, and joins, while InfluxQL maintains backward compatibility with existing InfluxDB 1.x and 2.x applications through the same query API. The embedded Python VM enables processing engine plugins and triggers that execute custom logic on write events, perform cross-database queries, and transform data in real time without external tooling. Flight SQL clients provide high-performance query access from Python, Go, Java, and Rust, and the HTTP API supports writes in line protocol format compatible with Telegraf's 300+ input plugins. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT/Apache 2.0 dual-licensed.
LinkWarden
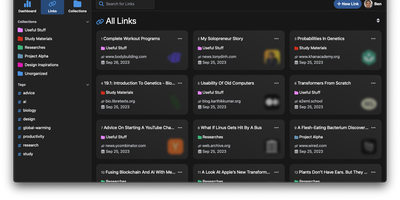
Links rot - the hard truth Linkwarden is built around, as a collaborative bookmark manager that preserves what it saves. Every page you save is fully preserved - a screenshot, a PDF, a self-contained single-file HTML archive (generated by the Monolith Rust binary), and a clean reader view - so the content survives even after the original site disappears. Think of it as a private Wayback Machine you own, with an optional one-click snapshot to archive.org on top. The reading experience matches the archival rigor: a distraction- free reader view supports text highlighting and annotation, and full-text search across everything you have saved is powered by Meilisearch. Optional AI tagging analyzes page content and auto-assigns tags - generate new ones, pick from your existing set, or constrain to predefined tags - with providers ranging from local Ollama models (fully private) to OpenAI, Anthropic, and OpenRouter. Organization is collections, sub-collections, and multiple tags per link; teams collaborate on shared collections with per-member permissions, and public collections share curated link sets (with preserved copies) to anyone. The stack is Next.js/React on TypeScript with PostgreSQL via Prisma, NextAuth supporting credentials, OAuth2, and SAML SSO, and a Playwright-driven headless Chromium worker doing the capture. Native iOS and Android apps and browser extensions feed it from anywhere.
Shoutrrr
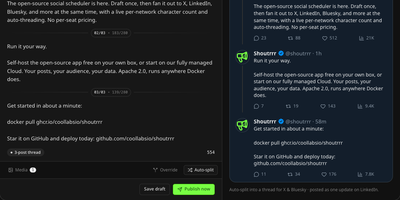
Write one post and Shoutrrr publishes it across X, Bluesky, LinkedIn, Facebook, Instagram, Threads, and Discord at the same moment, or holds it in a queue until the slot you picked. The composer counts characters against each network's limits as you type, attaches media with alt text, adjusts wording per platform when a message needs a local tweak, and splits long posts into threads where the network supports them. Recurring posting slots follow your workspace timezone, drafts drop into those slots from a month calendar, and anything can still go out instantly when news breaks. Every target publishes independently and retries on its own when a network hiccups, leaving a per-attempt trail you can inspect instead of a silent failure. Analytics chart follower and post-count trends for each account and report likes, reposts, replies, and impressions per post wherever the network's API allows. Teams share workspaces with role-based memberships and email invitations, keep clients in separate workspaces, and get in-app alerts the moment a post lands, fails, or needs an account reconnected. Account tokens sit encrypted at rest and refresh themselves, sign-in supports two-factor codes and passkeys, and the built-in MCP server hands AI assistants 22 tools to draft and schedule while publishing, retrying, and deleting refuse to run without your explicit confirmation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Shelve
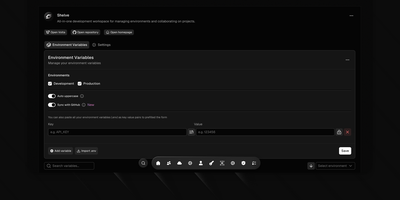
Eliminate scattered configuration files and leaked credentials across development teams with Shelve, an open-source secrets management platform that secures environment variables across development, staging, and production tiers. Engineering teams can organize sensitive database passwords and third-party API credentials within a centralized vault protected by AES-256 encryption and SHA-256 integrity verification. The platform synchronizes configurations directly to GitHub Actions and repository secret stores through an official GitHub App integration. Developers can inject encrypted variables directly into local processes using the dedicated CLI without saving plain-text secrets to disk. The built-in sharing vault creates self-destructing, password-protected links to exchange sensitive credentials securely with external contractors. Administrators can define custom workspace teams with granular role-based access controls, track change audit logs across configuration histories, and navigate management views using a keyboard-driven command palette. Automated schema validation engines detect missing parameters and enforce uniform uppercase naming standards across application tiers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
dbx
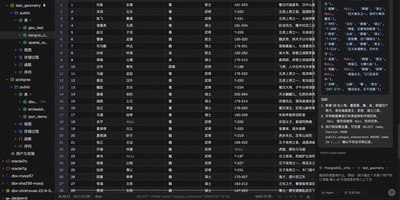
Universal database administration across modern enterprise infrastructure is simplified through dbx, a lightweight web client and SQL studio supporting over ninety database engines. Database administrators connect to MySQL, PostgreSQL, SQLite, Redis, MongoDB, ClickHouse, DuckDB, Oracle, and Microsoft SQL Server through authenticated network connections and encrypted SSH tunnels. The interactive query editor provides real-time multi-schema autocomplete, syntax linting, execution plan analysis, and natural language SQL query synthesis powered by configurable large language model backends. Teams visualize complex relational database architectures using interactive entity-relationship diagrams that map table foreign key constraints, primary indexes, and table partition layouts automatically. Operators inspect live Redis memory usage breakdowns, monitor real-time server command throughput, and manage key expirations without opening raw terminal sessions. The editable data grid supports multi-row modifications, foreign key reference lookups, CSV and JSON exports, and binary blob data inspection directly inside the browser viewport. Software developers expose connected databases directly to external AI coding assistants through native Model Context Protocol server endpoints. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Traffic Source
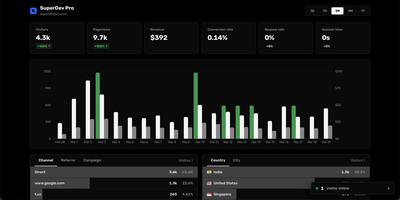
Traffic Source answers the three questions every site owner actually asks: who showed up, where did they come from, and did they pay. The live dashboard counts visitors in real time alongside pageviews, sessions, bounce rate, and session duration, with no cookie banner required because tracking uses no cookies at all. Referrer and UTM breakdowns show exactly which campaigns, newsletters, and posts earn their traffic, while country and city data arrives through proxy headers. Visitor journeys replay every page a person viewed before converting, so you can see the path from first click to checkout instead of guessing. Connect Stripe once and payments are matched to the sessions that produced them automatically, with no webhook plumbing to maintain. The affiliate system lets you create partners with custom commission rates and shareable referral links, and each affiliate gets a public dashboard showing their own clicks and earnings. Search Console data is pulled into the same screen, where a keyword explorer shows the pages, countries, and devices behind any query. One tiny tracking script covers all your sites, including single-page apps. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Excaliself
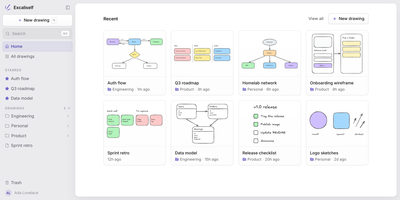
Excaliself turns the Excalidraw canvas into your team's own whiteboard server, where every sketch, diagram, and flowchart lives in your database instead of a vendor's cloud. The home screen works like a file cabinet for drawings: nest them in folders, star the keepers, drag files between spaces, and find anything again by title or by the text inside the drawing. Share a link and teammates edit together in real time with live cursors and follow mode; links can stay members-only or open to guests who have no account at all. A shared Team space sits next to everyone's private space, and one team library holds the shapes and icons the whole group reuses. AI clients can join with a personal access token: Claude Code or Claude Desktop can search your drawings, read what a diagram says, and create new ones from shapes or a Mermaid flowchart. Accounts are invite-only, single sign-on covers Google, Microsoft, and any OIDC provider, and admins manage members, roles, and password resets from Settings. Deleted drawings rest in a trash folder for thirty days before they are purged, and everything auto-saves as you draw. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
HolaOS
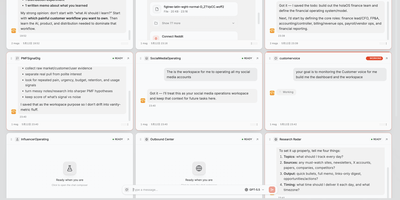
With over 6,500 GitHub stars, HolaOS bills itself as an "open agent computer" that reimagines the traditional operating system as a shared workspace where humans and AI agents collaborate across files, browsers, and 100+ integrated tools simultaneously. Unlike chat-only interfaces, HolaOS places live application UIs—Notion-style editors, browsers, custom workspace apps—side by side with the agent conversation, so operators always see what agents are doing and can intervene at any moment. The persistent memory system stores workspace knowledge locally as Markdown files and embedded vectors via SQLite vec, enabling RAG-powered recall that survives session boundaries without the typical context window bloat. Safe Session Compaction reserves roughly 70% of the model context window for fresh reasoning while folding older history into structured checkpoints that retain goals, constraints, progress, and decisions. Agents connect to Linear, GitHub, Slack, Jira, HubSpot, Gmail, and dozens more through one-click OAuth, automatically fetching relevant signals and converting scattered app data into working memory. BYOK support for Claude, GPT, and Gemini models lets operators use their own API keys at zero markup, while built-in Kimi K3 and GLM-5.2 models provide ready-to-use alternatives. Skills package reusable workflows that any agent can invoke on demand, and scheduled triggers enable autonomous digests, monitors, and reports. The runtime supports independent server deployment alongside the desktop client. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Modified Apache 2.0 licensed.
Pi Pocket
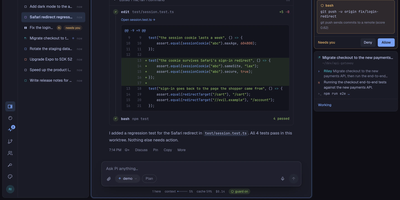
Pi Pocket puts the Pi coding agent in your phone browser, so you can start, steer, and review real coding sessions from anywhere while the work stays on your own server. Open a folder, a fresh Git worktree, or a GitHub repository, pick a model per session, and watch streamed replies with tool calls, queued follow ups, and a stop button when a run wanders. Sessions survive crashes and restarts because every model call, tool call, and subagent step is stored as it happens, and forks let you retry any reply with a different model on another branch. Invite teammates into a live session with presence, roles, and a side chat the agent never sees, or let PiP, the built in assistant, follow your other sessions and report back. GitHub watches and webhooks wake the agent when pull requests, issues, or workflows change, while scheduled messages and cron style goals keep routine work moving overnight. Spend views show cost per person and per session, and owner set limits pause new work instead of quietly burning budget. On a phone you get push notifications, dictation, share sheet intake, and a home screen app, and live reloadable extensions add routes, modules, and commands without a build step. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenMeter
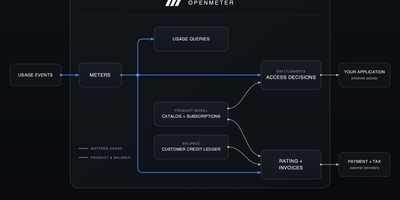
AI and API products live or die by usage, and OpenMeter is the open-source stack that measures it, rations it, and bills for it. Your application emits CloudEvents for every billable action; OpenMeter validates and deduplicates them, then aggregates usage in real time so dashboards and enforcement checks never wait for a nightly batch. Meters slice that usage by customer, time window, or any dimension you attach, which turns raw events into answers like tokens per workspace this month. Entitlements decide who gets what: metered allowances with balances and overage, boolean switches for features like SSO, and static JSON configuration for per-customer model access. Grants top allowances up once or on a schedule, resets roll balances over each usage period, and one API call tells your app whether a customer still has access right now. On the money side, plans carry flat, per-unit, tiered, package, or dynamic prices; subscriptions, credit balances, and the invoice lifecycle run alongside, with webhooks announcing everything to your other systems. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.