Kimai
From a freelancer logging billable hours to companies with hundreds of users, Kimai scales professional-grade open-source time tracking - a Symfony/PHP application without the per-seat pricing of Harvest or Toggl. Tracking is flexible by design: run multiple concurrent timers, use punch-in/punch-out mode, or enter times manually, organized by customer, project, and activity with tags, and priced by user-, customer-, or project-specific rates. The billing pipeline is where Kimai earns "professional grade": generate invoices directly from timesheet data with configurable templates (DOCX, ODS, XLSX, PDF), entry grouping, and invoice-number generators, while an export flag locks billed records against editing and excludes them from future invoices - the audit-safety detail spreadsheet workflows never get right. E-invoicing supports EN 16931, XRechnung 3.0, and Zugferd/Factur-X. Enterprise controls come standard: SAML and LDAP login against Google Workspace, Azure AD, or Authentik, TOTP two-factor auth, customizable role permissions, and teams that scope customers and projects to departments. Money and time budgets alert before overruns, advanced reporting slices recorded time by any dimension, and an extensive JSON API plus a plugin marketplace (expenses, approvals, and more) integrate it with existing infrastructure. Over 30 translations, multi-timezone, AGPL-licensed.
Argilla
Before a language model learns from your data, someone has to label it well; Argilla gives AI engineers and domain experts a shared workspace to label, review, and refine the datasets that fine-tune language models and train NLP pipelines. You build each dataset from the Python SDK, mixing text, chat, and image fields with the exact questions your task needs: single-label classification for intent detection, span questions for named entities, ratings for response quality, rankings for preference tuning, or free text for corrections. Annotators then work through records in a focused labeling interface where model predictions already sit attached as suggestions, turning most reviews into a fast confirm-or-correct decision instead of a blank-page exercise. Full-text search, metadata filters, and status filters slice a hundred thousand records down to the ones needing attention, while vector-based semantic search finds lookalike examples, near-duplicates, and the disagreement hotspots where guidelines need sharpening. Dataset owners watch completion progress, manage who has responded to what, and split work across workspaces with owner, admin, and annotator roles for each team or client. Finished datasets export with responses, suggestions, and metadata intact, locally or straight to the Hugging Face Hub, ready for fine-tuning and evaluation runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OpenNebula
One front-end server can run your entire cloud: OpenNebula orchestrates KVM virtual machines and LXC containers across clusters of hosts, presenting everything through the FireEdge Sunstone web interface and a full API. Operators define VM templates once and instantiate them anywhere, attaching disks and networks, taking snapshots, scheduling actions, and opening remote consoles through Guacamole without leaving the browser. The OneDRS distributed resource scheduler reads historical and real-time metrics to predict demand spikes and migrate workloads before contention bites, with customizable policies and automation levels. GPU passthrough and PCI device hotplugging serve AI and accelerator workloads, while OVA import through the oneswap command ingests virtual machines exported from VMware vCenter for re-virtualization projects. Edge Clusters deploy on demand on premises or at remote providers, extending the same management model to hybrid and distributed sites without a separate stack. The 7.4 Helix release redesigns Sunstone with a slide-in side drawer and richer resource visualizations, and brings OneKS managed Kubernetes plus LVM storage to the Community Edition. Ceph and LVM datastores, incremental backups, cluster-level and generic quotas for resources like vGPUs, and OneFlow service orchestration for multi-VM applications round out daily operations. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Para
The name means steam in Bulgarian, and the job matches: Para is the boiler room that powers your application's backend so you never build one from scratch. You store plain JSON objects through a REST API and get them back persisted, indexed for full-text search, and cached on every write, without designing schemas or gluing three systems together yourself. One server hosts many applications at once, each with its own table, search index, and cache, so a client project, a side app, and an internal tool can share a single deployment without sharing data. Users sign in with social accounts, LDAP, or SAML and receive JSON Web Tokens, while resource permissions decide exactly which objects each client may touch. Queries go beyond key lookups: field, wildcard, geo point, and more-like-this searches all run against the same stored objects. Signed webhooks notify your own endpoints when data changes, and an MCP server lets AI assistants manage configuration, data, and search against the same backend. The admin Web Console handles users, objects, backups, and permissions from the browser, and client libraries cover JavaScript, PHP, Java, C#, Android, and iOS. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Quickwit
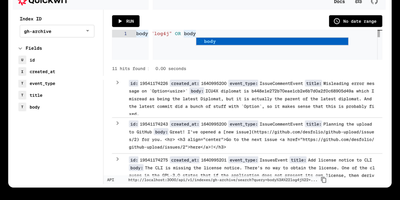
With over 11,000 GitHub stars and now backed by Datadog while remaining fully Apache 2.0 licensed, Quickwit delivers the search performance Elasticsearch users expect at a fraction of the infrastructure cost by moving the index to object storage instead of expensive local SSDs. The Rust-based engine, built on the Tantivy search library with SIMD-accelerated vectorized processing and zero garbage collection overhead, achieves sub-second search latency directly against Amazon S3, Azure Blob Storage, Google Cloud Storage, or any S3-compatible backend like MinIO and Ceph. The Elasticsearch-compatible REST API covers ingest, search, query DSL, and aggregations, enabling existing log shippers including Vector, Fluent Bit, and Syslog to migrate without rewriting configurations. Native OpenTelemetry Protocol endpoints accept logs and traces via gRPC, while Jaeger integration provides a drop-in distributed tracing backend. Ingestion from Apache Kafka, Amazon Kinesis, and Apache Pulsar supports streaming pipelines with multi-index partitioning, and the schemaless JSON indexing mode eliminates the need for upfront schema definitions. Stateless searchers and indexers scale horizontally on Kubernetes or bare metal, with a control plane that distributes indexing tasks and a janitor that manages retention policies and GDPR-compliant deletions. The built-in web UI displays search results and cluster state, while the official Grafana data source enables log exploration dashboards. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
MyTube
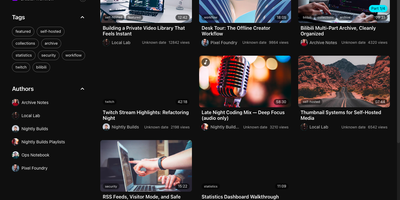
For video enthusiasts and media archivers who want complete ownership over their online video subscriptions, MyTube provides a self-hosted video downloader, library organizer, and streaming portal. Paste a single link or queue a batch of URLs from YouTube, Bilibili, Twitch, MissAV, and over one thousand yt-dlp compatible sites to archive videos directly to your disk. Subscribe to your favorite creators so new uploads download automatically in the background alongside their default language subtitles. Local video uploads automatically generate thumbnails and pull movie or television posters, cast details, release years, and ratings from TMDB. Curate custom collections, filter your catalog by tags or authors, and generate private RSS feed links for external podcast and feed readers. Built-in playback tools include keyboard shortcuts, cinema mode, Canvas-based in-car playback, and optional real-time audio translation with live subtitles via Google Gemini. You can sync finished recordings to Alist or OpenList cloud storage, trigger custom shell scripts on task completion, and receive instant Telegram bot alerts when downloads finish or fail. Share your library safely using read-only visitor accounts while protecting admin controls with WebAuthn passkeys or a 3x3 gesture lock. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
WBO
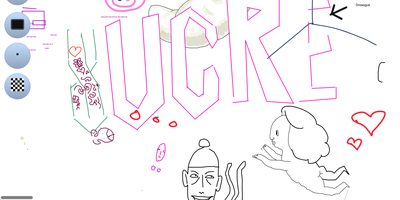
A Node.js server, a large shared canvas, and a URL - WBO (Whiteboard Ophir) is collaborative whiteboarding reduced to its essence. There are no accounts and no setup - to collaborate, you send someone the board's link, and every stroke appears for all connected users in real time over WebSockets, with cursor positions shared so you can see where collaborators are working. Board state persists automatically and continuously, so a diagram drawn in today's lesson is still there next week at the same URL. Boards come in three flavors: a public free-for-all, private boards with random unguessable names, and named boards with custom URLs shared by anyone who knows the name. The tools cover teaching and brainstorming needs - pencil, straight lines, rectangles, ellipses, text annotations, eraser, a full color palette with brush sizes - and boards export as SVG or PNG. Despite the simplicity, the server is production-minded: JWT authentication gates board access with granular capabilities (open, edit, and clear as separate permissions), rate limiting caps per-client message volume, reverse-proxy and subpath deployment are supported, and OpenTelemetry provides metrics, logs, and traces. It works on tablets and touch devices, speaks multiple languages, and consumes minimal resources. AGPL-licensed.
Nowen Note
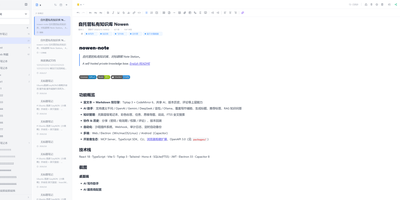
Nowen Note is a self-hosted knowledge base where your notes, tasks, daily journals, and mind maps live in one private workspace you control. One tree holds folders, rich-text documents, and Markdown notes side by side, with drag-and-drop ordering, unlimited nesting, colored tags, pinning, and full-text search across everything. Each note can switch between a rich-text editor and Markdown with live preview, split view, outlines, tables, code blocks, math formulas, diagrams, comments, and version history. Connect the AI provider you prefer, such as an OpenAI-compatible API, Gemini, DeepSeek, or local Ollama, to continue drafts, rewrite passages, translate, summarize, and ask questions answered from your own notes. Tasks get list, board, calendar, and timeline views with dependencies, recurring rules, reminders, and templates, while daily journals capture short entries, moods, and photos and roll them into AI weekly and monthly reviews. Teammates edit together in real time, and folder-level permissions, passwords, allow and deny rules, share links with expiry dates, and guest comments decide exactly who sees what. Imports arrive from Obsidian, SiYuan, Word documents, web pages, and plain Markdown, attachments can live on local disk or S3-compatible storage, and scheduled backups travel to email or WebDAV. Keep working offline with a cached workspace that syncs when you reconnect, clip pages from the browser extension, and connect other tools through the OpenAPI, SDK, webhooks, and MCP server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Reloops
Reloops is a self-hosted creative asset workspace where teams keep every video, design, PDF, audio file, and live website in one library and collect feedback on the files themselves instead of in scattered email threads. Reviewers click anywhere on an image to pin a note to that exact spot, and on video the comments attach to the precise frame, so "fix this bit" always points at the bit in question. Every upload becomes a new version on the same asset, older cuts stay available for side-by-side comparison, and approvals are recorded on the file so nobody ships the wrong export by accident. Clients never need an account: send them a share link or a branded collection and they can watch, comment, and sign off as guests. The library searches the way people remember work, because each asset carries generated descriptions, tags, and metadata filters, so "the approved homepage with the blue button" actually finds something. Day to day, assignments and review queues keep feedback moving, while scoped API keys let agents such as Claude, OpenClaw, Zapier, and n8n upload new versions, post comments, update statuses, and manage share links inside the same workspace. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
PandaWiki
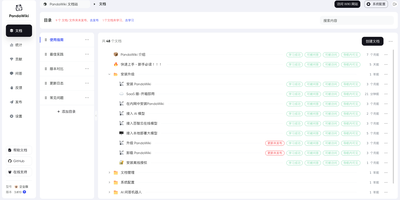
In seven wizard steps, PandaWiki sets up a product docs, manual, FAQ, or blog site whose built-in AI answers visitors using only your own content. Those visitors can chat with an assistant that cites its sources and accepts image questions, or switch to a docs-only search that lists ranked pages with summaries. Publishing stays under control: each document has three switches, visible in navigation, reachable by URL, and answerable by AI, and nothing appears or gets learned until it is published. Authors write in a Markdown and HTML editor, or import from URLs, RSS and Atom feeds, sitemaps, offline .txt, .md, .xlsx, .docx, and .pdf files, Notion, Yuque, SiYuan, Wiki.js, Feishu, Confluence, and DingTalk. Pages export to Word, PDF, or Markdown. The wizard covers models, domain, HTTP or HTTPS ports, import, publishing, answer testing, and page decoration. One knowledge base can also feed a web widget and DingTalk, Feishu, WeCom, and Discord bots. Administrators get a dashboard of visits, questions, visitor regions, hot documents, and referring domains. Chat models come from Baizhi Cloud, DeepSeek, OpenAI, or Ollama, while vector and reranking models are built in. The open-source edition covers one wiki site, 300 documents, and one admin, and its console and documentation are in Chinese. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
TeamMapper
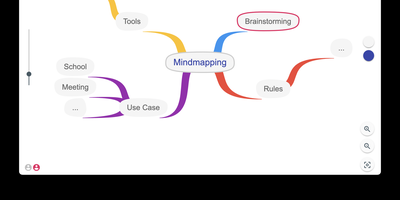
Turning chaotic group brainstorming sessions into structured visual diagrams, TeamMapper provides a real-time collaborative mind mapping workspace that teams and classrooms can join instantly without creating user accounts. Workshop facilitators, teachers, and product squads start from a central root topic and branch outward into hierarchical radial trees, using keyboard shortcuts and full undo-redo history to capture ideas at the speed of conversation. Every node can be styled with custom branch and background colors, adjustable font weights and sizes, external reference links, uploaded raster images, and visual pictograms from the ARASAAC library to reinforce memory and visual association. Sharing a live session takes a single click: hosts distribute either a view-only link, a full modification invite URL, or a scannable QR code so remote colleagues and students in the same room can edit branches simultaneously. When enabled by the administrator, an integrated AI assistant can automatically generate initial mind map branches and subtopics from a text prompt to jump-start planning sessions. Completed maps export cleanly to JSON, Mermaid diagram syntax, scalable SVG vectors, high-resolution PNG images, or printable PDF documents, and existing JSON maps can be re-imported at any time for follow-up workshops. Built-in privacy controls automatically purge inactive mind maps and orphaned image attachments after a configurable retention window, simplifying GDPR compliance for schools and enterprises. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
DEEIX Chat
Organizations deploying multiple large language models across departments use DEEIX Chat as their centralized AI workspace for model routing, multimodal conversations, document retrieval, MCP tool execution, and usage governance. Administrators connect upstream channels across OpenAI, Anthropic, Google Gemini, xAI, and OpenRouter protocols while configuring route priorities, traffic weights, and automatic circuit breaking from a unified control plane. Team members switch models mid-conversation, branch message threads, adjust reasoning effort, and generate images or video without managing individual API keys, or optionally bring their own provider keys under admin policy rules. Uploaded PDFs, spreadsheets, and images undergo OCR and semantic chunking so users can attach personal or shared knowledge bases directly to chat sessions with traceable retrieval evidence. Interactive responses render live HTML, SVG, Mermaid diagrams, KaTeX math, and stateful parameter sliders inside a sandboxed preview pane alongside the conversation. Built-in support for Streamable HTTP Model Context Protocol servers lets users discover and invoke external tools with per-message execution limits and full call inspection. Integrated permission groups, OIDC single sign-on, TOTP two-factor authentication, token and per-call billing ledgers, and audit logs give operators complete visibility over usage and spend. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Arkon
With 1,200+ GitHub stars since its April 2026 launch, Arkon provides an enterprise-grade knowledge management layer that turns scattered organizational documentation into AI-accessible structured context. The platform runs as a centralized MCP server, compiling your SOPs, policies, technical docs, and institutional knowledge into a versioned wiki with draft-approval workflows, then serving that wiki to Claude Desktop, Claude.ai, Cursor, and any MCP-compatible client through a single permission-scoped endpoint. OAuth 2.1 with PKCE authentication eliminates manual token management — employees authenticate through a browser login while the system discovers endpoints automatically via RFC 8414. The RBAC v2 system supports custom roles with granular permissions, department-scoped AI Skills, workspace isolation, and comprehensive audit logging so every query and access event is traceable. RAG retrieval powered by pgvector embeddings enables AI clients to search across all organizational documents with source attribution, while the AI Skills system lets teams define reusable instruction sets scoped to specific departments or roles. The architecture runs seven Docker containers coordinated by Compose: PostgreSQL with pgvector for embeddings and metadata, Redis for caching, MinIO for document storage, a FastAPI backend, two ARQ async workers for embedding generation and document processing, and a Next.js frontend portal accessible on port 3119. API keys are encrypted at rest with Fernet, and no telemetry leaves the deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. PolyForm Internal Use licensed.
MetaMCP
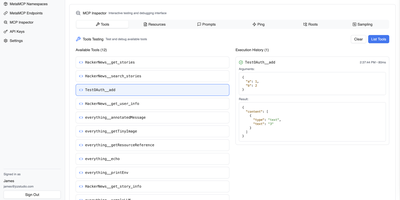
With 2,600+ GitHub stars, MetaMCP solves the MCP server sprawl problem by aggregating any number of upstream servers into a single authenticated endpoint that any MCP client connects to once. Group servers into namespaces — development tools in one, data sources in another — then publish each namespace as its own SSE, Streamable HTTP, or OpenAPI endpoint with API-key authentication in headers or query parameters, or full OAuth per the MCP Spec 2025-06-18 standard. The aggregation engine discovers tools, resources, and prompts from all active servers in parallel, prefixes tool names with server identifiers to prevent collisions, and applies configurable middleware including tool filtering to reduce context-window bloat and description overrides to improve LLM comprehension. The web management UI lets you configure MCP servers with stdio, SSE, or Streamable HTTP transports, toggle servers active or inactive per namespace, create and revoke API keys per endpoint, and inspect discovered tools with their schemas. Nested MetaMCP support enables hierarchical architectures where one MetaMCP instance consumes another, creating multi-level tool organization with automatic name resolution. Compatible with Claude Desktop, Claude Code, Cursor, Open WebUI, and any MCP-compatible client through a single connection URL. The Docker container packages the TypeScript backend with PostgreSQL for configuration persistence, exposing the management UI on port 12005 and MCP endpoints on configurable ports. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
CyberScraper 2077
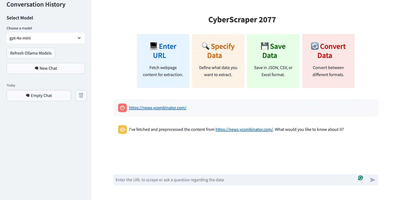
With 3,100+ GitHub stars, CyberScraper 2077 replaces brittle CSS selectors and XPath queries with natural language data extraction powered by Large Language Models. Users paste a URL, describe the data they want in plain English, and the AI extracts structured results from any website — no HTML parsing knowledge required. The tool supports three LLM backends: OpenAI GPT models for maximum accuracy, Google Gemini for cost-effective extraction, and local Ollama instances for fully private scraping where URLs and data never leave your server. Built on Python asyncio with Playwright browser automation, it handles concurrent page fetching with content-based and query-based LRU caching to minimize redundant API calls. The Streamlit web interface runs on port 8501 and provides one-click export to JSON, CSV, HTML, SQL, Excel, and direct Google Sheets upload. Tor network integration routes requests through onion routing for anonymous scraping of both clearnet and .onion hidden service sites with automatic circuit management and stream isolation. Stealth mode randomizes user agents, manages cookies, and controls JavaScript execution timing to bypass bot detection systems. Multi-page scraping navigates through paginated results with automatic URL pattern detection. Docker deployment packages all dependencies including Playwright browsers into a single container. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Domain Watchdog
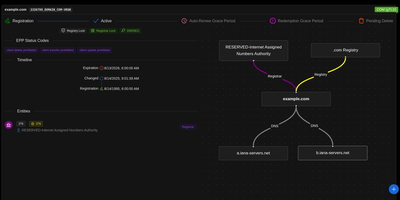
When the domain you want is already taken, Domain Watchdog tracks its history, warns you as it changes, and can try to register it as soon as it becomes available. Searching any domain returns its registrar, status, nameservers, and registration events from RDAP, the structured JSON successor to WHOIS. A timeline lays out the full lifecycle, from creation through renewals and transfers to final deletion, while deletion forecasting orders tracked domains by their expected drop window. Watchlists group domains with the events that matter, send alerts by email or as webhooks to Slack, Mattermost, or Discord, and publish an iCal feed plus RSS feeds for events and EPP status. Attach a connector for OVH, Gandi, Namecheap, AutoDNS, or Name.com, and an expired domain on the watchlist triggers an order attempt through that provider's API. The app also lists ICANN-accredited registrars and TLDs, and rate limiting with caching minimizes RDAP requests. Administrators can cap watchlists, domains per watchlist, and webhooks per watchlist, toggle public RDAP lookups, and add custom static content to the instance. Scripts can manage watchlists and connectors, search domains, and request user tokens through the documented REST API. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
RisingWave
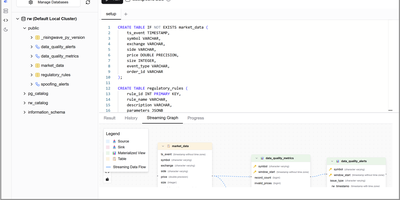
With over 9,100 GitHub stars and production deployments powering real-time analytics at companies like SHOPLINE where it reduced API latency by 76.7%, RisingWave is the PostgreSQL-compatible streaming database that collapses the traditional Debezium-plus-Kafka-plus-Flink-plus-serving-database stack into a single Rust-powered system. The platform continuously ingests data from PostgreSQL and MySQL via native CDC connectors that eliminate Debezium middleware, consumes Kafka, Redpanda, Pulsar, and Kinesis topics, accepts webhook events from SaaS applications, and batch-loads historical data from S3 and data warehouses. Standard SQL defines sources, materialized views, and sinks — no new DSL, no Java, and no custom API — while the PostgreSQL wire protocol means psql, DBeaver, pgAdmin, Grafana, Metabase, Superset, Tableau, and every PostgreSQL client library works without modification. Materialized views are incrementally maintained as events arrive, delivering point lookups in single-digit milliseconds without recomputing aggregates from scratch. For long-term retention, RisingWave writes to Apache Iceberg tables with a hosted REST catalog and automated table maintenance including compaction, small-file optimization, and snapshot cleanup, with data queryable by Spark, Trino, DuckDB, and DataFusion. The disaggregated compute-storage architecture uses S3-based state management for elastic scaling, instant failure recovery measured in seconds rather than the minutes-to-hours typical of RocksDB-based systems, and cost-efficient storage tiering. An MCP server enables AI agents to query and operate RisingWave directly. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Foreman
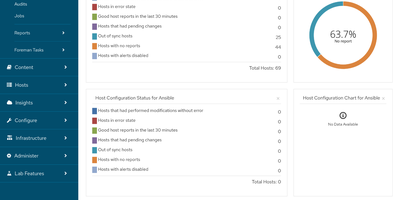
Foreman is the control room for a server fleet, taking machines from blank hardware or an empty VM to configured, monitored hosts through one web interface. Create a host entry and it network-boots by PXE or UEFI HTTP, or starts from a discovery image that phones home its hardware inventory so unknown machines can be claimed and built by rule. Installation runs from templates for Kickstart, Preseed, AutoYaST, Agama, and cloud-init, while host groups bundle the operating system, partition layout, and parameters that make every build of a role identical. The same console provisions onto bare metal, libvirt, VMware, oVirt, Amazon EC2, Google Compute Engine, and OpenStack, because each provider plugs in as a compute resource with its own images and networks. After installation, Puppet classes and parameters, Ansible roles with recurring runs, or Salt states keep configuration enforced, and the reports and facts those tools send back fill dashboards showing which hosts are current, which drifted, and which are erroring. Smart Proxy services carry DHCP, DNS, TFTP, and configuration enforcement into each subnet or datacenter segment, remote execution runs jobs across the fleet, and the Katello plugin adds content and patch management on top. Hammer gives the whole API a command-line face, and role-based access with LDAP or FreeIPA sign-in keeps large teams in their lanes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.